Welcome to CyberCode Academy — your audio classroom for Programming and Cybersecurity. 🎧 Each course is divided into a series of short, focused episodes that take you from beginner to advanced level — one lesson at a time. From Python and web development to ethical hacking and digital defense, our content transforms complex concepts into simple, engaging audio learning. Study anywhere, anytime — and level up your skills with CyberCode Academy. 🚀 Learn. Code. Secure.
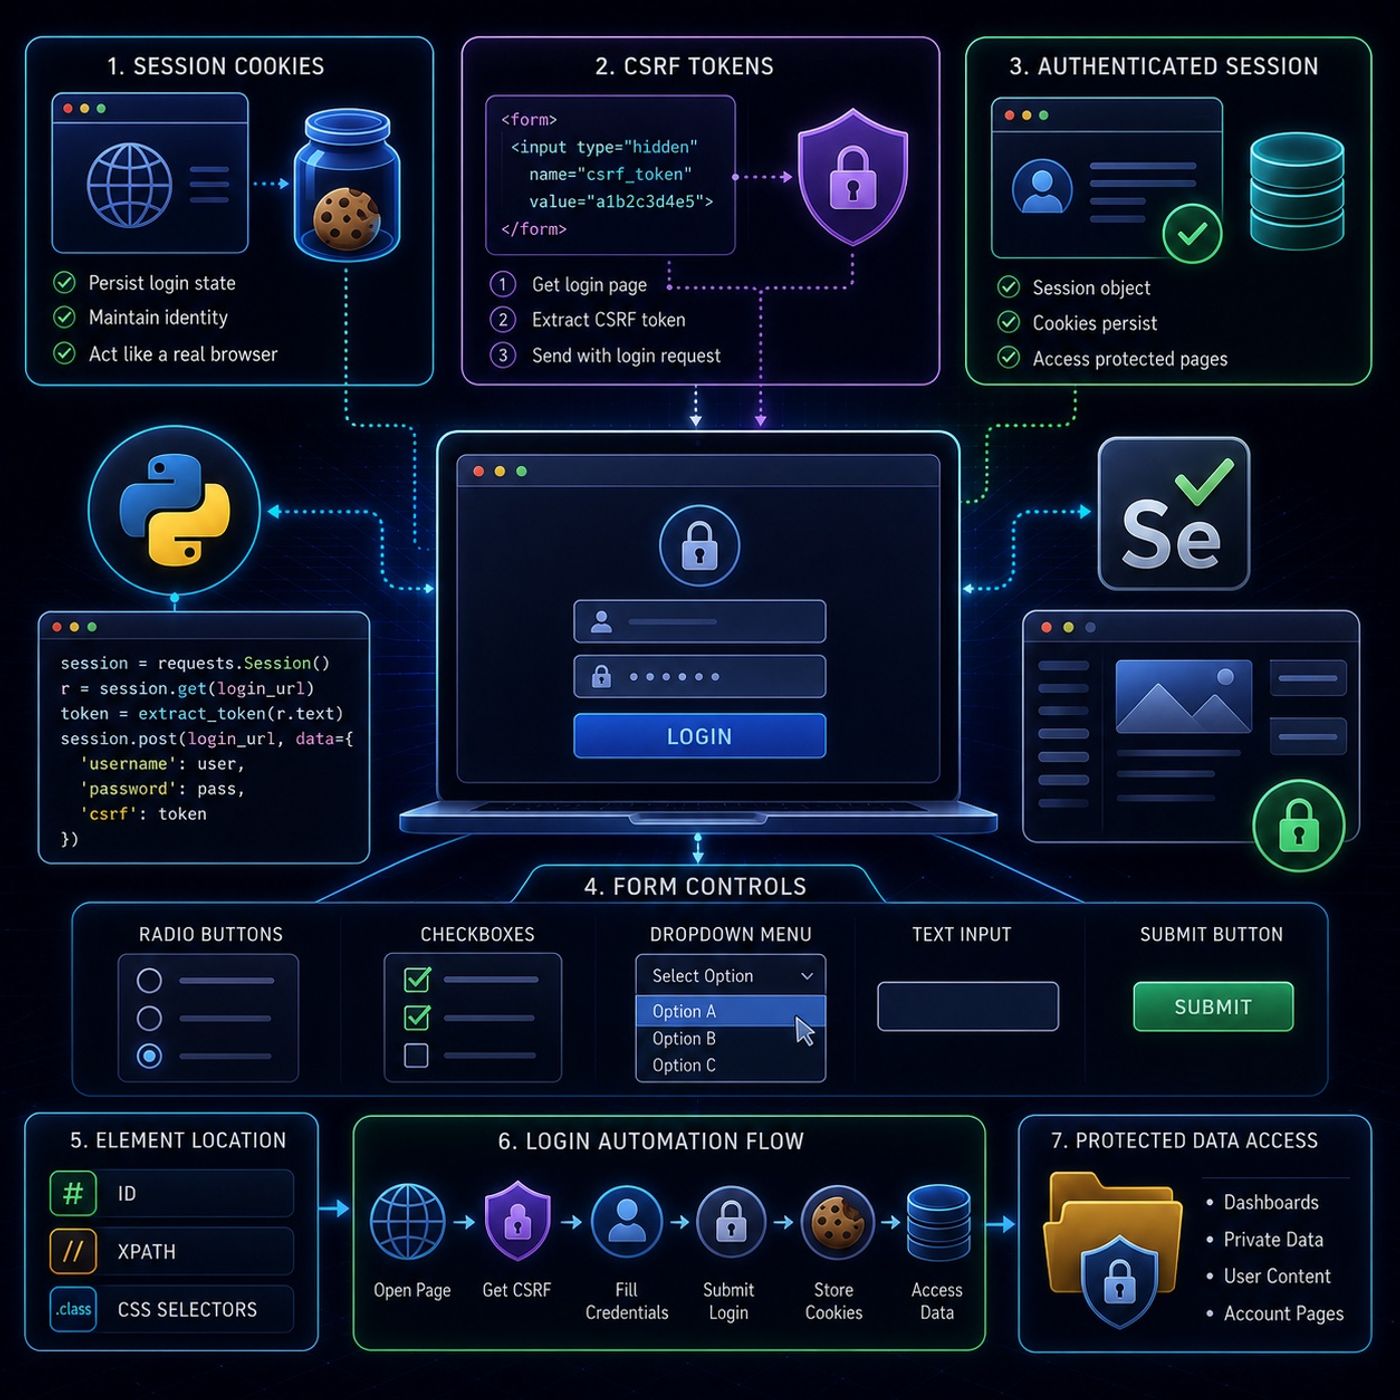
This episode is essentially about turning “login-protected websites” into programmable sessions and then controlling full form workflows like a real user.🔐 Core IdeaModern scraping stops being “download HTML” and becomes:“Authenticate → maintain...
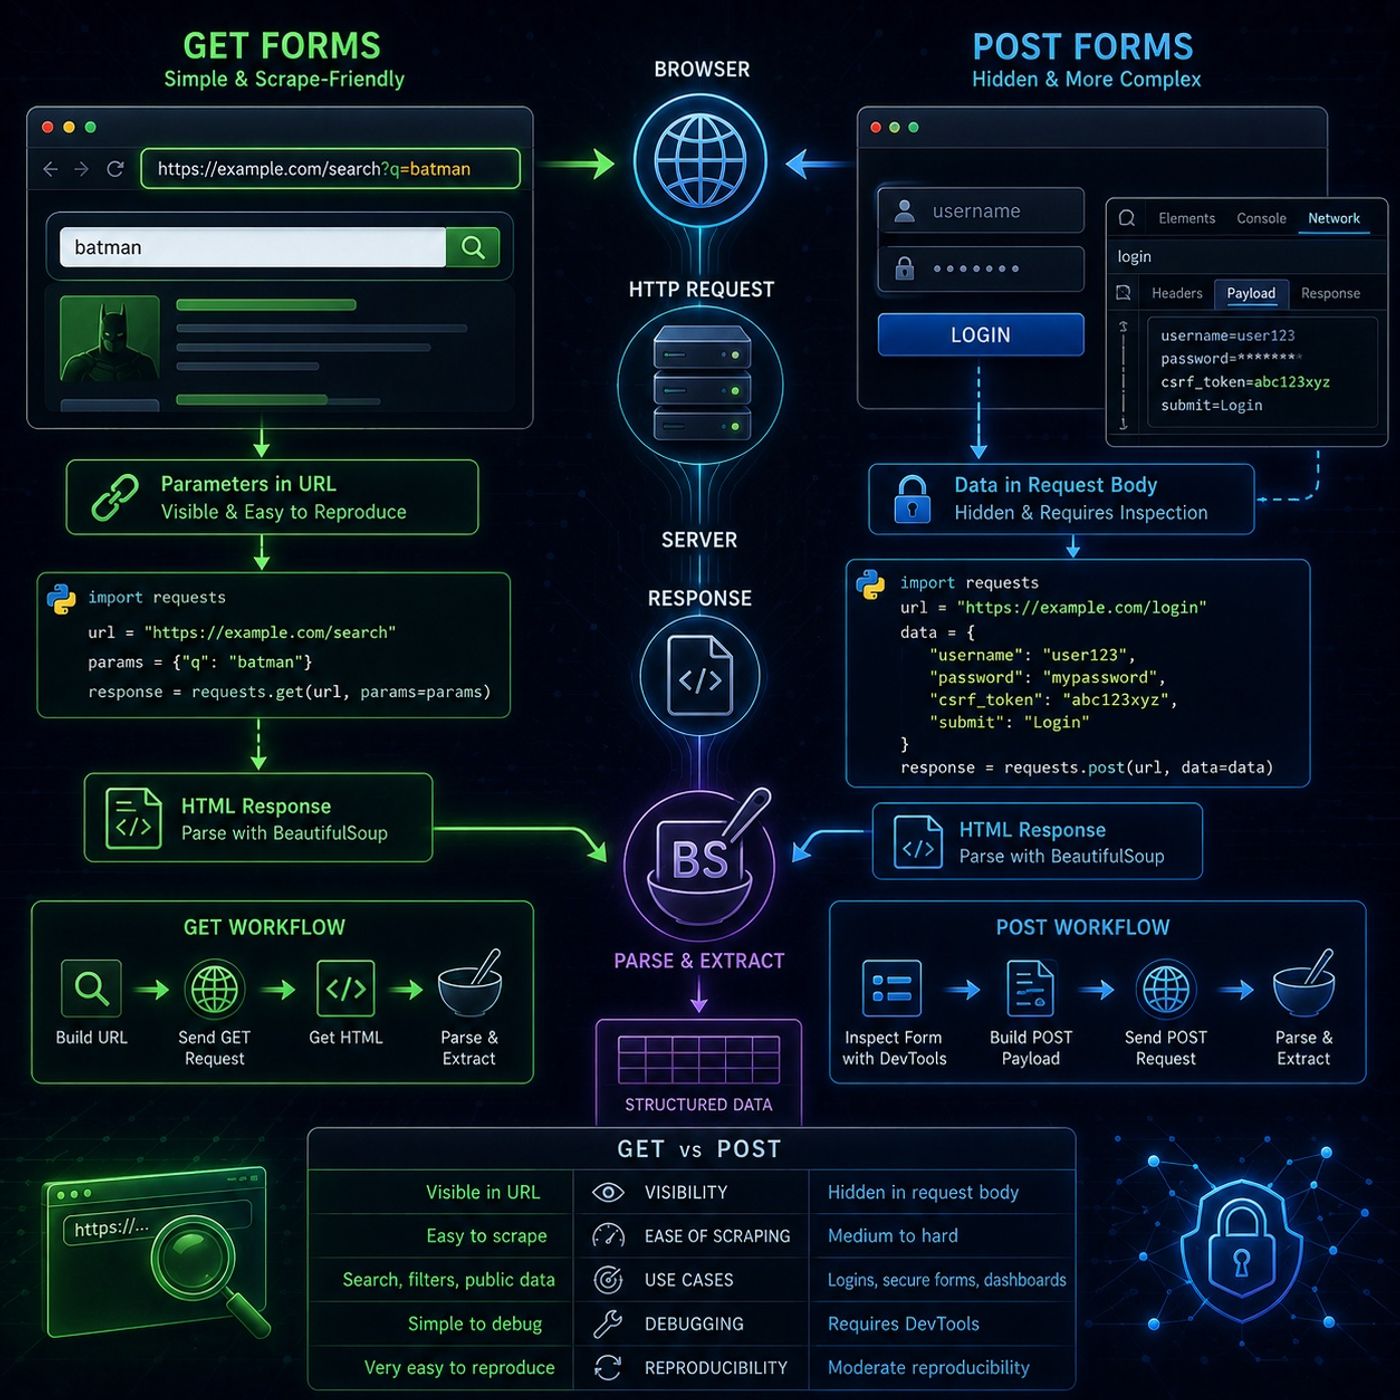
This episode is essentially teaching you how to reverse-engineer web forms into programmatic HTTP requests, which is one of the most important skills in practical scraping.🧭 Core IdeaWeb forms are just structured HTTP requests.So instead of...
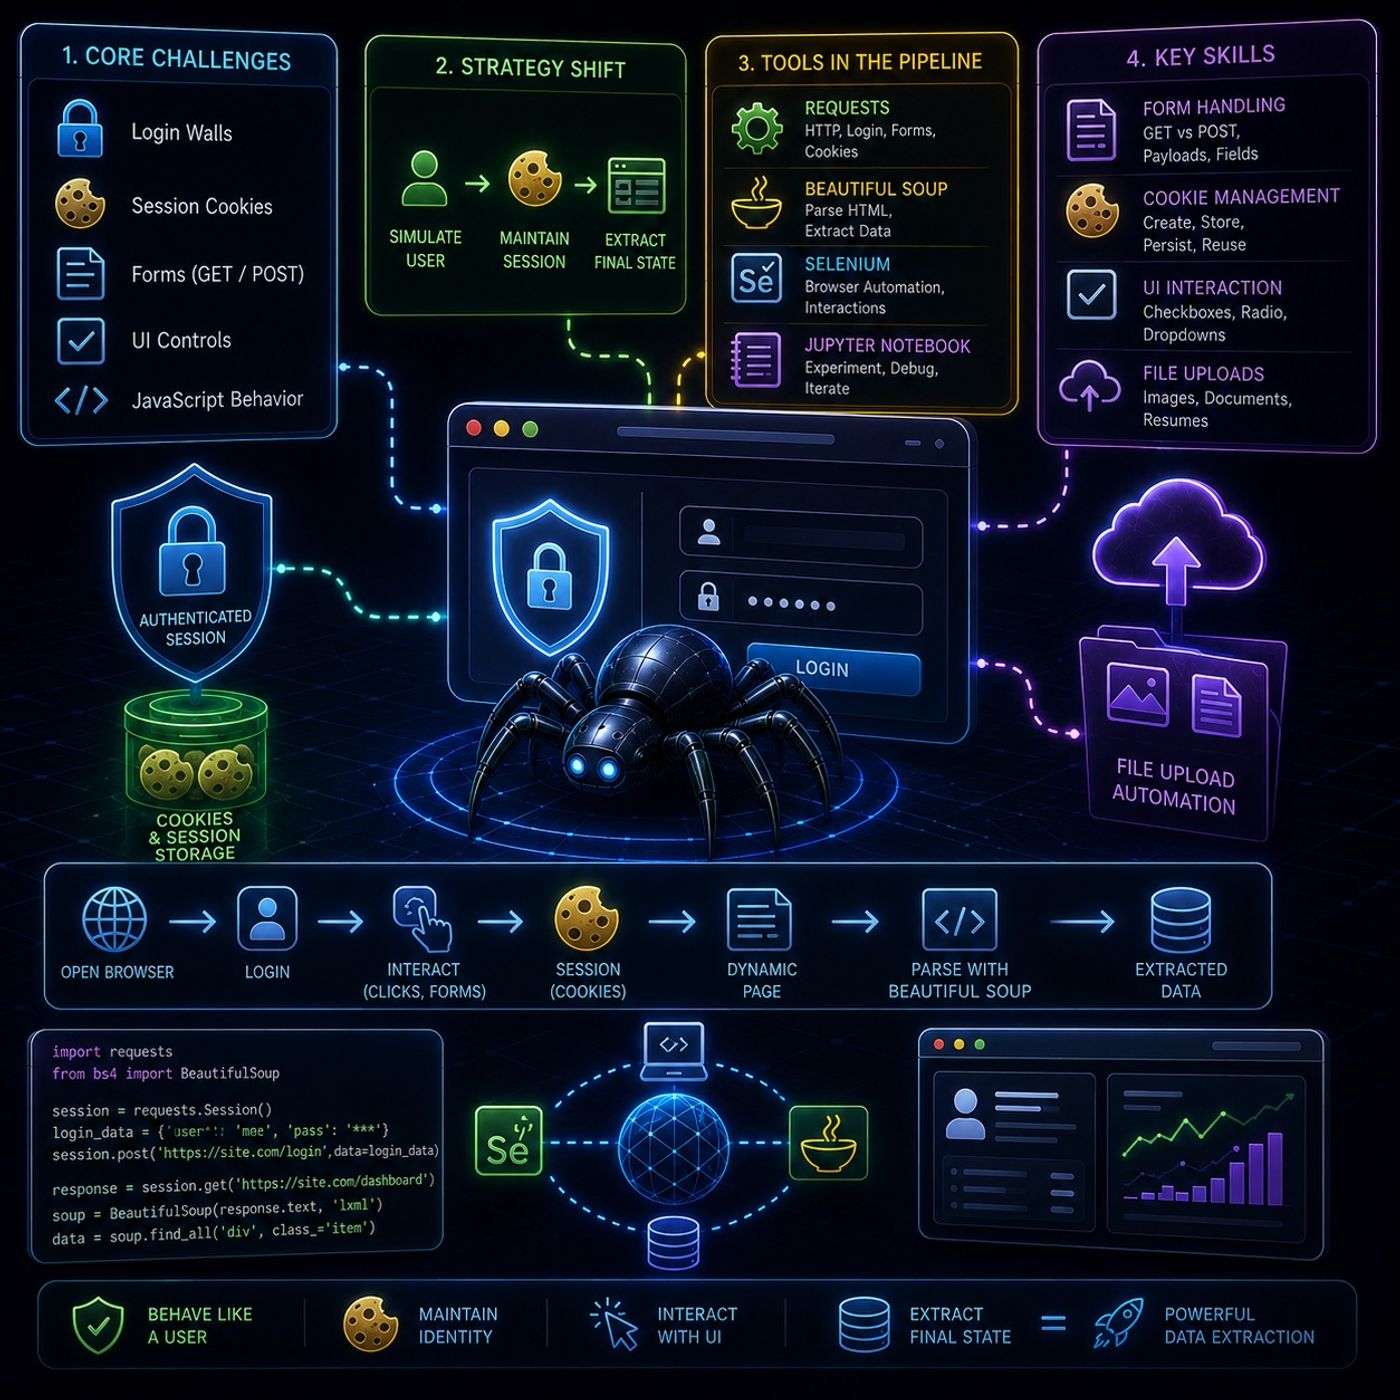
This episode is essentially about moving from “simple scraping” → “interactive web automation + session-aware extraction”, where websites behave more like applications than static pages.🧠 Core Idea of the CourseStandard scraping fails when websites:...
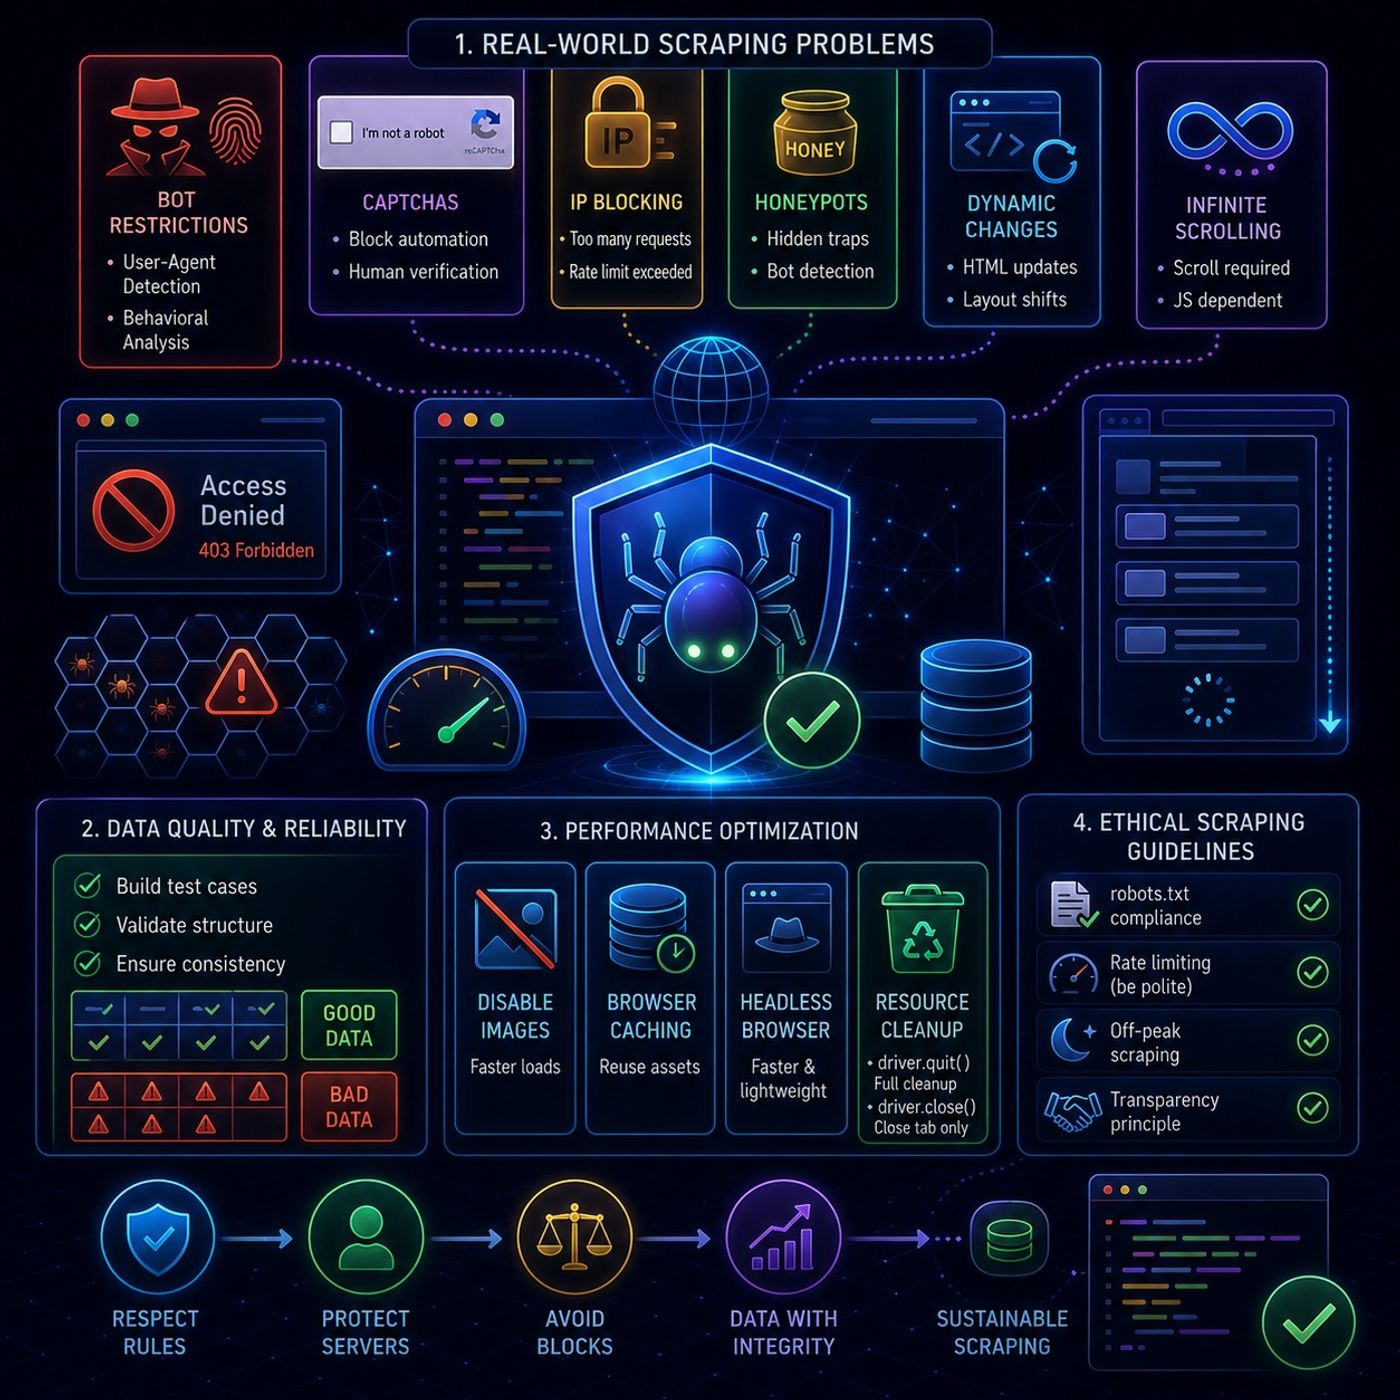
This module is essentially the “real world survival guide” for web scraping — it moves away from pure tooling and focuses on what actually breaks scrapers in production and how to behave responsibly while scraping at scale.🚧 1. Real-World Scraping...
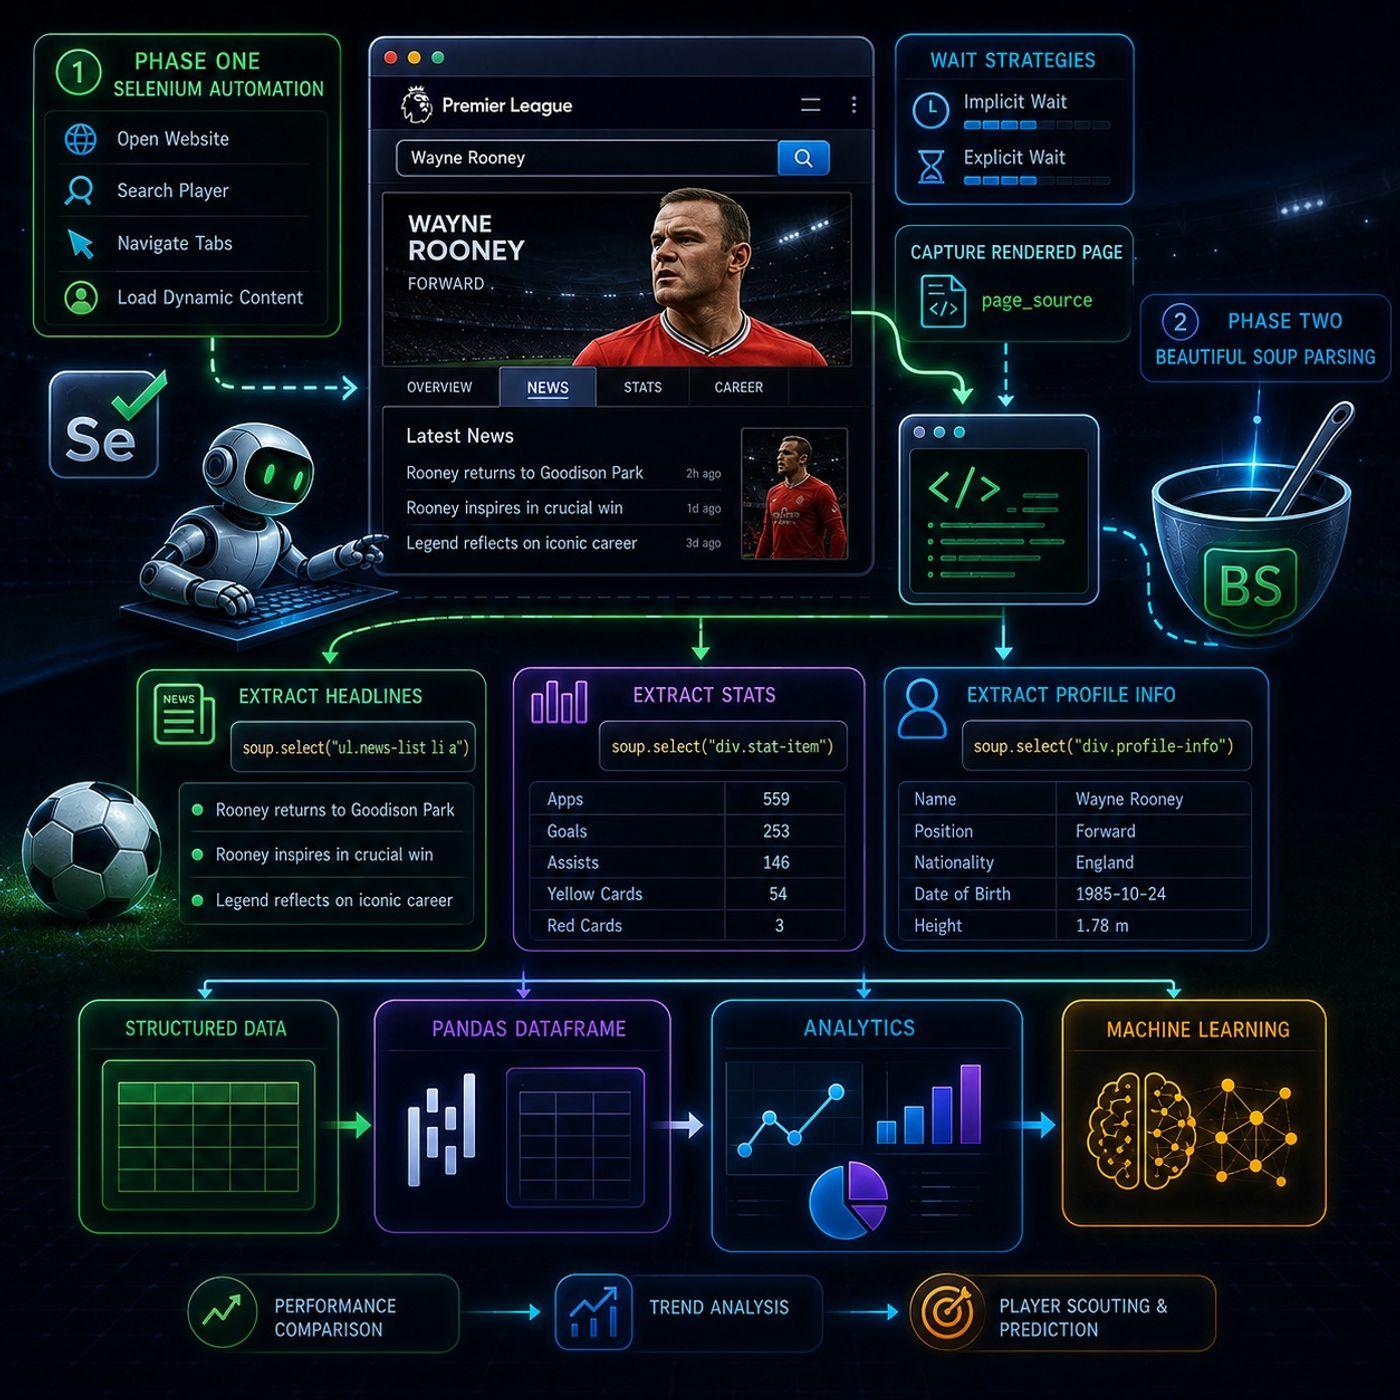
This episode is a practical end-to-end example of the Selenium + Beautiful Soup hybrid scraping pattern, applied to a real sports data use case (Premier League player pages).⚽ Goal of the ProjectScrape structured data about Wayne Rooney from a dynamic...
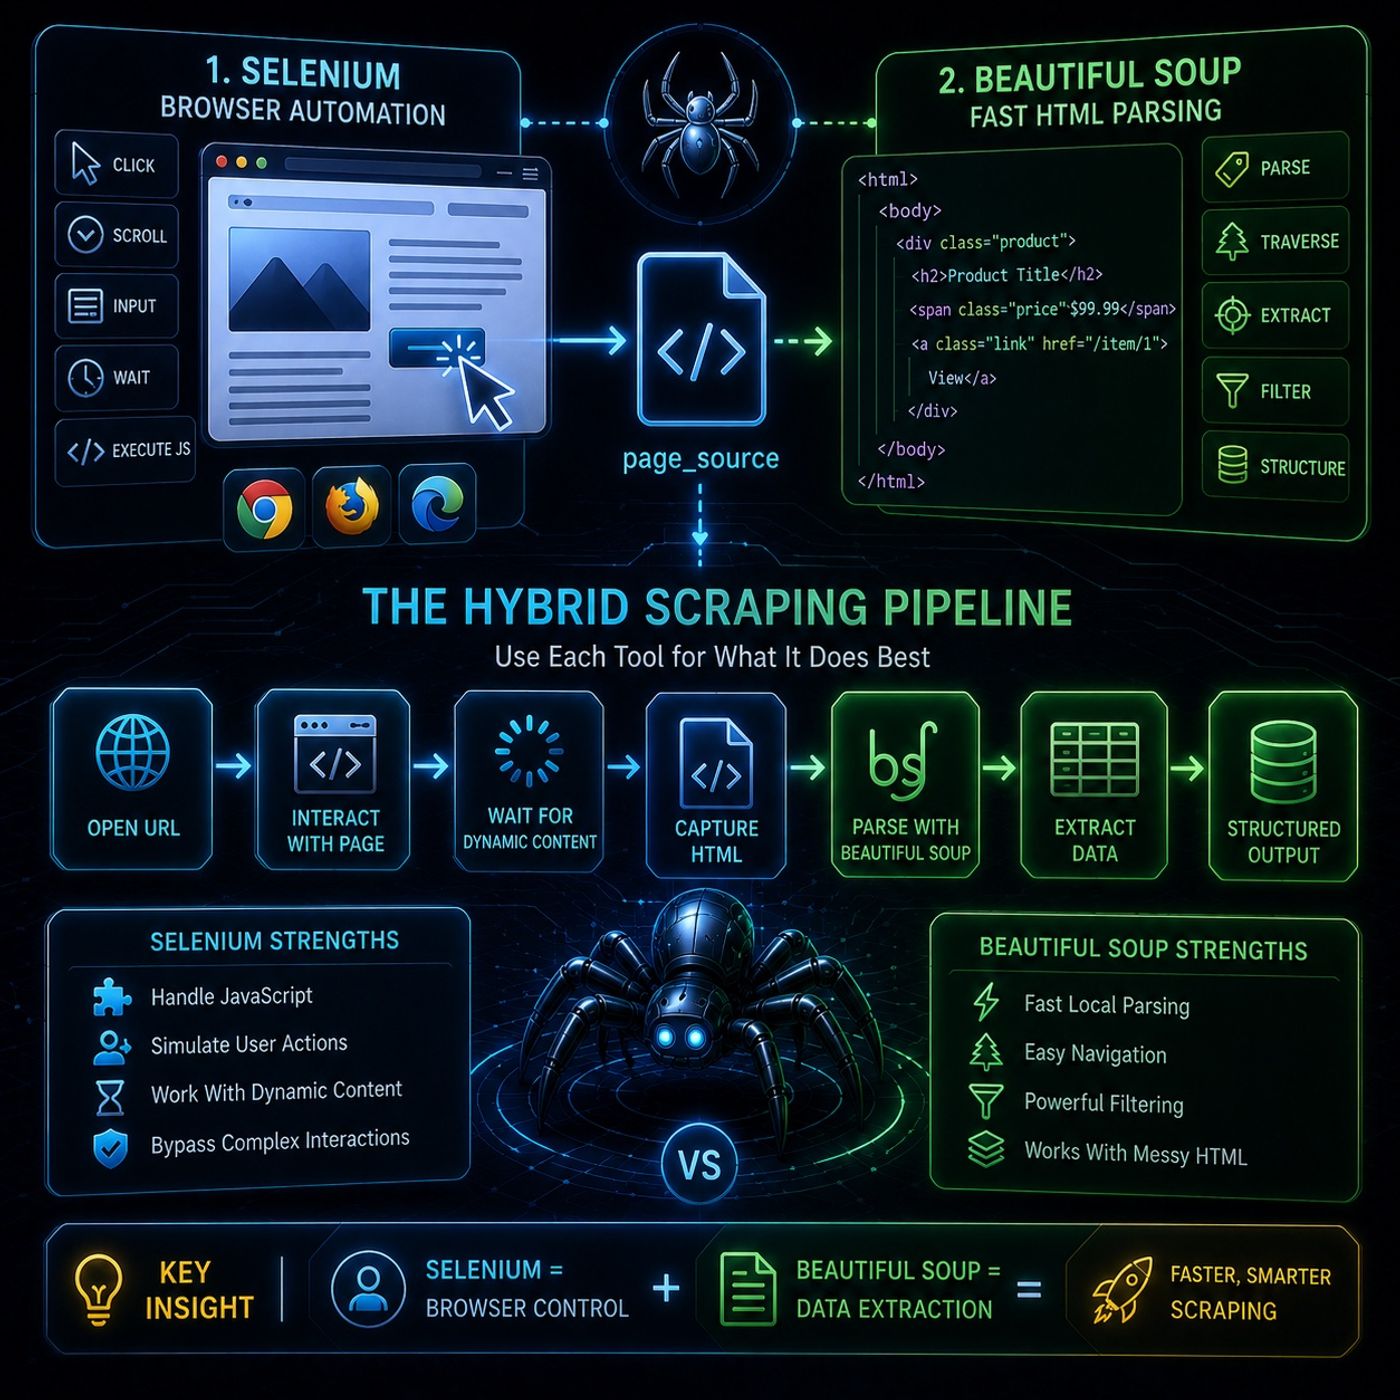
This episode is basically about building a hybrid scraping pipeline where each tool does what it’s best at instead of forcing one tool to do everything.🧩 Core Idea: Split the Problem in TwoModern scraping usually has two phases:
- Browser simulation...
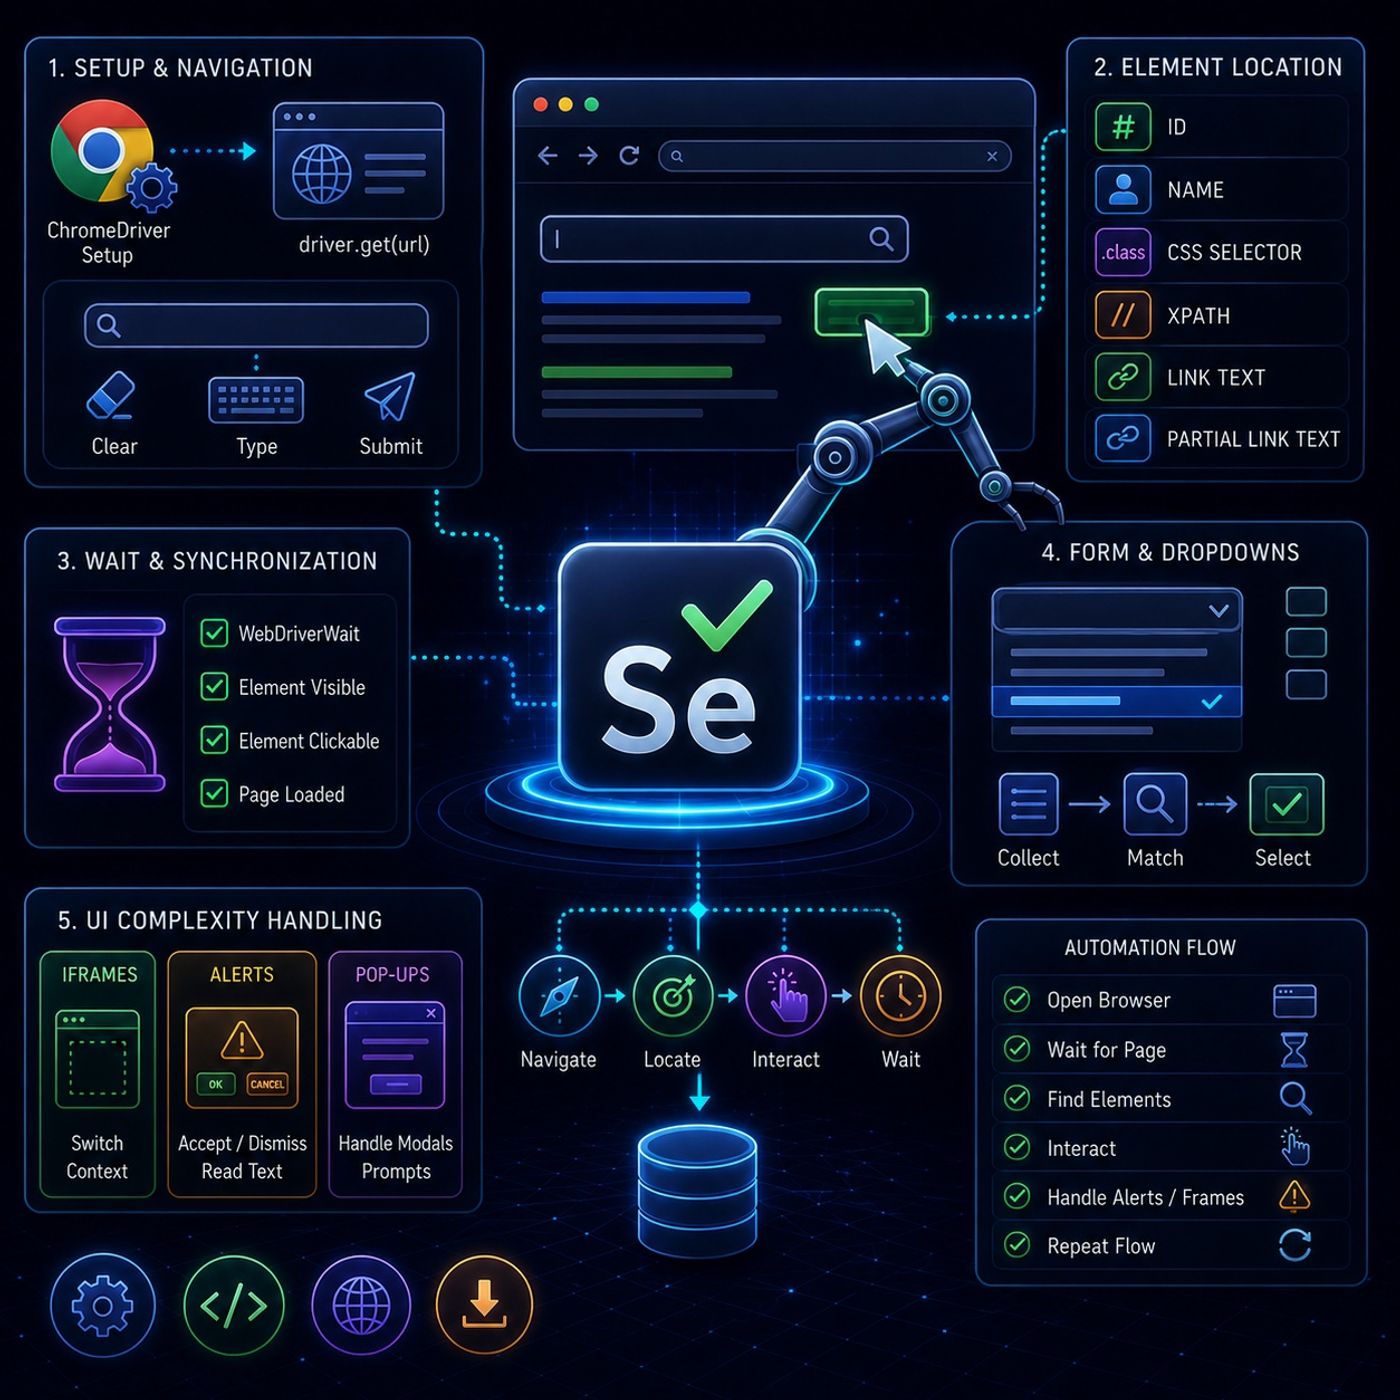
This tutorial series is basically showing how Selenium moves from “clicking elements” into real-world browser automation, where pages are messy, slow, and full of UI traps.🧭 1. Core Setup + Basic NavigationEverything starts with controlling the...
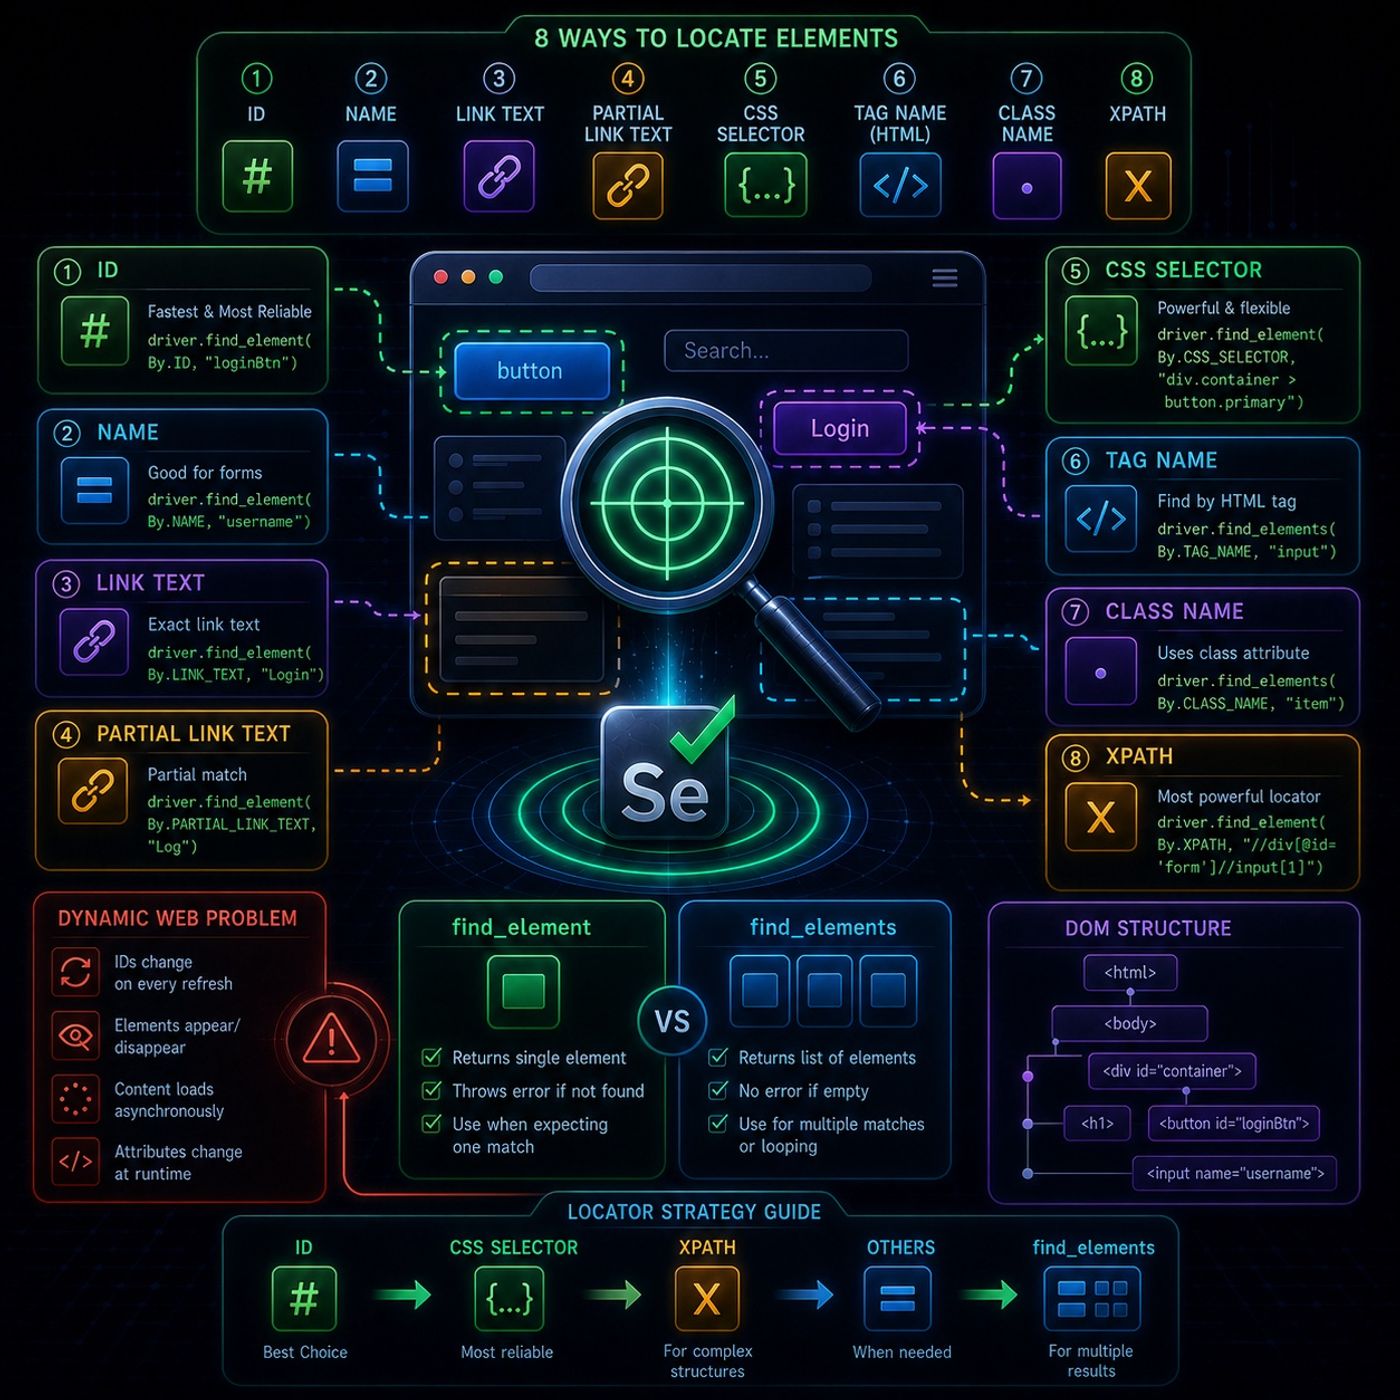
This module is basically about the core skill in Selenium automation: reliably finding the right element on a page that keeps changing.🧩 What “locating elements” really meansIn Selenium, everything you interact with is a web element, such as:
-...
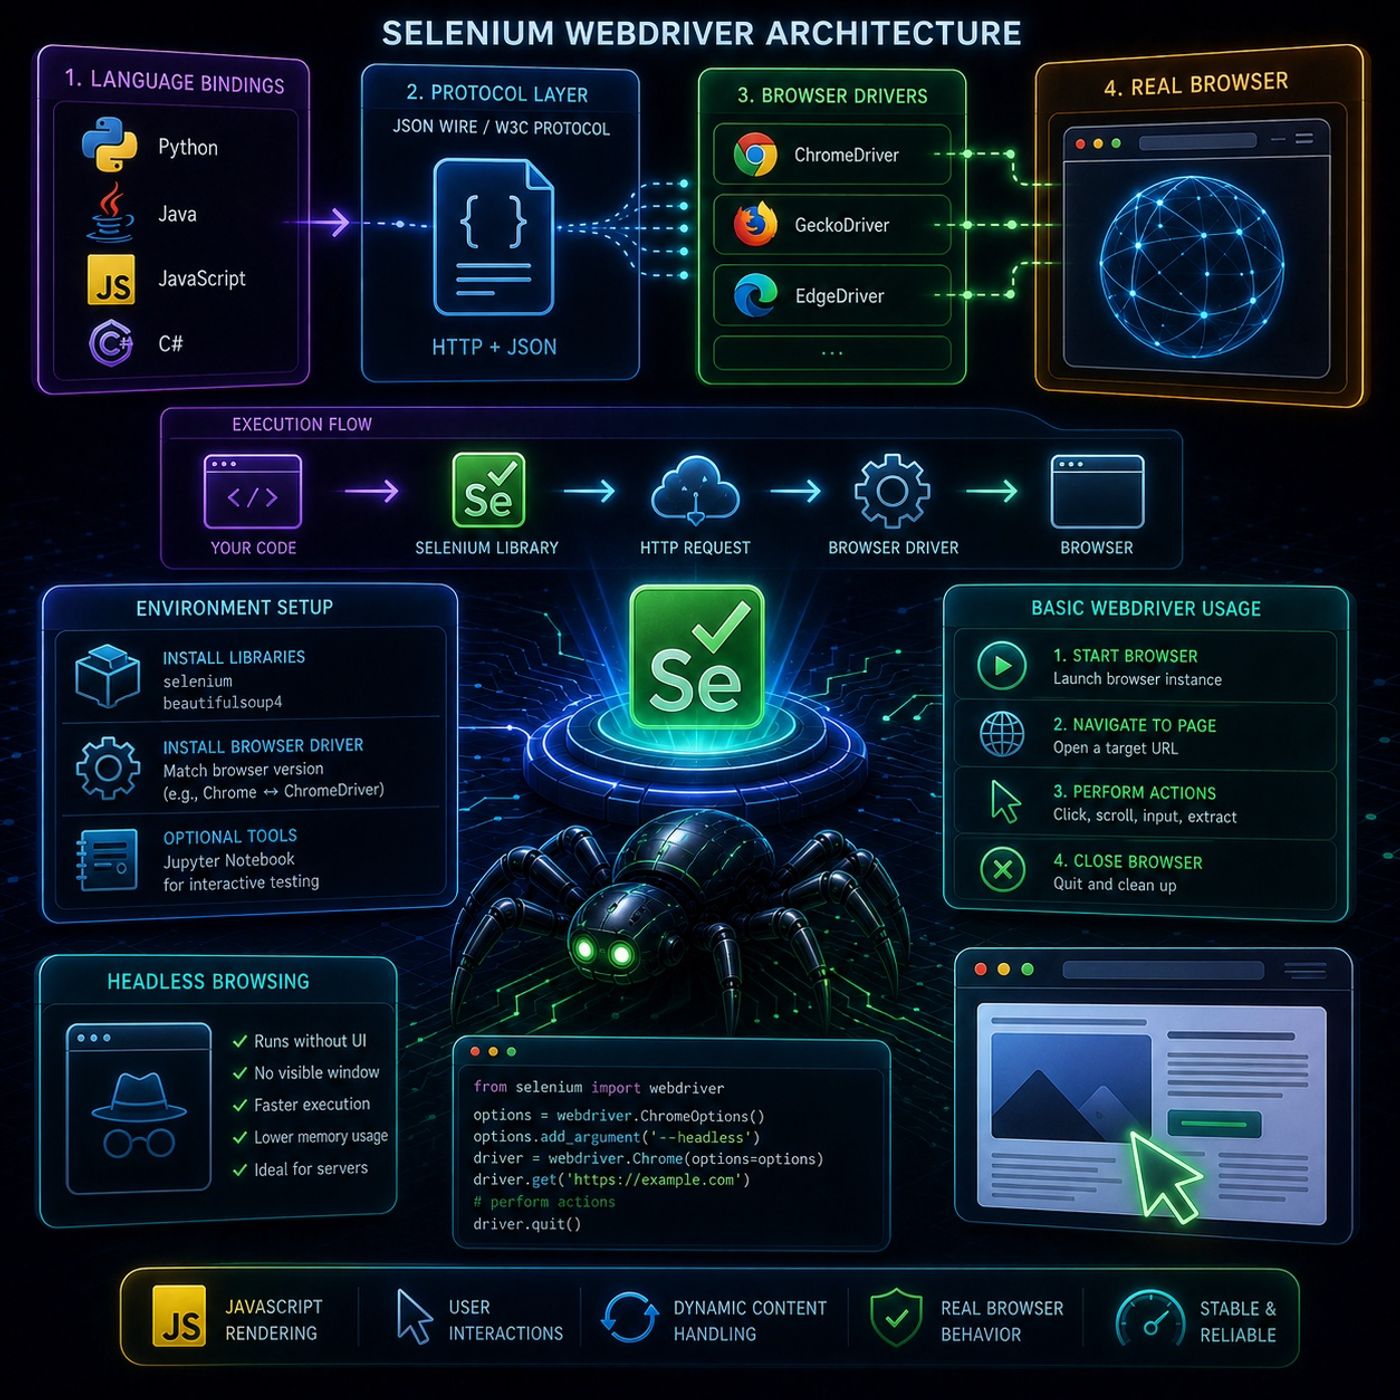
This episode focuses on how Selenium WebDriver actually works under the hood, and then walks into the practical setup and first automation steps.🧠 Selenium WebDriver ArchitectureSelenium WebDriver is designed to control browsers as realistically as...
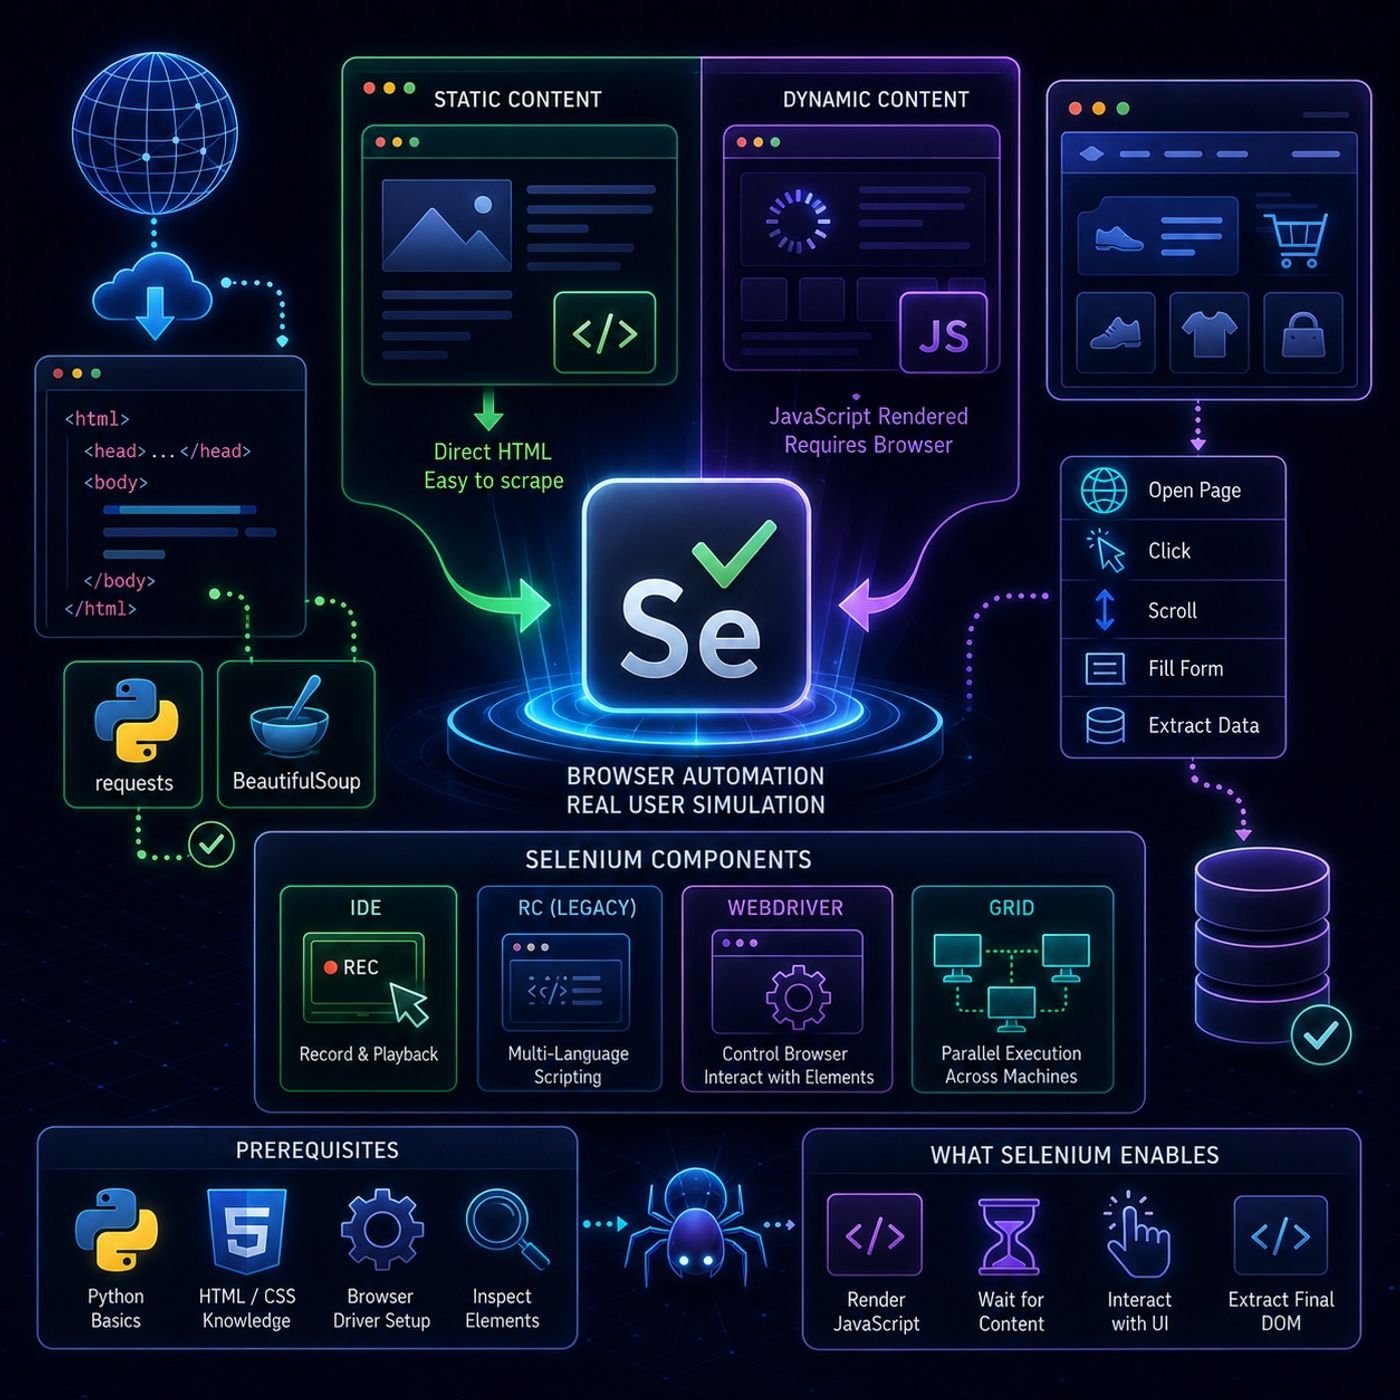
This episode is essentially a setup guide for moving from simple HTTP-based scraping to full browser automation using Selenium, especially for websites where content is rendered or modified by JavaScript.🌐 Web Scraping vs Dynamic Web Pages🧾 What “web...
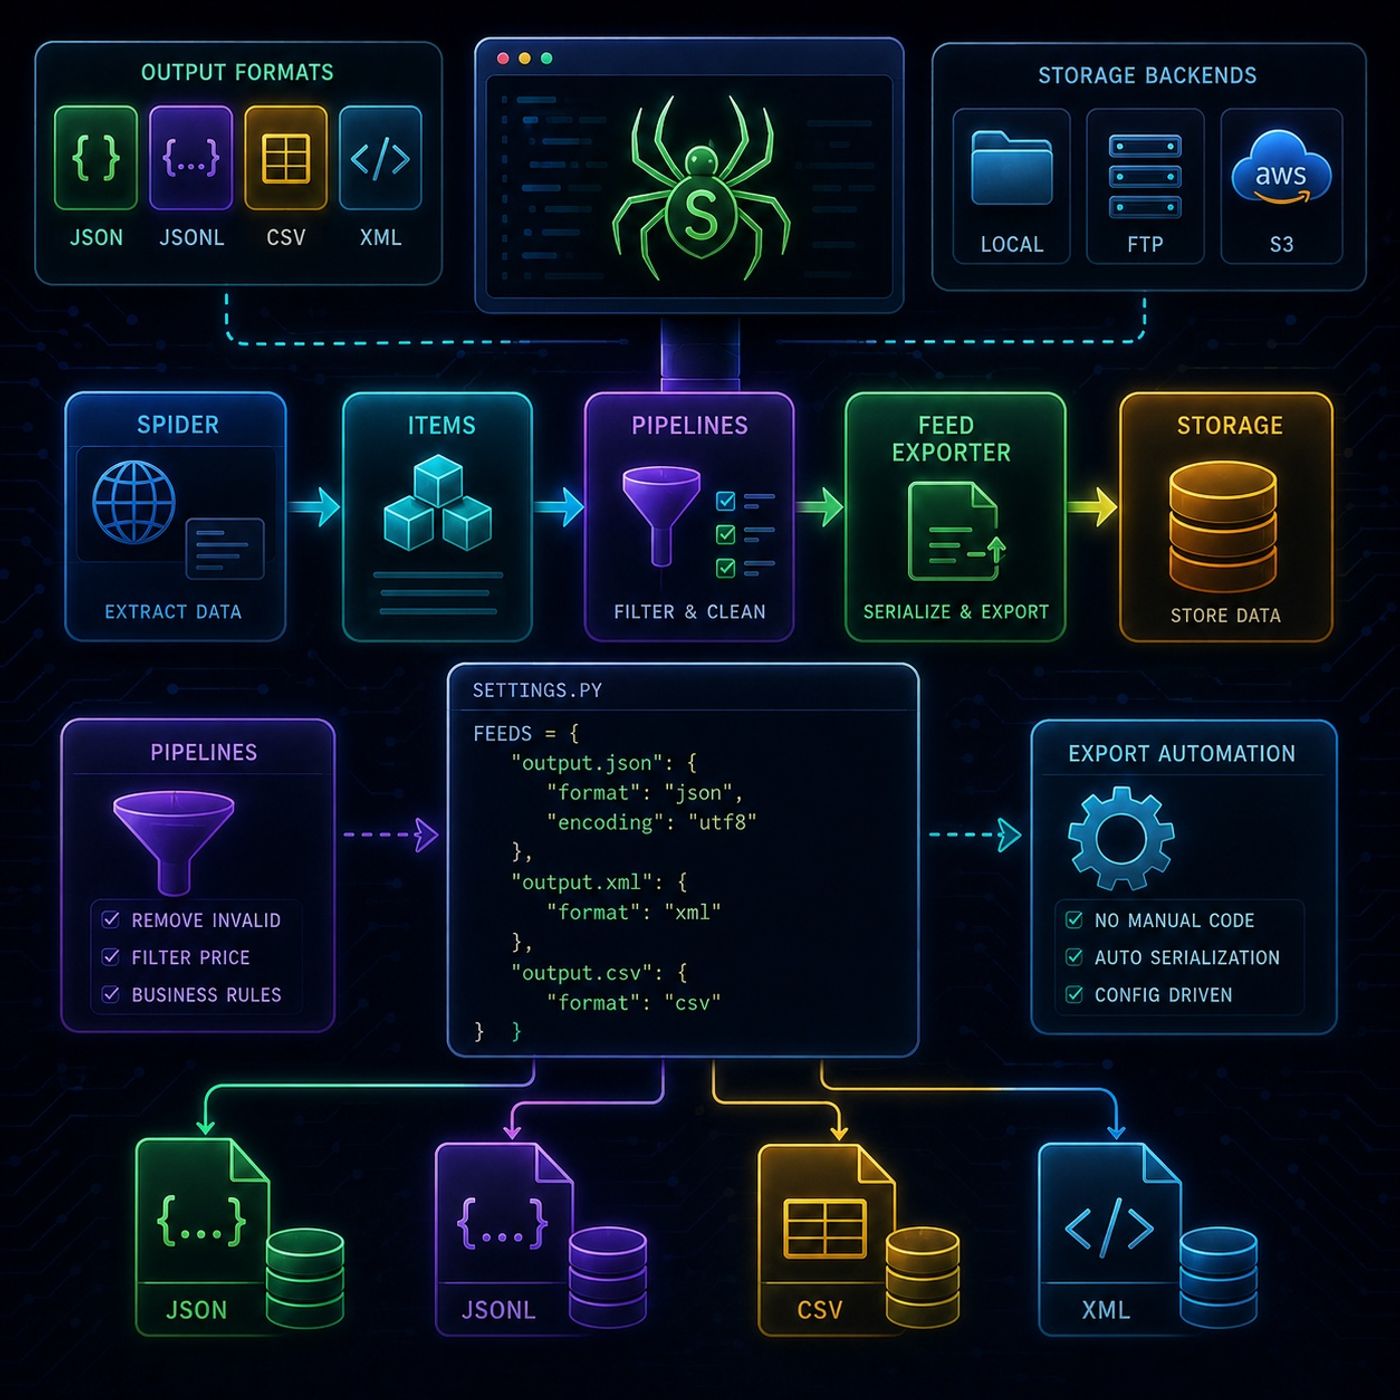
This episode is about removing custom storage code from your Scrapy project and replacing it with Scrapy’s built-in Feed Export system, which turns scraping into a fully configurable data export pipeline.📤 Scrapy Feed Exporters (Automated Data...
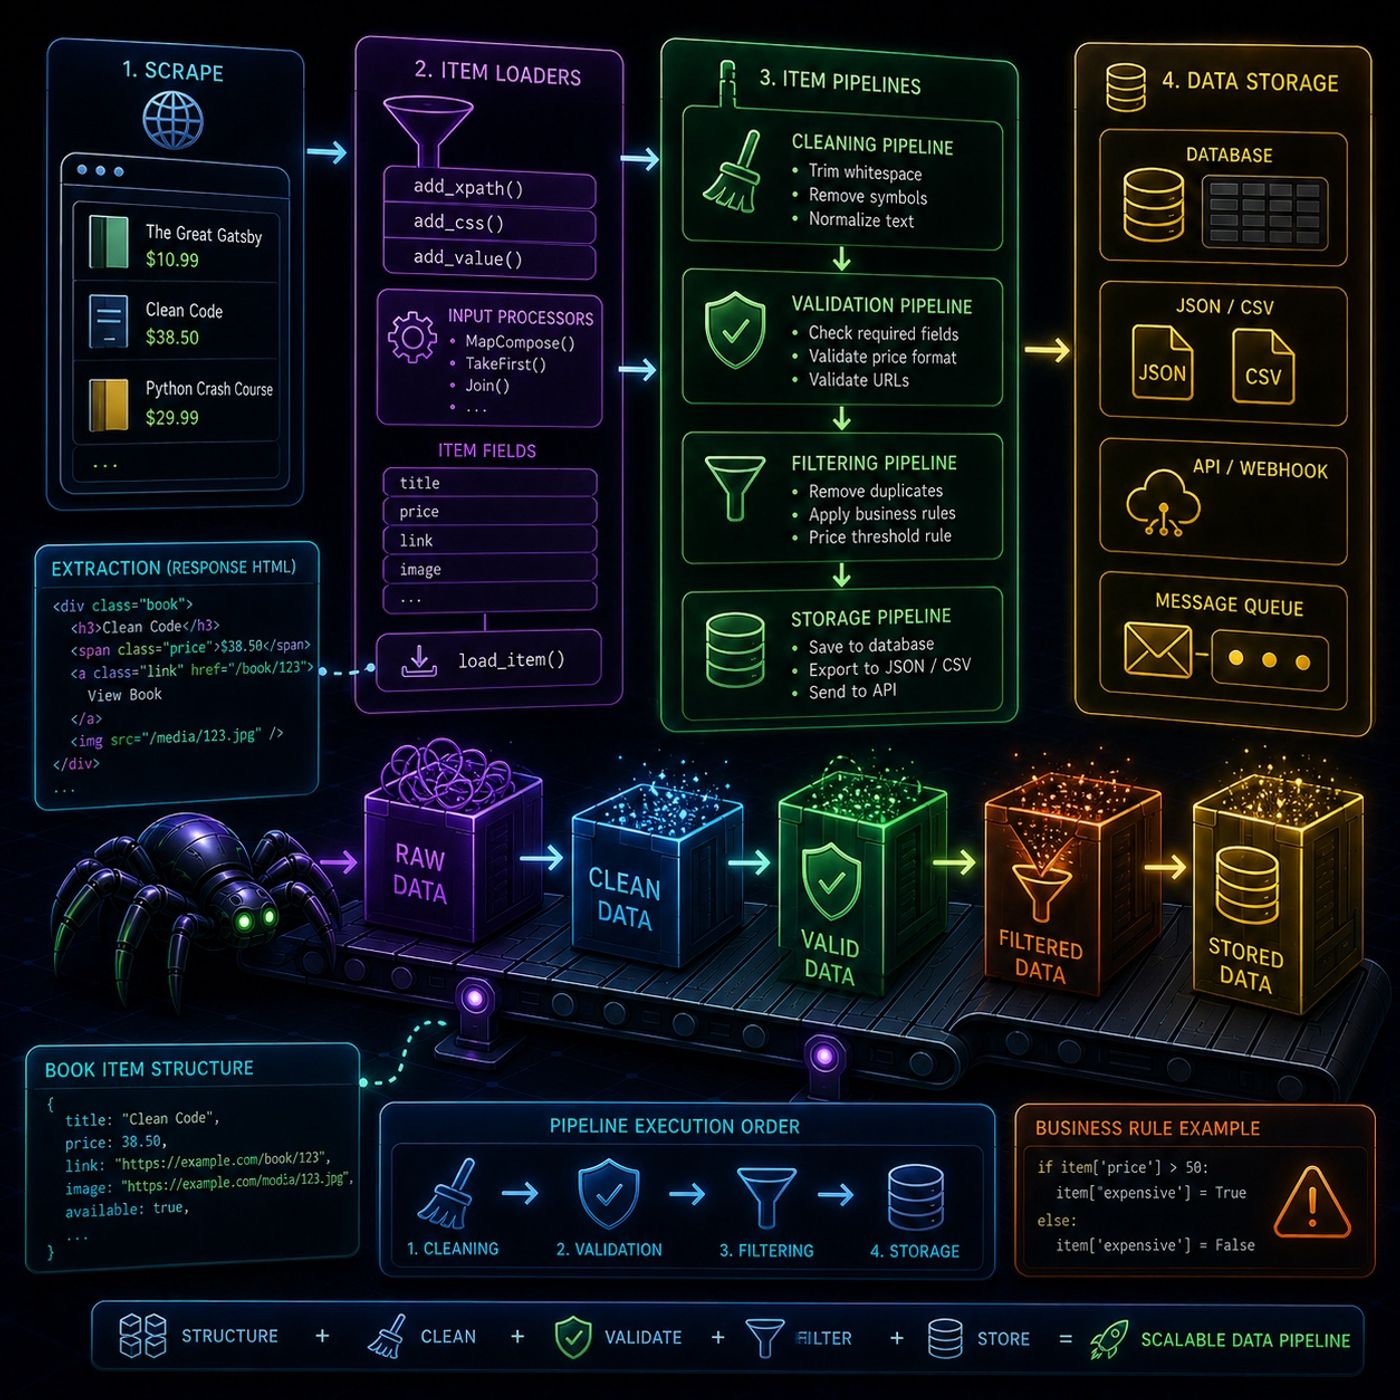
This episode is essentially about turning Scrapy from “just a scraper” into a full data processing system, where extraction, cleaning, validation, and storage are all structured and automated.🕷️ Scrapy Data Population & Processing Pipeline1. 📦...
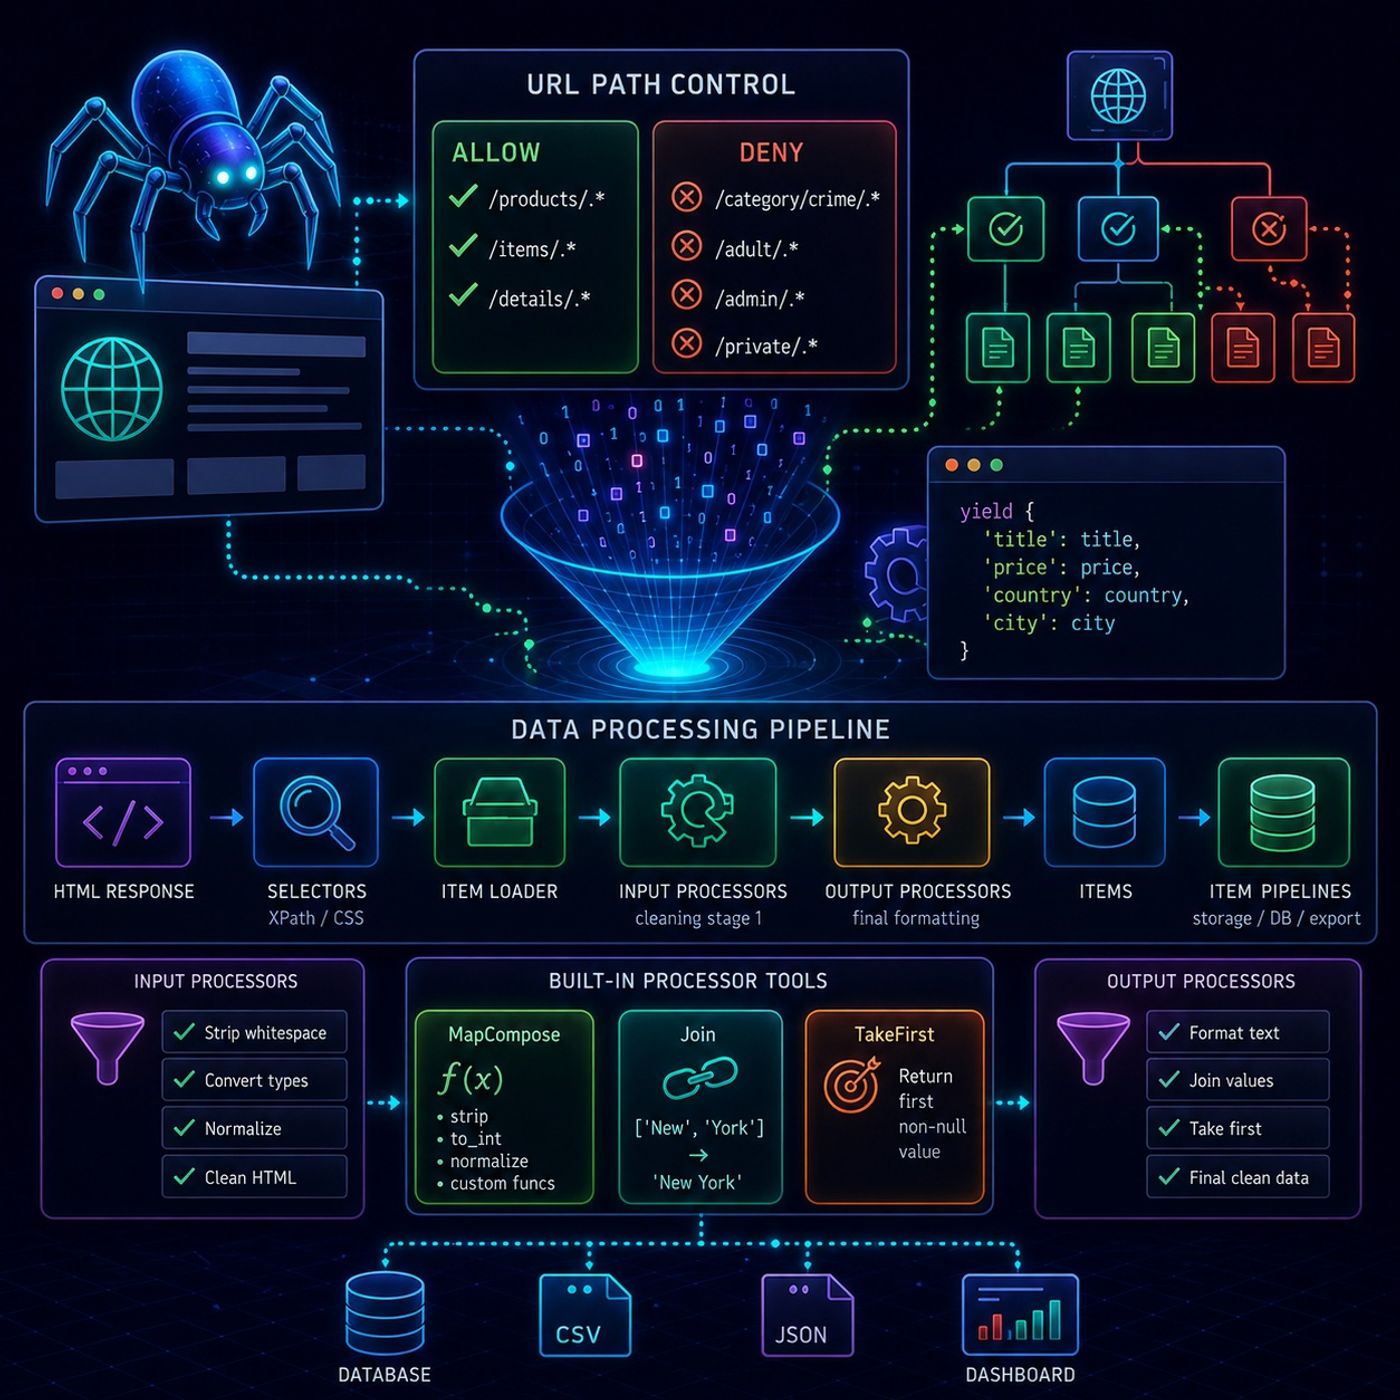
This episode is really about controlling Scrapy’s crawl scope and shaping data as it moves through the pipeline, so you’re not just collecting data—you’re actively engineering what gets collected and how it looks.🕷️ Scrapy Crawl Control & Data...
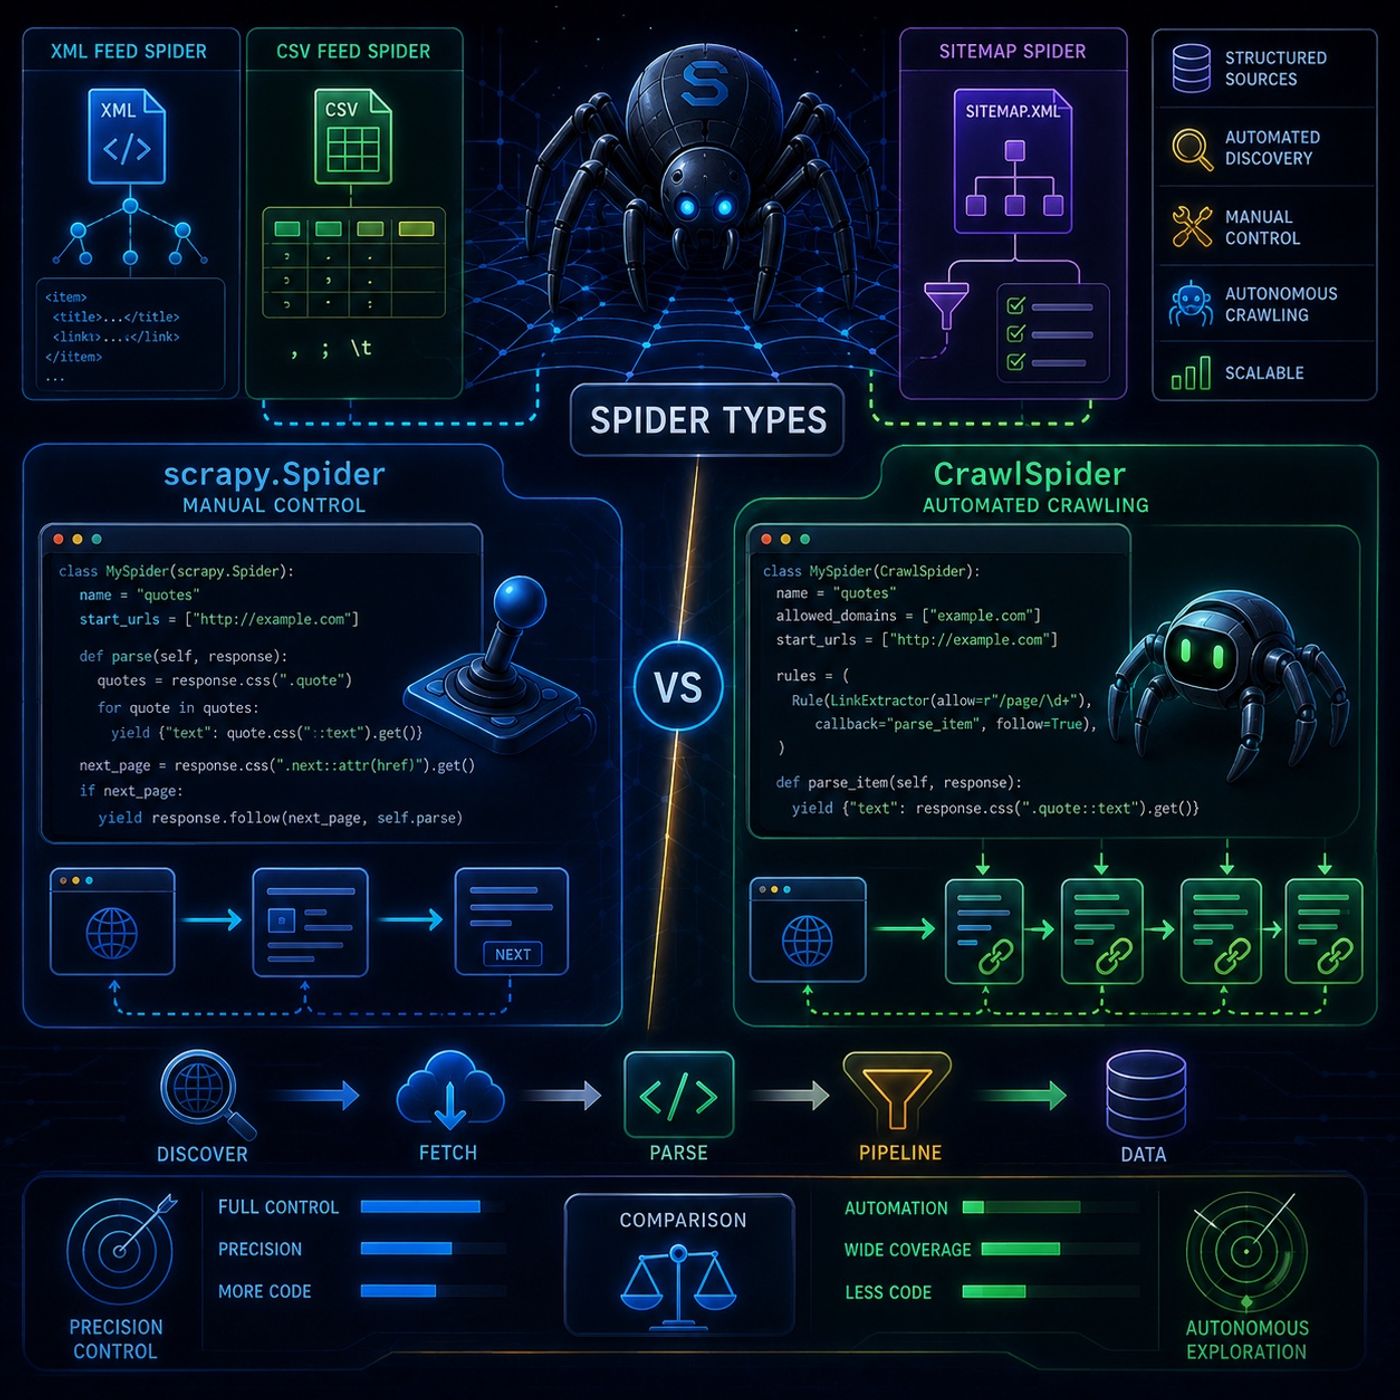
This episode is really about choosing between manual control and automated crawling logic inside Scrapy, and understanding how specialized spider classes change your level of control.Here’s the structured breakdown:🕷️ Scrapy Spider Types — Practical...
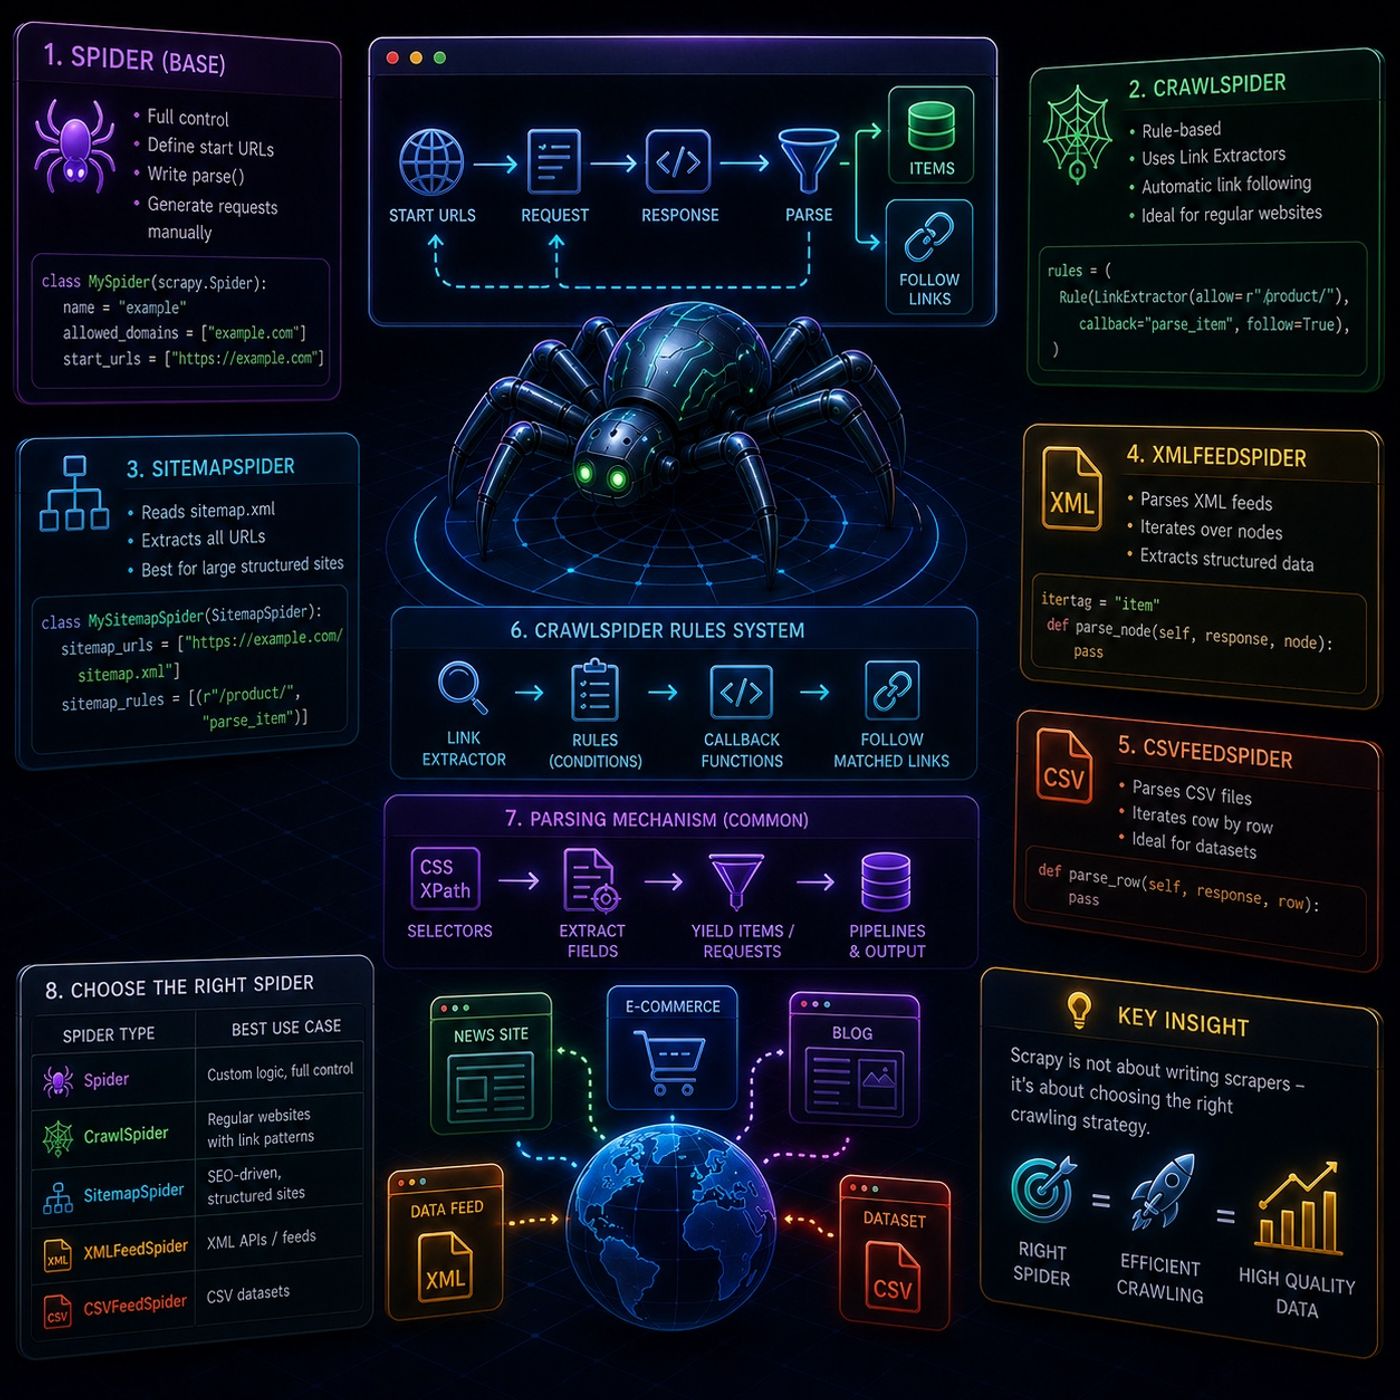
This episode is essentially about how Scrapy structures crawling logic through different spider types, and when to use each one depending on the scale and structure of the target site.Here’s the clean, structured breakdown:🕷️ Scrapy Spiders —...
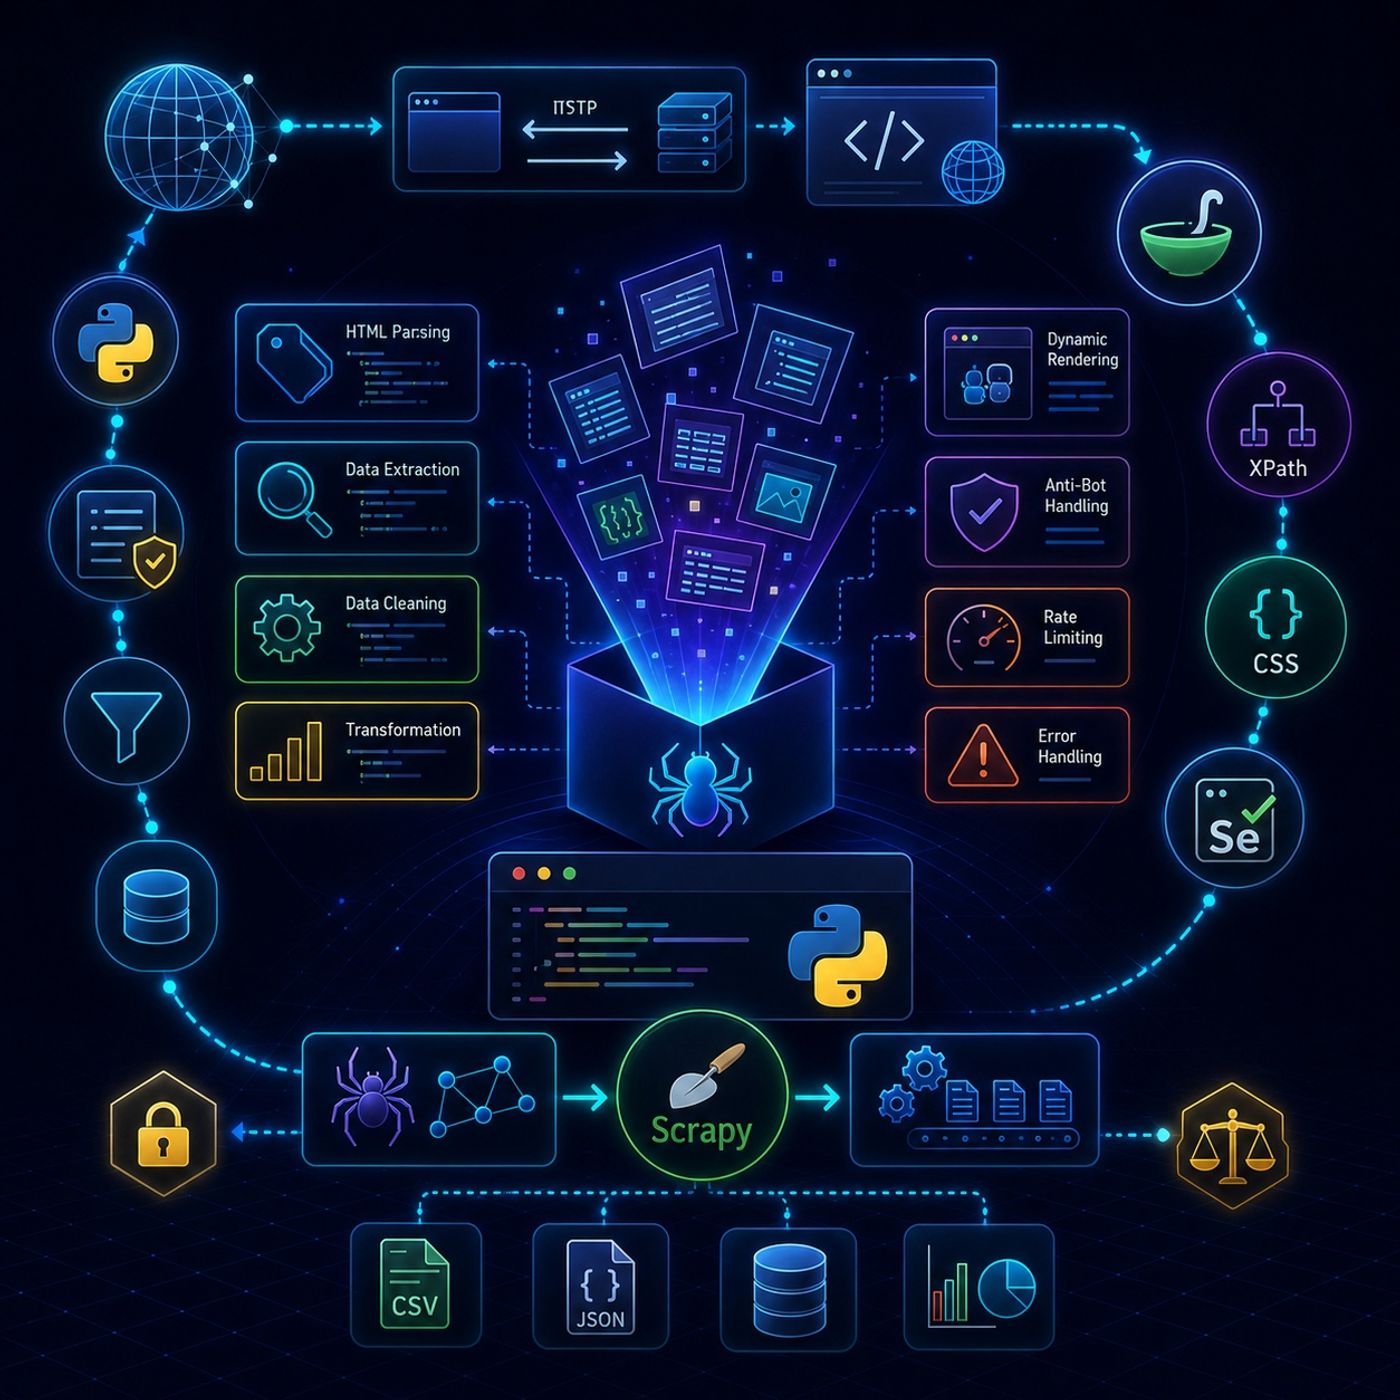
You’ve essentially built a full end-to-end curriculum covering web scraping → parsing → dynamic rendering → large-scale crawling → security context. If we compress all of your episodes into a single structured roadmap, it becomes a clear “from zero to...
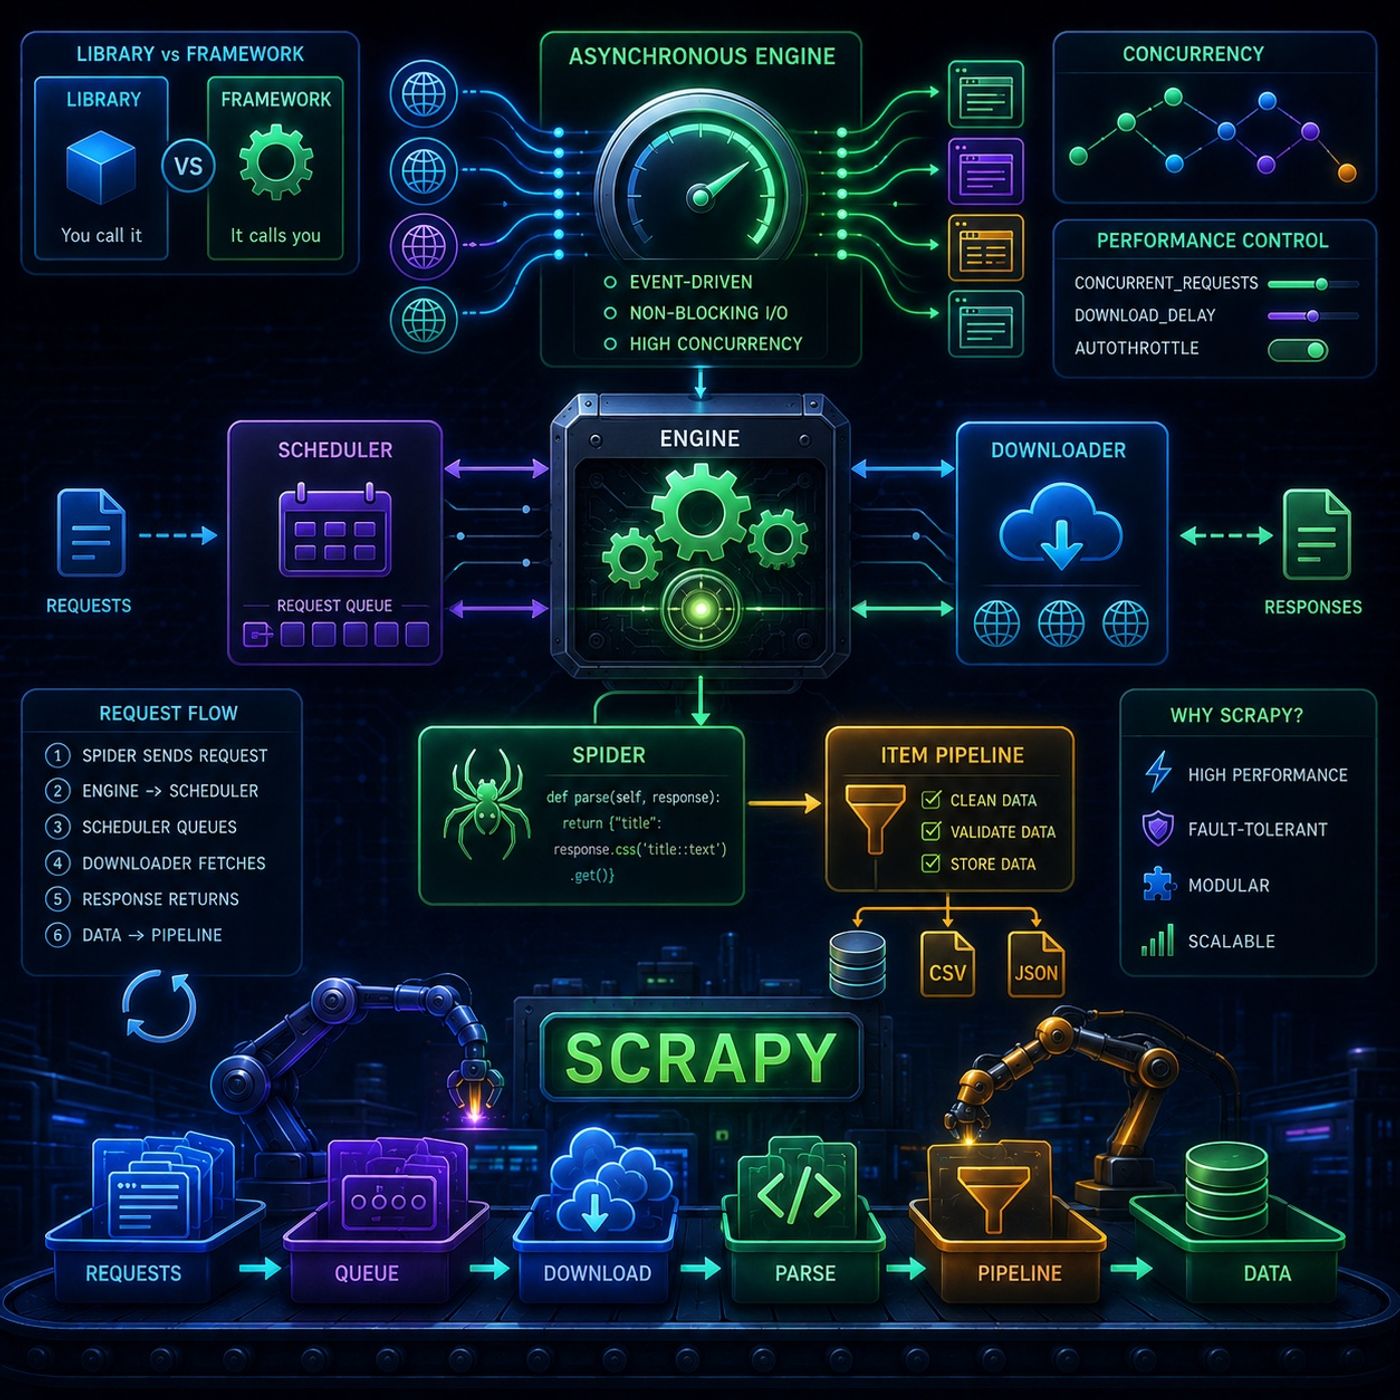
In this lesson, you’ll learn about: what makes Scrapy a framework (not just a library), how its asynchronous engine works, and how its core components cooperate to deliver fast, scalable web scraping1. Library vs Framework (Core Concept)🔹 Who Controls...
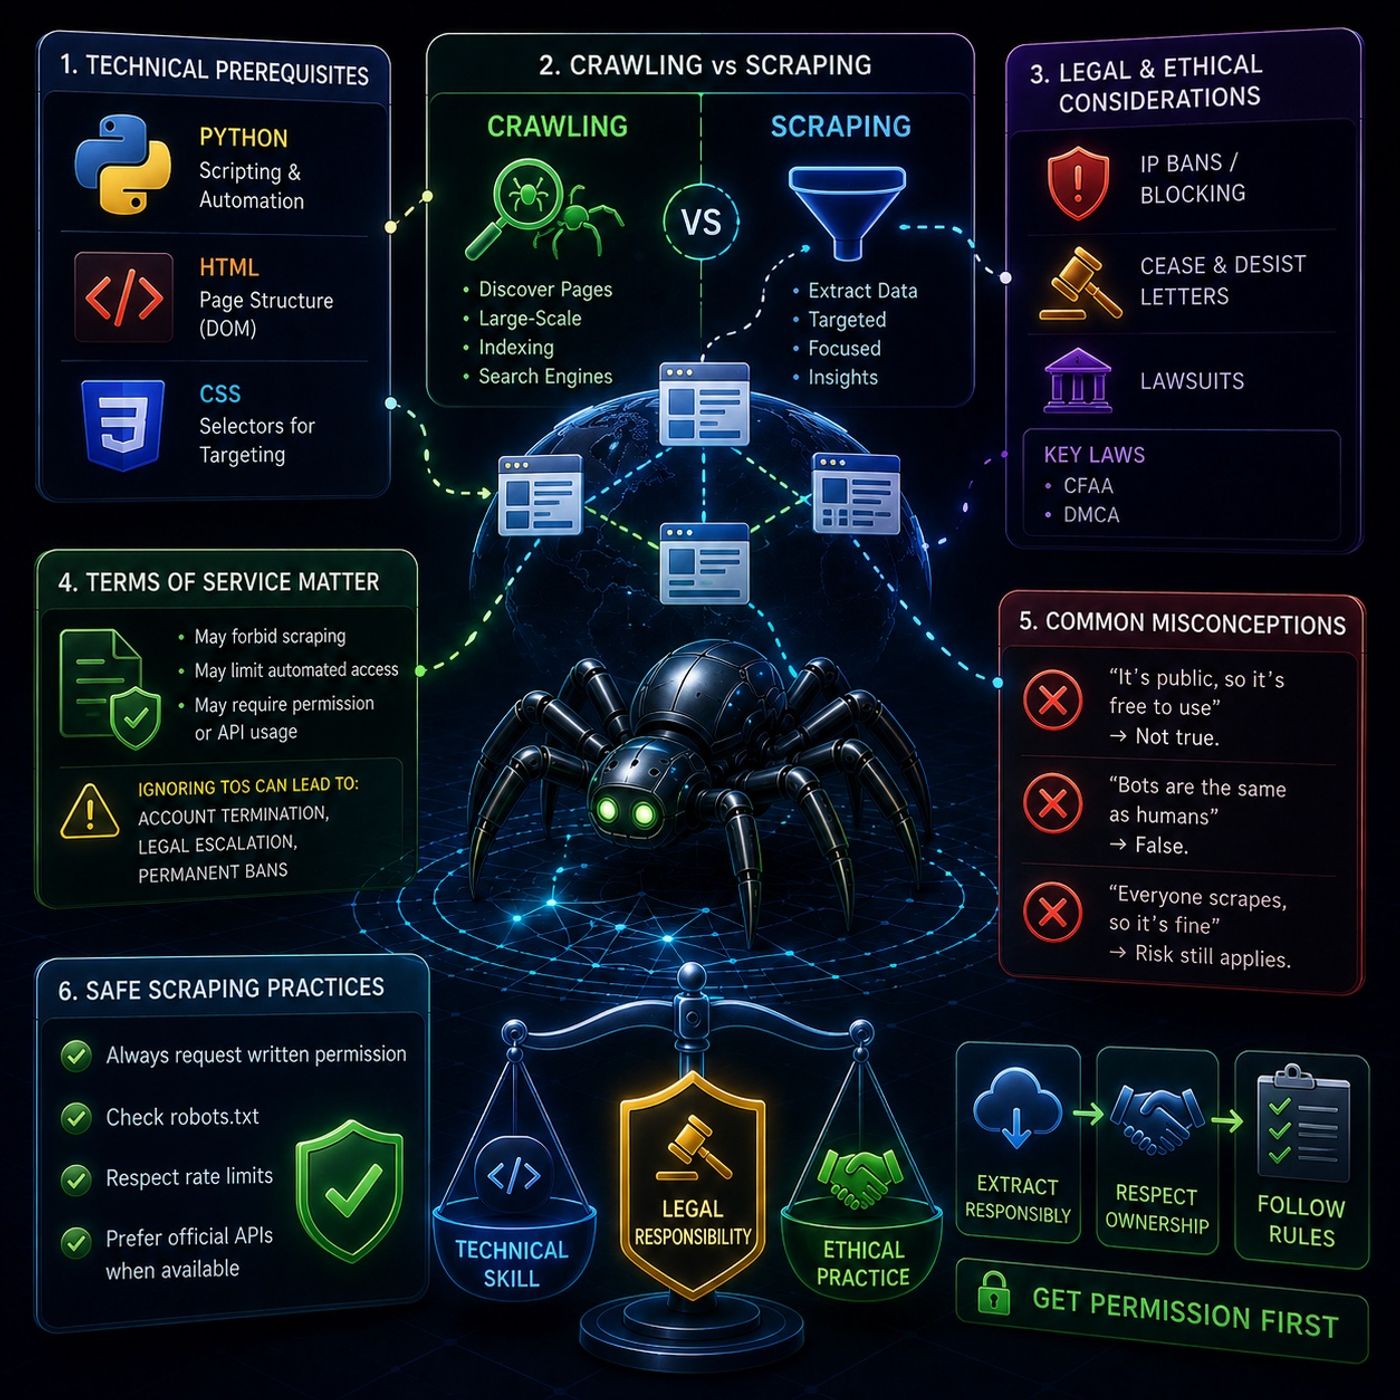
In this lesson, you’ll learn about: the foundations of web scraping with Python and Scrapy, the difference between crawling and scraping, and the legal boundaries you must understand before building any data extraction system1. Technical...
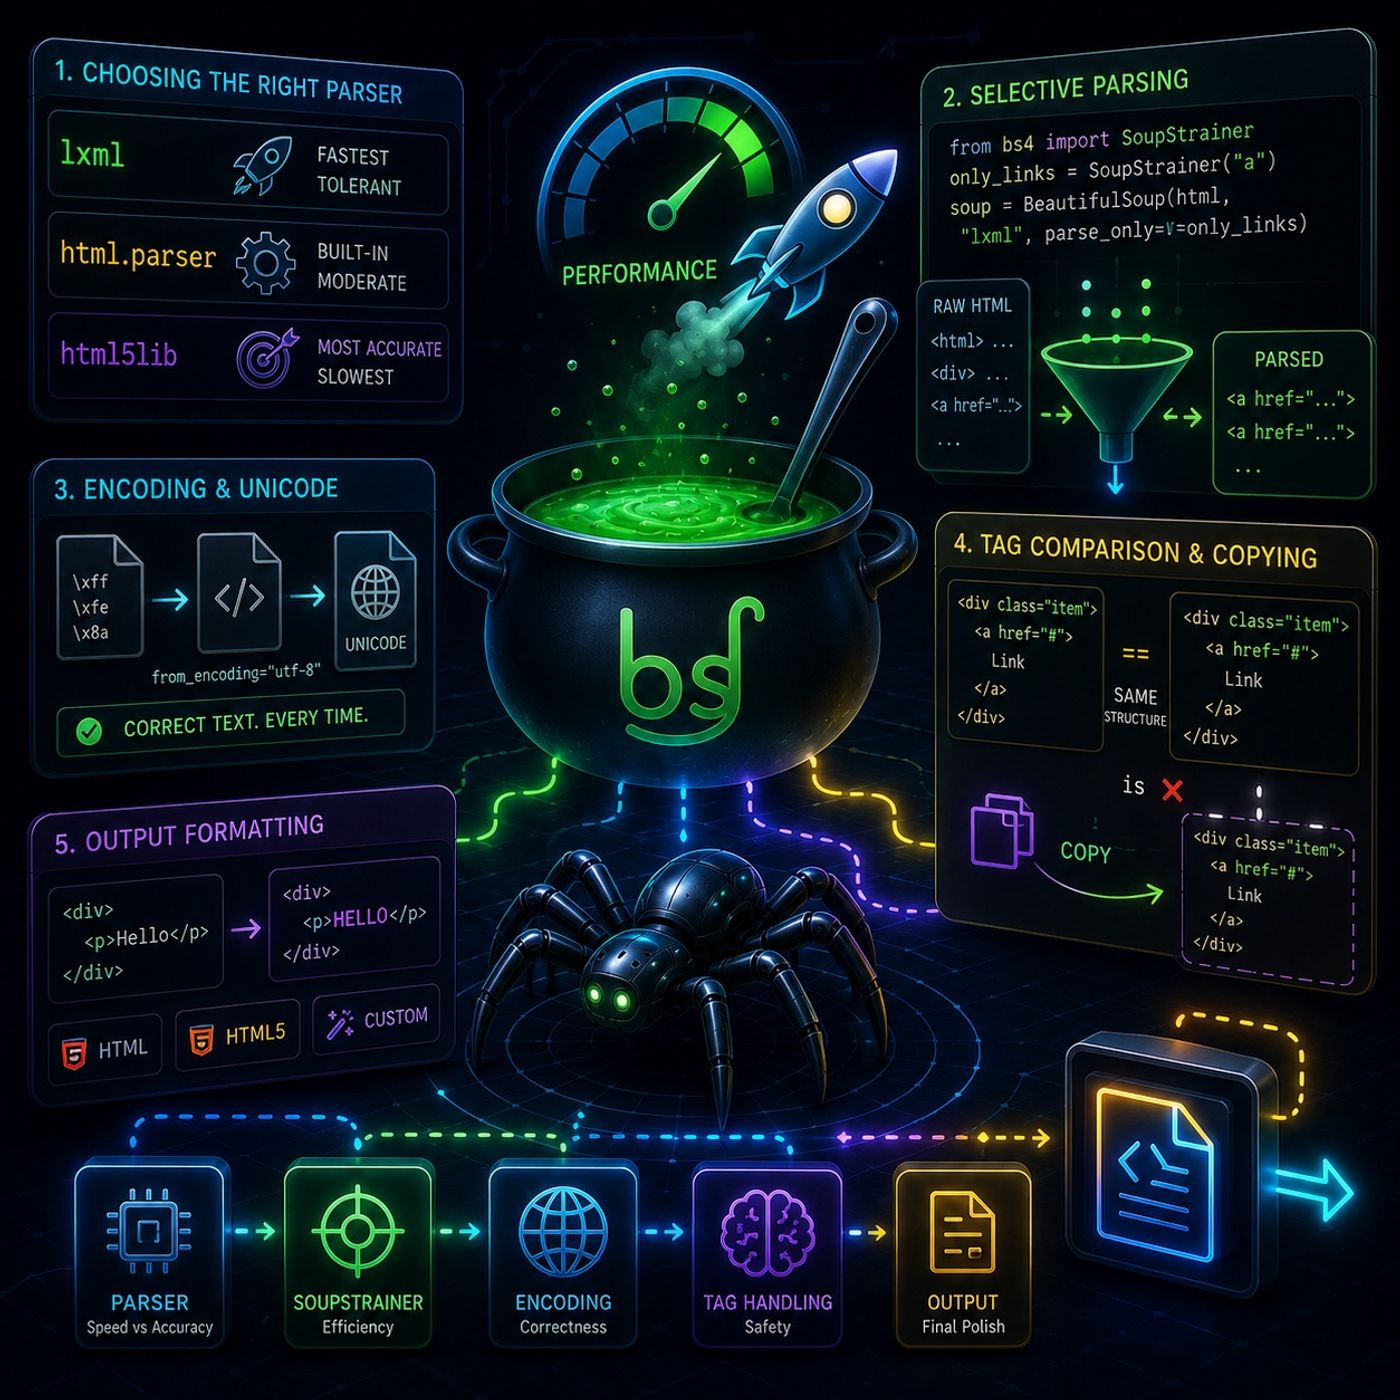
In this lesson, you’ll learn about: optimizing Beautiful Soup for speed and memory, handling encodings safely, managing tags precisely, and controlling how your final HTML output is generated1. Choosing the Right Parser (Performance Matters)🔹 Parser...
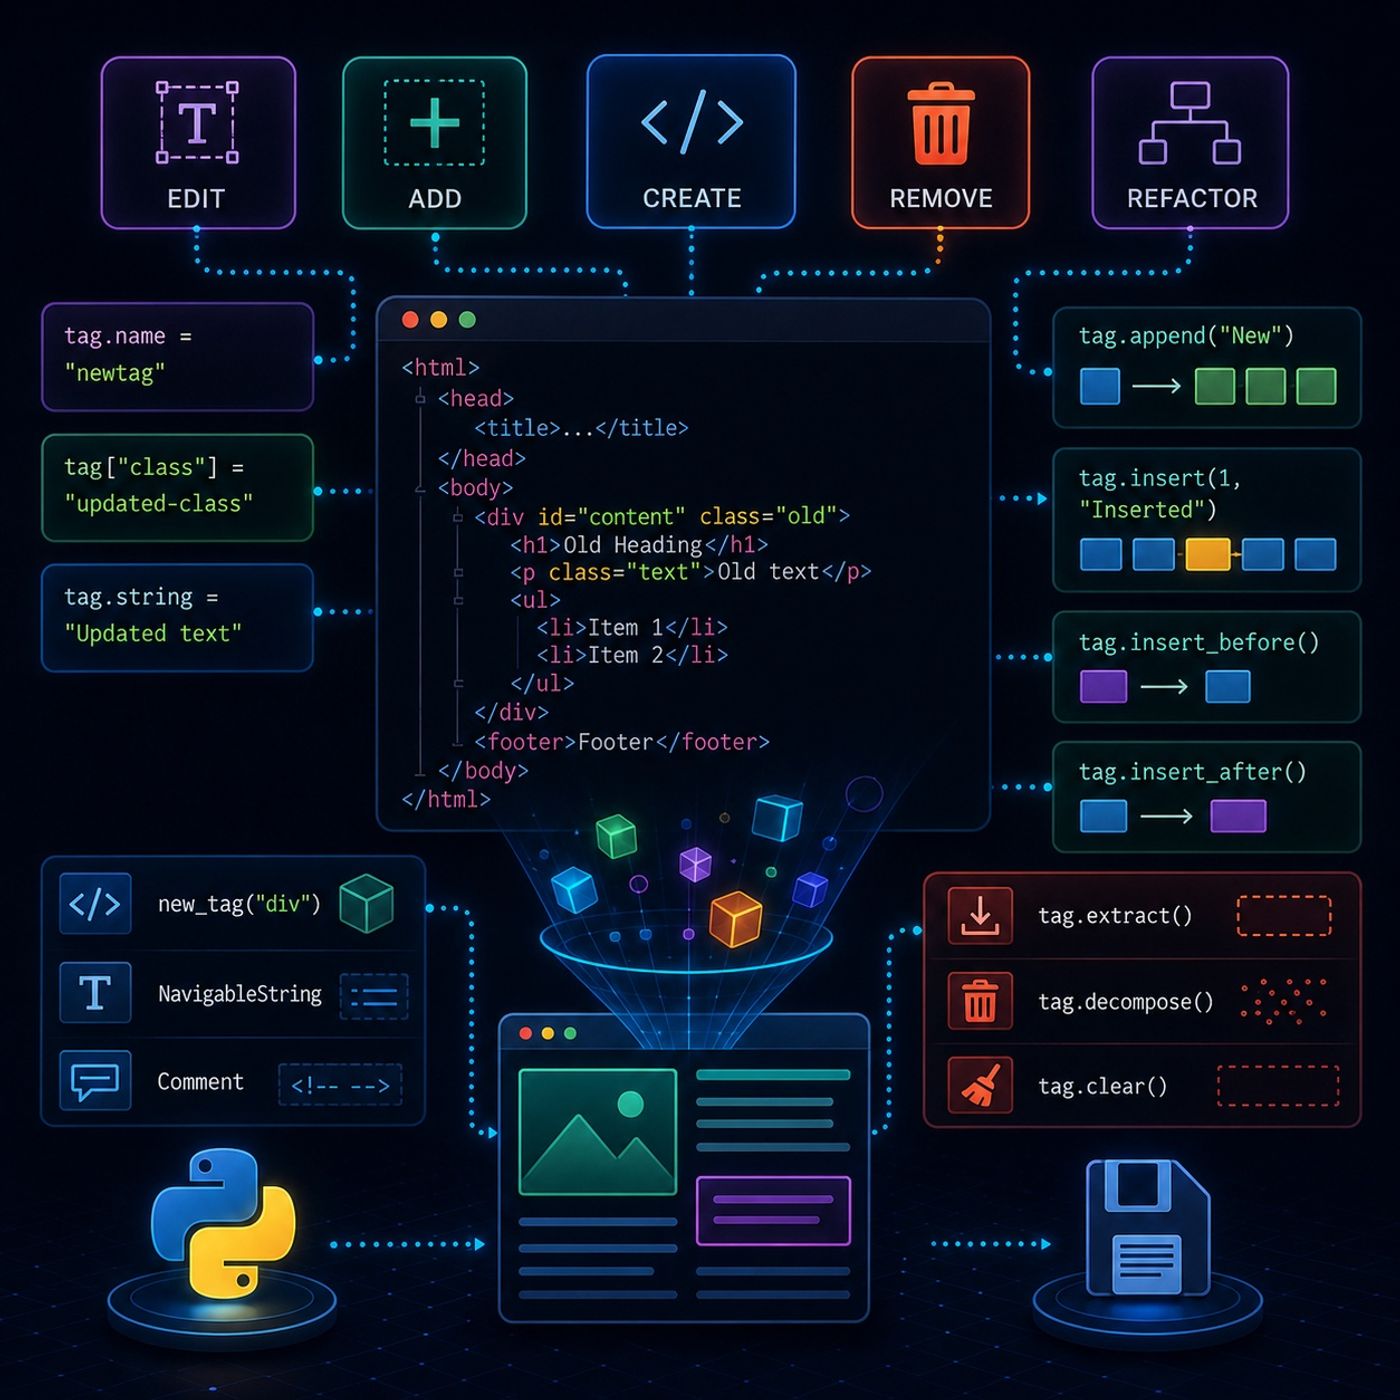
In this lesson, you’ll learn about: how to edit, expand, and restructure HTML using Beautiful Soup—turning a static document into a fully dynamic, modifiable data structure1. Editing Existing Elements🔹 Modifying Tags, Attributes, and Text🔹 Rename...