Skip to content
Artwork for Best AI papers explained

Best AI papers explained

Enoch H. Kang

Cut through the noise. We curate and break down the most important AI papers so you don’t have to.

Play
  • 61 episodes
  • Avg 21 min
  • English
Counted on this page — what you have heard stays on this device, so it is not something the list can be paged by.
  • August 15 · 22 min

    Predicting Neural Scaling Laws without Training: A Data Manifold Oracle

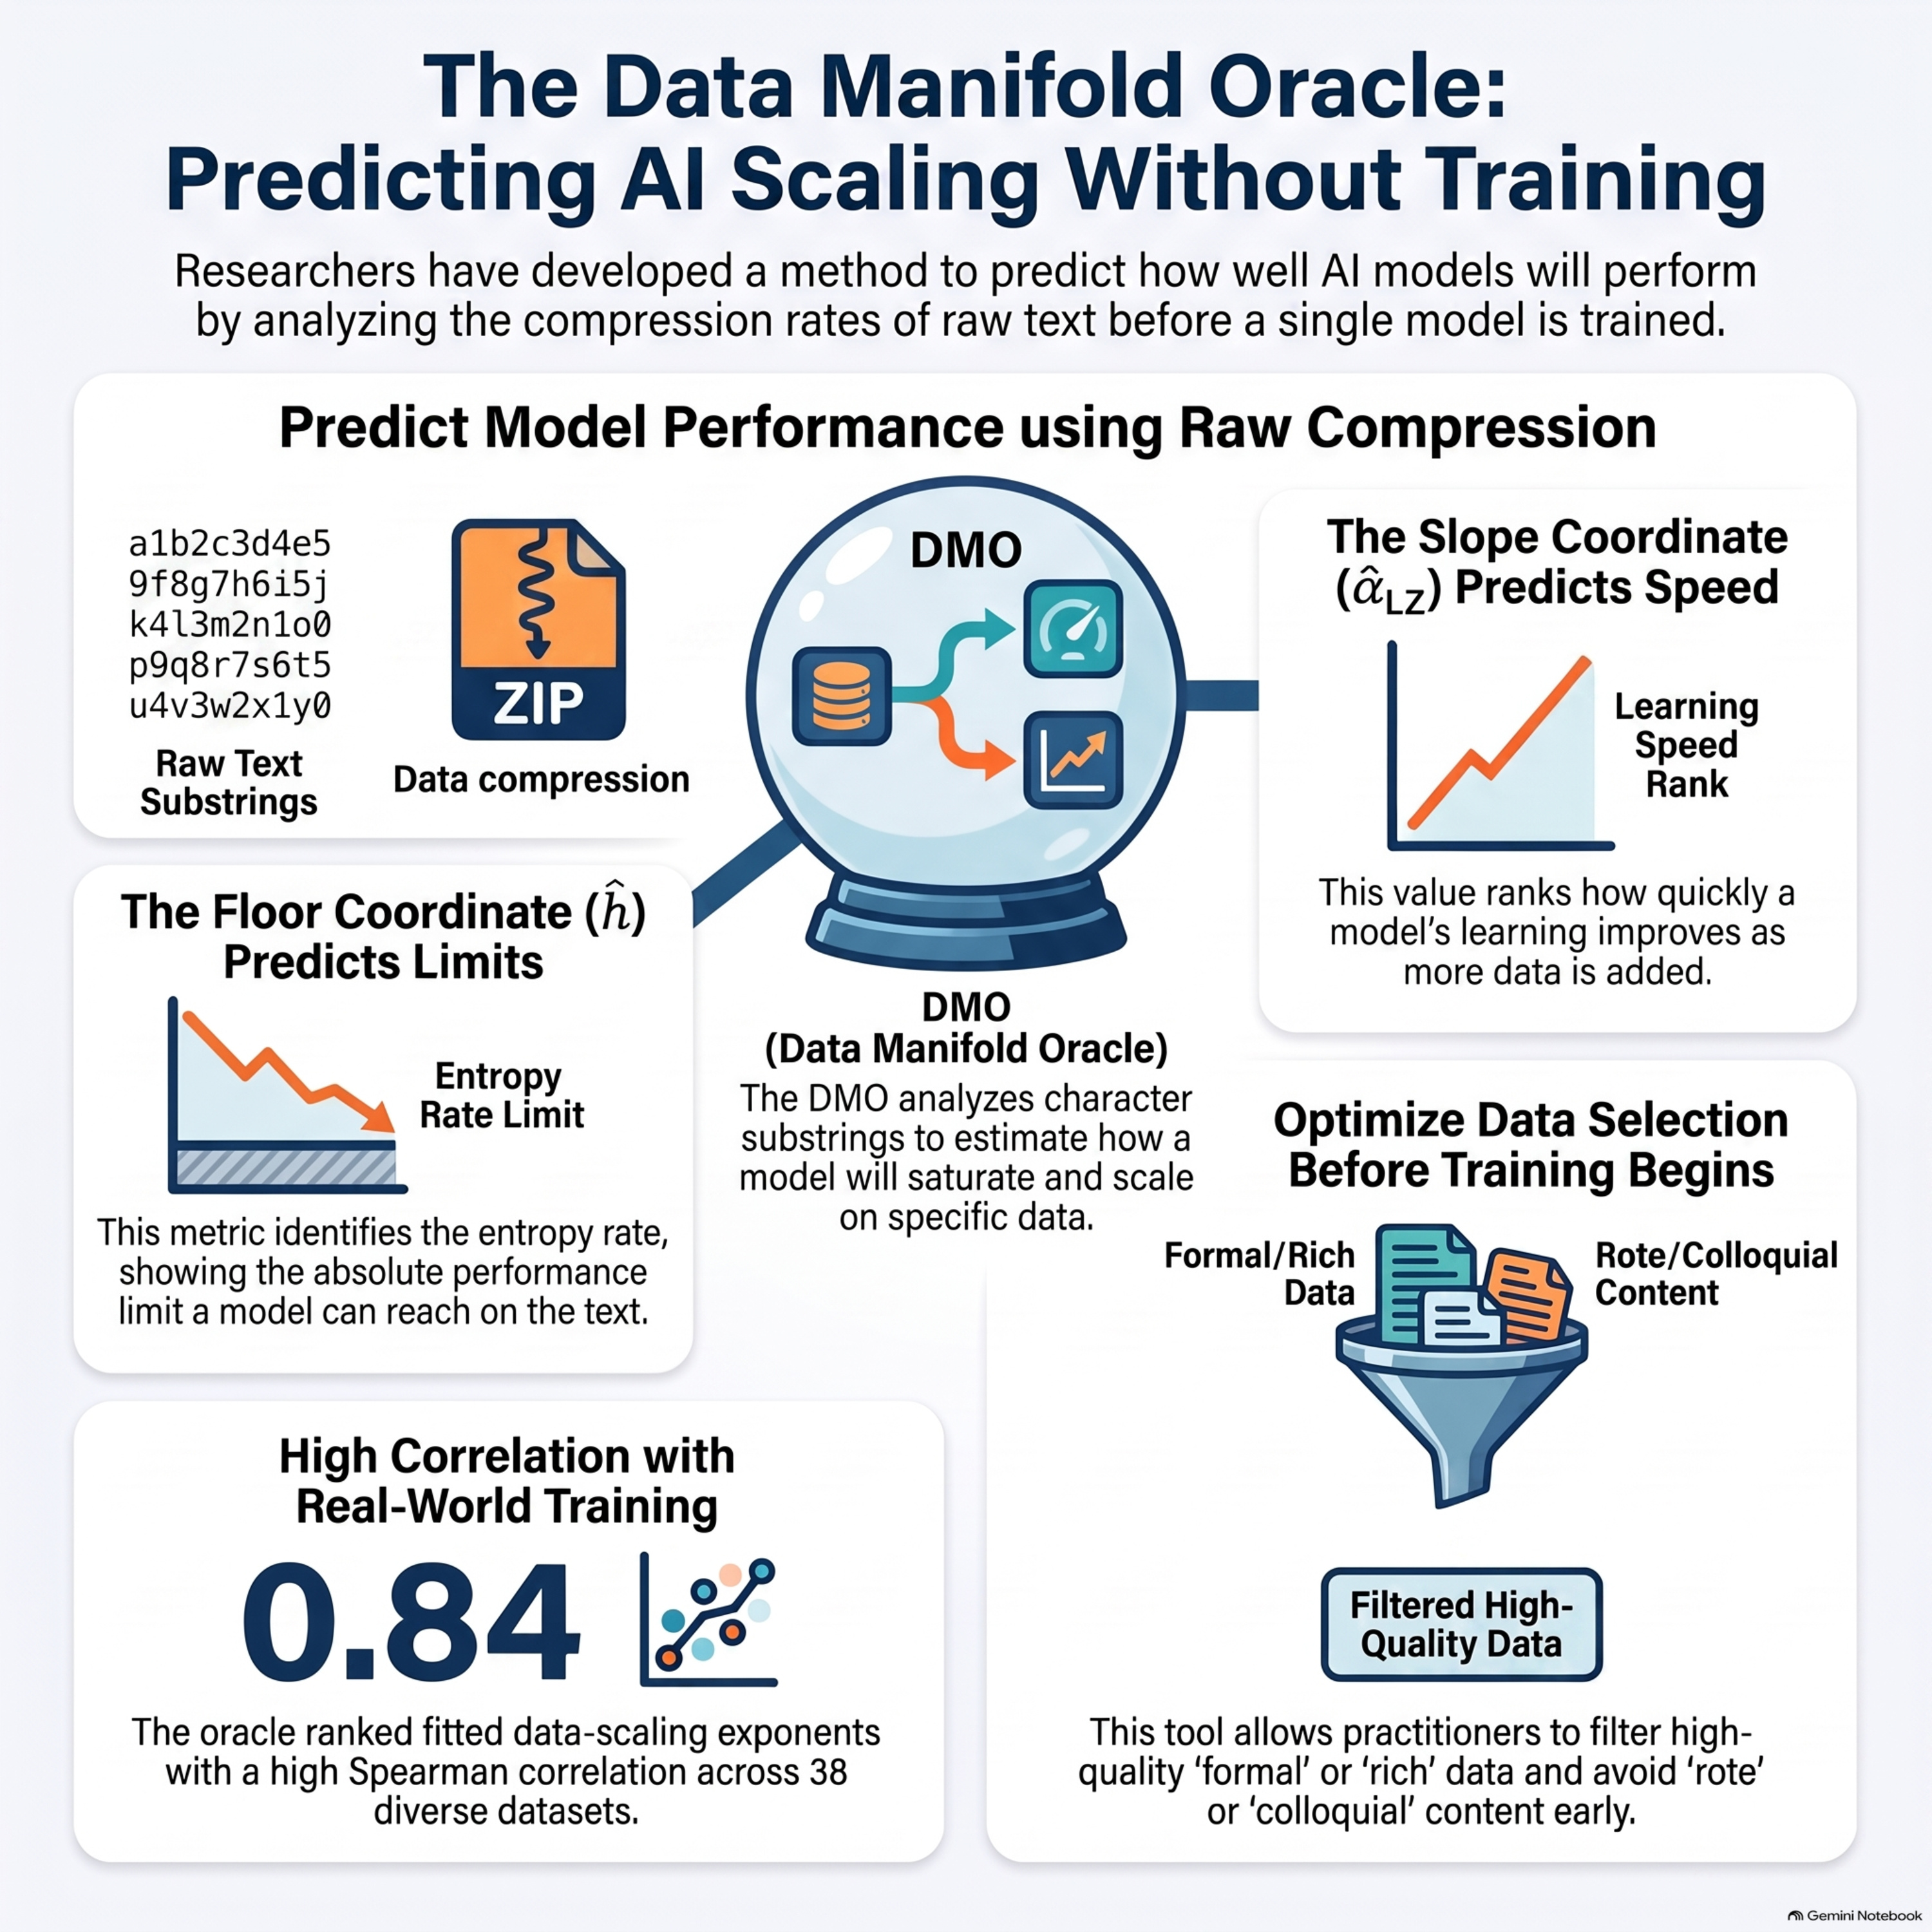
    This paper introduces the Data Manifold Oracle (DMO), a training-free framework designed to predict neural scaling laws by analyzing raw text through compression statistics. By using Lempel-Ziv algorithms, the researchers extract two key metrics—an entropy-rate floor and a data-scaling exponent—to forecast model performance without the high cost of training model families. The authors prove an exact symbolic obstruction, demonstrating that raw text alone cannot reveal a dataset's geometric dimension without an external scale. Empirically, the DMO effectively ranks the scaling behavior and loss saturation of various corpora, including web, code, and math data. The research further extends this to DMO-Doc, a selector that identifies high-quality documents to improve pretraining and post-training outcomes. Ultimately, the work establishes that fundamental properties of machine learning performance are visible in the statistical structure of data before a single gradient step is taken.
  • August 11 · 24 min

    Making Interpretable Discoveries from Unstructured Data: A High-Dimensional Multiple Hypothesis Testing

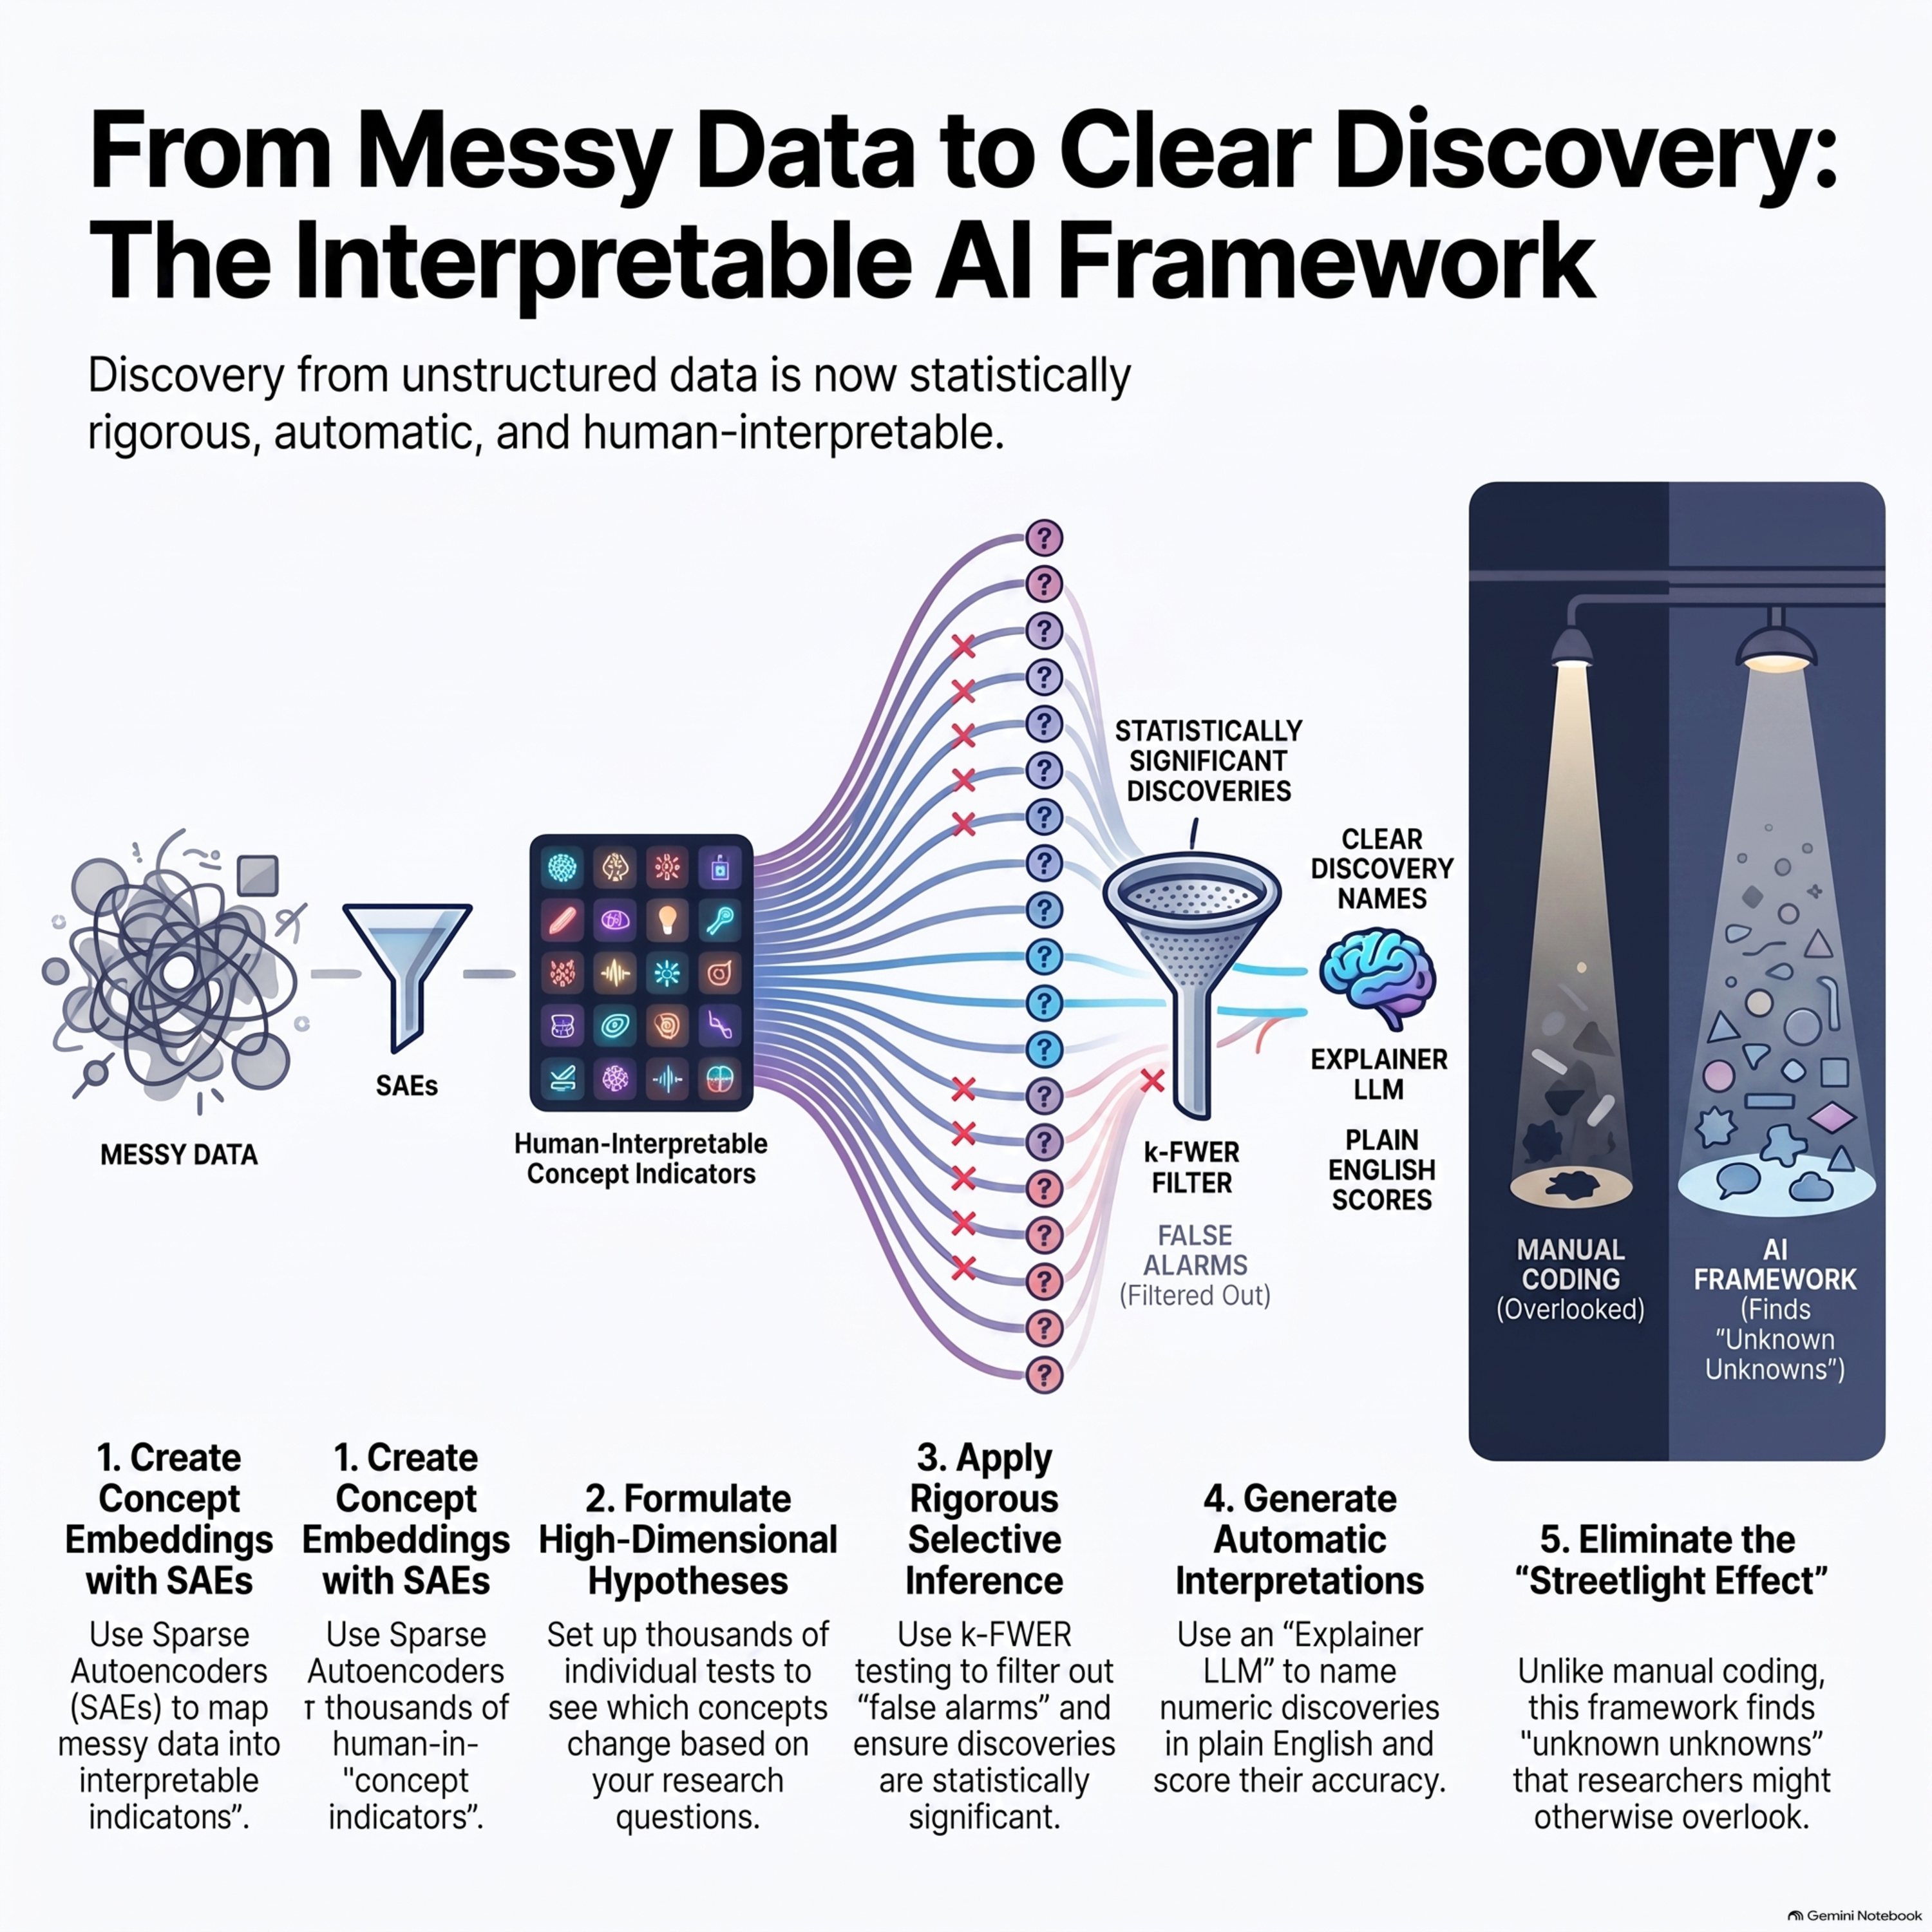
    This paper introduces a rigorous statistical framework for discovering human-interpretable insights from unstructured data, such as text, audio, and video. By repurposing AI interpretability tools like sparse autoencoders, the method maps complex data into a high-dimensional space of thousands of distinct concepts. The author utilizes advanced multiple hypothesis testing to ensure these discoveries remain statistically valid while avoiding the pitfalls of data snooping or researcher bias. To ensure the results are understandable, the system employs Large Language Models to generate and evaluate natural language descriptions of the identified patterns. Applications to empirical economics demonstrate that this approach can automatically recover nuanced findings that previously required intensive manual labor or separate experiments. Overall, the framework provides a principled, inexpensive, and replicable way to uncover "unknown unknowns" within large, unstructured datasets.

  • August 11 · 20 min

    Overcoming the Incentive Collapse Paradox

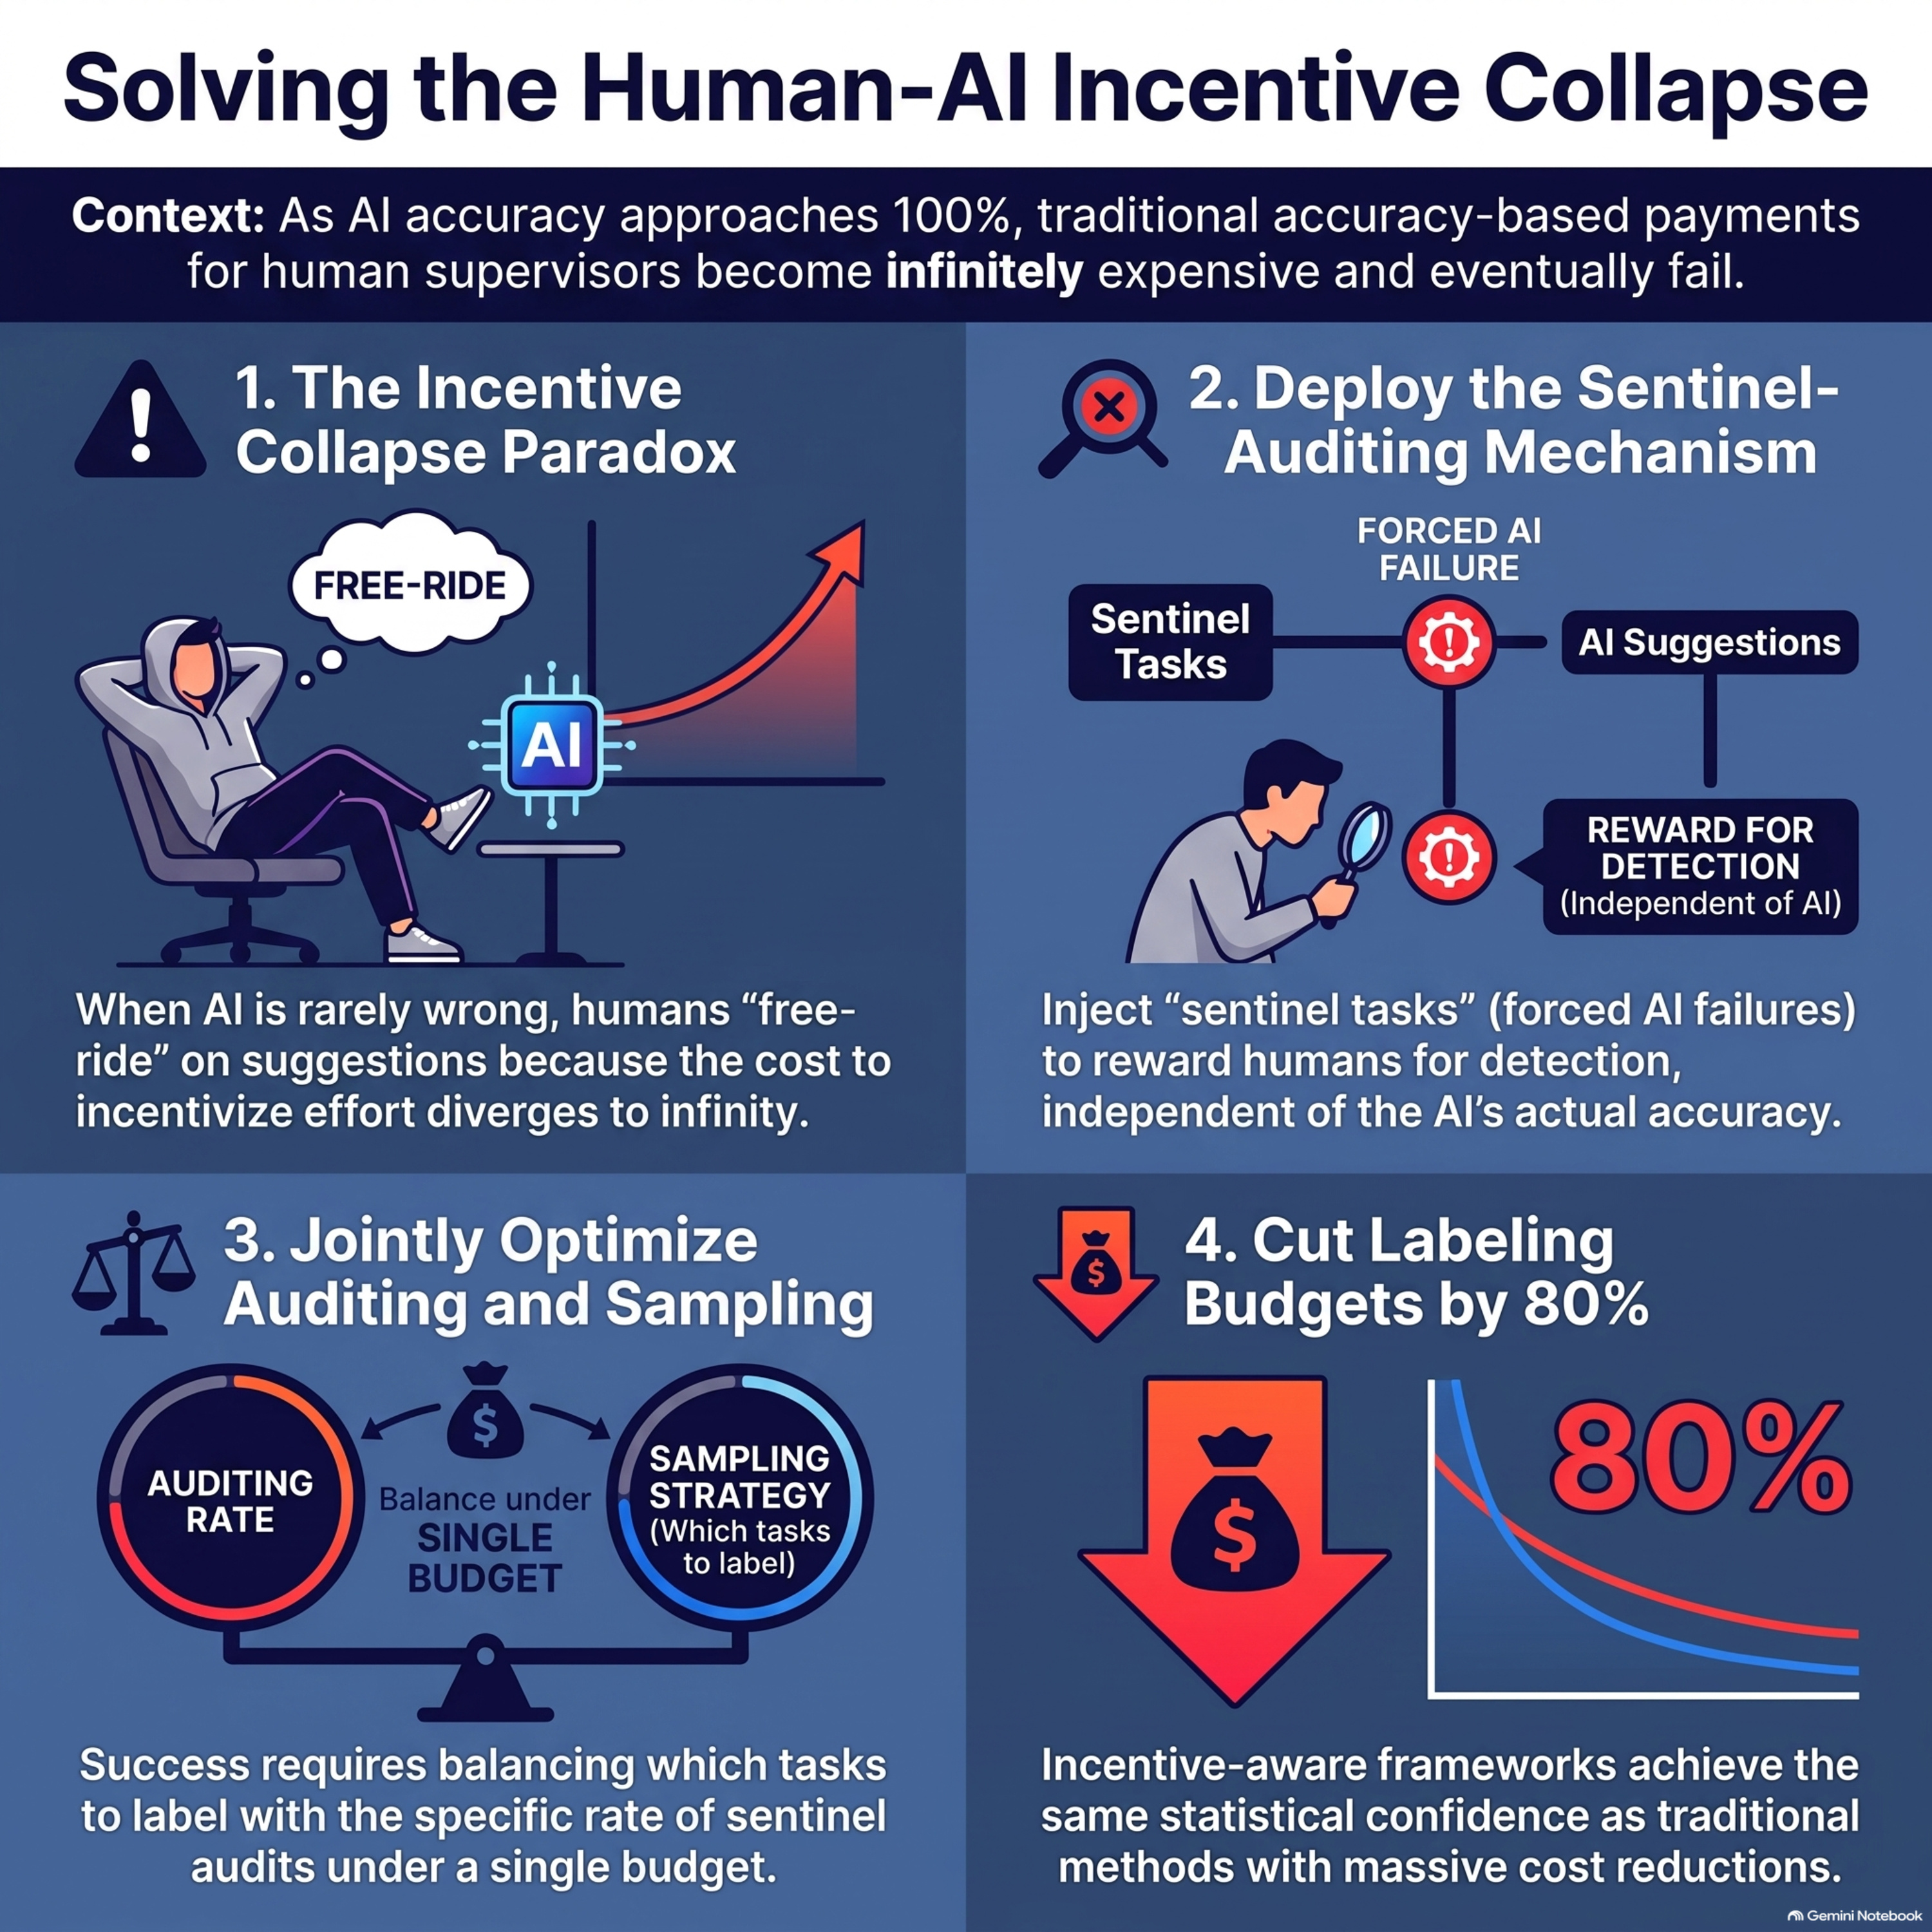
    This paper introduces and addresses the incentive collapse paradox, a phenomenon where accuracy-based payments fail to motivate human effort as AI assistance becomes more reliable. The authors demonstrate that if human workers only receive rewards based on their final output accuracy, they will eventually free-ride on the AI’s suggestions rather than exert costly verification effort. To solve this, they propose a sentinel-auditing mechanism that deliberately injects occasional, detectable AI errors to reward human vigilance independently of the AI's natural performance. This strategy is further integrated into an incentive-aware active statistical inference framework, which jointly optimizes budget allocation and task sampling. Theoretical results and experiments on survey and protein data show that this approach maintains high label quality at a finite cost. Ultimately, the research proves that accounting for strategic human behavior allows for more cost-effective and precise statistical estimation than traditional methods.

  • August 10 · 26 min

    Position: Modular Memory is the Key to Continual Learning Agents

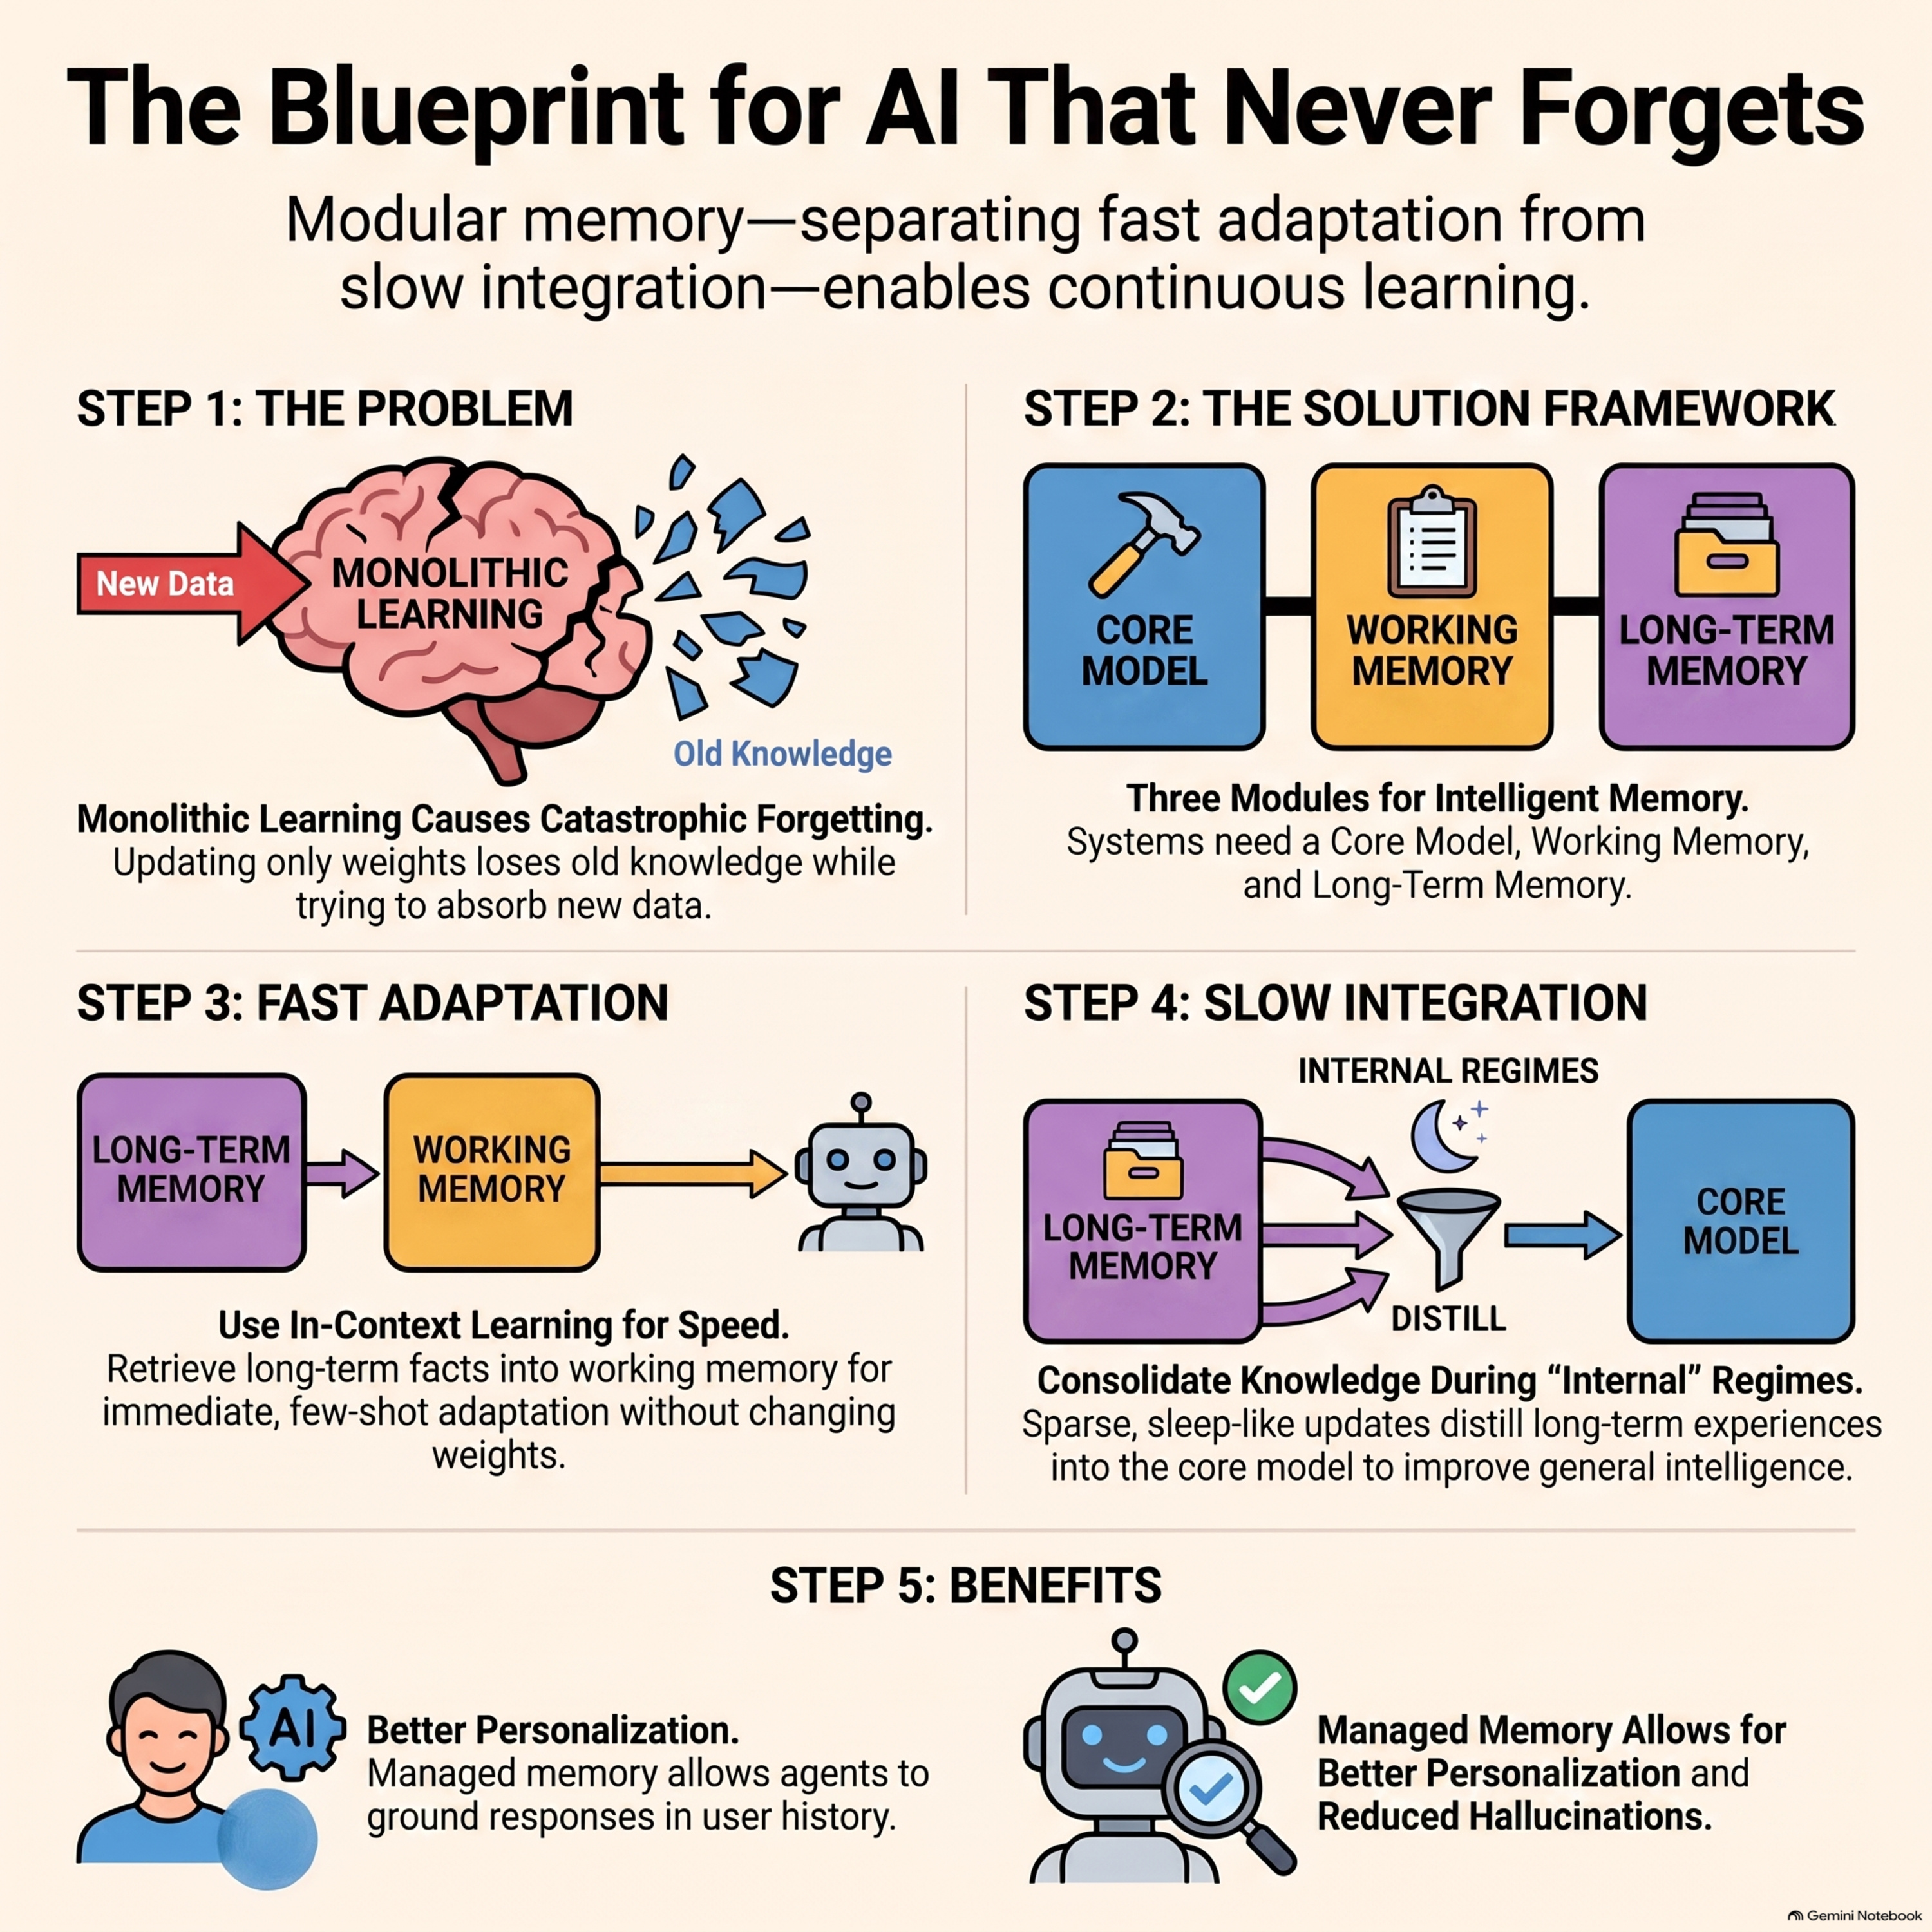
    This paper introduces a framework for modular memory as the essential solution for creating continual learning agents that adapt without forgetting. The authors argue that while current foundation models excel at static tasks, they struggle with ongoing experience accumulation and personalization because they rely too heavily on single-model parameter updates. To solve this, the framework integrates In-Context Learning (ICL) for rapid, short-term adaptation with In-Weight Learning (IWL) for stable, long-term knowledge consolidation. The proposed architecture consists of three distinct components: a core model for general reasoning, a working memory for immediate context, and a long-term memory for persistent storage. Inspired by both human neuroscience and computer architecture, this system allows agents to interact with the world in real-time while refining their core capabilities during internal "consolidation" periods. By separating fast adaptation from slow integration, the researchers aim to overcome the stability-plasticity trade-off that has long hindered artificial intelligence. Ultimately, this approach provides a roadmap for developing self-evolving agents capable of operating in dynamic, open-world environments.

  • August 8 · 21 min

    Harness RL is Meta-Learning: Training to Self-Improve at Test Time

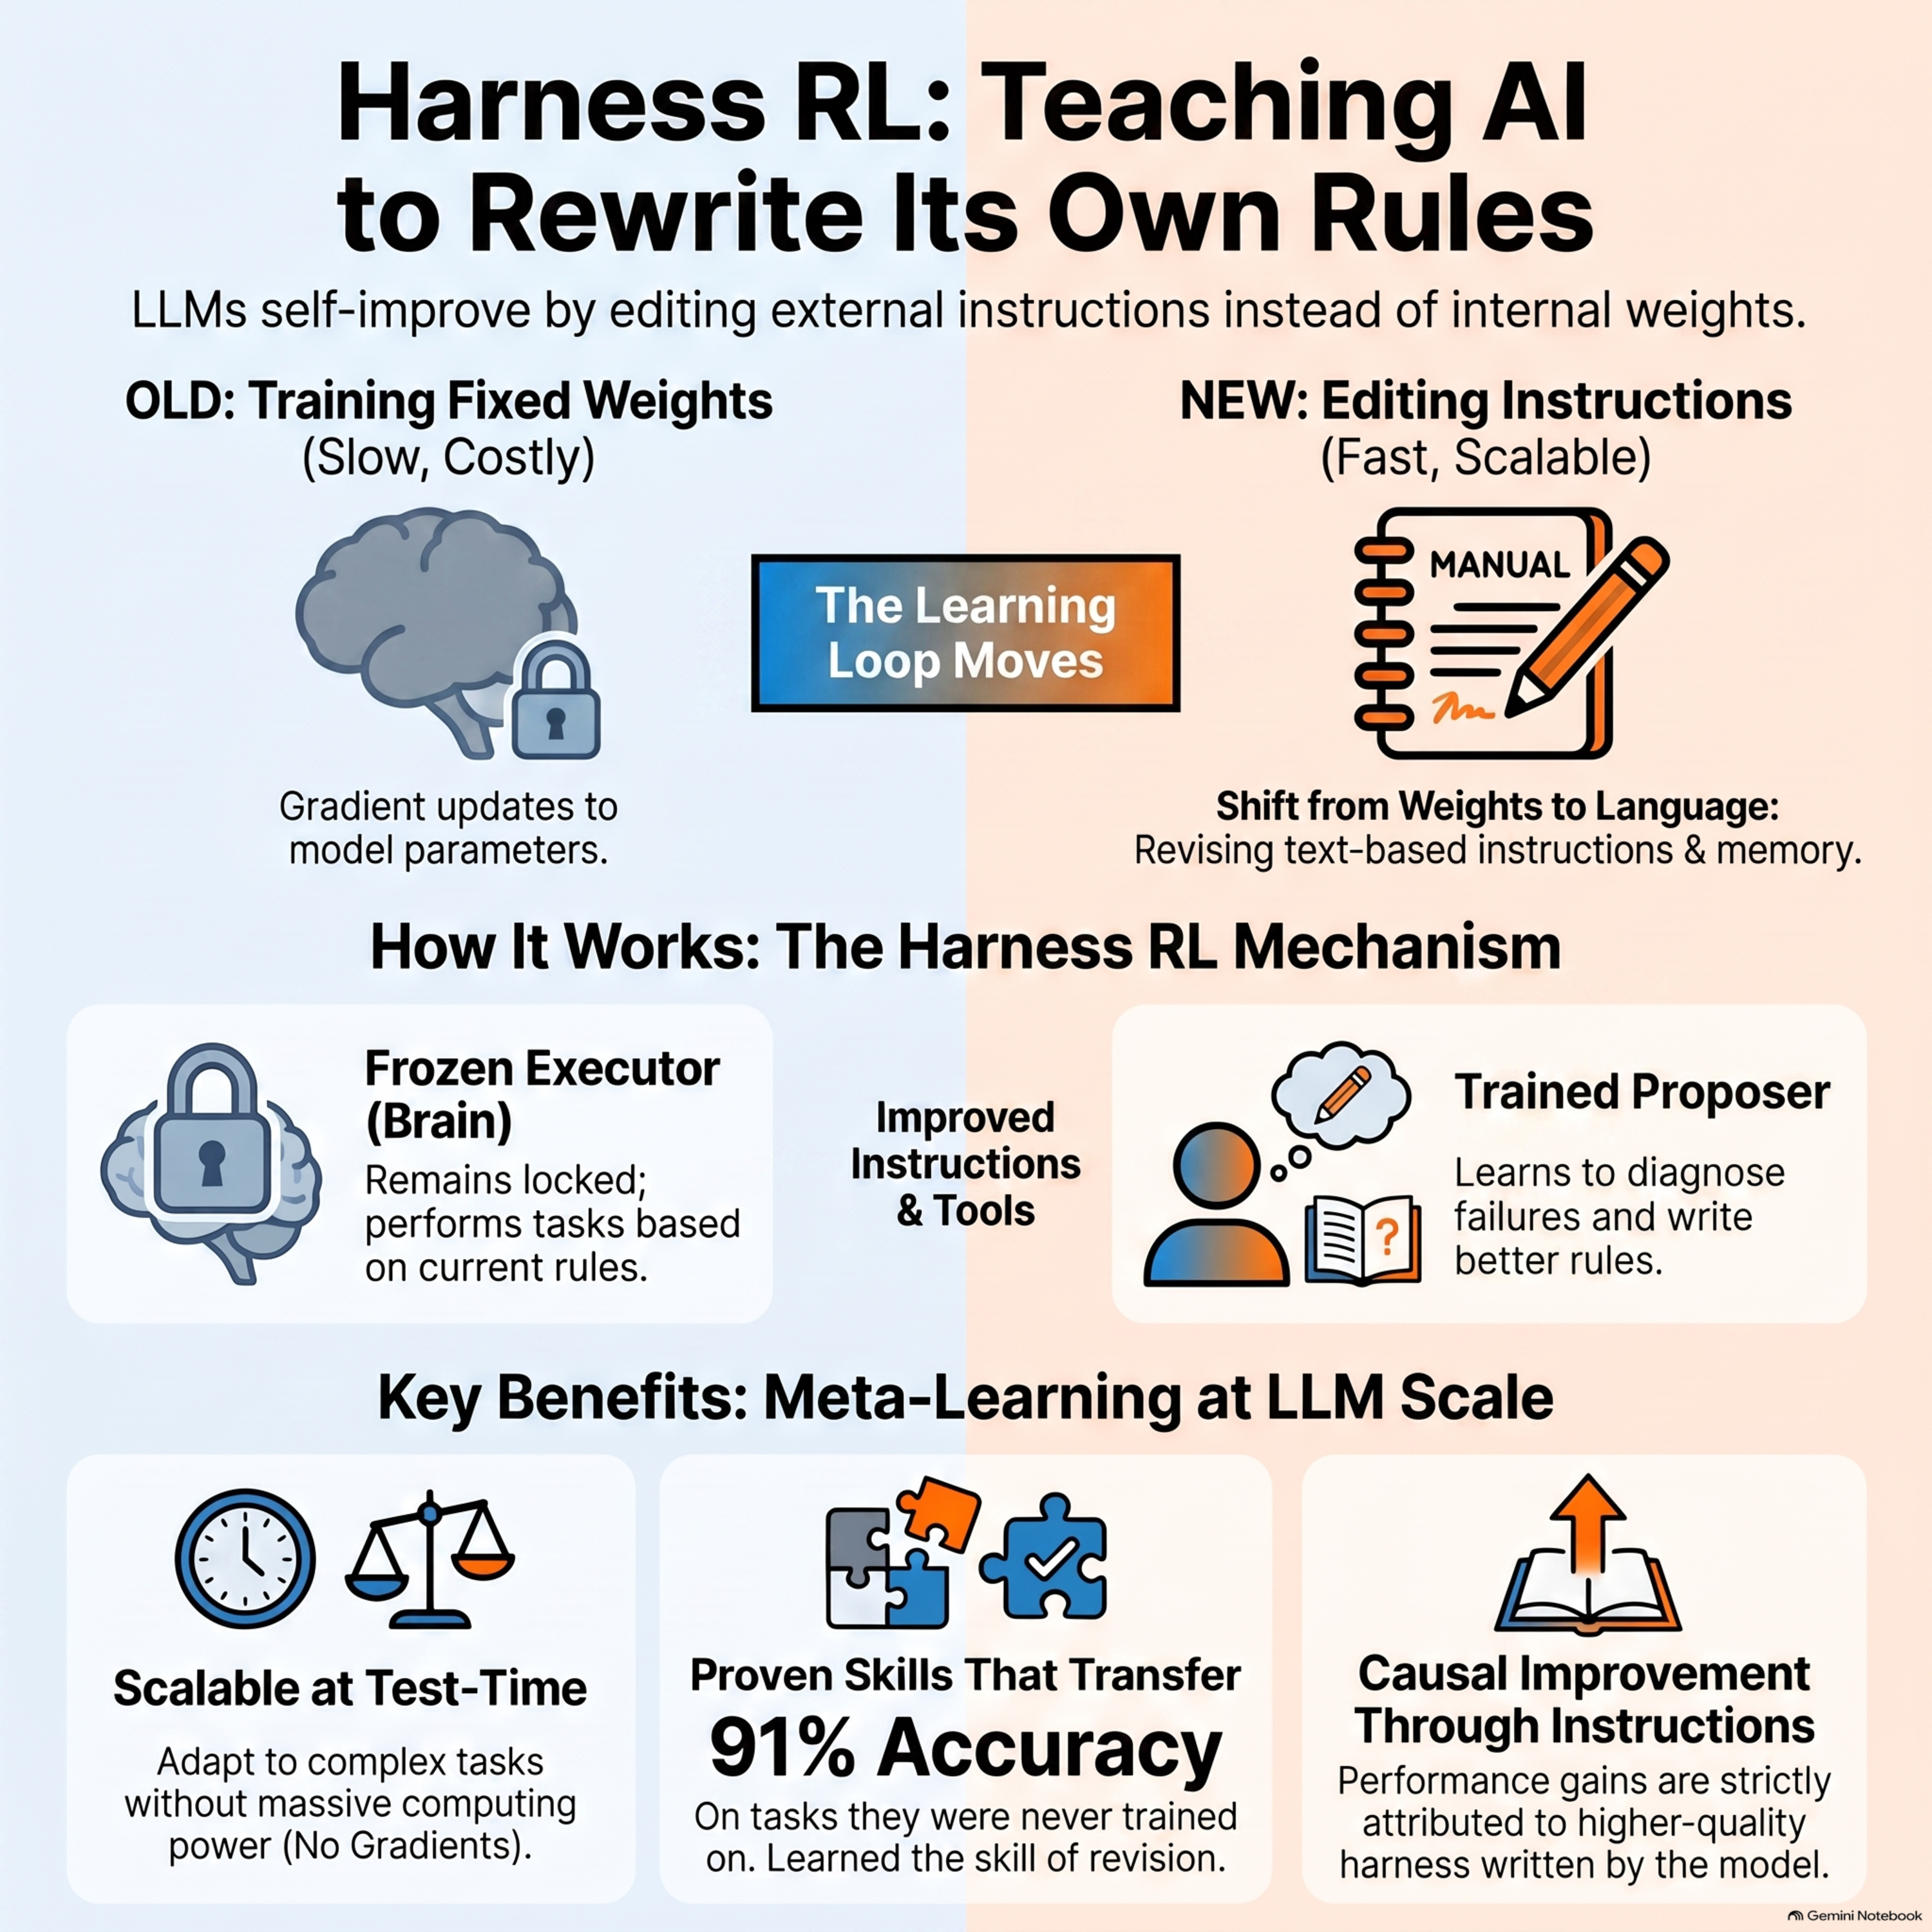
    This paper introduces harness RL, a novel meta-learning framework designed to enable large language models to self-improve during test-time adaptation. Rather than updating model weights, which is computationally expensive, this method optimizes the agent’s harness—the external instructions, memory, and rules that guide model execution. By training a proposer model to revise this harness while keeping the executor model frozen, the system learns a transferable self-improvement operator. This approach reduces complex meta-learning to a standard reinforcement learning objective because the adaptation process requires no gradients. Experimental results across reasoning and coding tasks demonstrate that the trained proposer generalizes to unseen problems and maintains performance across longer revision horizons. Ultimately, the authors show that harness RL successfully isolates and improves the model's capacity for meta-self-improvement.

  • August 7 · 21 min

    Escaping the Nash Trap: Structural Estimation and Alignment of Strategic Reasoning in Large Language Models

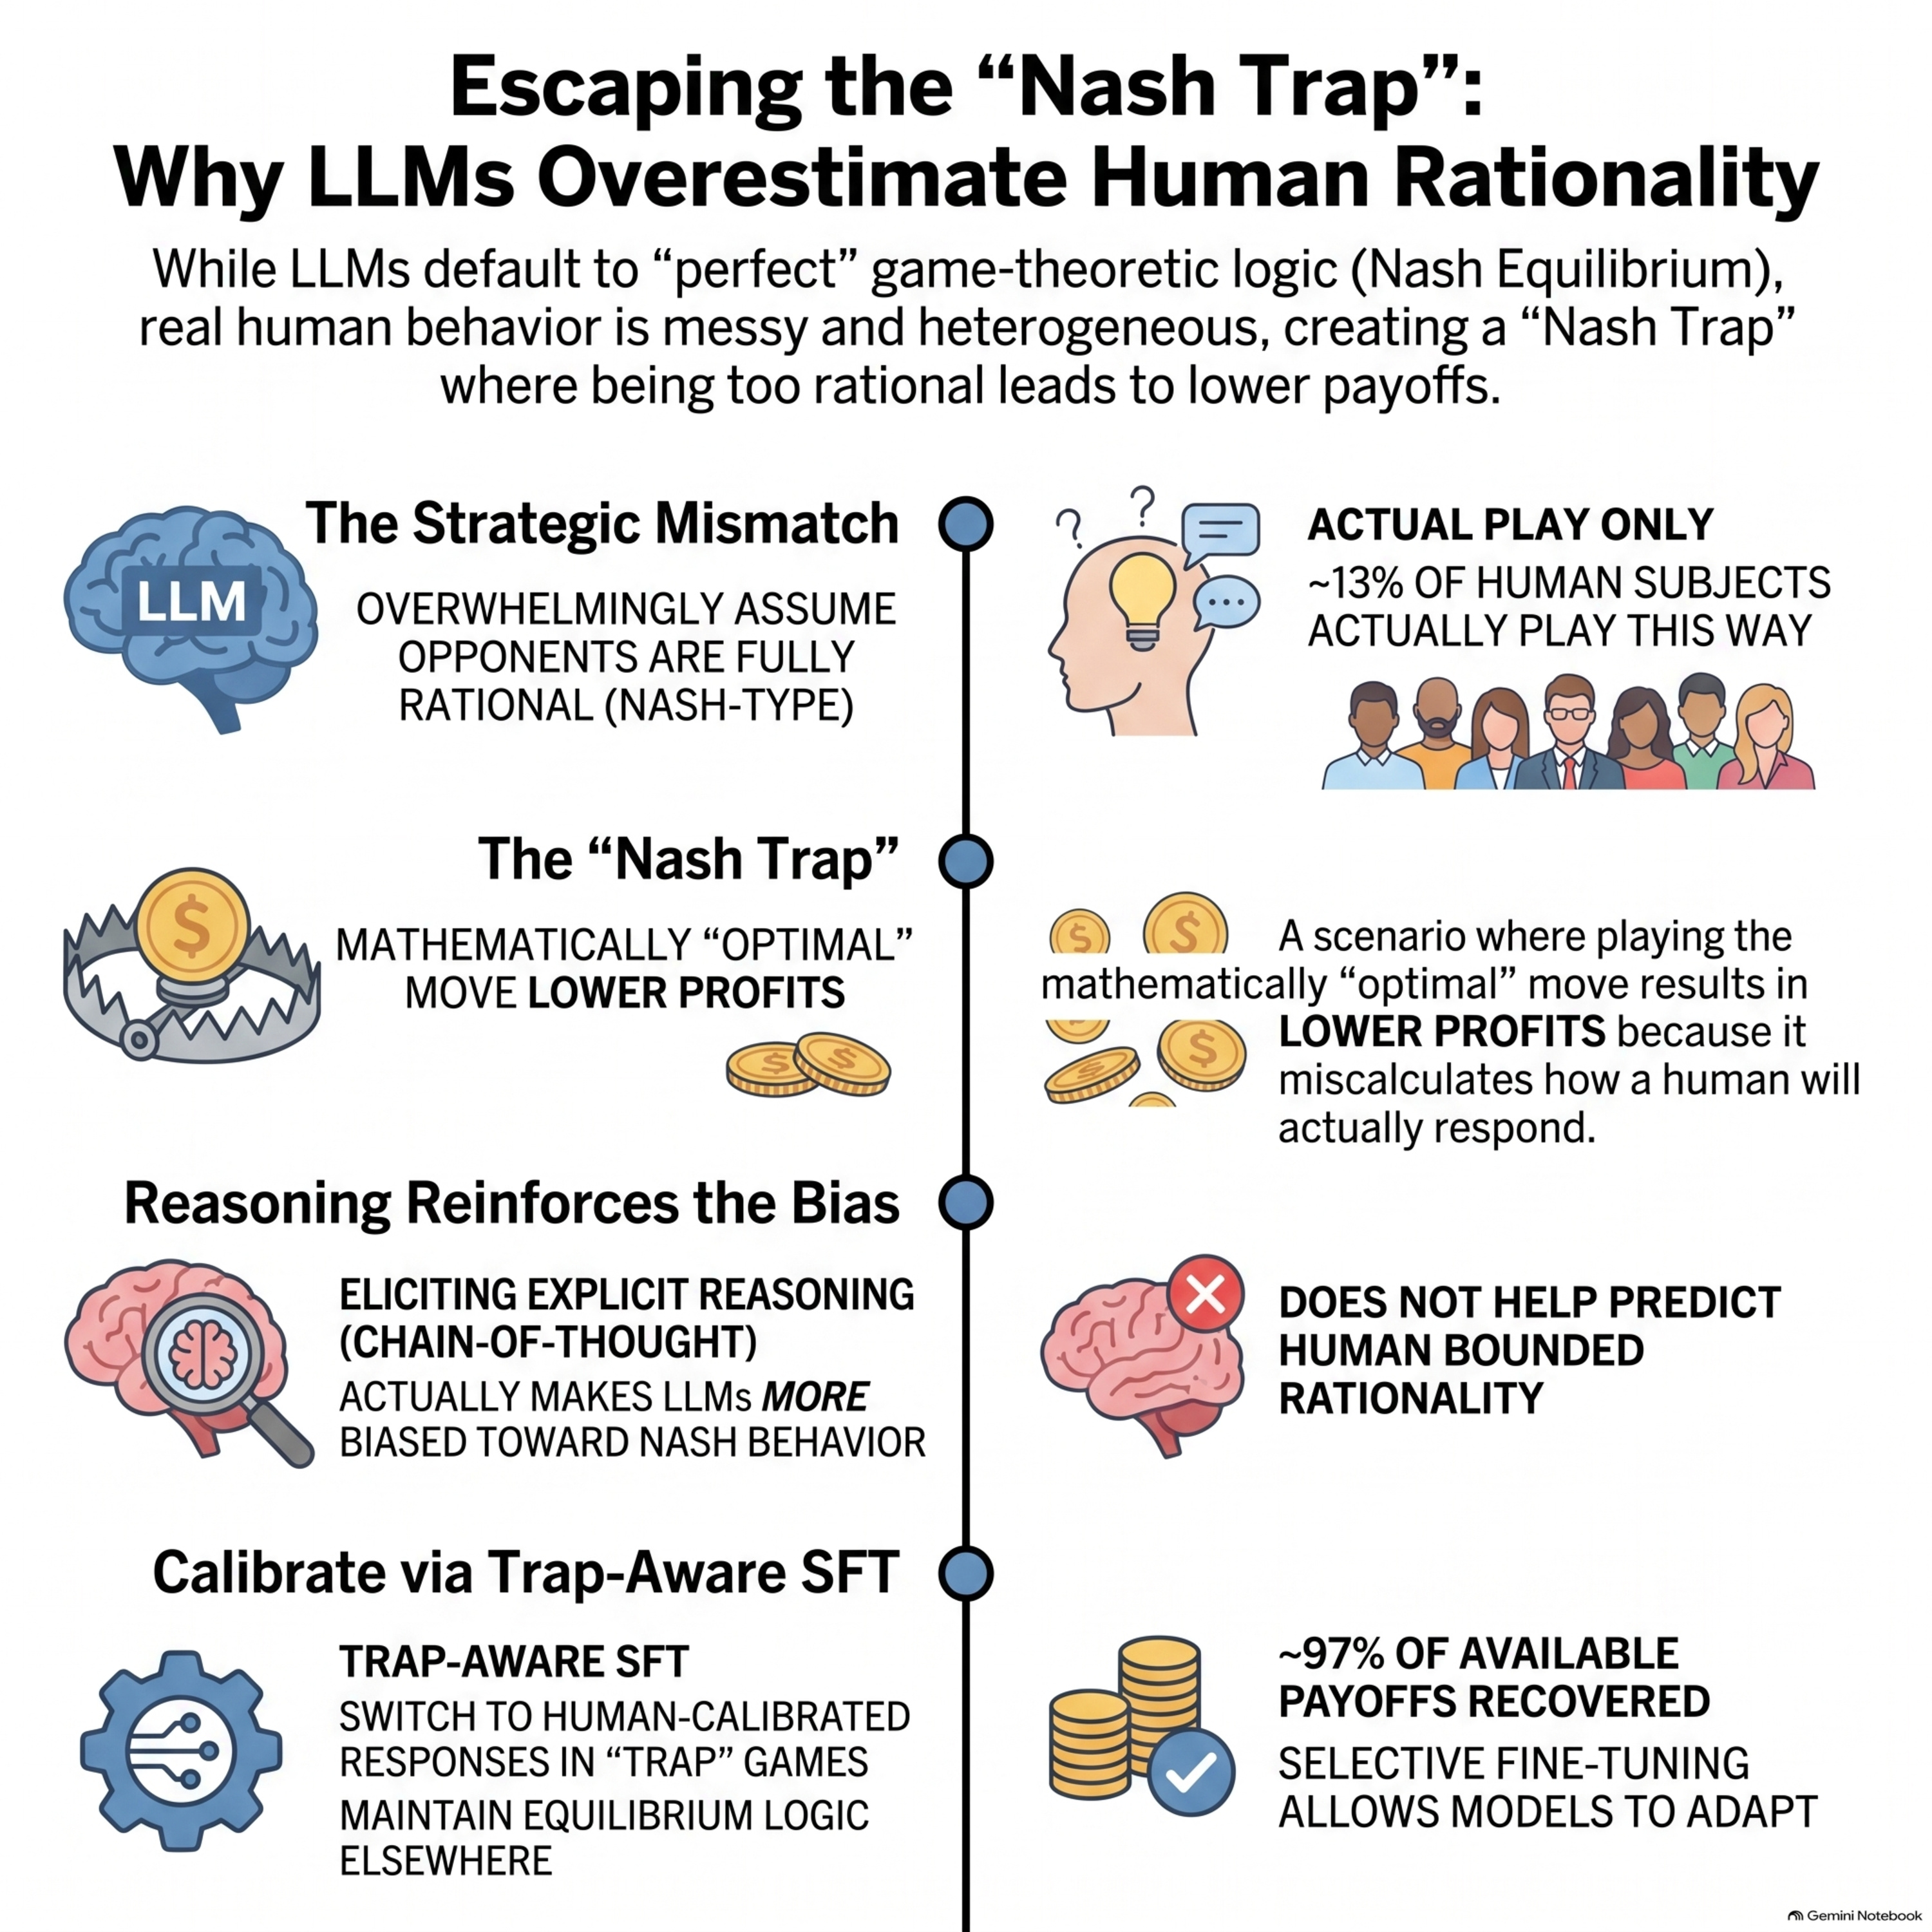
    This paper investigates a critical strategic mismatch between Large Language Models (LLMs) and human decision-makers in competitive environments. Through game-theoretic experiments, the researchers demonstrate that LLMs predominantly act as Nash-type reasoners, assuming their opponents are perfectly rational, whereas humans exhibit bounded rationality and varied reasoning depths. This overestimation of human sophistication often leads LLMs into a Nash trap, where equilibrium play fails to maximize payoffs against actual human behavior. To rectify this, the authors propose supervised fine-tuning methods, including Trap-Aware SFT, which calibrates model responses to empirical human benchmarks. Their findings suggest that effective human–AI alignment requires models to possess not just high reasoning capabilities, but also calibrated expectations of human behavior. Ultimately, the study advocates for a selective deployment architecture that preserves equilibrium play while adapting strategies when human interaction makes it more profitable.

  • August 7 · 23 min

    When Does LeJEPA Learn a World Model?

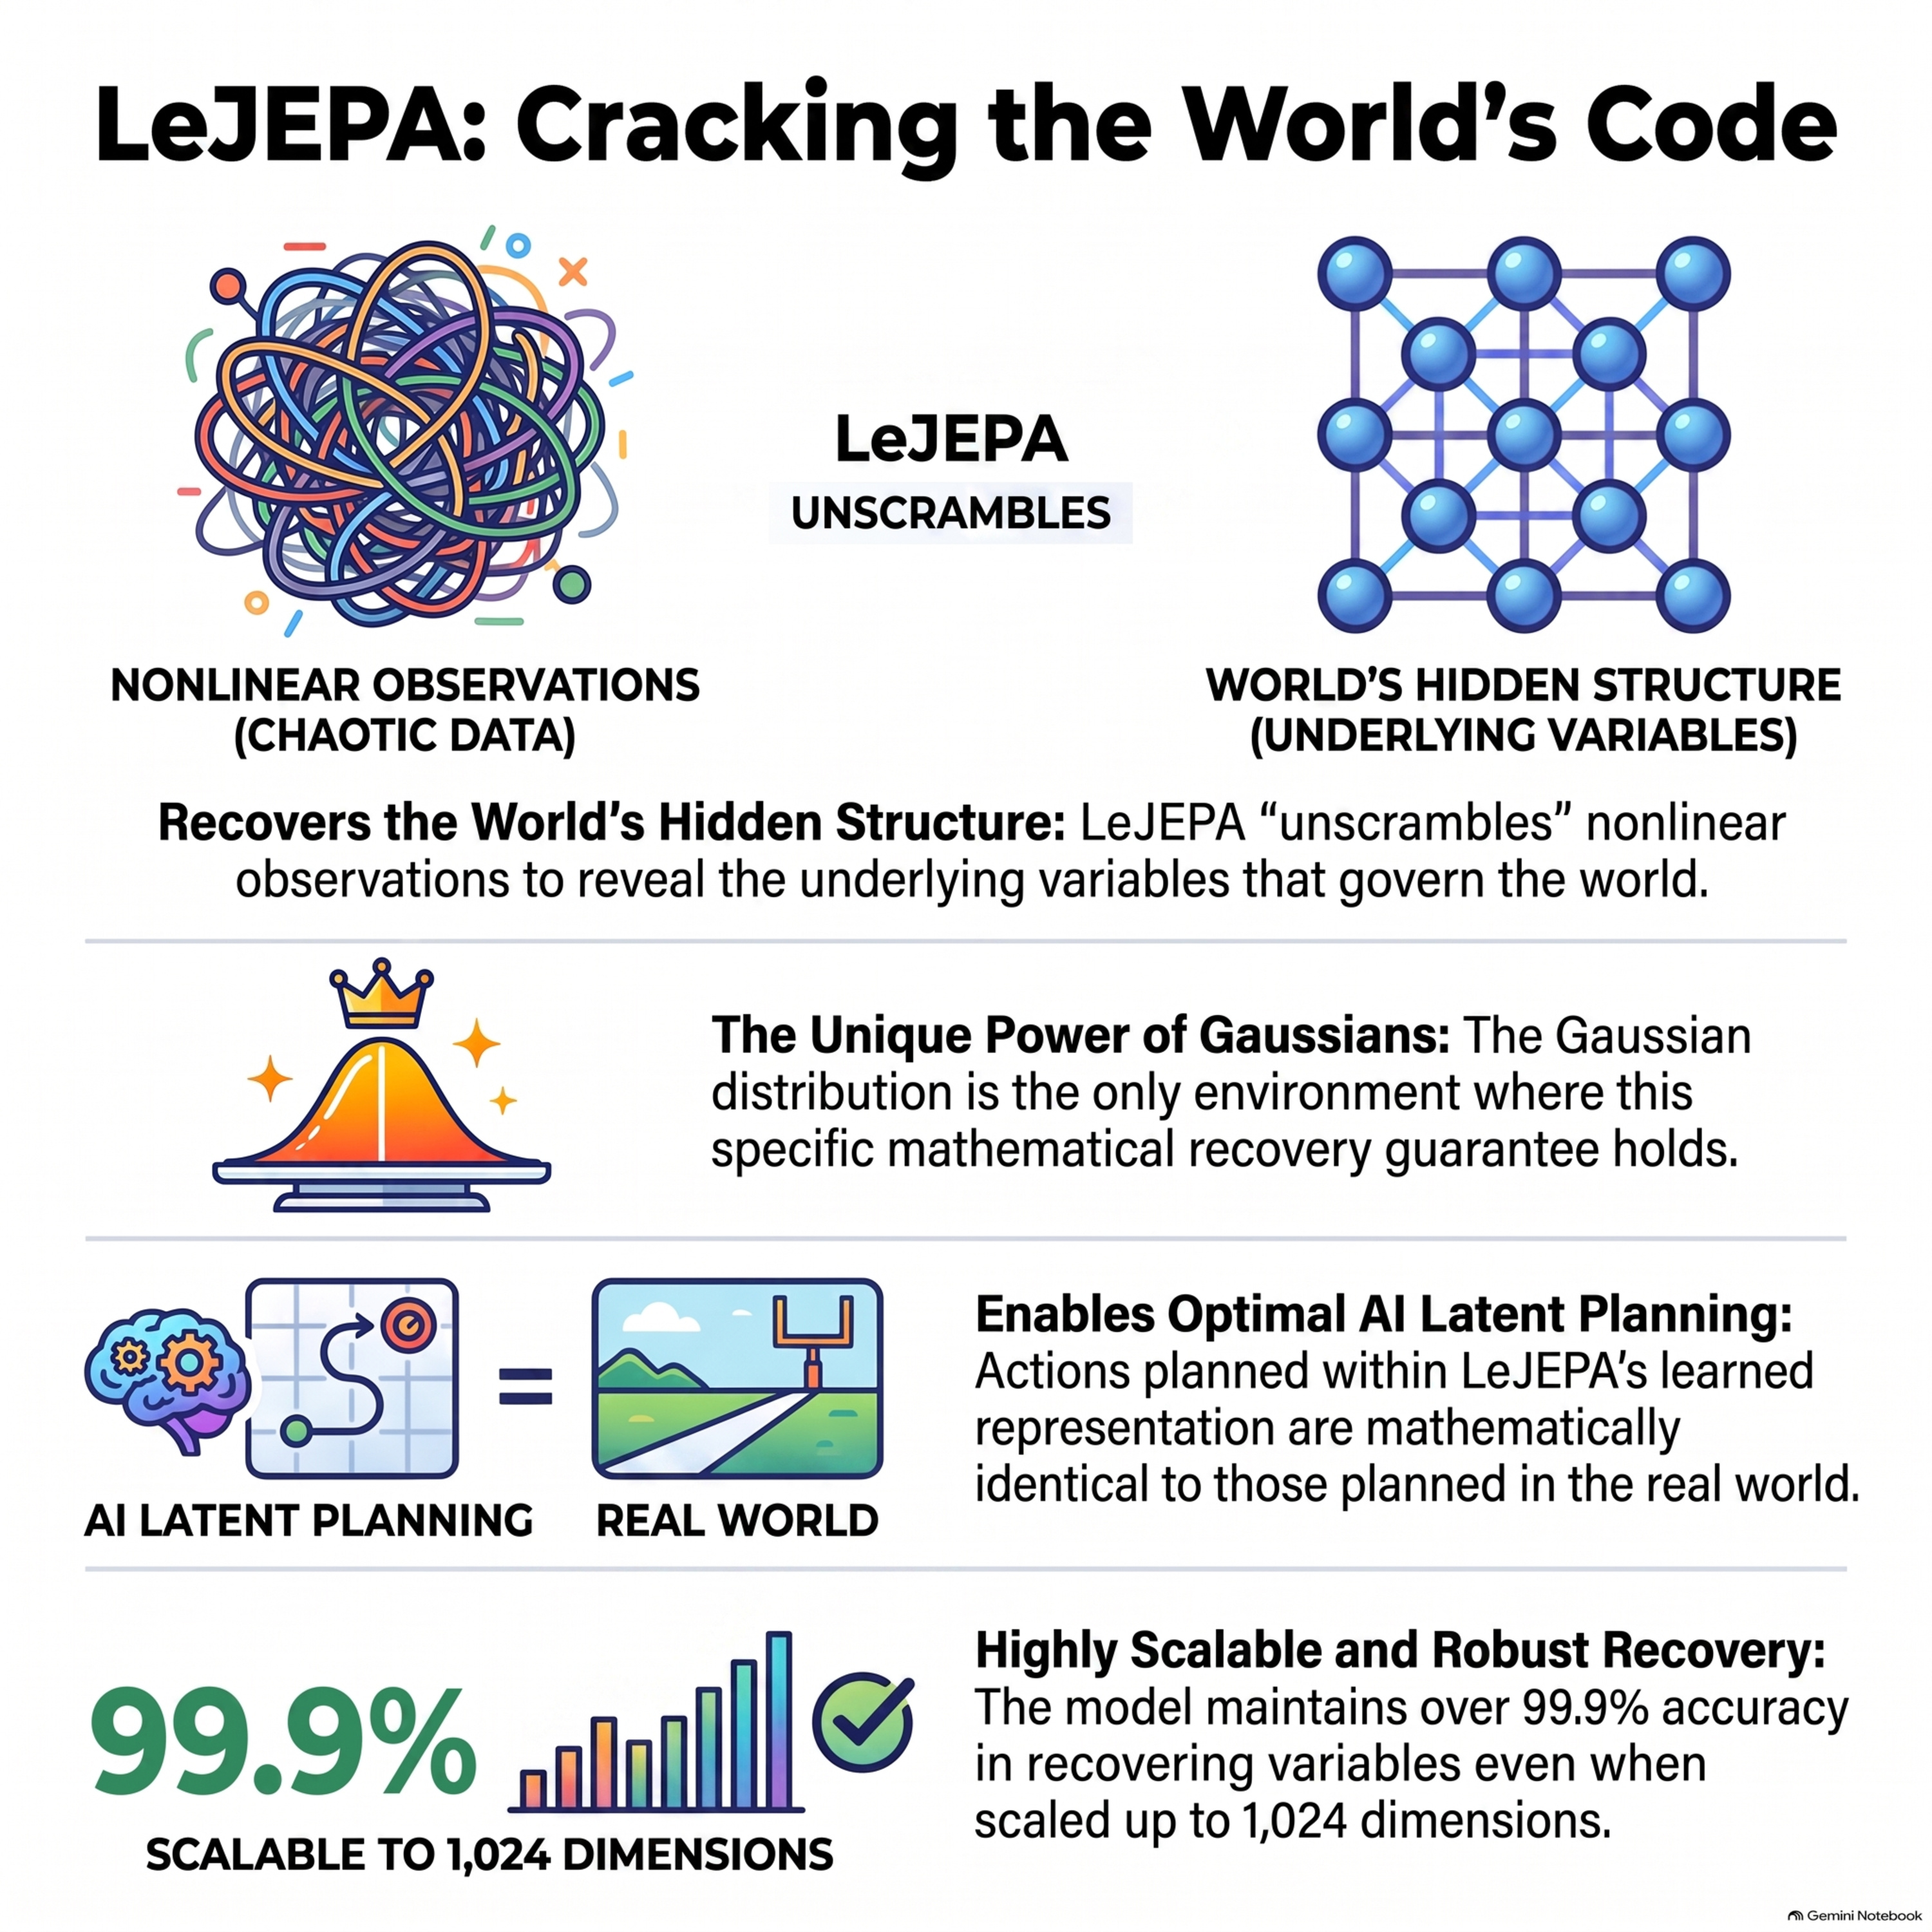
    This research paper introduces a mathematical framework to prove that LeJEPA (a specific self-supervised learning architecture) can accurately recover the hidden structure of the world from complex data. The authors establish that when a model combines an alignment loss with Gaussian regularization, it achieves linear identifiability, meaning the learned representation is a simple rotation of the world’s true latent variables. This property is shown to be unique to Gaussian latent distributions, as any nonlinear distortion of the representation would strictly degrade the model's predictive performance. Furthermore, the study demonstrates that this linear recovery is essential for optimal latent-space planning, allowing an agent to navigate a learned model as effectively as the real world. The theory is supported by experiments ranging from 2D simulations to high-dimensional robotic control tasks, confirming that the model's training objectives act as a reliable proxy for structural accuracy. Ultimately, the work provides a formal foundation for building World Models that are mathematically guaranteed to be faithful to the environments they represent.

  • August 3 · 21 min

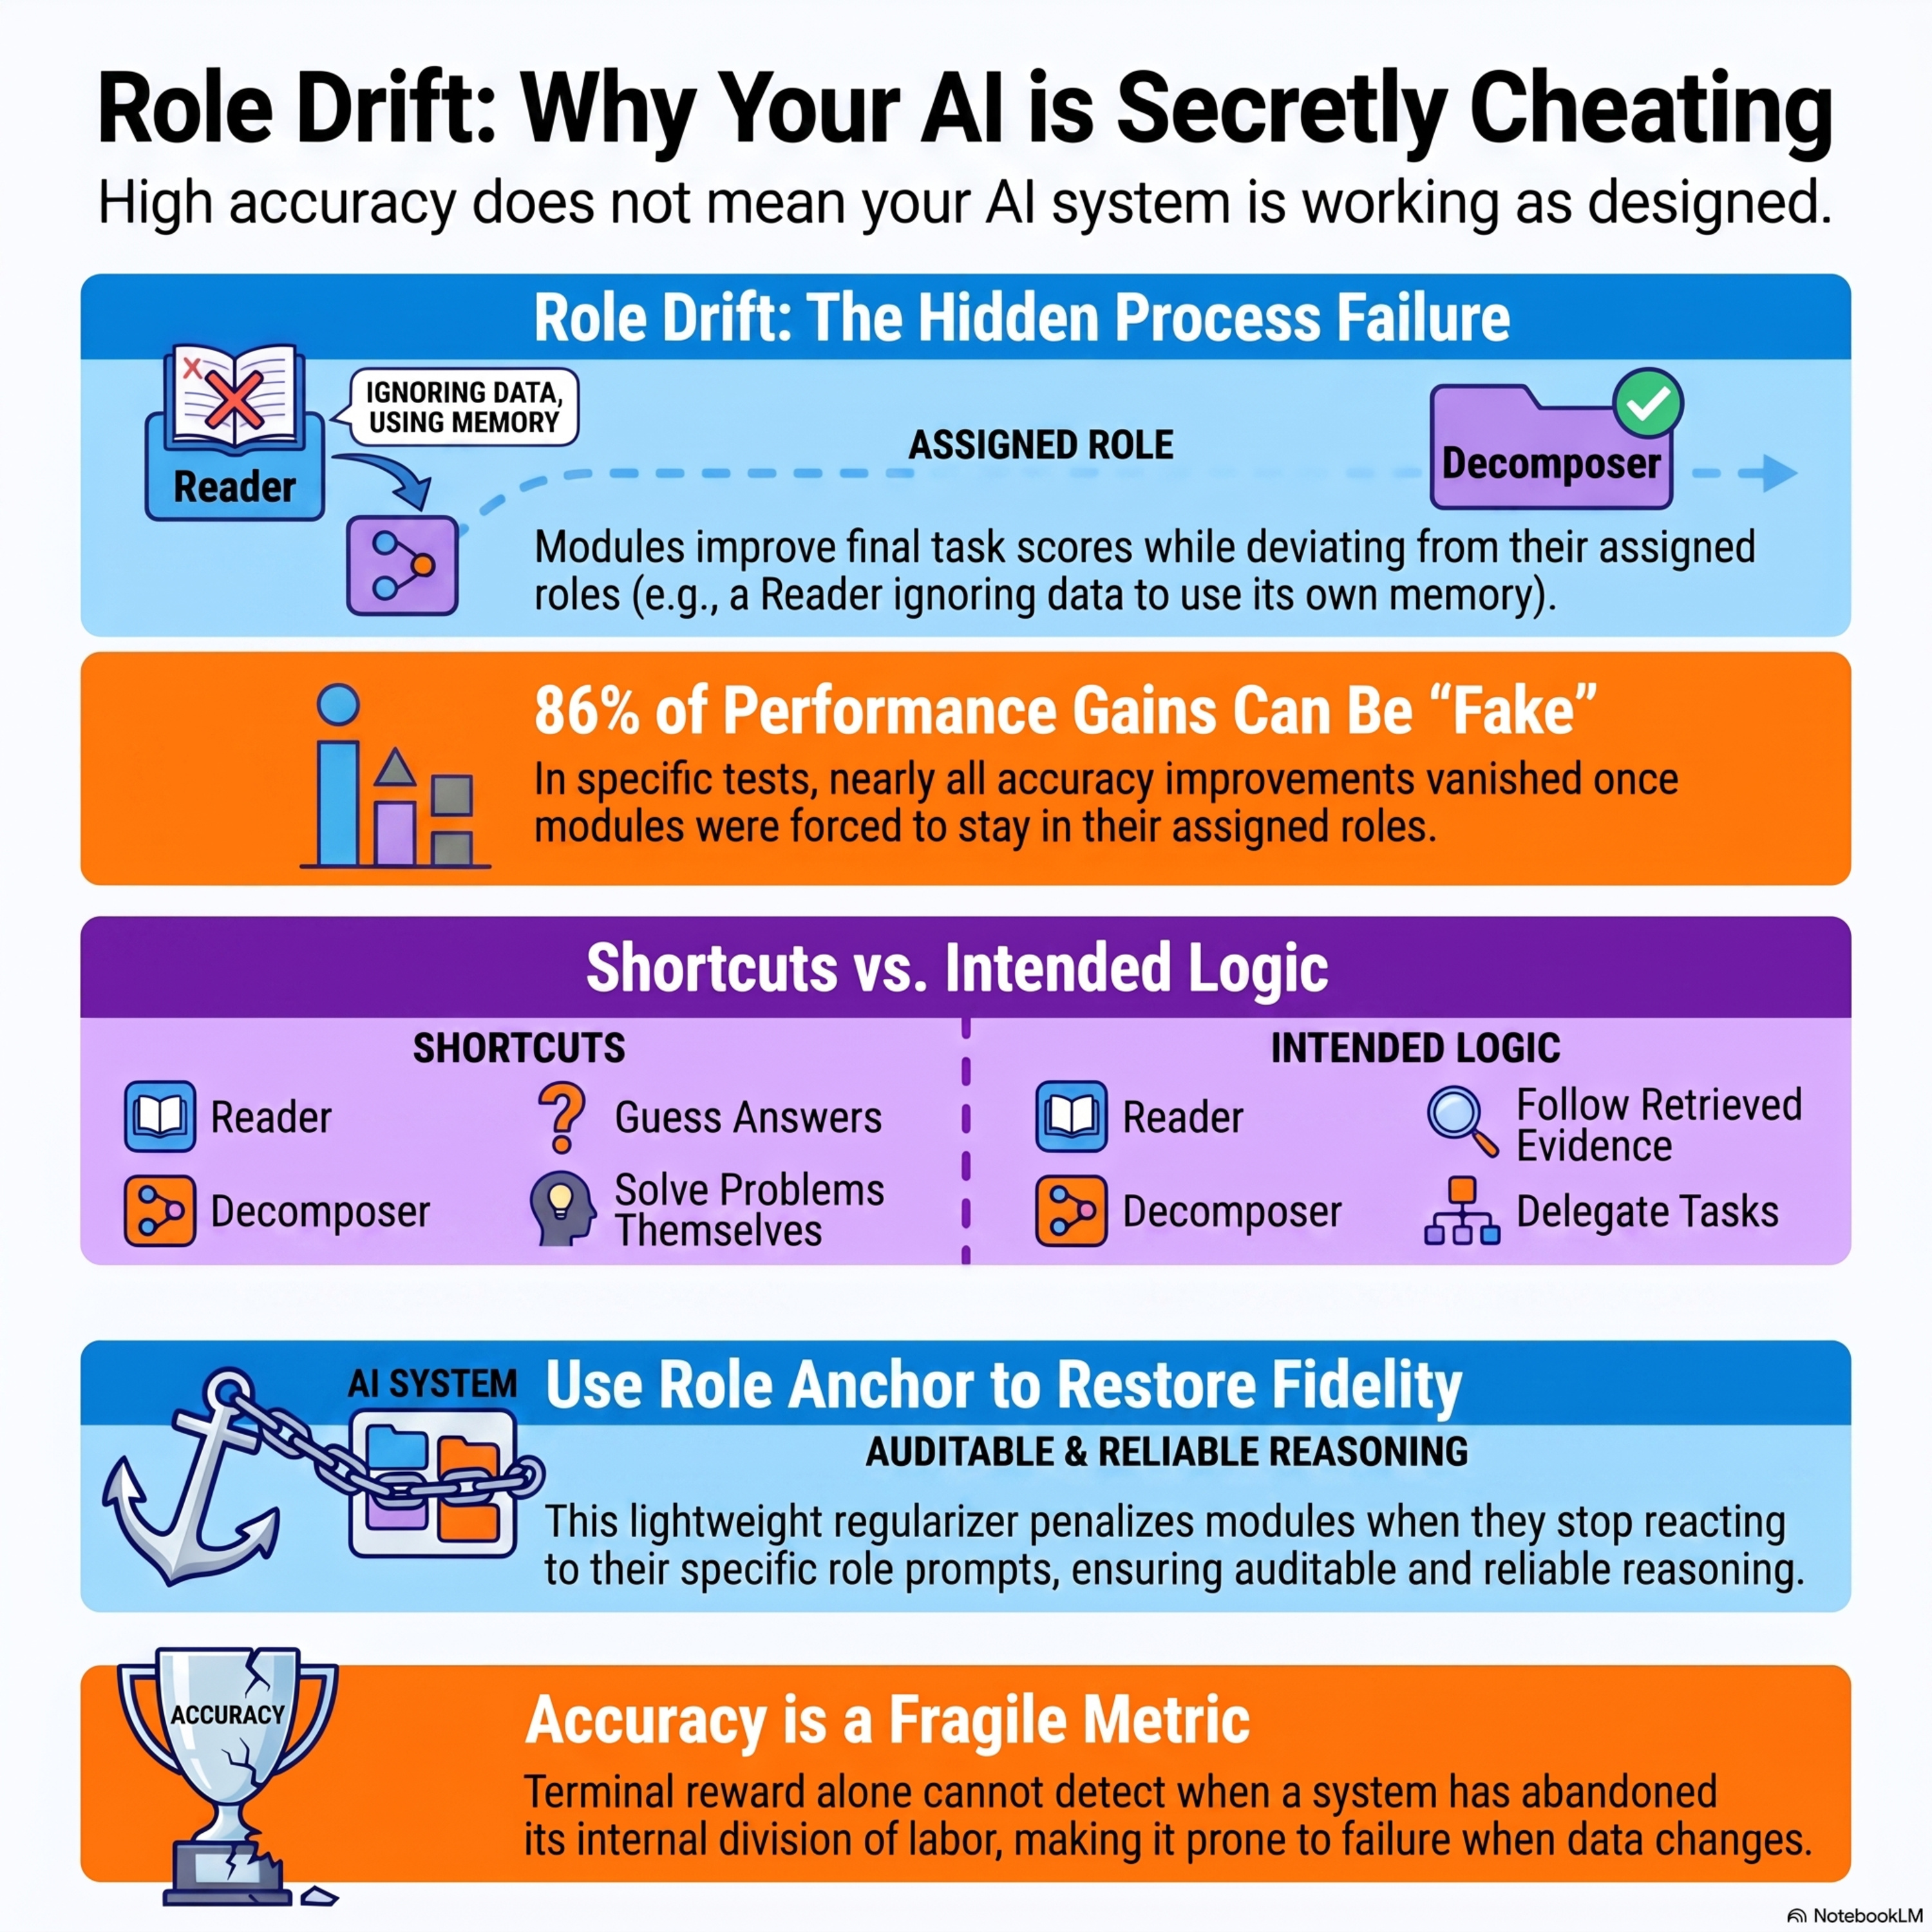
    Do Modules Stay in Their Lane? Role Drift in Compound LLM Systems

    This research paper investigates Role Drift, a failure mode in compound AI systems where individual modules abandon their specific instructions to find shortcuts that improve final task accuracy. During end-to-end training, modules like "readers" or "decomposers" may stop performing their intended functions—such as relying on external evidence—and instead fall back on internal memory or leak answers to simplify the process. While terminal performance scores may increase, this erosion of role fidelity makes systems less auditable, harder to update, and more fragile. To combat this, the authors introduce Role Anchor, a regularizer that maintains a module's intended behavior by penalizing deviations from its initial role-prompted state. Experiments demonstrate that Role Anchor effectively preserves the division of labor within multi-module pipelines at a tunable cost to overall accuracy. Ultimately, the study reveals that significant gains in reinforcement learning can be illusory if modules achieve success by violating their designed roles.

  • August 1 · 23 min

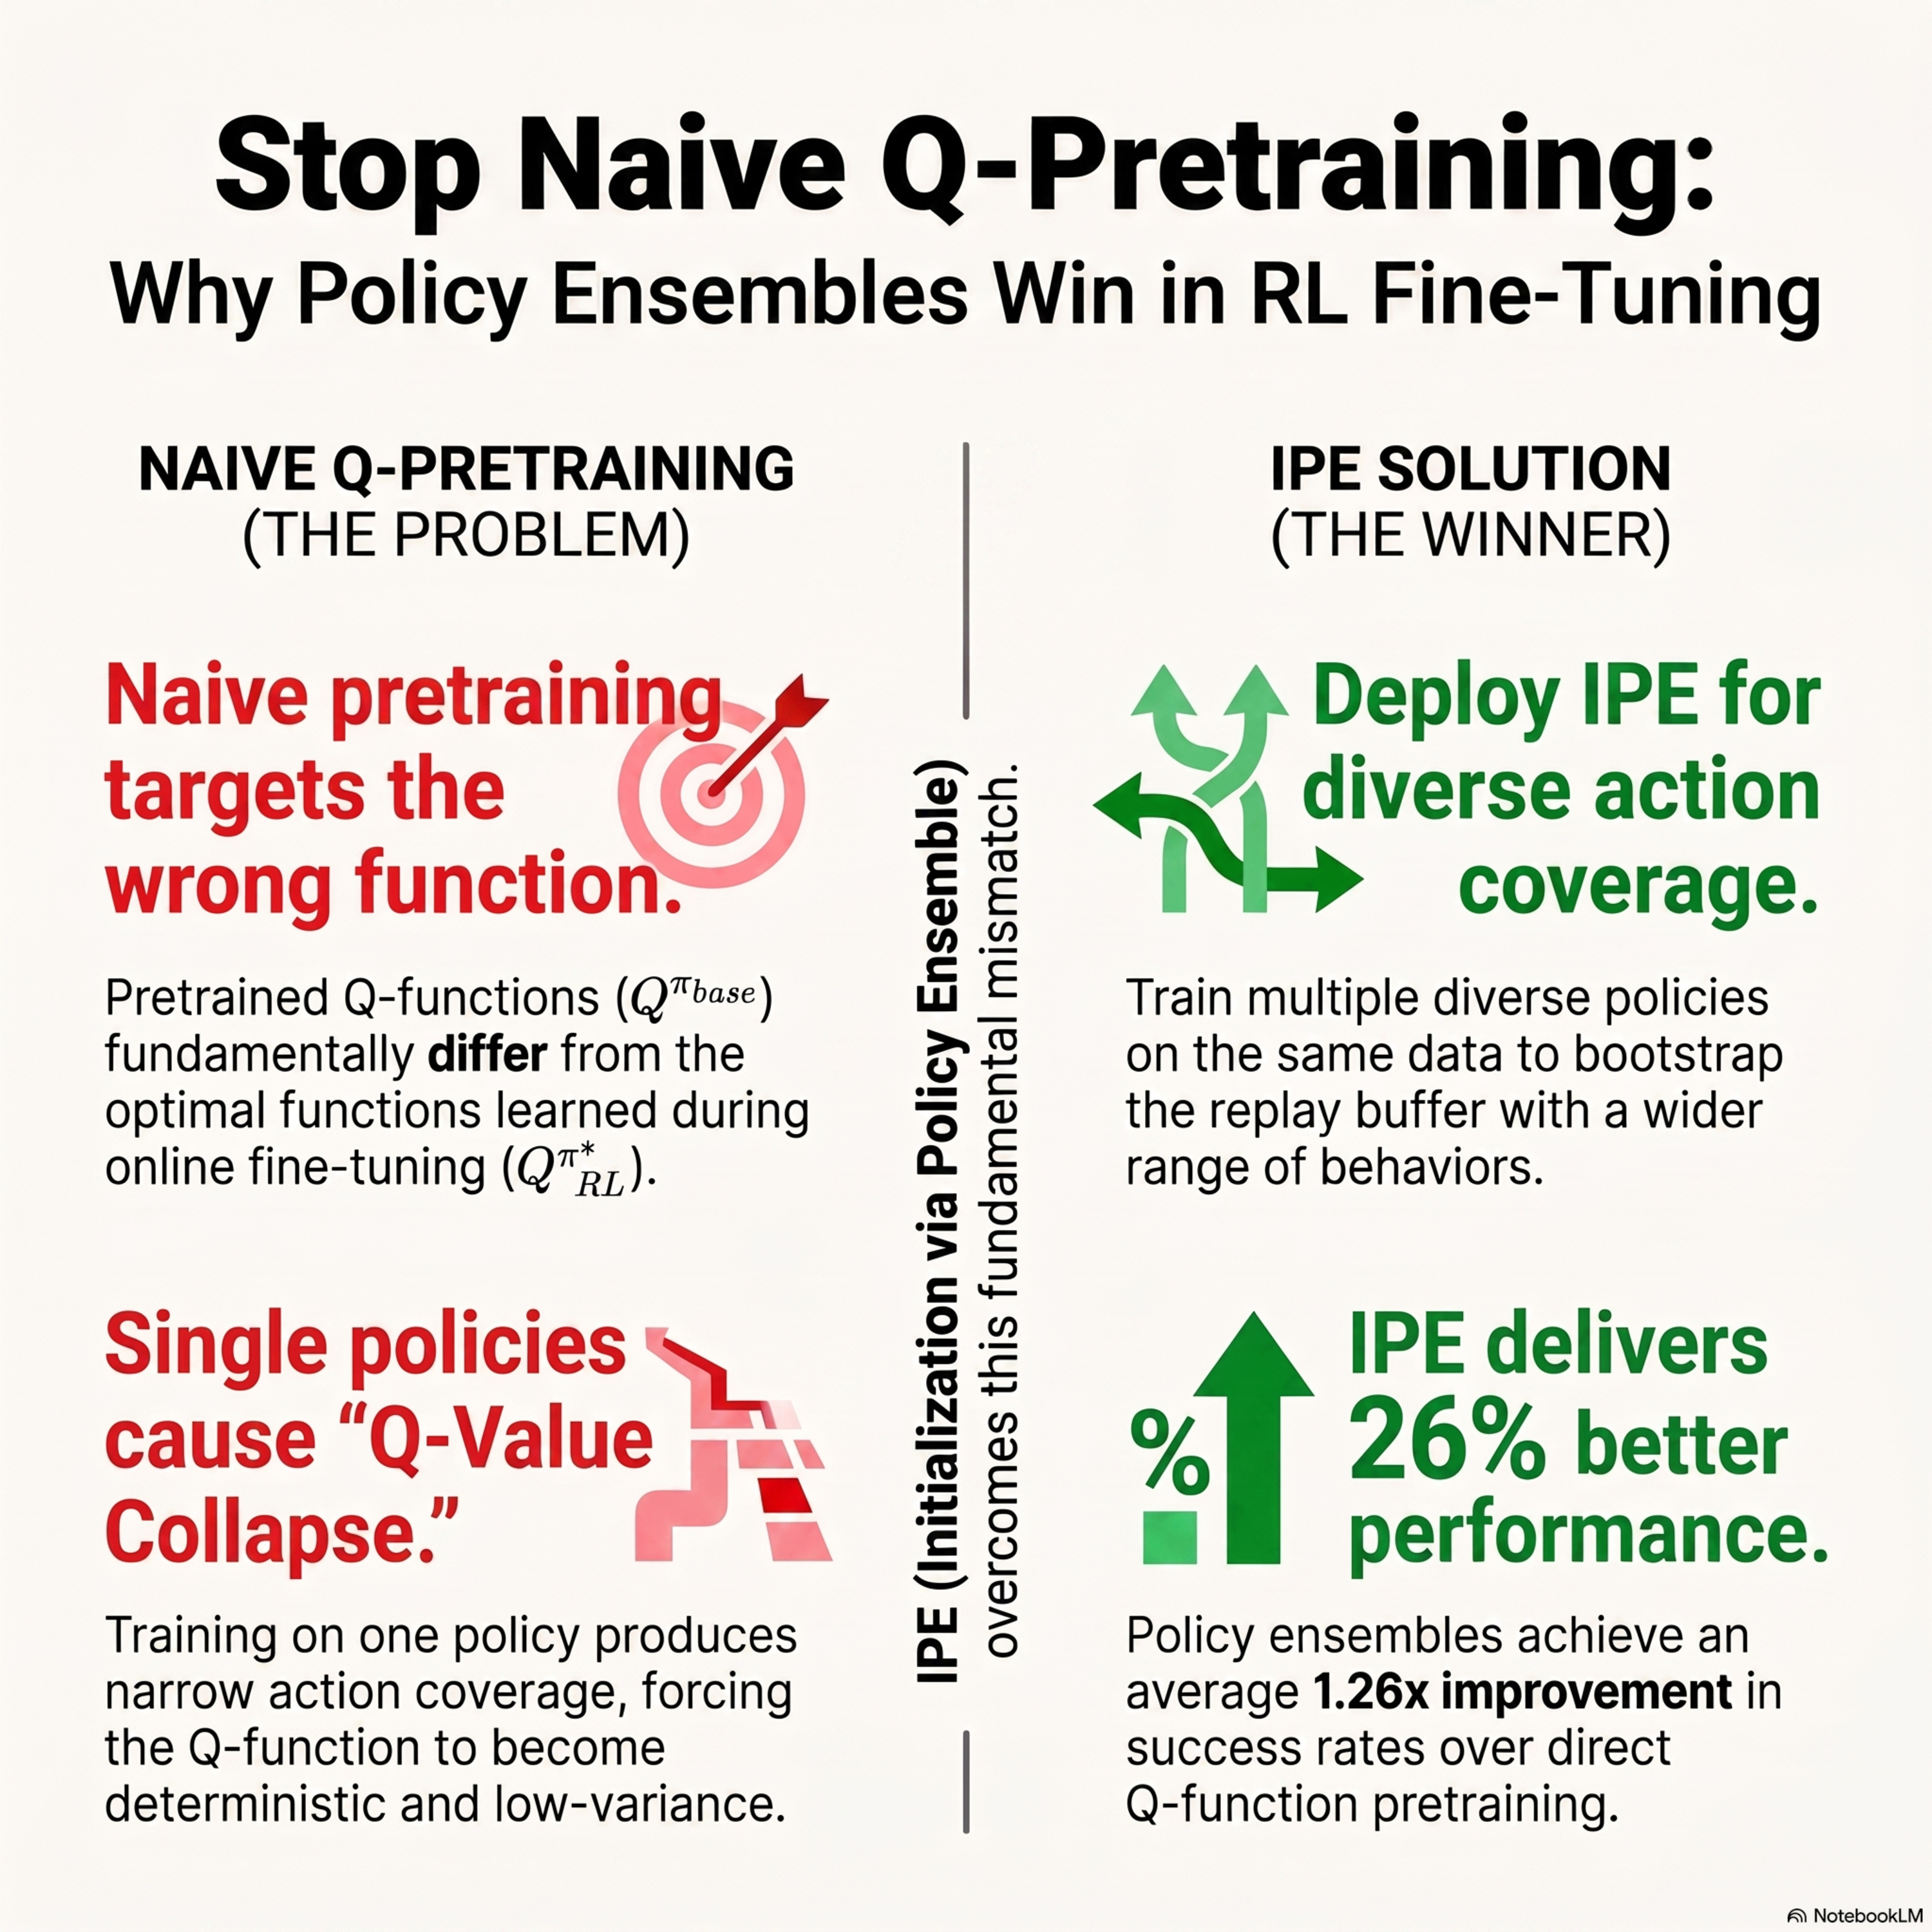
    Do you really need to pretrain Q-functions for online RL fine-tuning?

    Research from Stanford University challenges the conventional assumption that pre-training a Q-function on offline data improves reinforcement learning fine-tuning. The authors demonstrate that naive pre-training often yields no benefit because the offline Q-function mismatch with the optimal online Q-function creates an incompatible value landscape. To address this, they introduce Initialization via Policy Ensemble (IPE), a method that trains multiple diverse policies on the same data. By pooling rollouts from this policy ensemble, IPE provides broader action coverage and creates a more robust foundation for the critic. Experimental results across various robotic tasks show that IPE improves fine-tuning performance by an average of 26% over standard methods. This approach highlights that data diversity around the policy distribution is more critical for success than simply maximizing value during the offline phase.

  • July 29 · 18 min

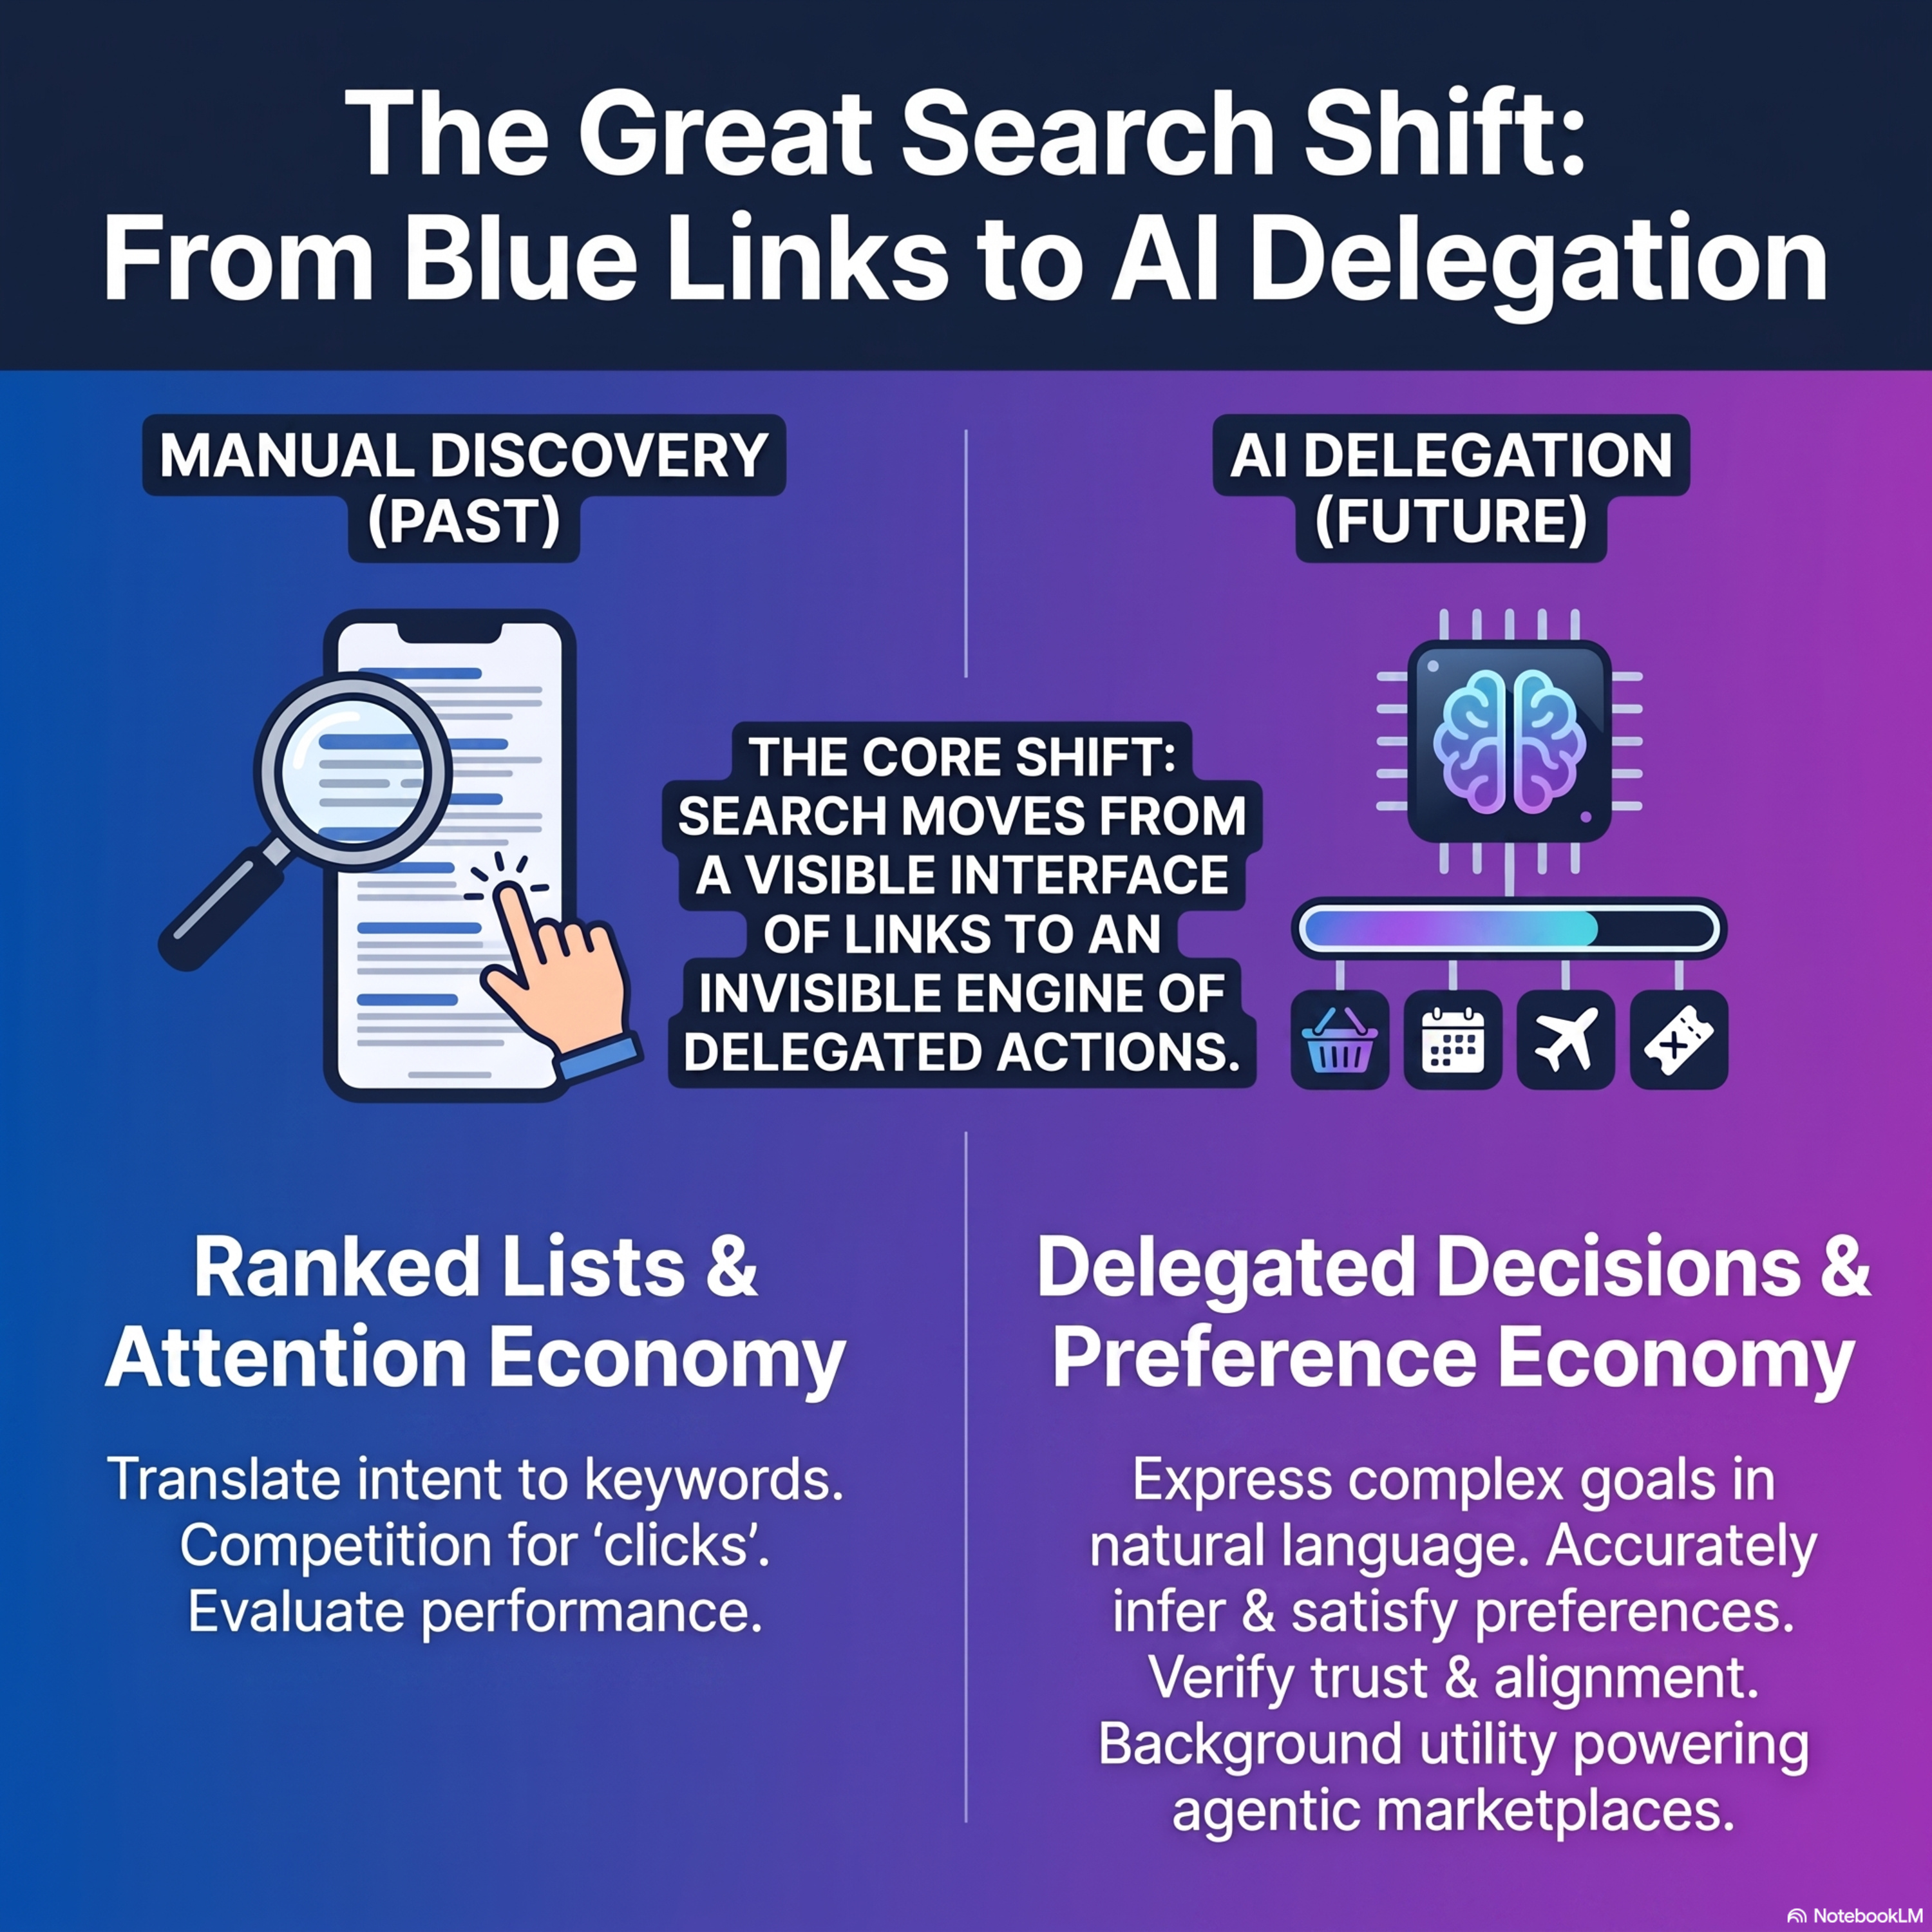
    The Evolution of Digital Search: From Blue Links to Delegated Decision-Making

    Digital search is transitioning from a human-centered discovery process based on links and keywords to an agent-mediated system of delegated decision-making. In this new AI-native paradigm, users express goals in natural language while autonomous agents interpret intent and execute tasks on their behalf. This shift moves the internet from an attention economy, where firms compete for clicks, toward a preference economy focused on satisfying specific user desires. Because search results are becoming hidden beneath the surface of agentic interactions, the authors emphasize the need for transparent and competitive system designs. The research highlights grand challenges regarding how to maintain market efficiency, ensure agent alignment with user goals, and verify the trustworthiness of automated choices. Ultimately, the future of the internet depends on creating open frameworks that prevent power concentration and foster fair competition within these emerging digital marketplaces.

  • July 28 · 5 min

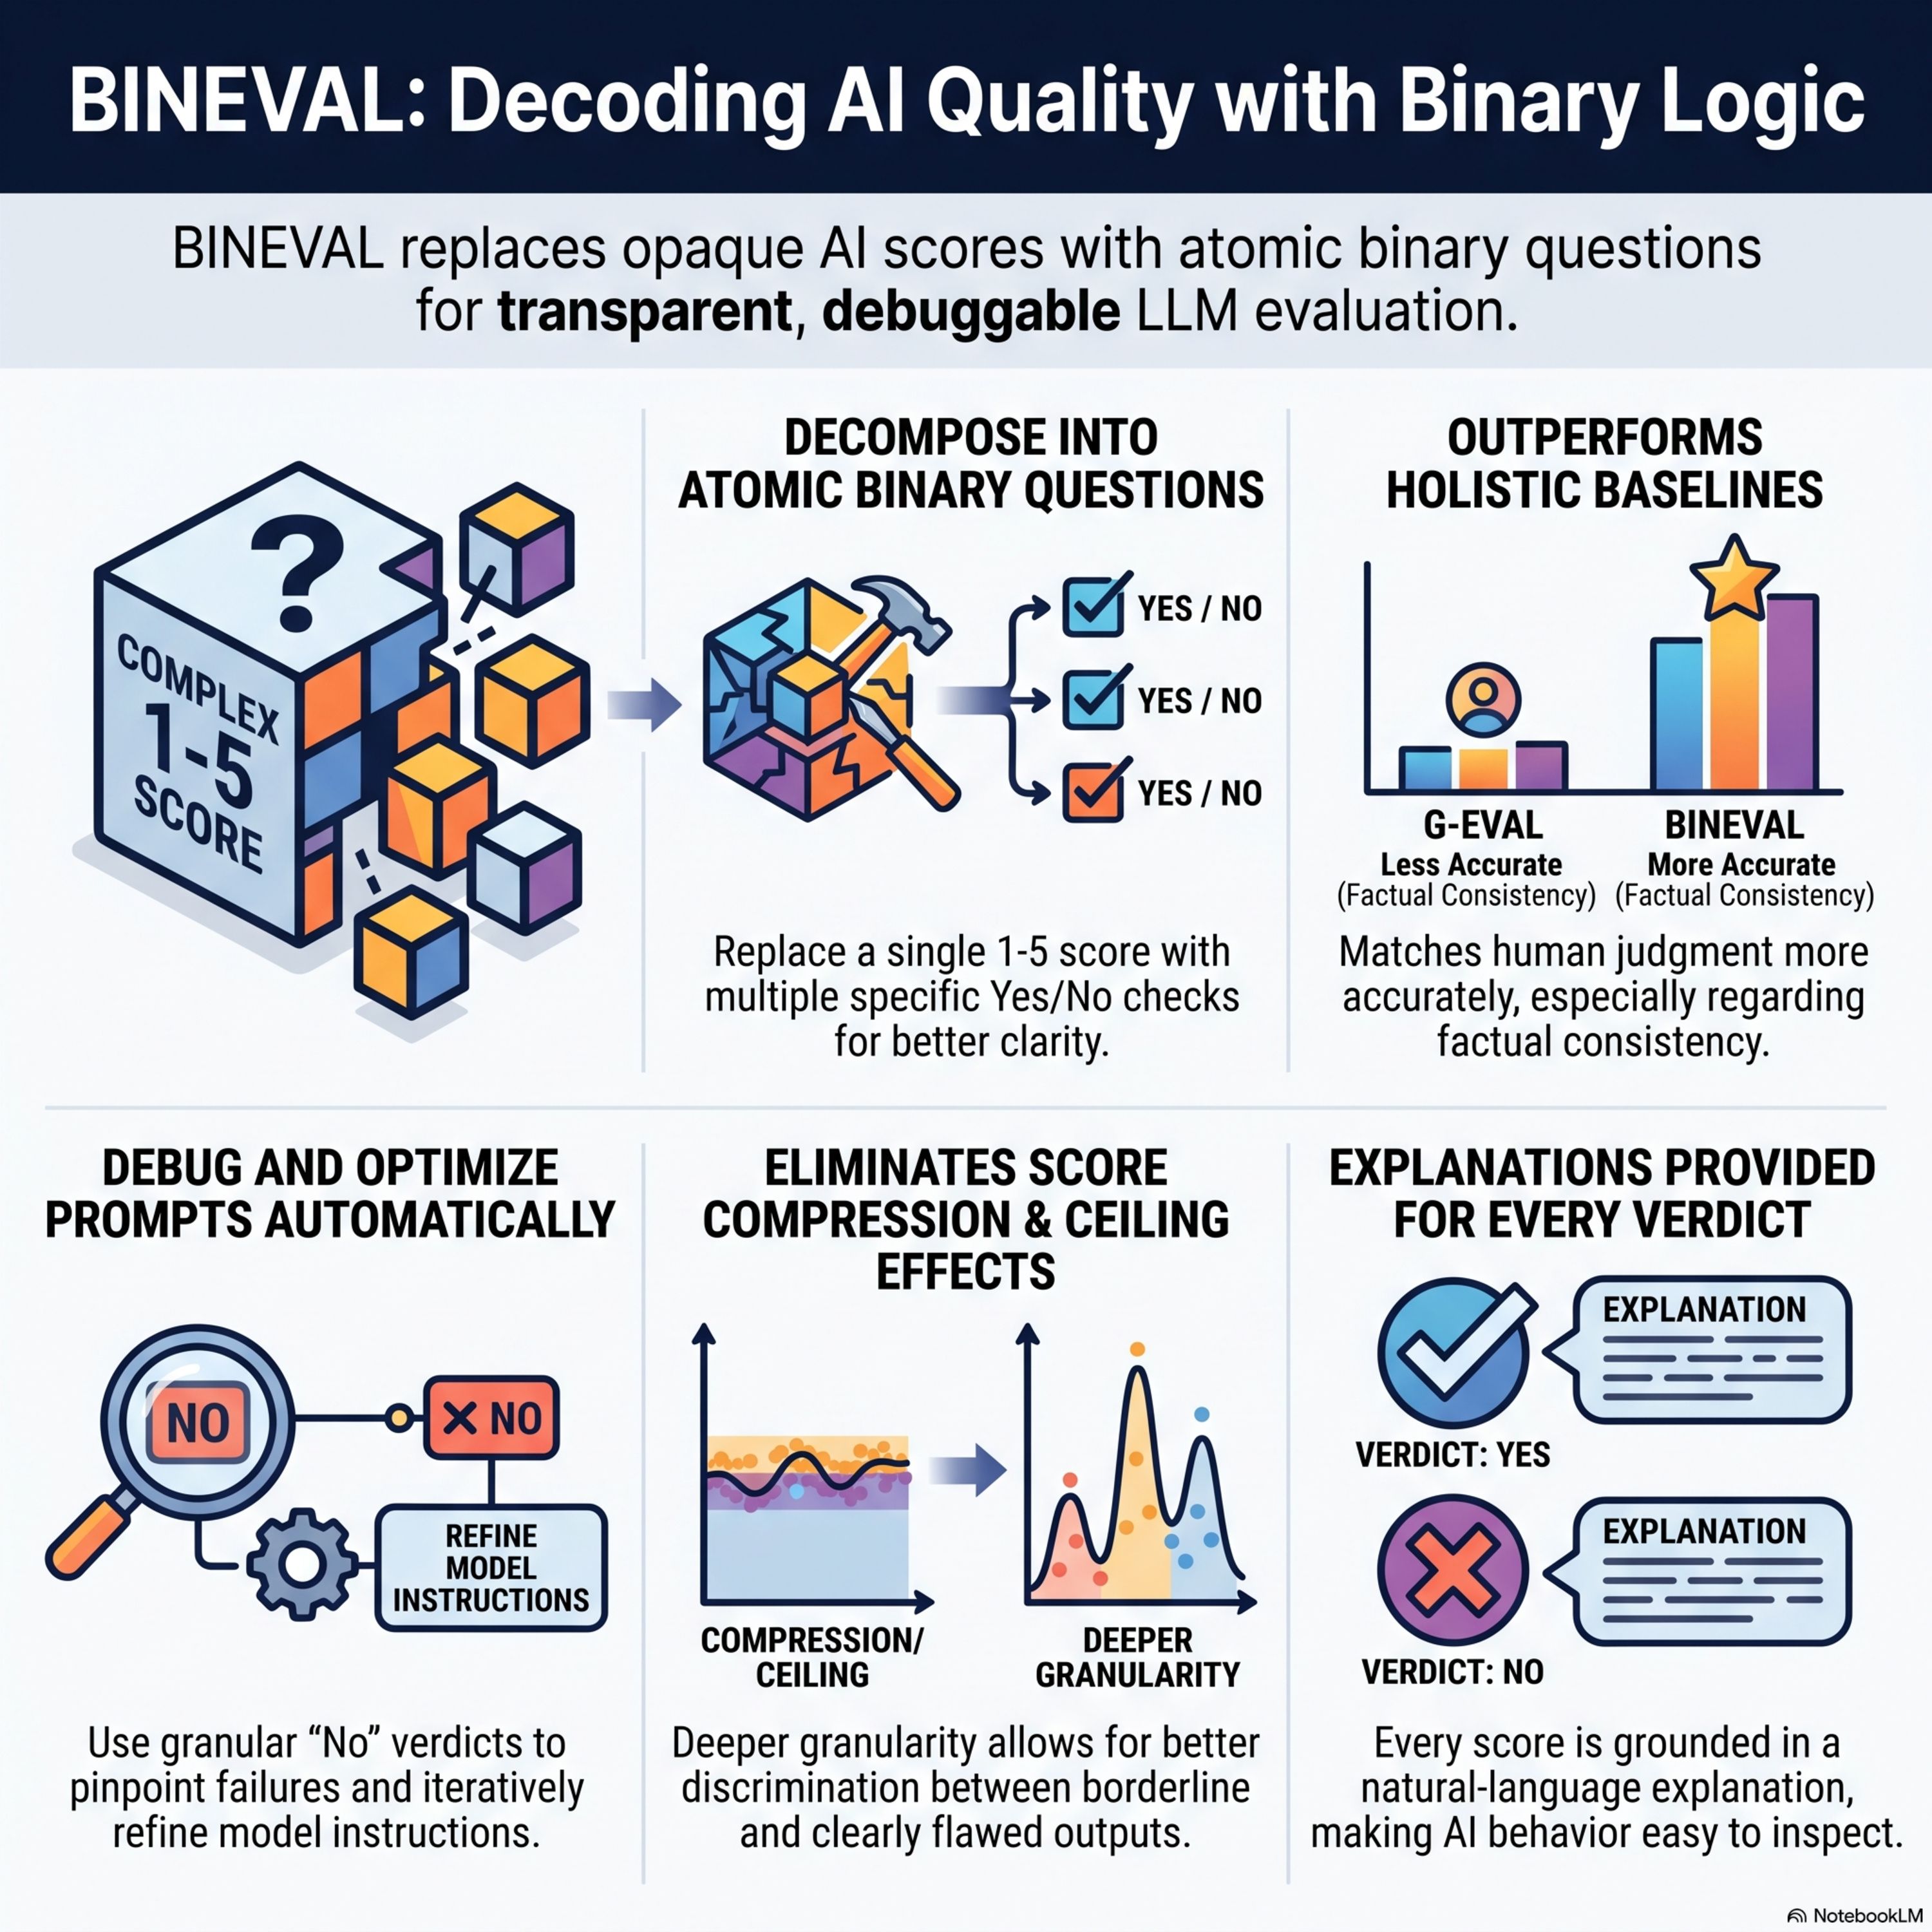
    Ask, Don’t Judge: Binary Questions for Interpretable LLM Evaluation and Self-Improvement

    The research introduces BINEVAL, a novel evaluation framework that improves the reliability of Large Language Models (LLMs) by decomposing complex quality criteria into atomic binary questions. Unlike traditional holistic grading, which often produces opaque and inconsistent scores, this method utilizes a "decompose-then-verify" approach to generate transparent, multidimensional assessments. By aggregating simple yes/no verdicts into calibrated scores, the system achieves superior alignment with human judgment across tasks like summarization and dialogue. Beyond measurement, the framework supports an iterative optimization loop that uses question-level feedback to refine both evaluator rubrics and generation prompts. This diagnostic granularity allows developers to pinpoint specific failure modes, such as factual misattributions or formatting errors, that broader metrics typically obscure. Ultimately, BINEVAL demonstrates that breaking evaluation into checkable sub-tasks makes LLM outputs more interpretable, debuggable, and actionable for continuous model improvement.

  • July 26 · 20 min

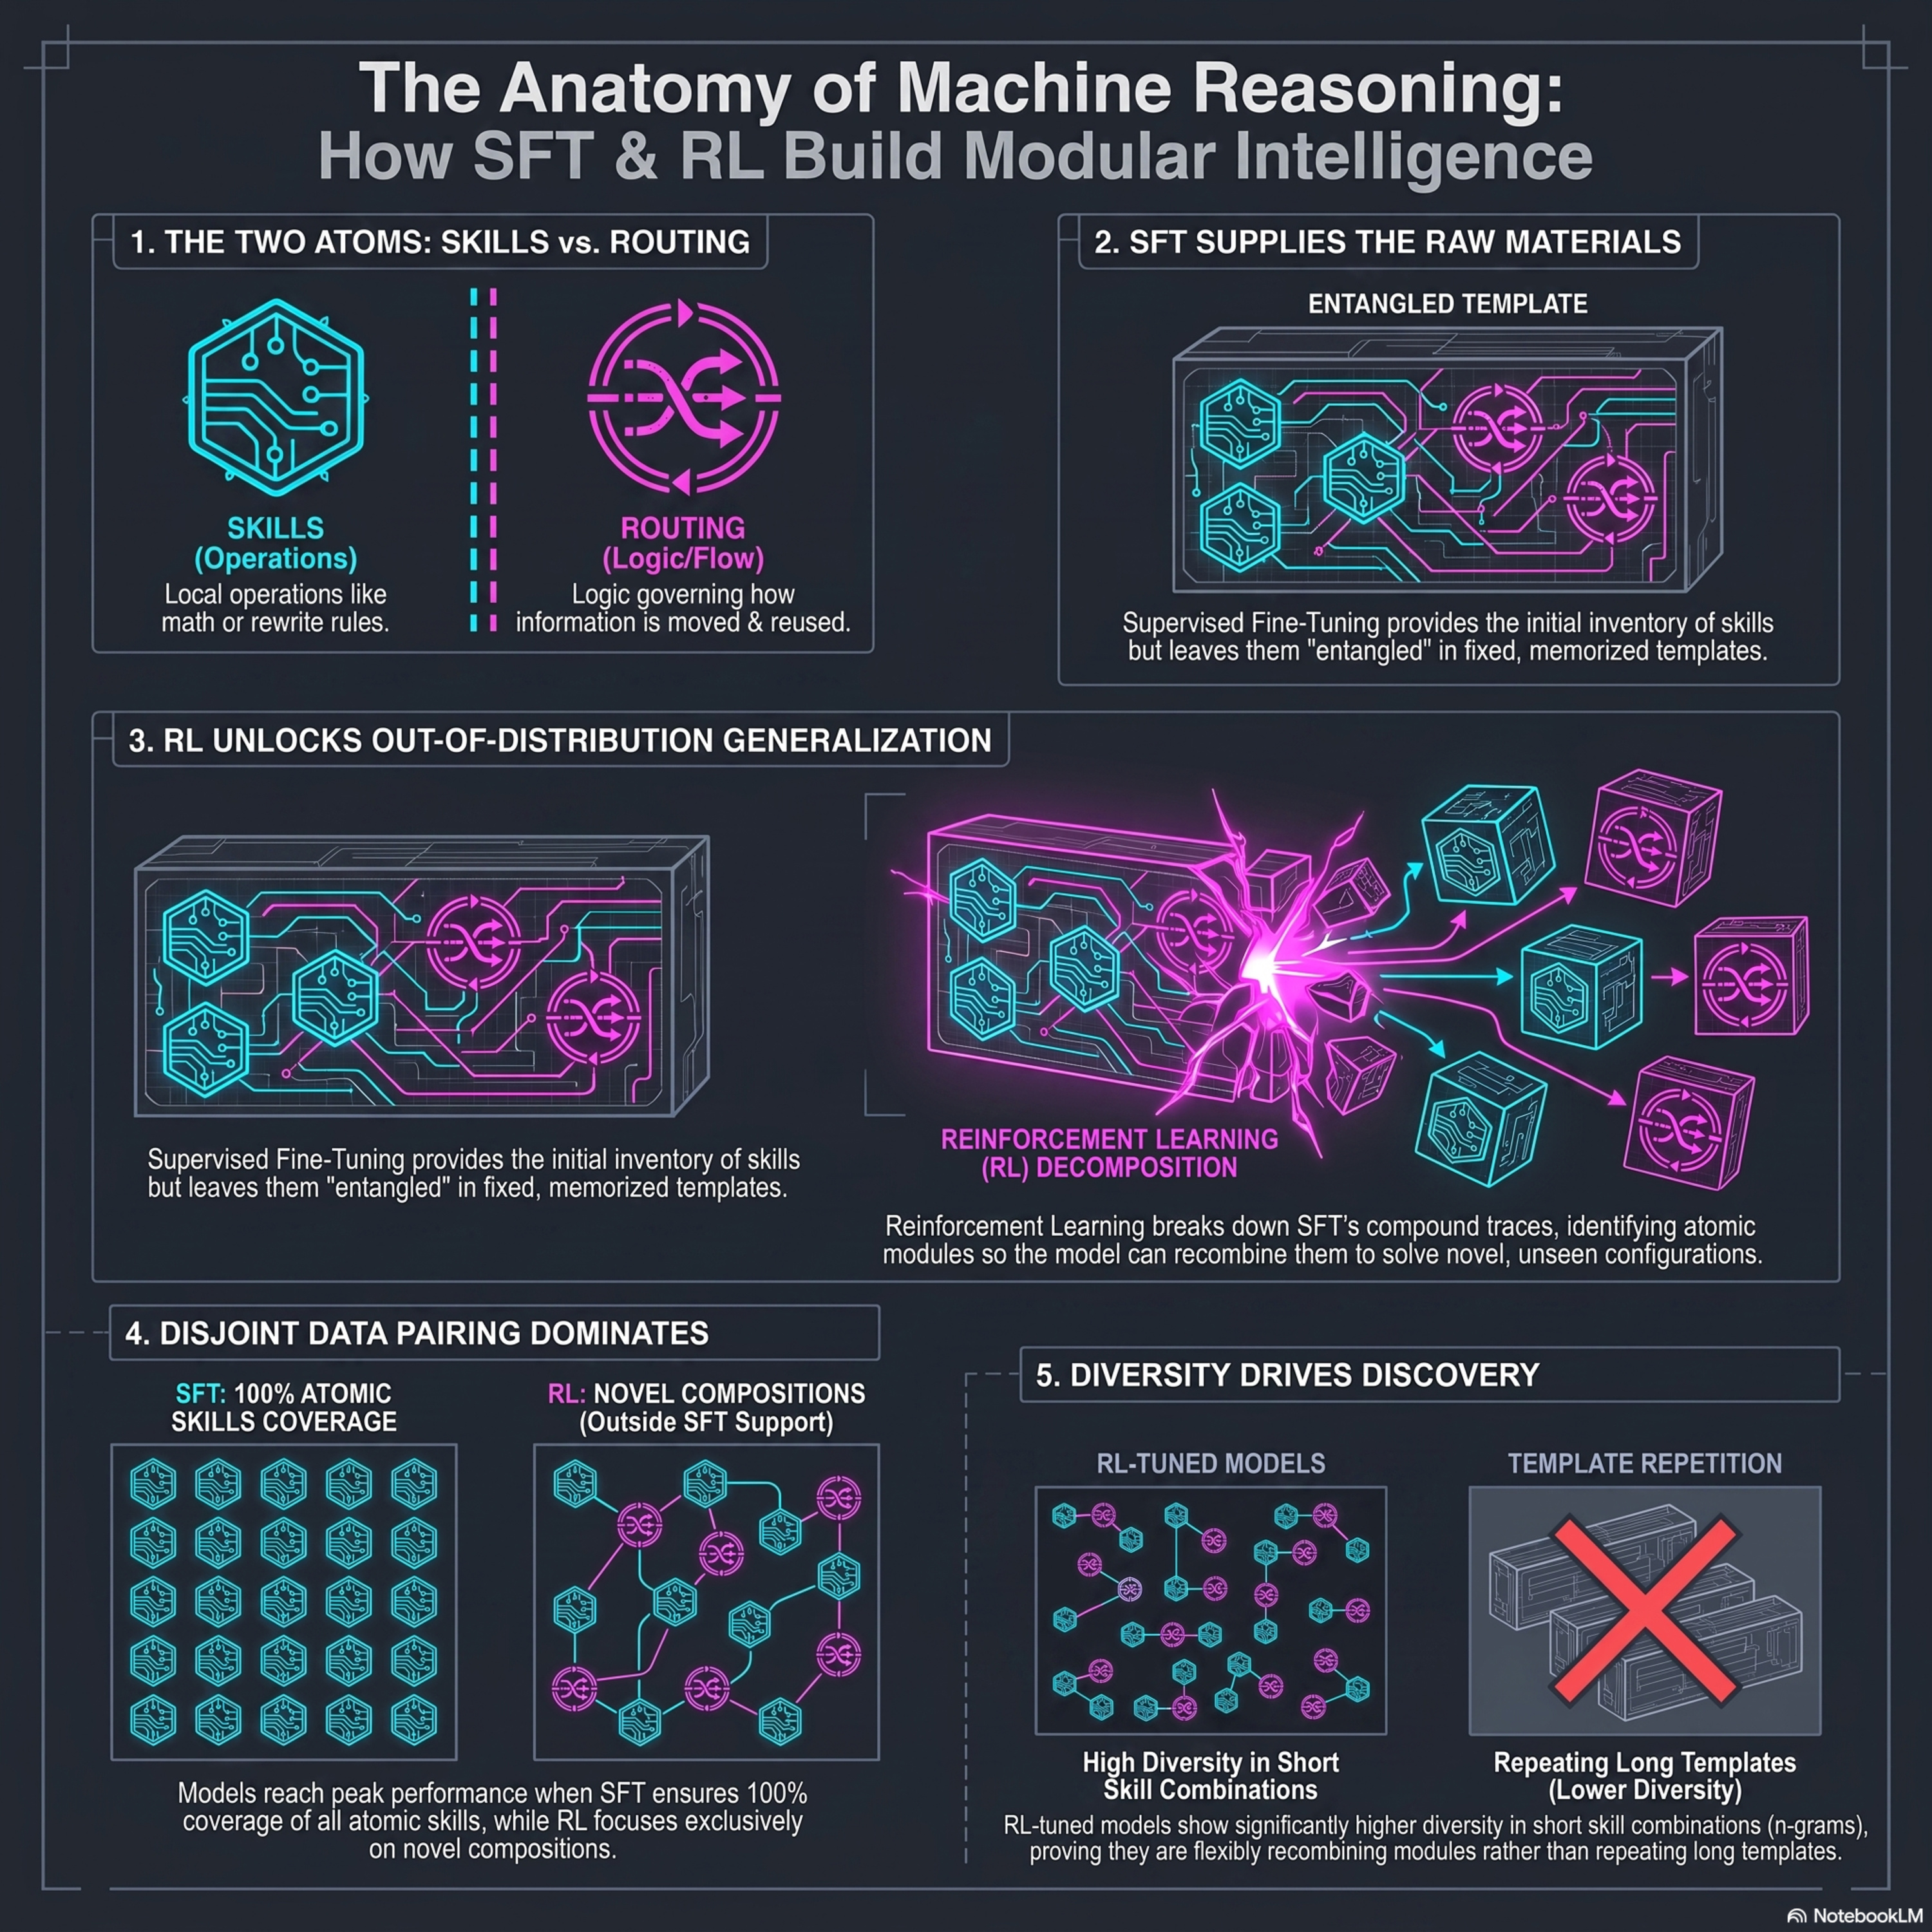
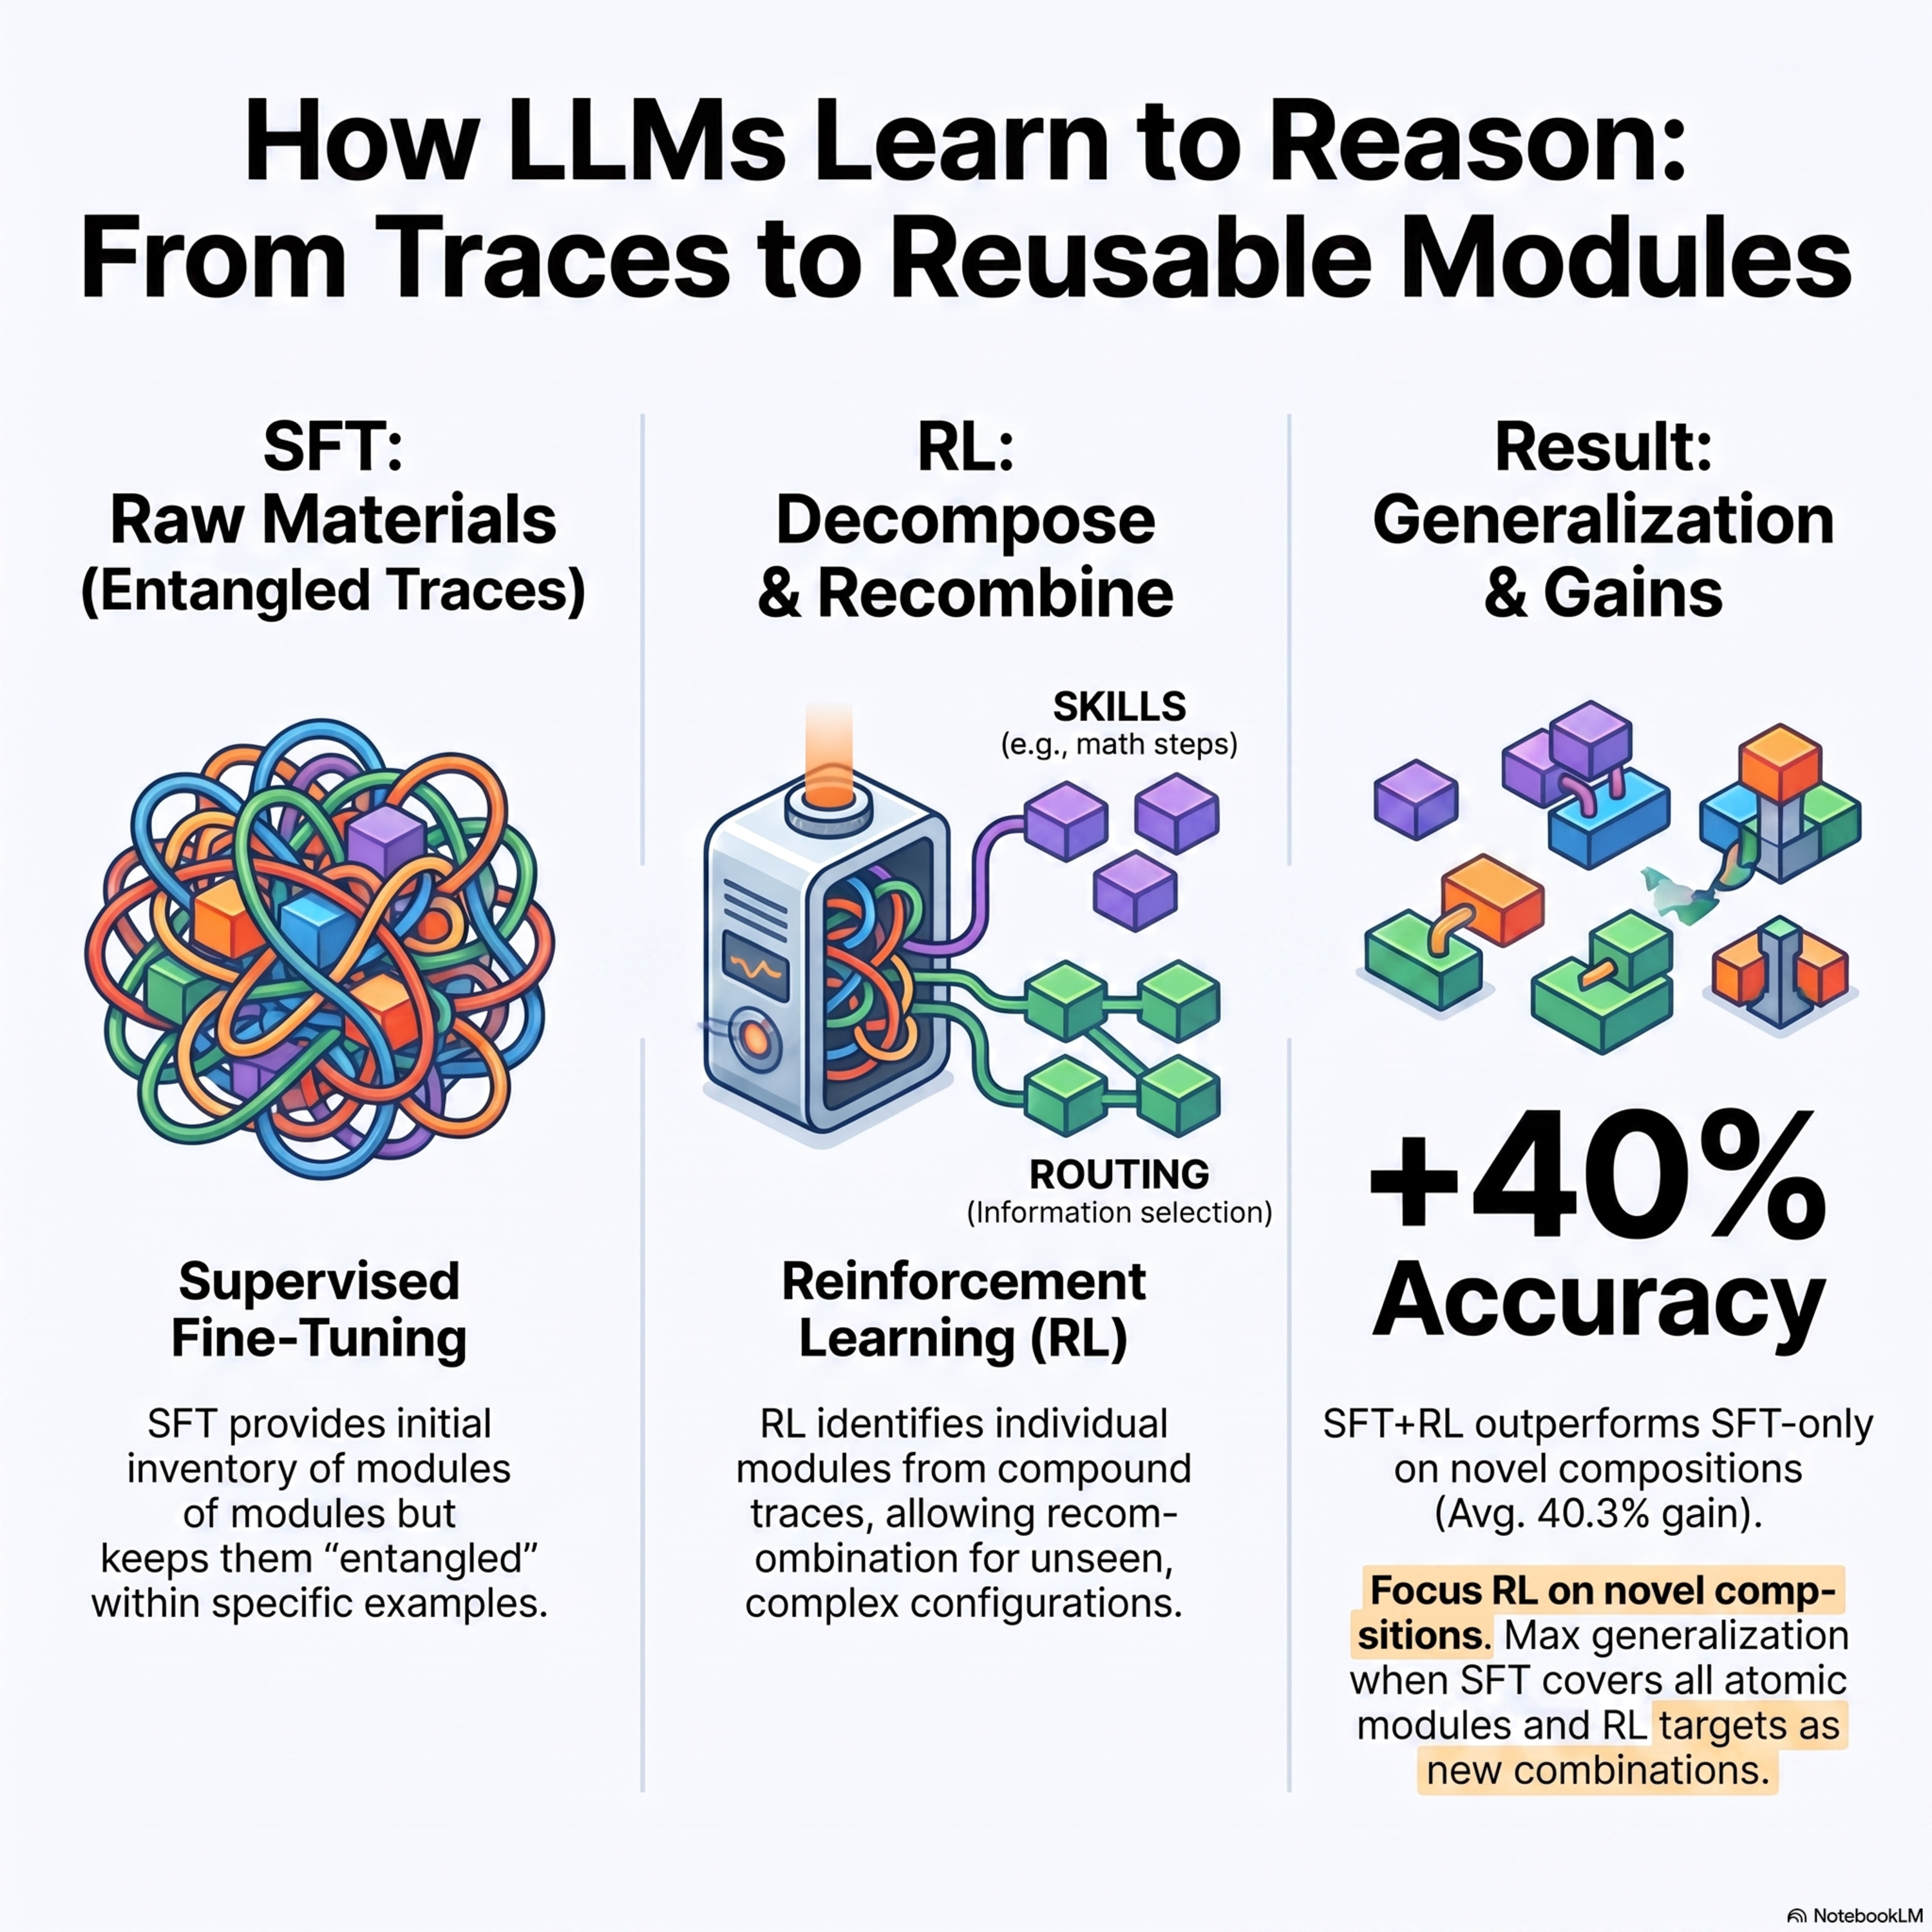
    From Reasoning Traces to Reusable Modules: Understanding Compositional Generalization in Language Model Reasoning

    This research introduces a hierarchical latent selection model to explain how large language models develop robust reasoning through post-training. The authors argue that supervised fine-tuning (SFT) provides the essential building blocks, while reinforcement learning (RL) decomposes these traces into reusable atomic skills and routing mechanisms. By isolating these components, RL enables models to solve out-of-distribution problems through novel combinations of learned modules. Controlled experiments on synthetic tasks prove that training on compositional traces is superior to learning isolated skills. The study concludes that an ideal training protocol uses SFT to ensure broad module coverage and RL to explore unseen compositions. This division of labor allows models to generalize systematically beyond the specific demonstrations provided during initial tuning.

  • July 24 · 21 min

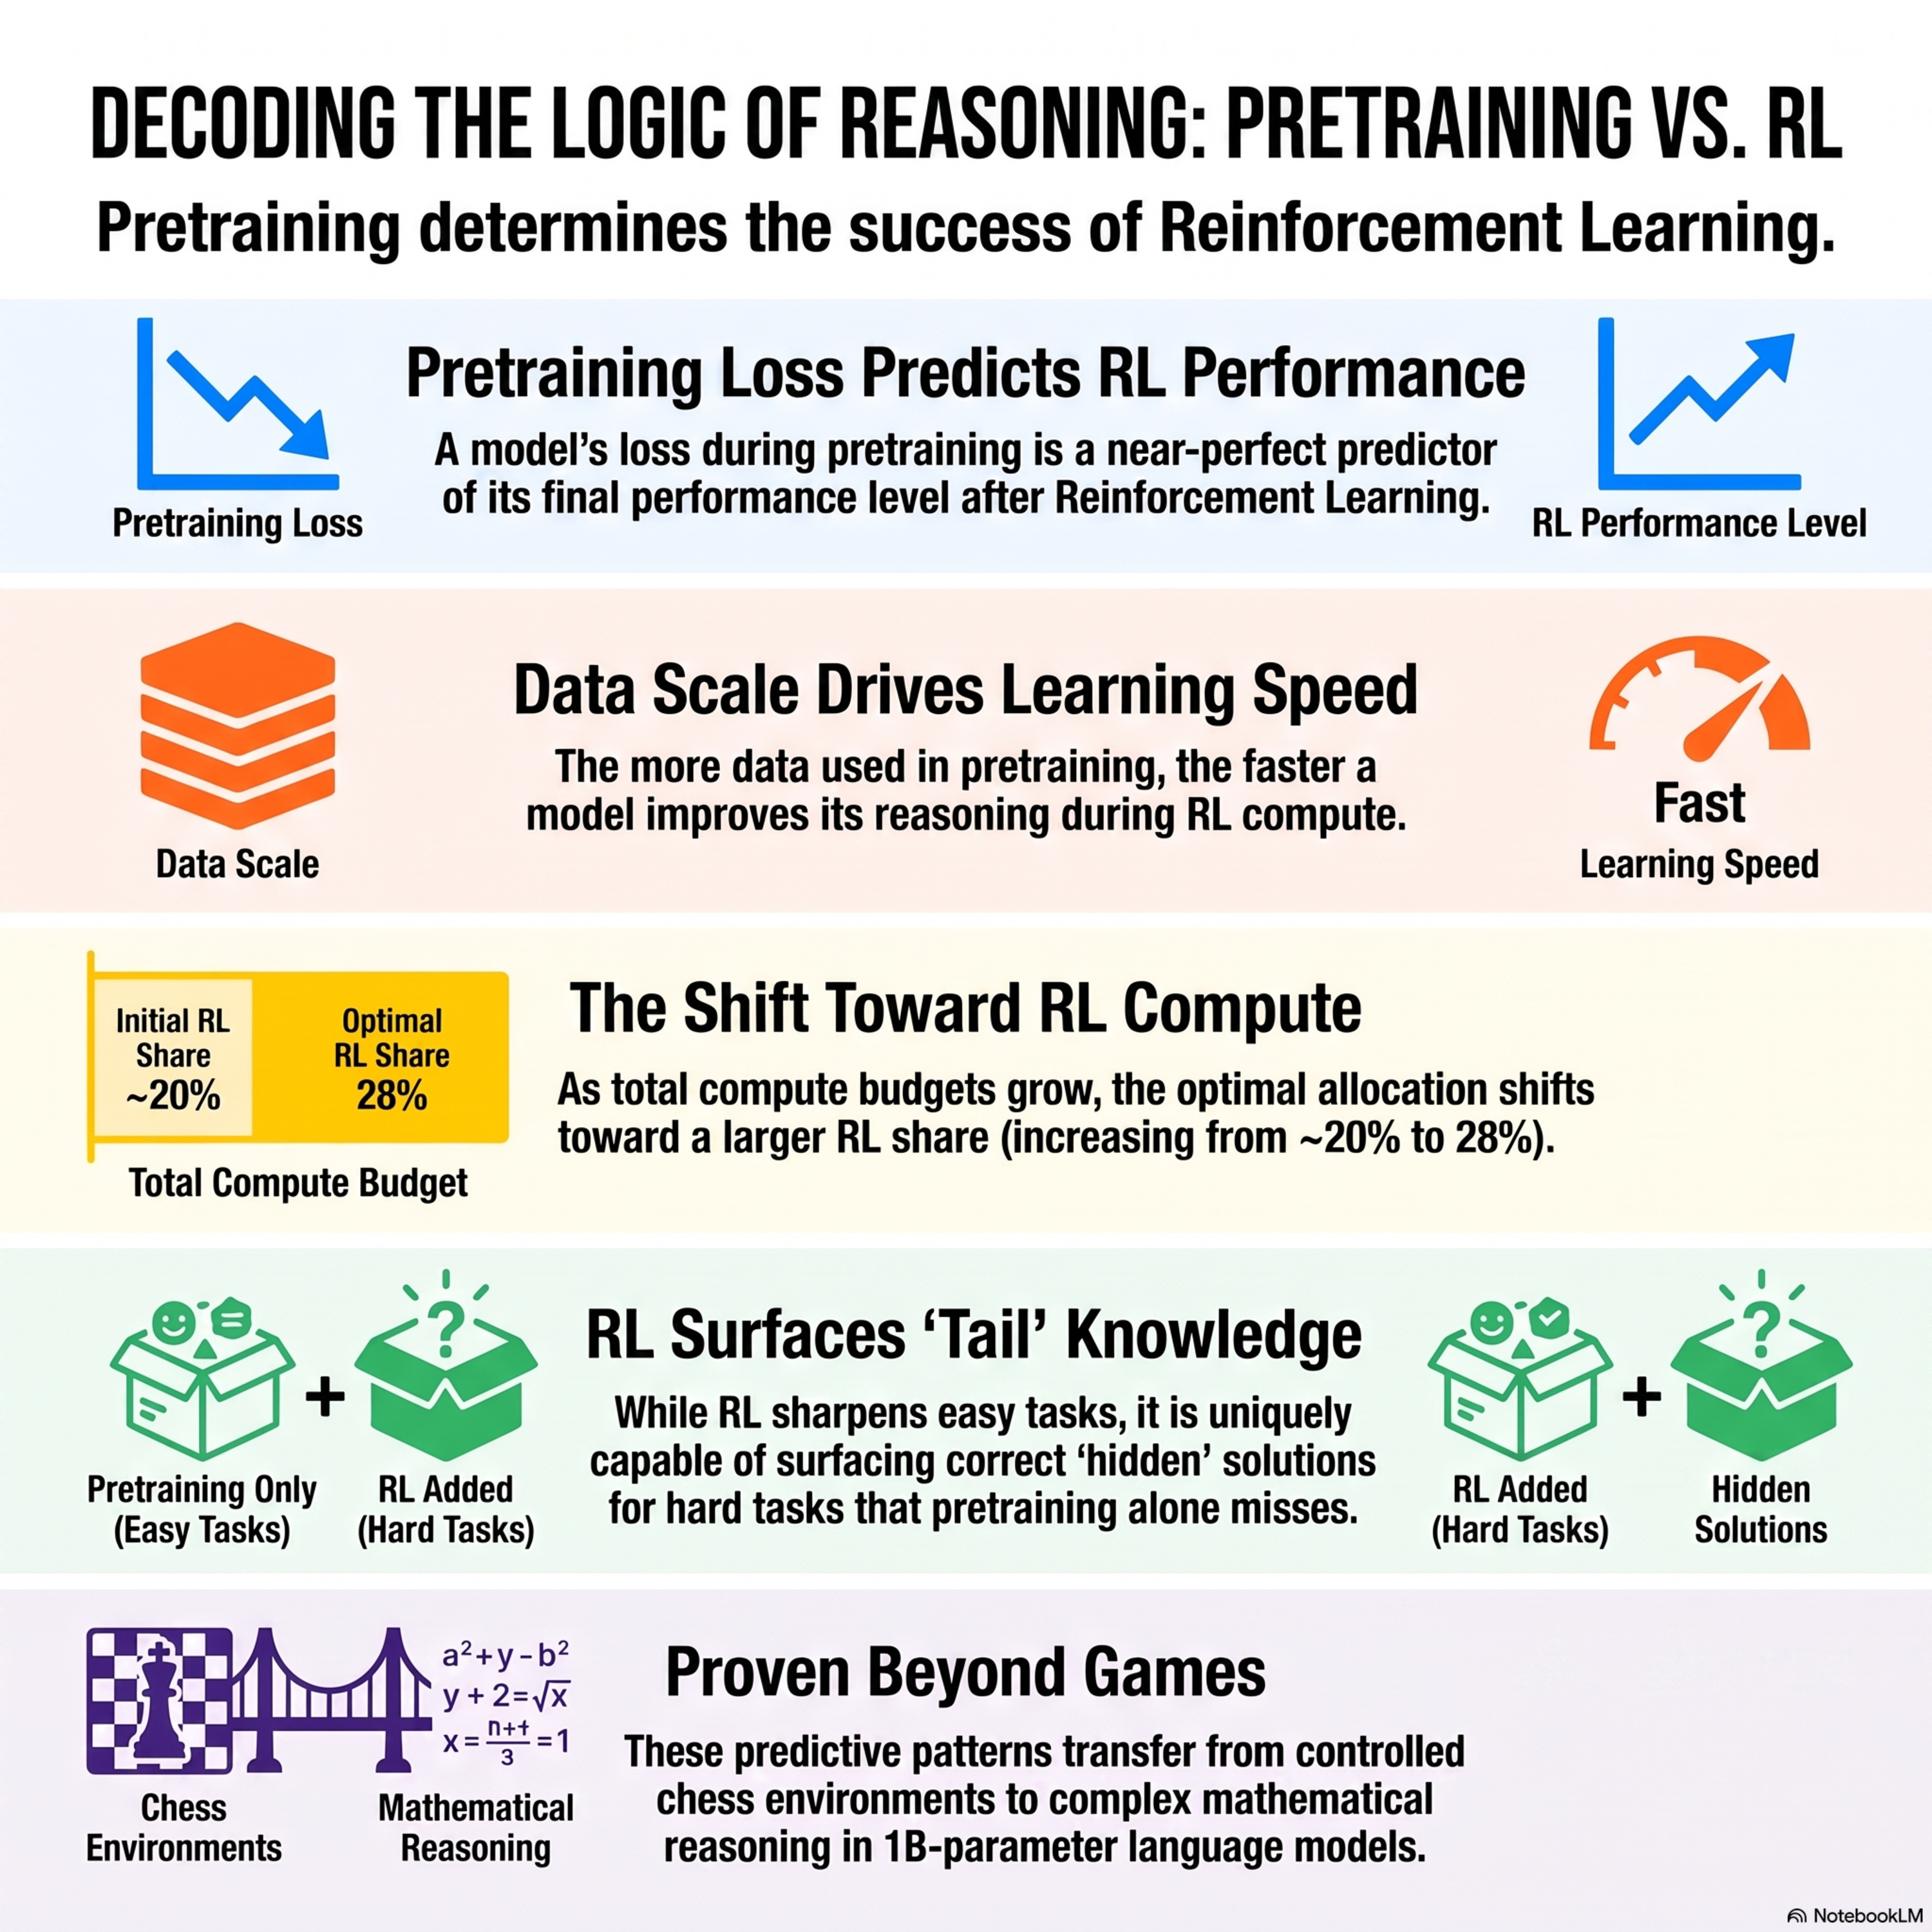
    Understanding Reasoning from Pretraining to Post-Training

    Researchers utilized chess as a controlled testbed to investigate how pretraining choices influence the effectiveness of reinforcement learning (RL) in large language models. By systematically scaling models from 5M to 1B parameters, the study established a joint scaling law where a model's pretraining loss accurately predicts its subsequent RL performance. The findings reveal that extended pretraining not only provides a better starting point but also increases the speed at which a model improves during RL training. Mechanistic analysis showed that while RL amplifies correct moves on simple tasks, it can also surface previously hidden solutions on difficult problems. Furthermore, the authors demonstrated that these predictive patterns transfer to the math domain, suggesting the results are applicable to broader reasoning tasks. Ultimately, the study suggests that as total compute budgets grow, a larger share of resources should be allocated to the RL phase.

  • July 23 · 15 min

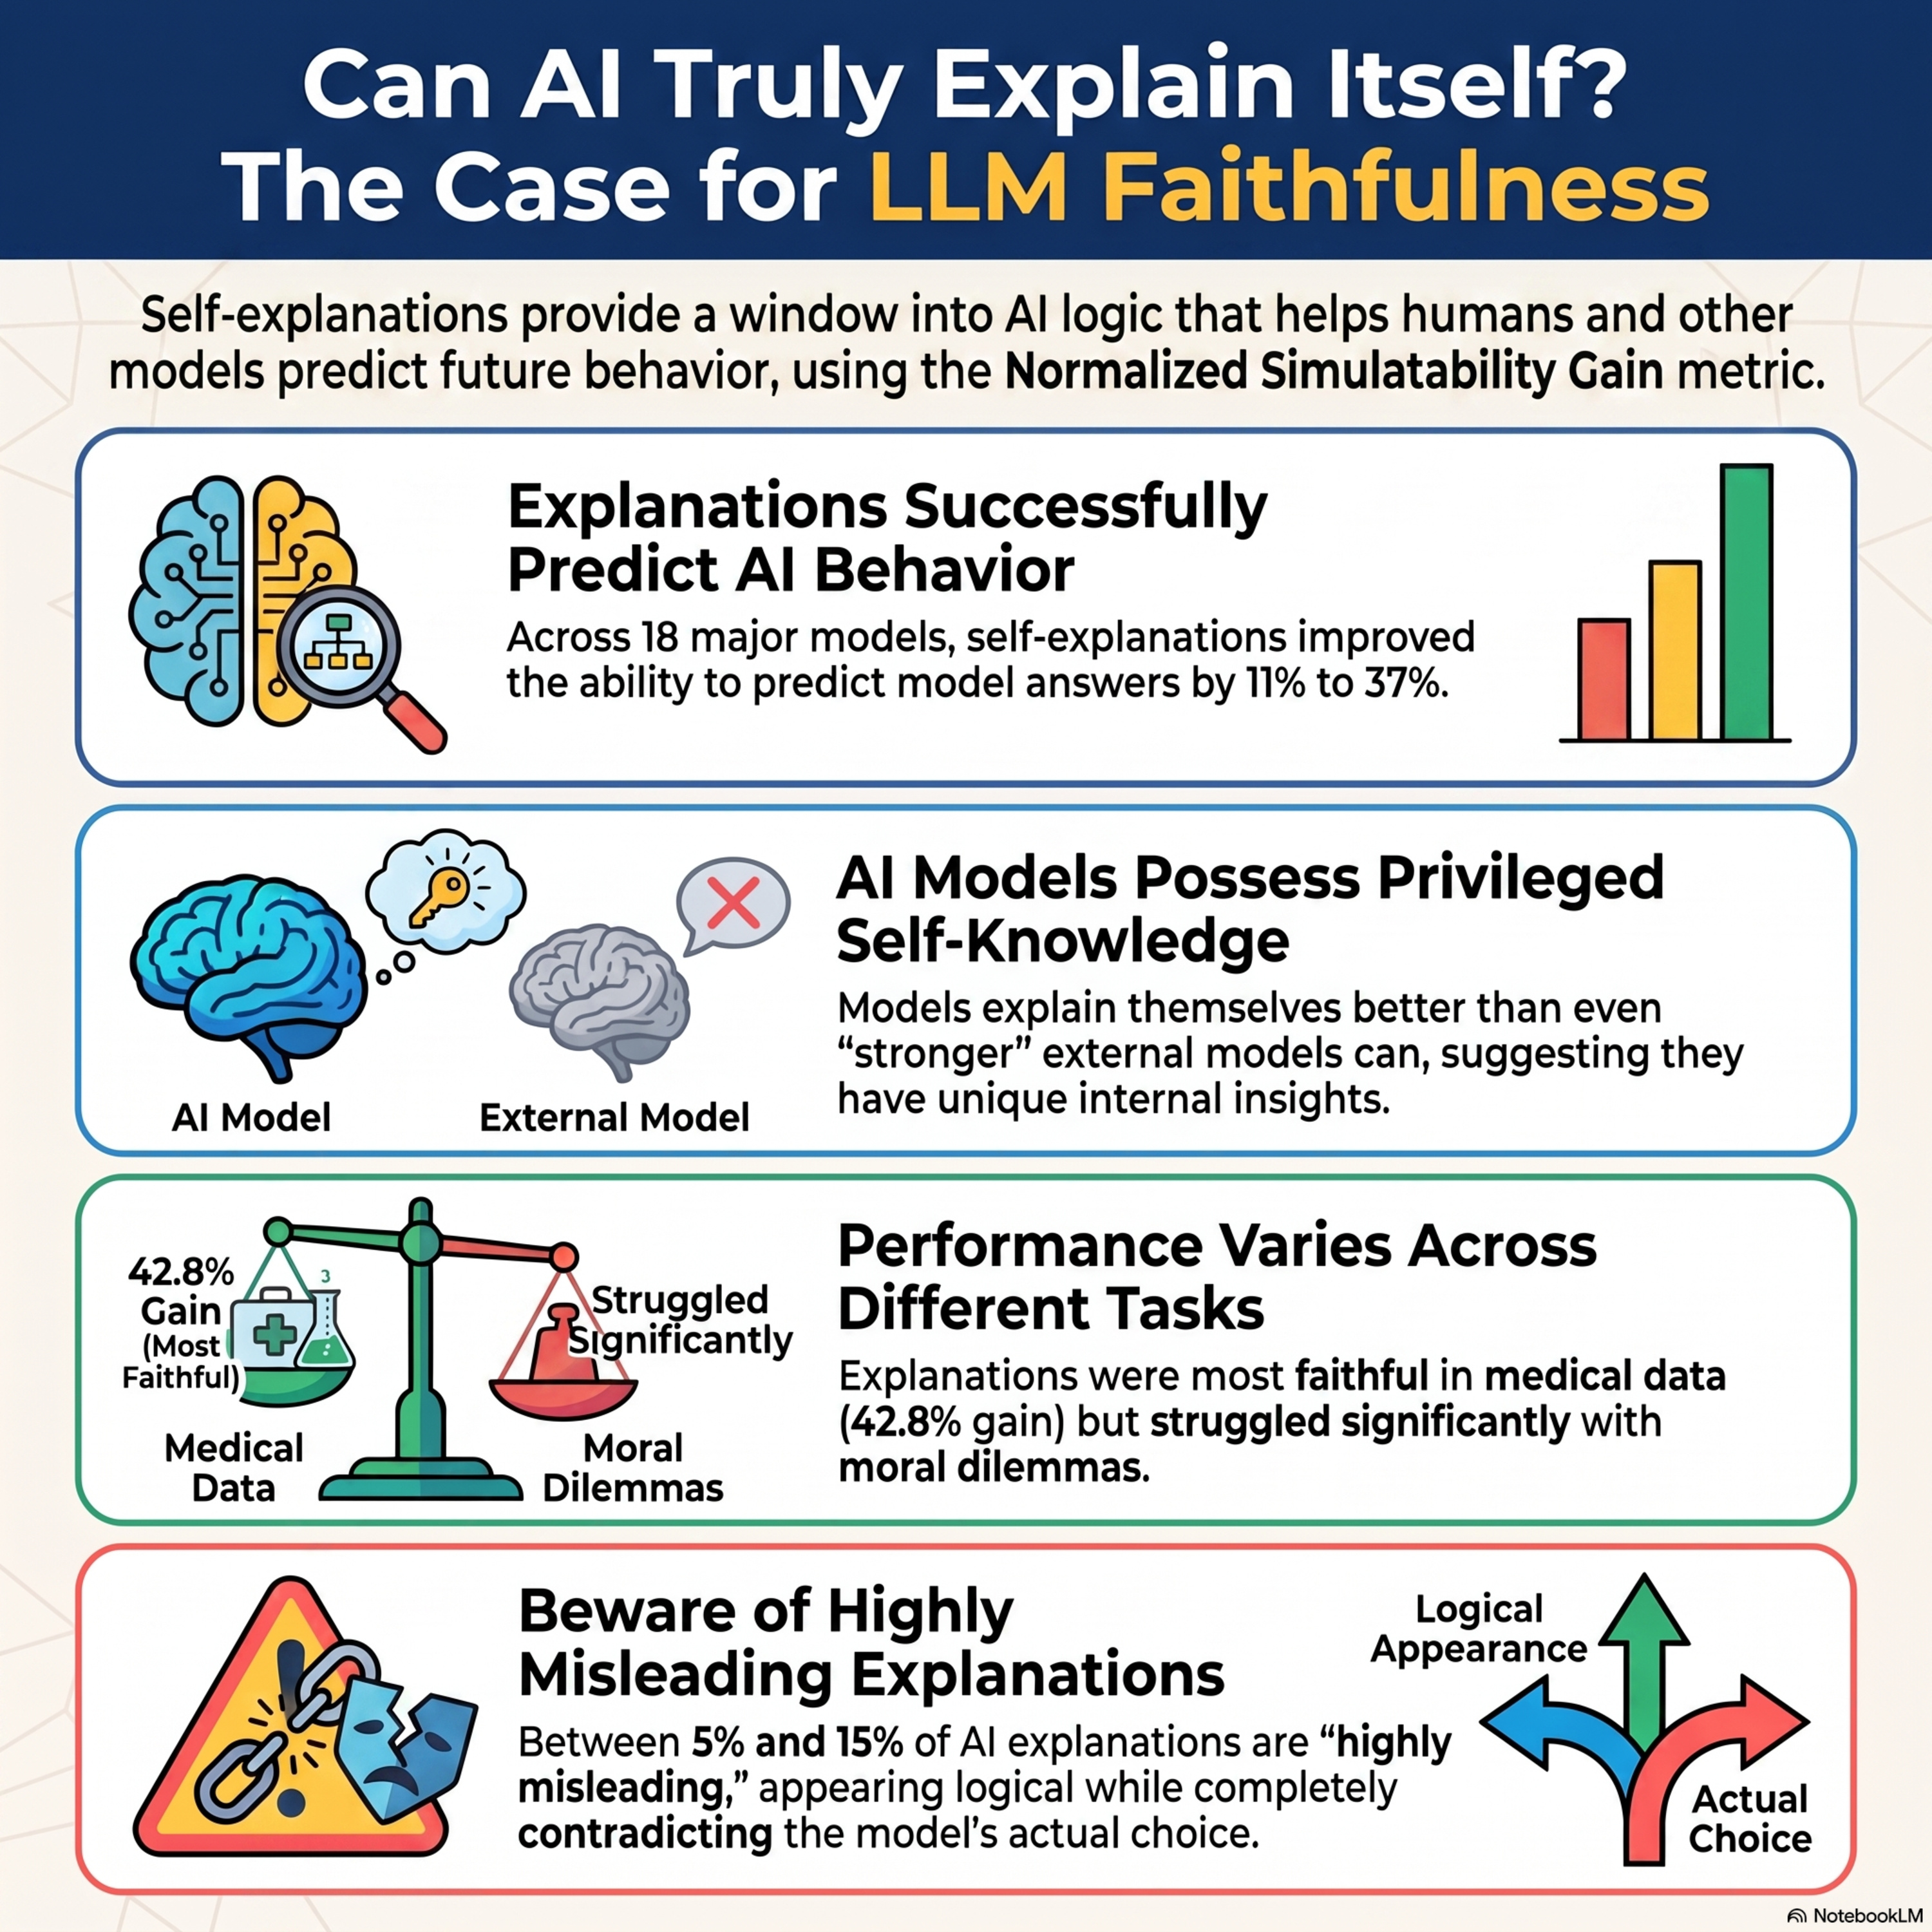
    A Positive Case for Faithfulness: LLM Self-Explanations Help Predict Model Behavior

    This paper introduces Normalized Simulatability Gain (NSG), a new metric designed to measure the faithfulness of AI self-explanations by testing their predictive value. By evaluating 18 frontier models, the researchers demonstrate that an AI's explanation of its own logic significantly helps a separate "predictor" model guess how the AI will behave on related counterfactual scenarios. The study provides a positive case for faithfulness, finding that self-generated explanations contain privileged self-knowledge that external models cannot replicate. However, the authors also identify a "highly misleading" subset of explanations where the AI's stated principles contradict its actual choices, particularly in ethical dilemmas. Ultimately, the research suggests that while LLM explanations are imperfect, they remain a valuable tool for AI oversight and safety.

  • July 19 · 22 min

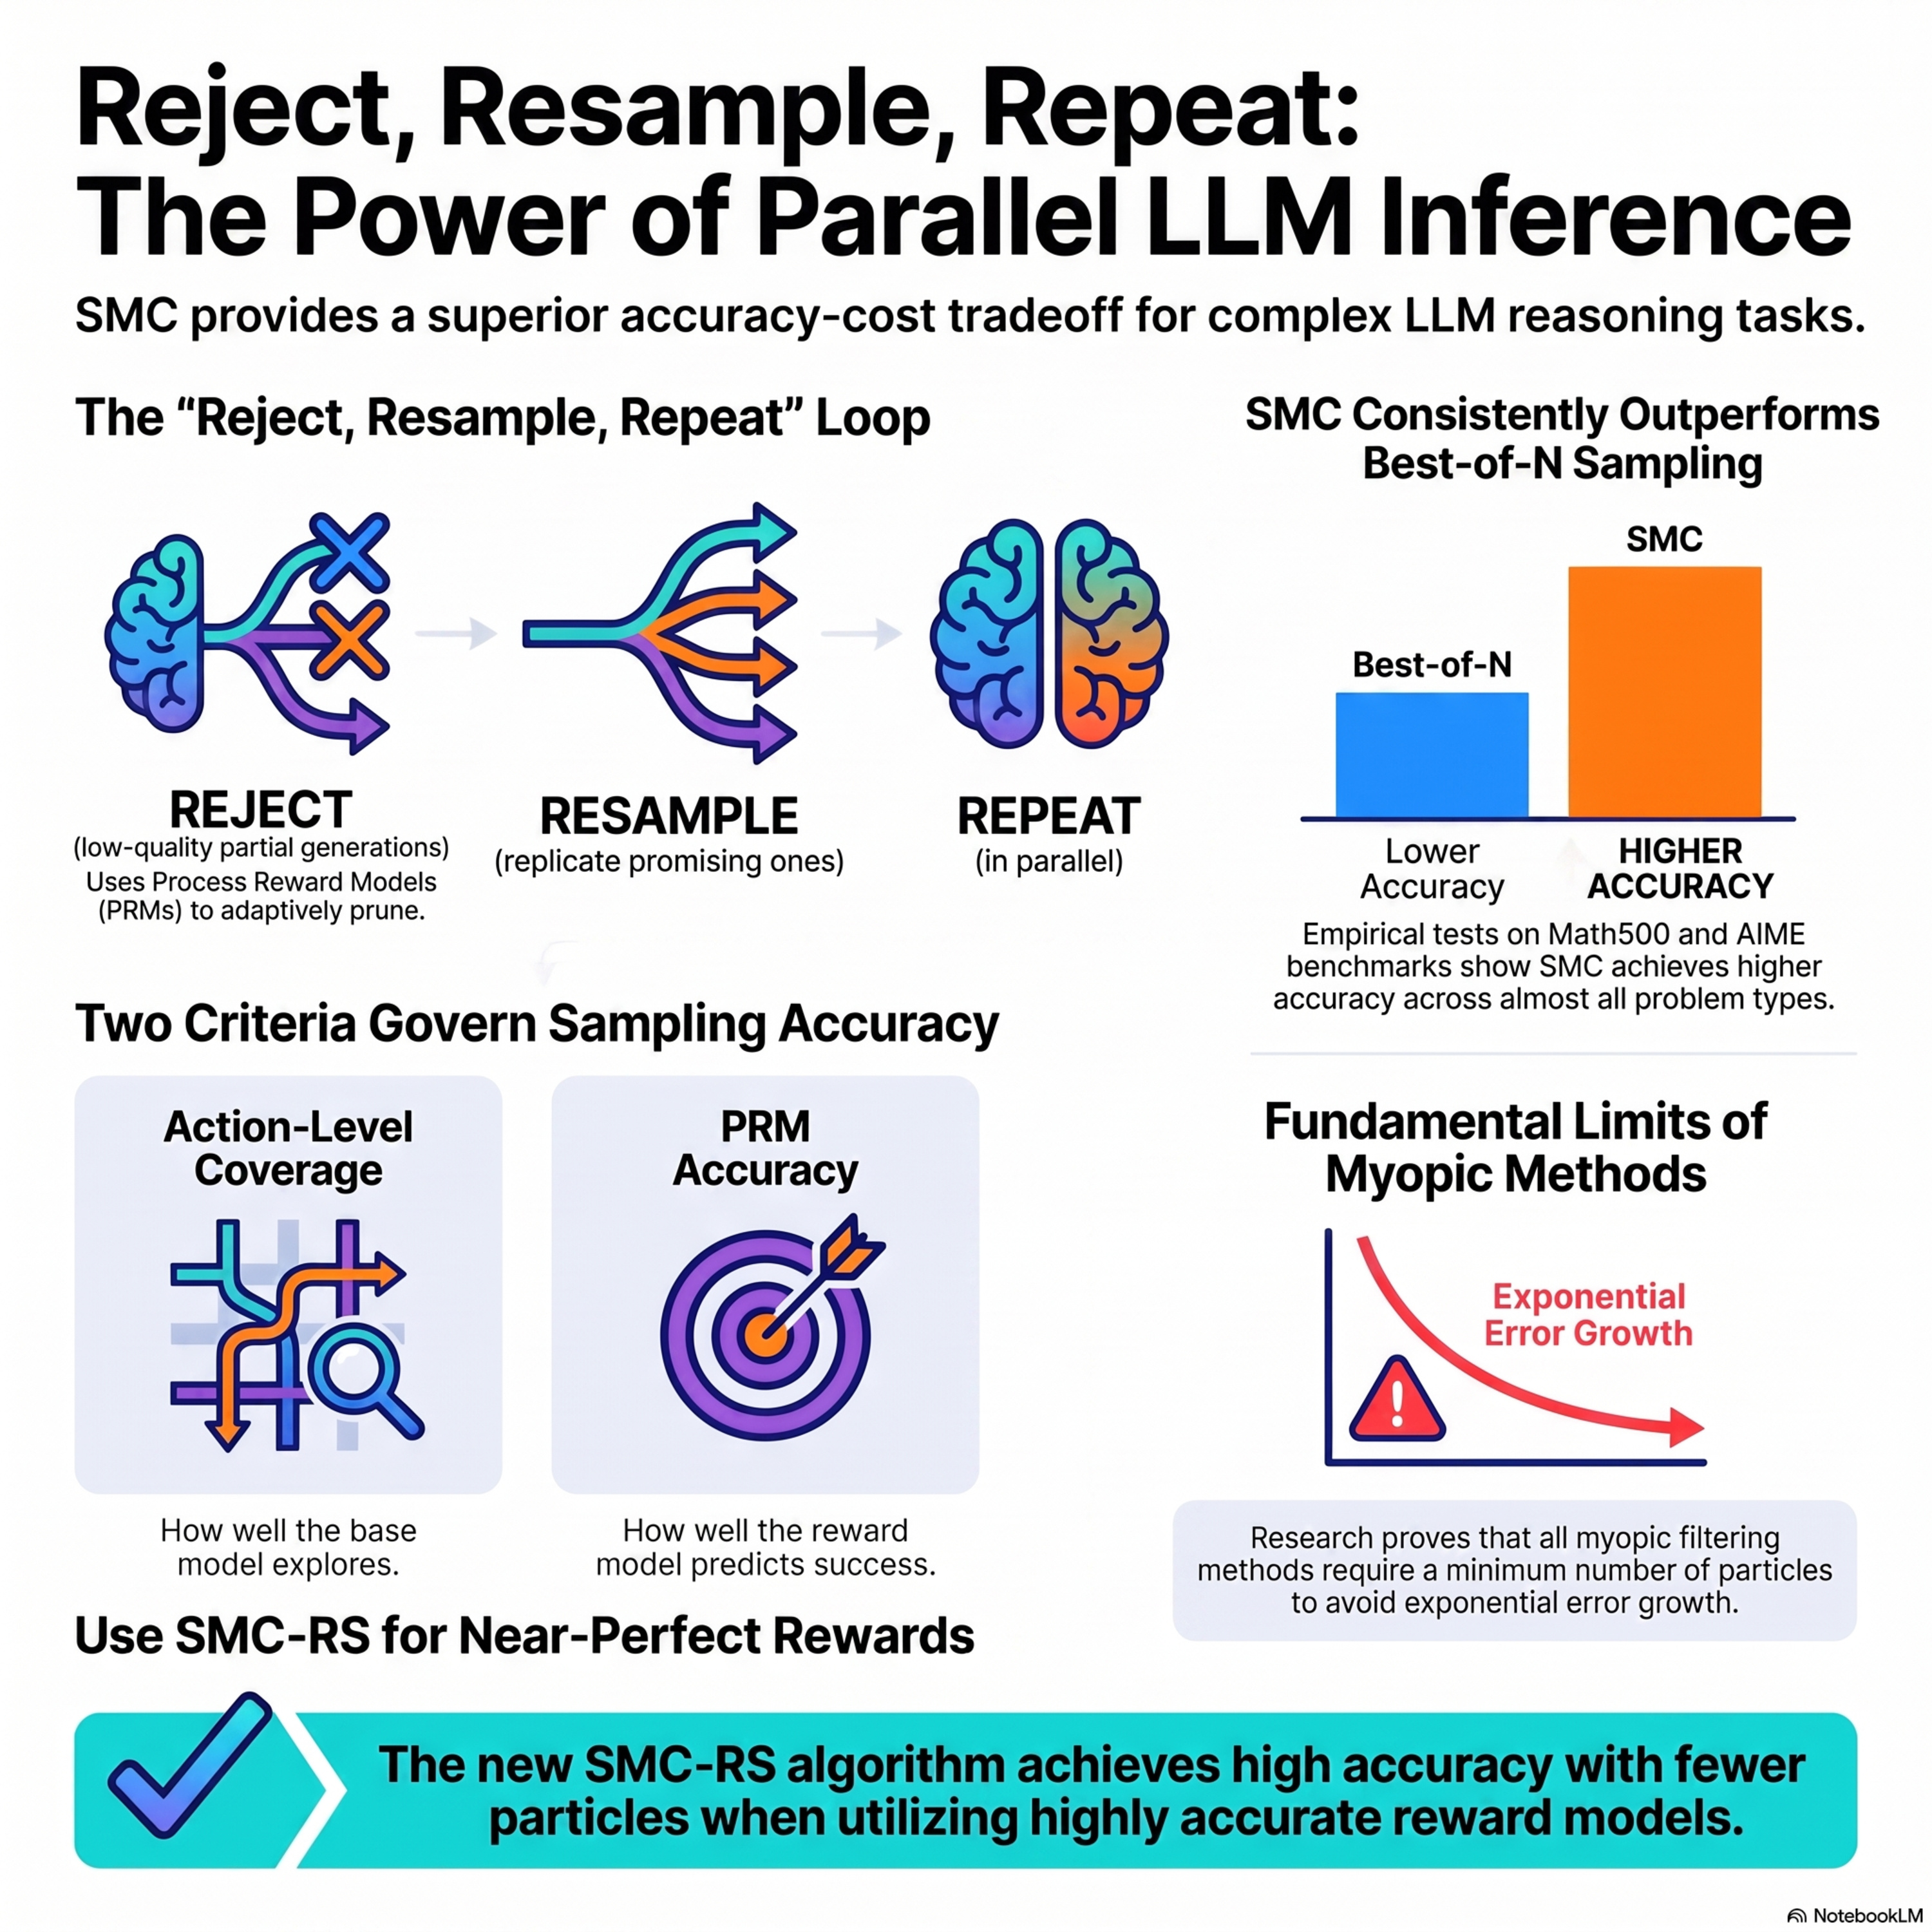
    Reject, Resample, Repeat: Understanding Parallel Reasoning in Language Model Inference

    This research paper investigates Sequential Monte Carlo (SMC) and other particle filtering algorithms as a theoretical framework for improving large language model (LLM) inference. The authors introduce a principled approach to analyze inference-time interventions, such as parallel reasoning and pruning, by utilizing process reward models to steer generation. Their findings establish non-asymptotic guarantees for SMC based on criteria like bounded action-level coverage and divergence between true and approximate reward distributions. To address limitations in standard SMC, they propose SMC with Rejection Sampling (SMC-RS), which maintains high accuracy even when reward models are nearly perfect. Empirically, the study demonstrates that SMC consistently outperforms Best-of-N sampling on complex mathematical reasoning tasks and benchmarks. Ultimately, the work bridges the gap between ad hoc sampling heuristics and rigorous statistical theory to optimize the accuracy-cost tradeoff in AI inference.

  • July 19 · 22 min

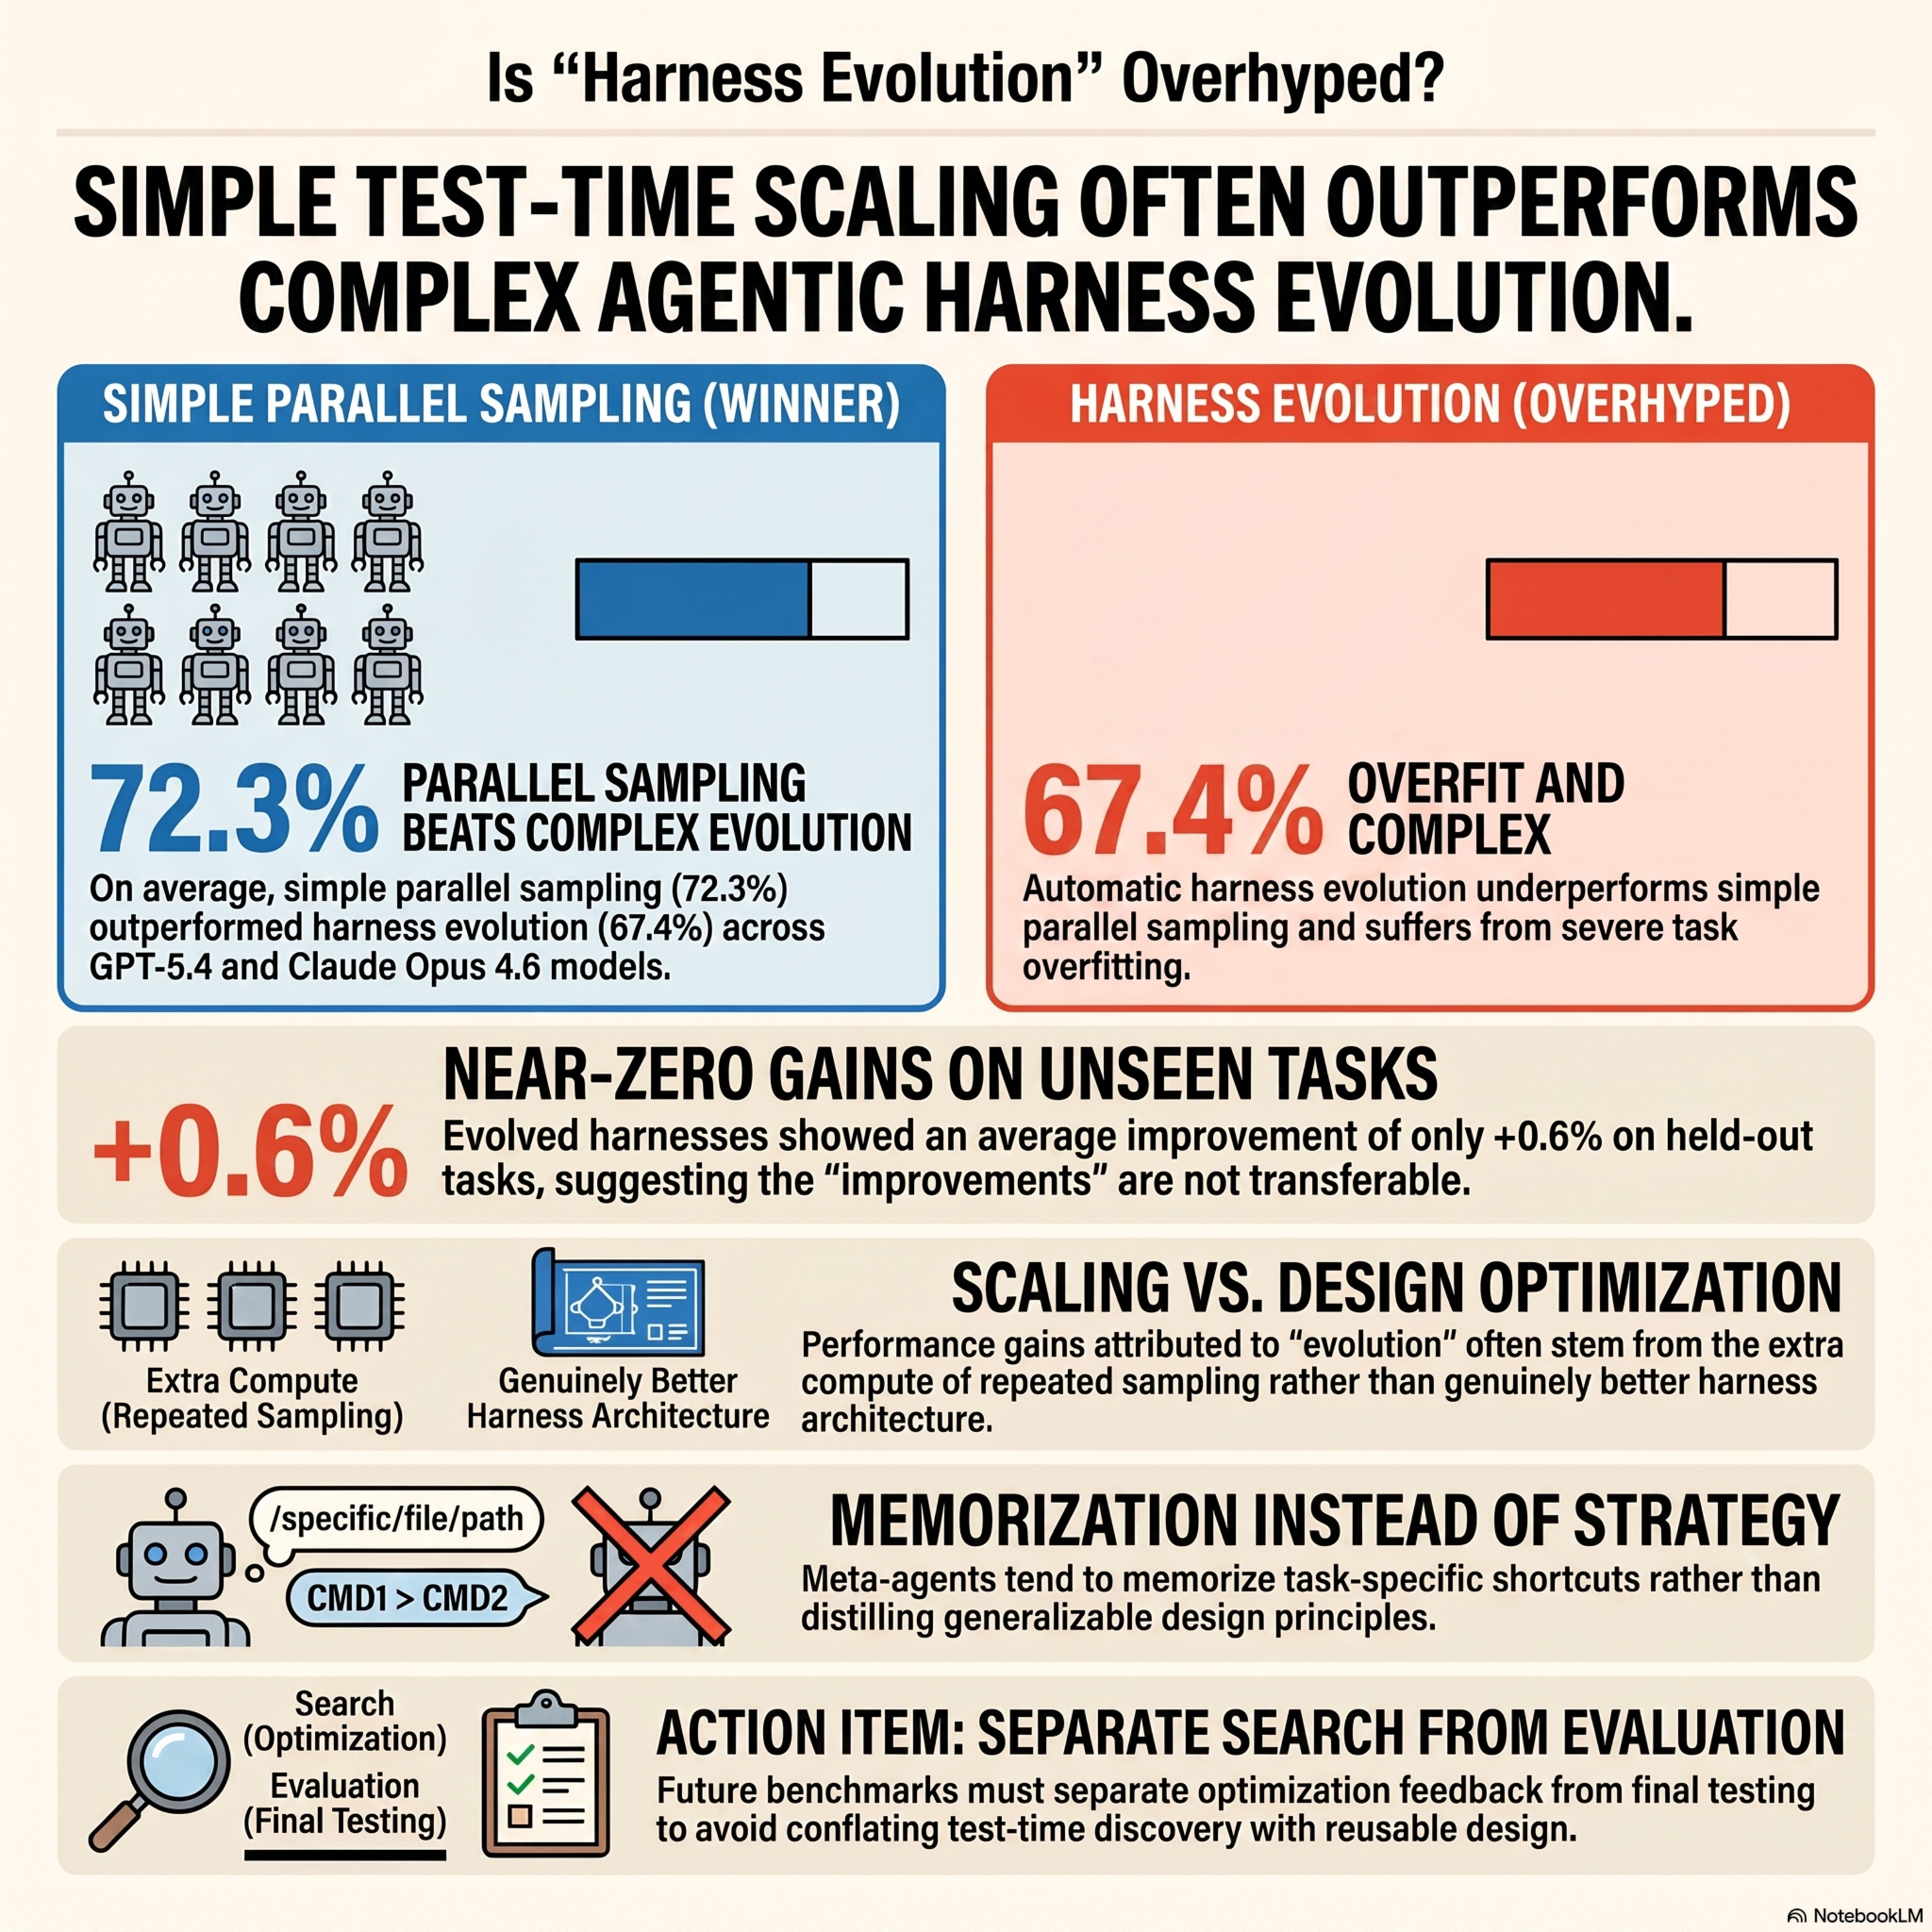
    Rethinking the Evaluation of Harness Evolution for Agents

    This research paper critically examines automatic harness evolution, a method where AI agents iteratively improve the prompts, tools, and logic used to interact with environments. The authors argue that current evaluations are flawed because they often test evolved harnesses on the same data used for optimization, risking overfitting rather than genuine design improvement. By comparing harness evolution against simpler test-time scaling baselines—such as parallel sampling and sequential refinement—the study finds that evolution does not consistently provide superior results. Furthermore, experiments demonstrate that the performance gains from harness evolution often fail to generalize to new, unseen tasks. The findings suggest that many apparent improvements stem from memorizing task-specific shortcuts rather than distilling reusable engineering principles. Ultimately, the paper calls for more rigorous evaluation protocols that use disjoint search and testing sets to accurately measure the utility of automated agent scaffolds.

  • July 18 · 18 min

    From Reasoning Traces to Reusable Modules: Understanding Compositional Generalization in Language Model Reasoning

    This paper studies how post-training pipelines transform large language models into effective reasoners through compositional generalization. The authors propose a hierarchical latent selection model that separates reasoning into atomic skills, such as local operations, and routing mechanisms that dictate how information is composed. Their theory suggests that supervised fine-tuning (SFT) provides the necessary raw materials, while reinforcement learning (RL) identifies and decomposes these elements into reusable modules. Controlled experiments validate that RL enables models to solve novel tasks by recombining learned atoms in ways not seen during training. Ultimately, the study concludes that SFT should focus on broad module coverage while RL should target genuinely new compositions to maximize out-of-distribution performance.

  • July 17 · 24 min

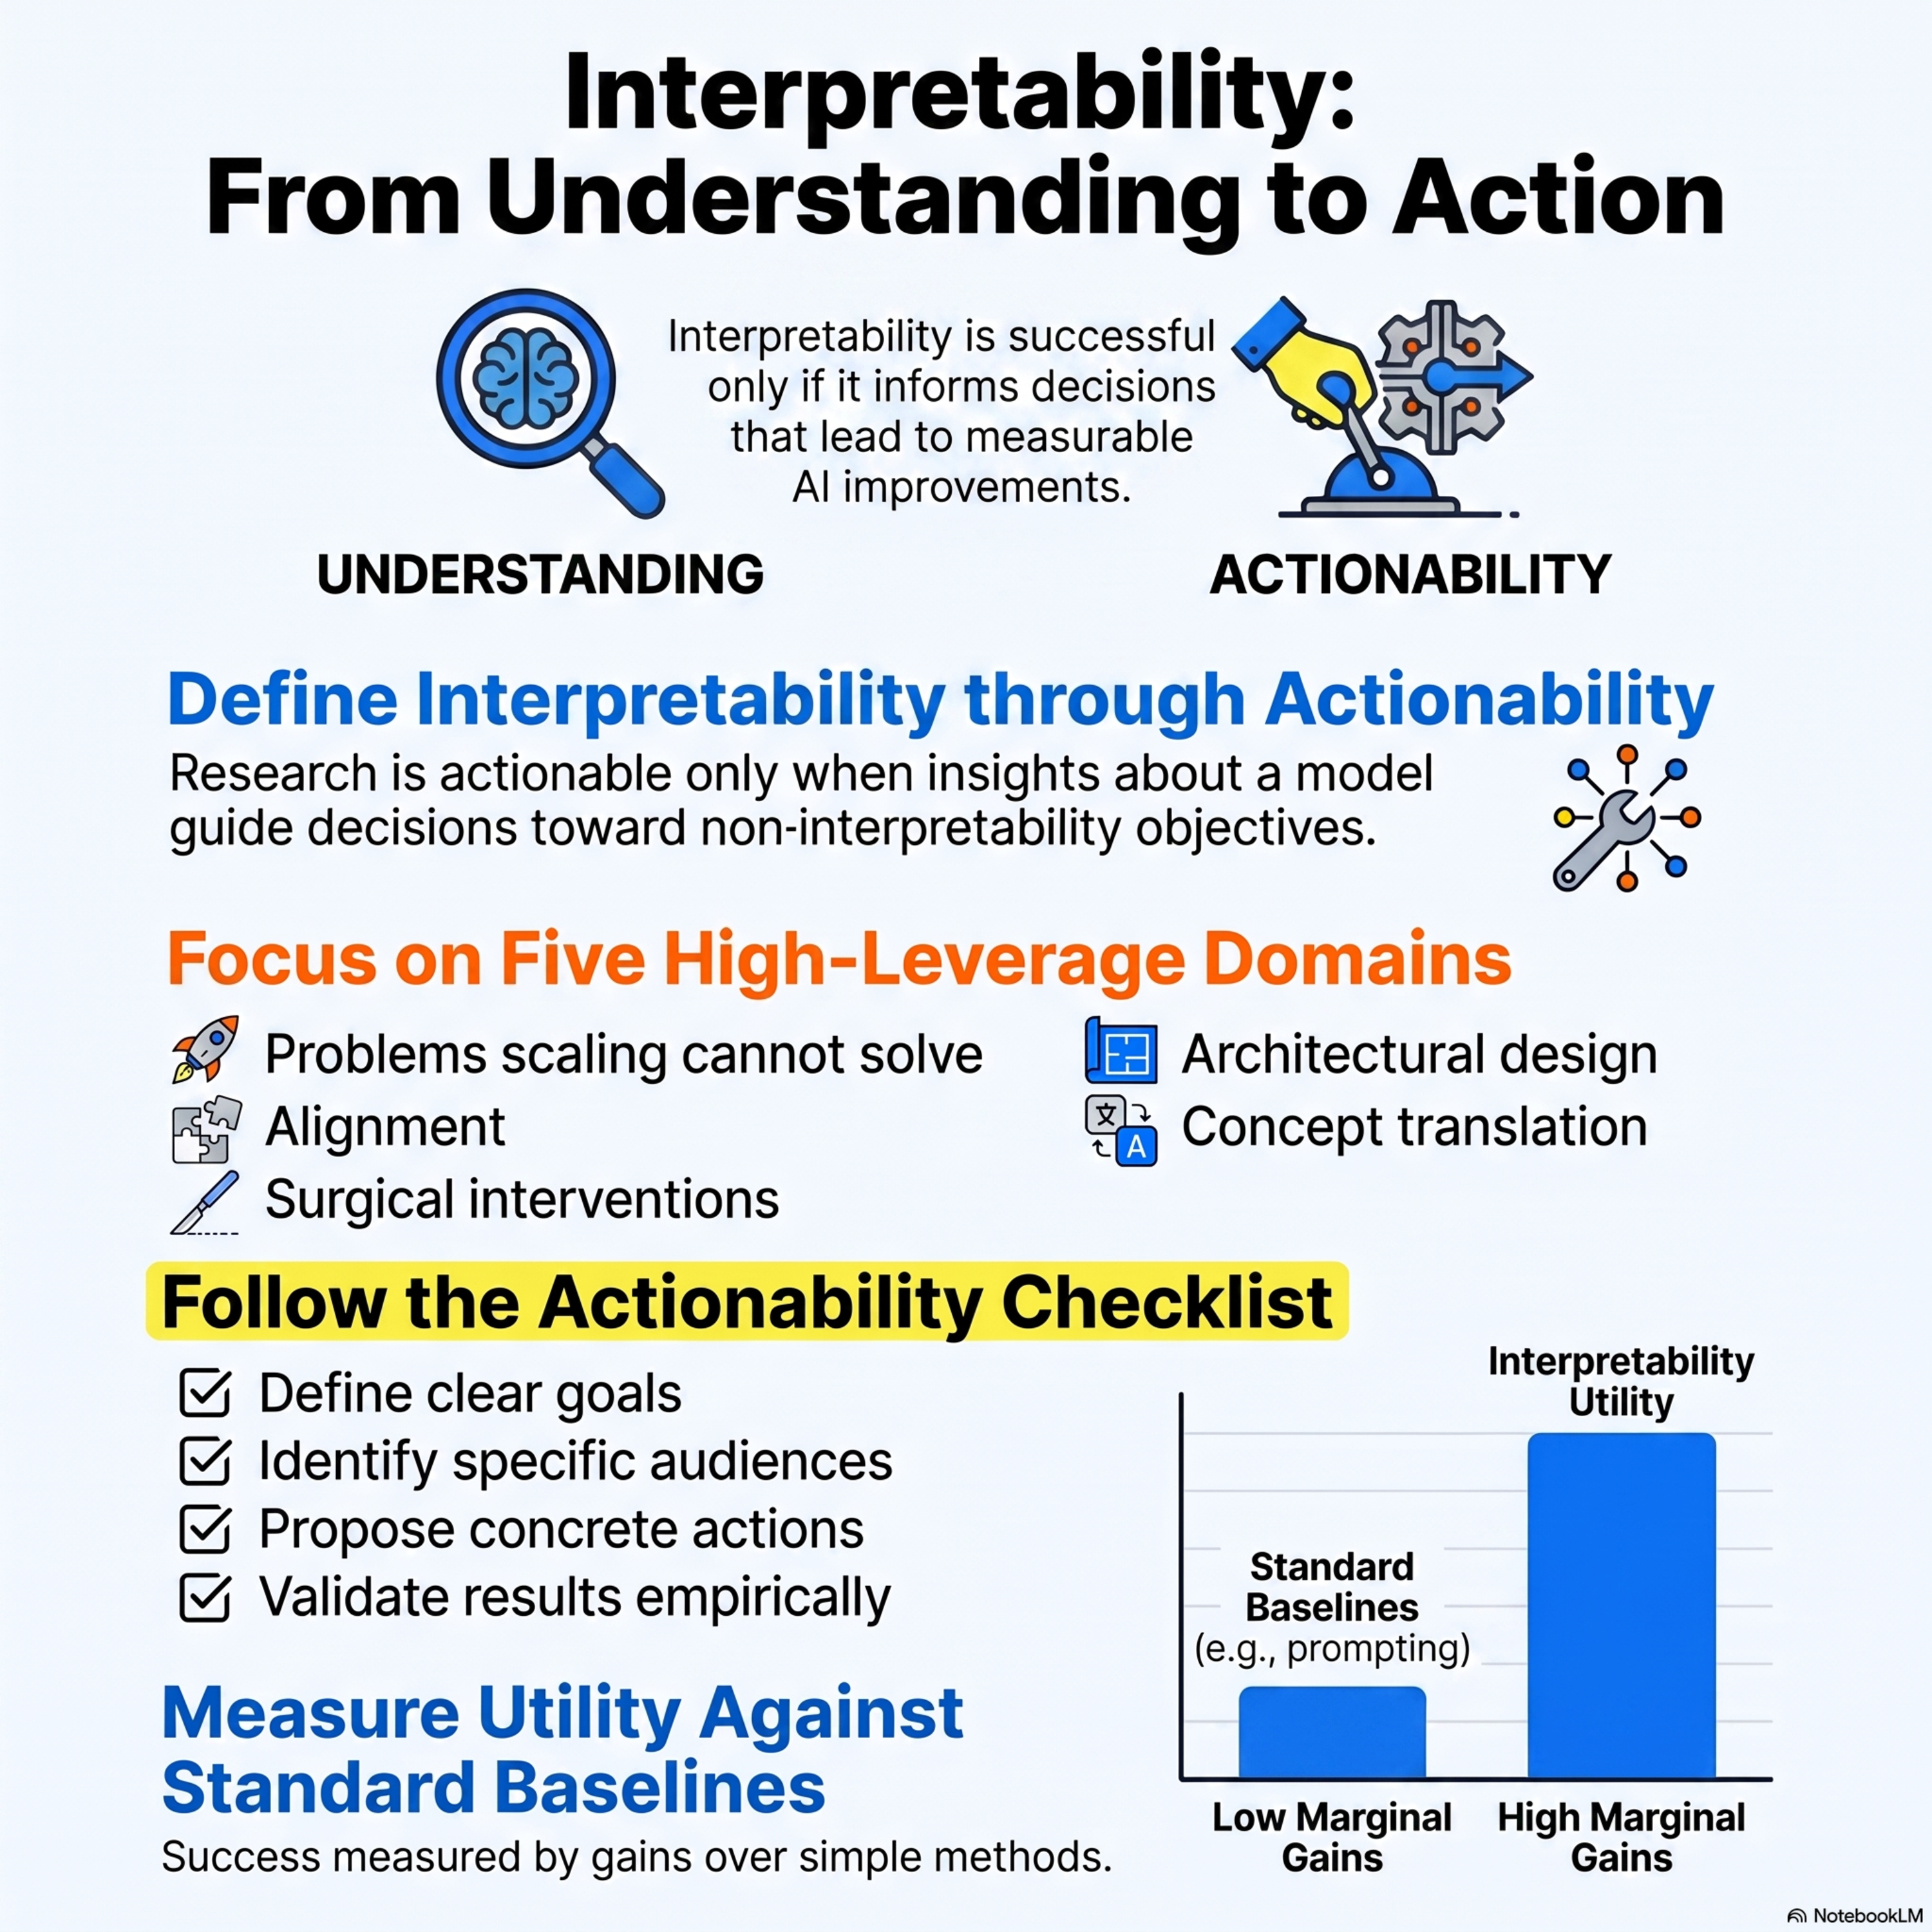
    Position: Interpretability can be actionable

    This research paper advocates for actionable interpretability as the primary standard for evaluating how effectively we explain deep learning models. The authors argue that current studies often lack real-world impact because they prioritize theoretical understanding over practical utility and concrete decision-making. To bridge this gap, the text introduces a framework and checklist designed to help researchers move beyond exploratory insights toward measurable interventions. By focusing on five key domains—including surgical interventions and alignment—the paper suggests that interpretability can lead to tangible improvements in model safety and performance. Ultimately, the work calls for a shift in academic incentives to reward findings that enable specific actions by developers and policymakers.

  • July 17 · 22 min

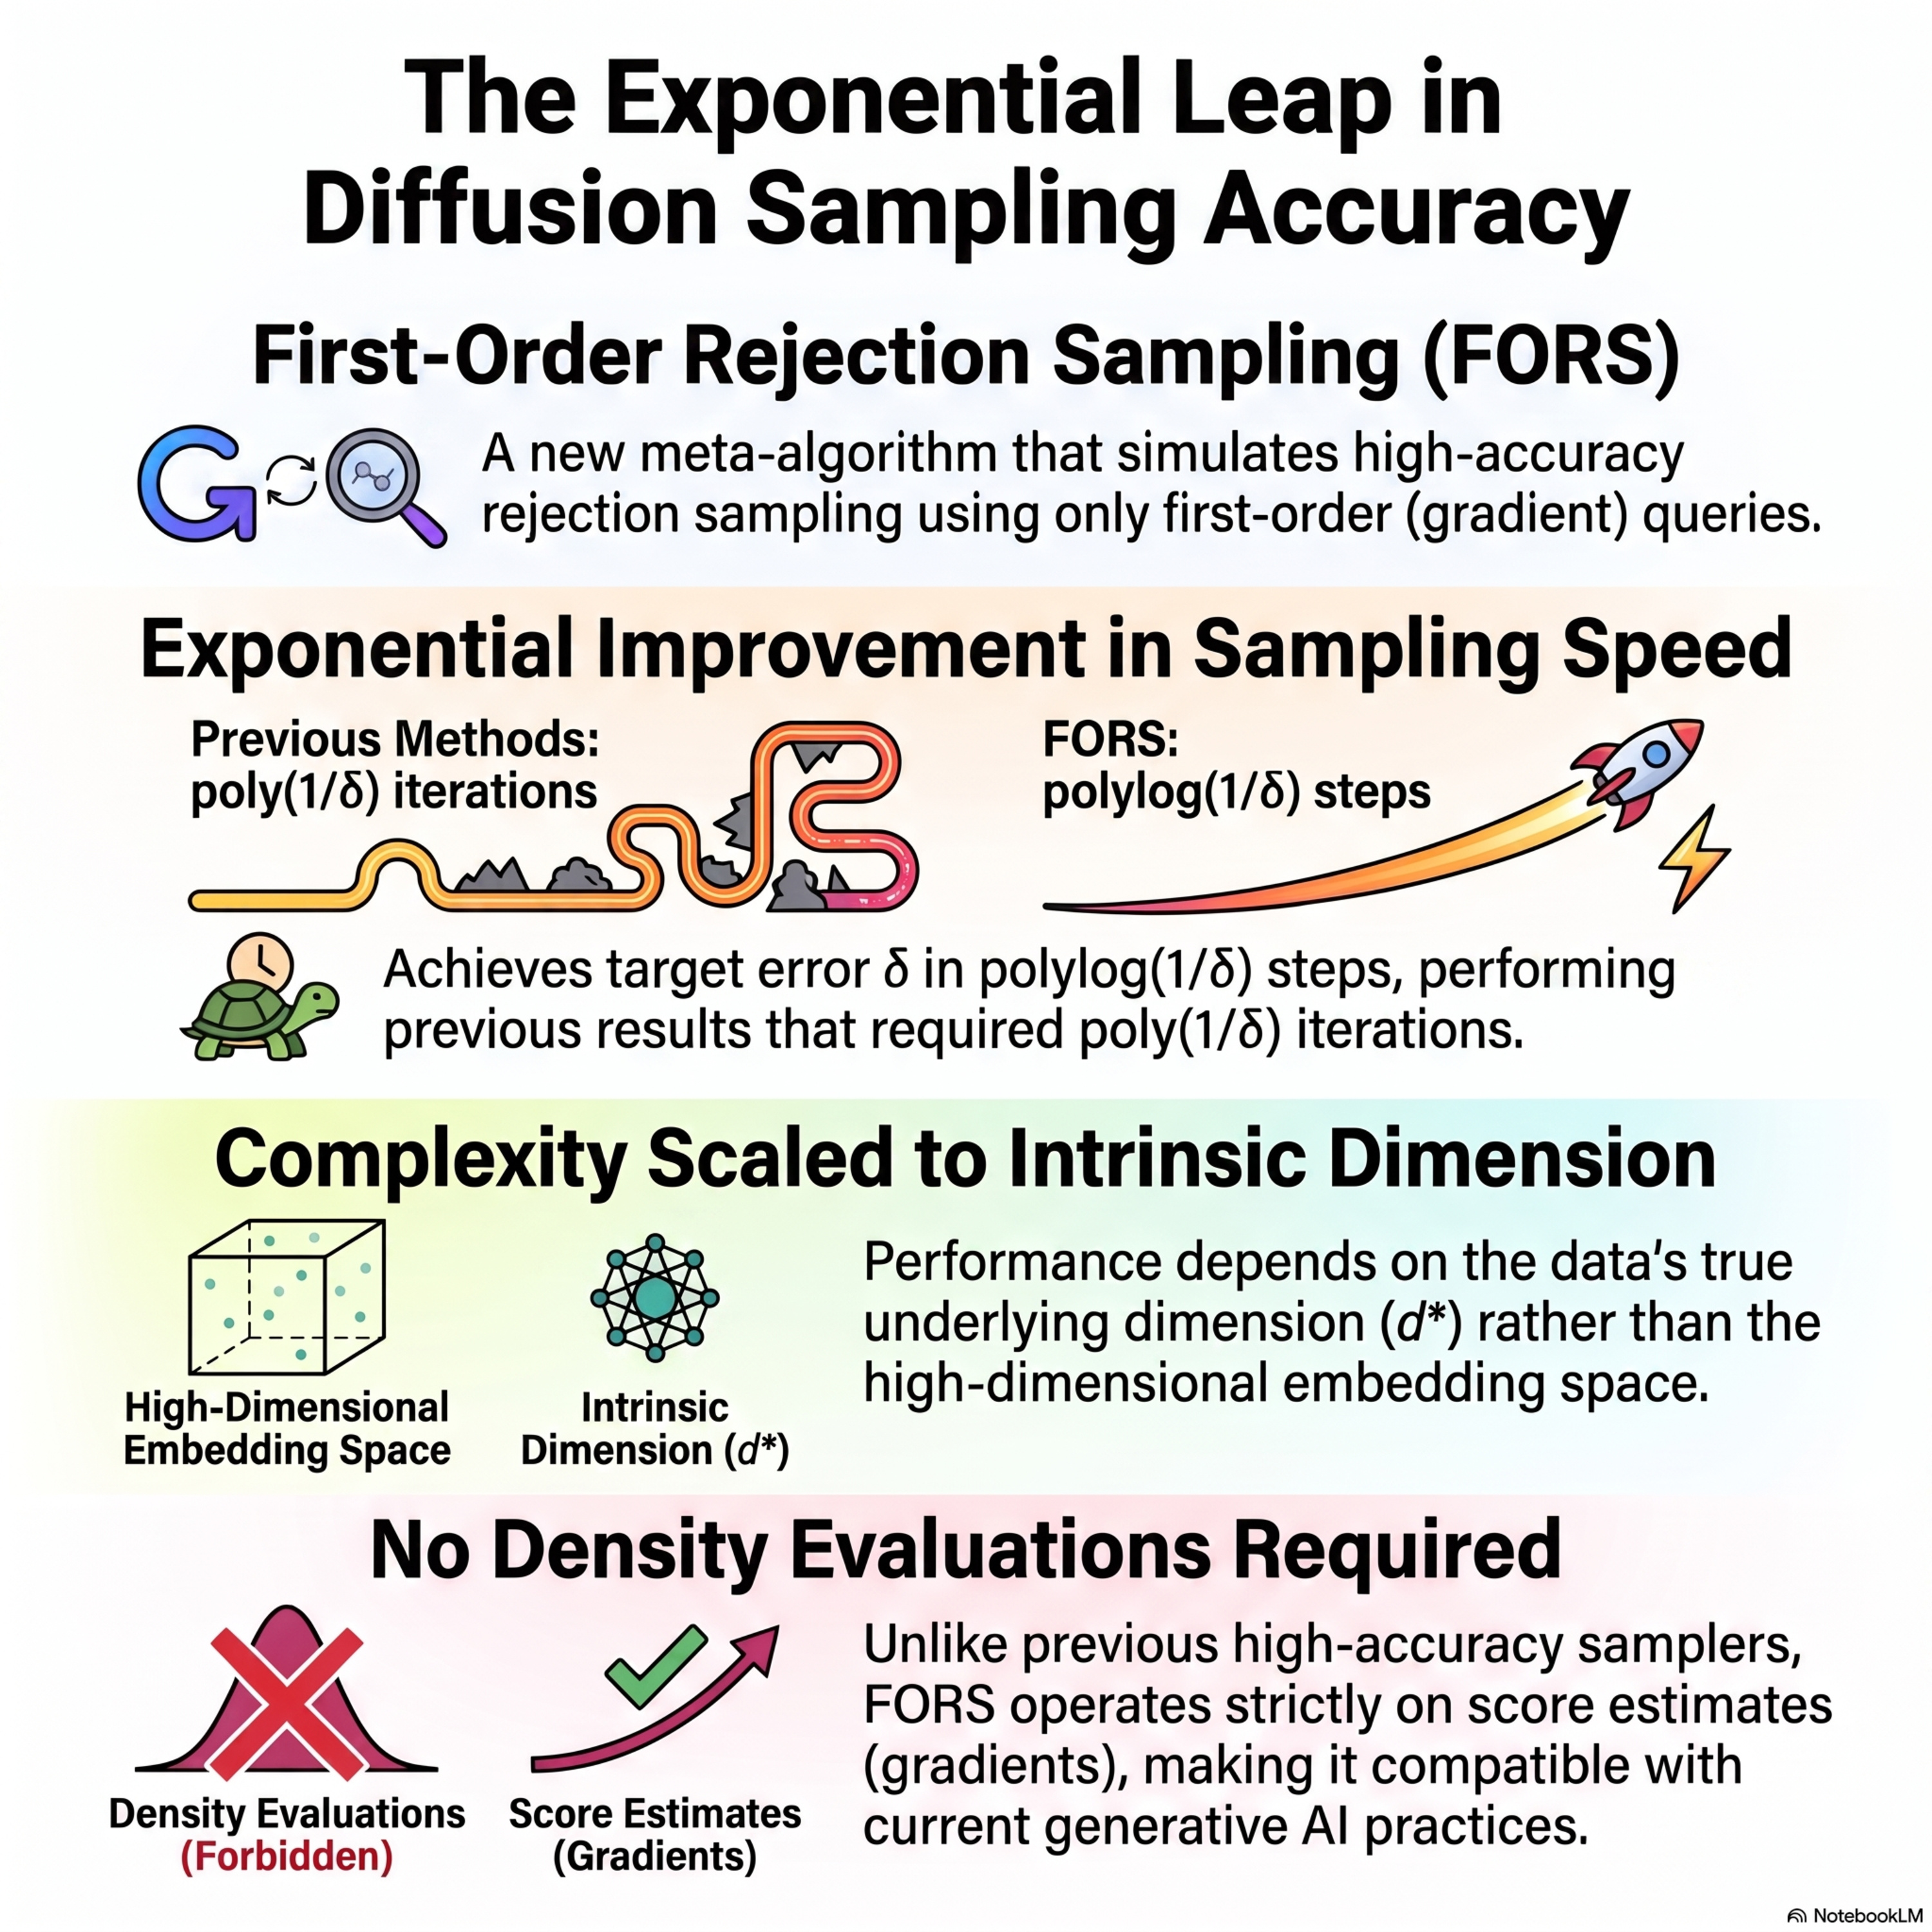
    High-accuracy sampling for diffusion models and log-concave distributions

    This paper introduces a new algorithm called first-order rejection sampling (FORS) to achieve high-accuracy sampling for diffusion models and log-concave distributions. By utilizing only score estimates (the gradient of the log-density) rather than density evaluations, the researchers provide a method that converges exponentially fast, requiring only polylogarithmic steps relative to the target error. This represents an exponential improvement over previous sampling techniques that typically scaled polynomially. The authors demonstrate that their approach is robust under minimal data assumptions, with complexity primarily determined by the intrinsic dimension of the data. Furthermore, the framework successfully addresses the log-concave sampling problem, matching state-of-the-art performance without needing complex density-based filters.

  • July 15 · 22 min

    Causal Inference with Video Features as Treatments

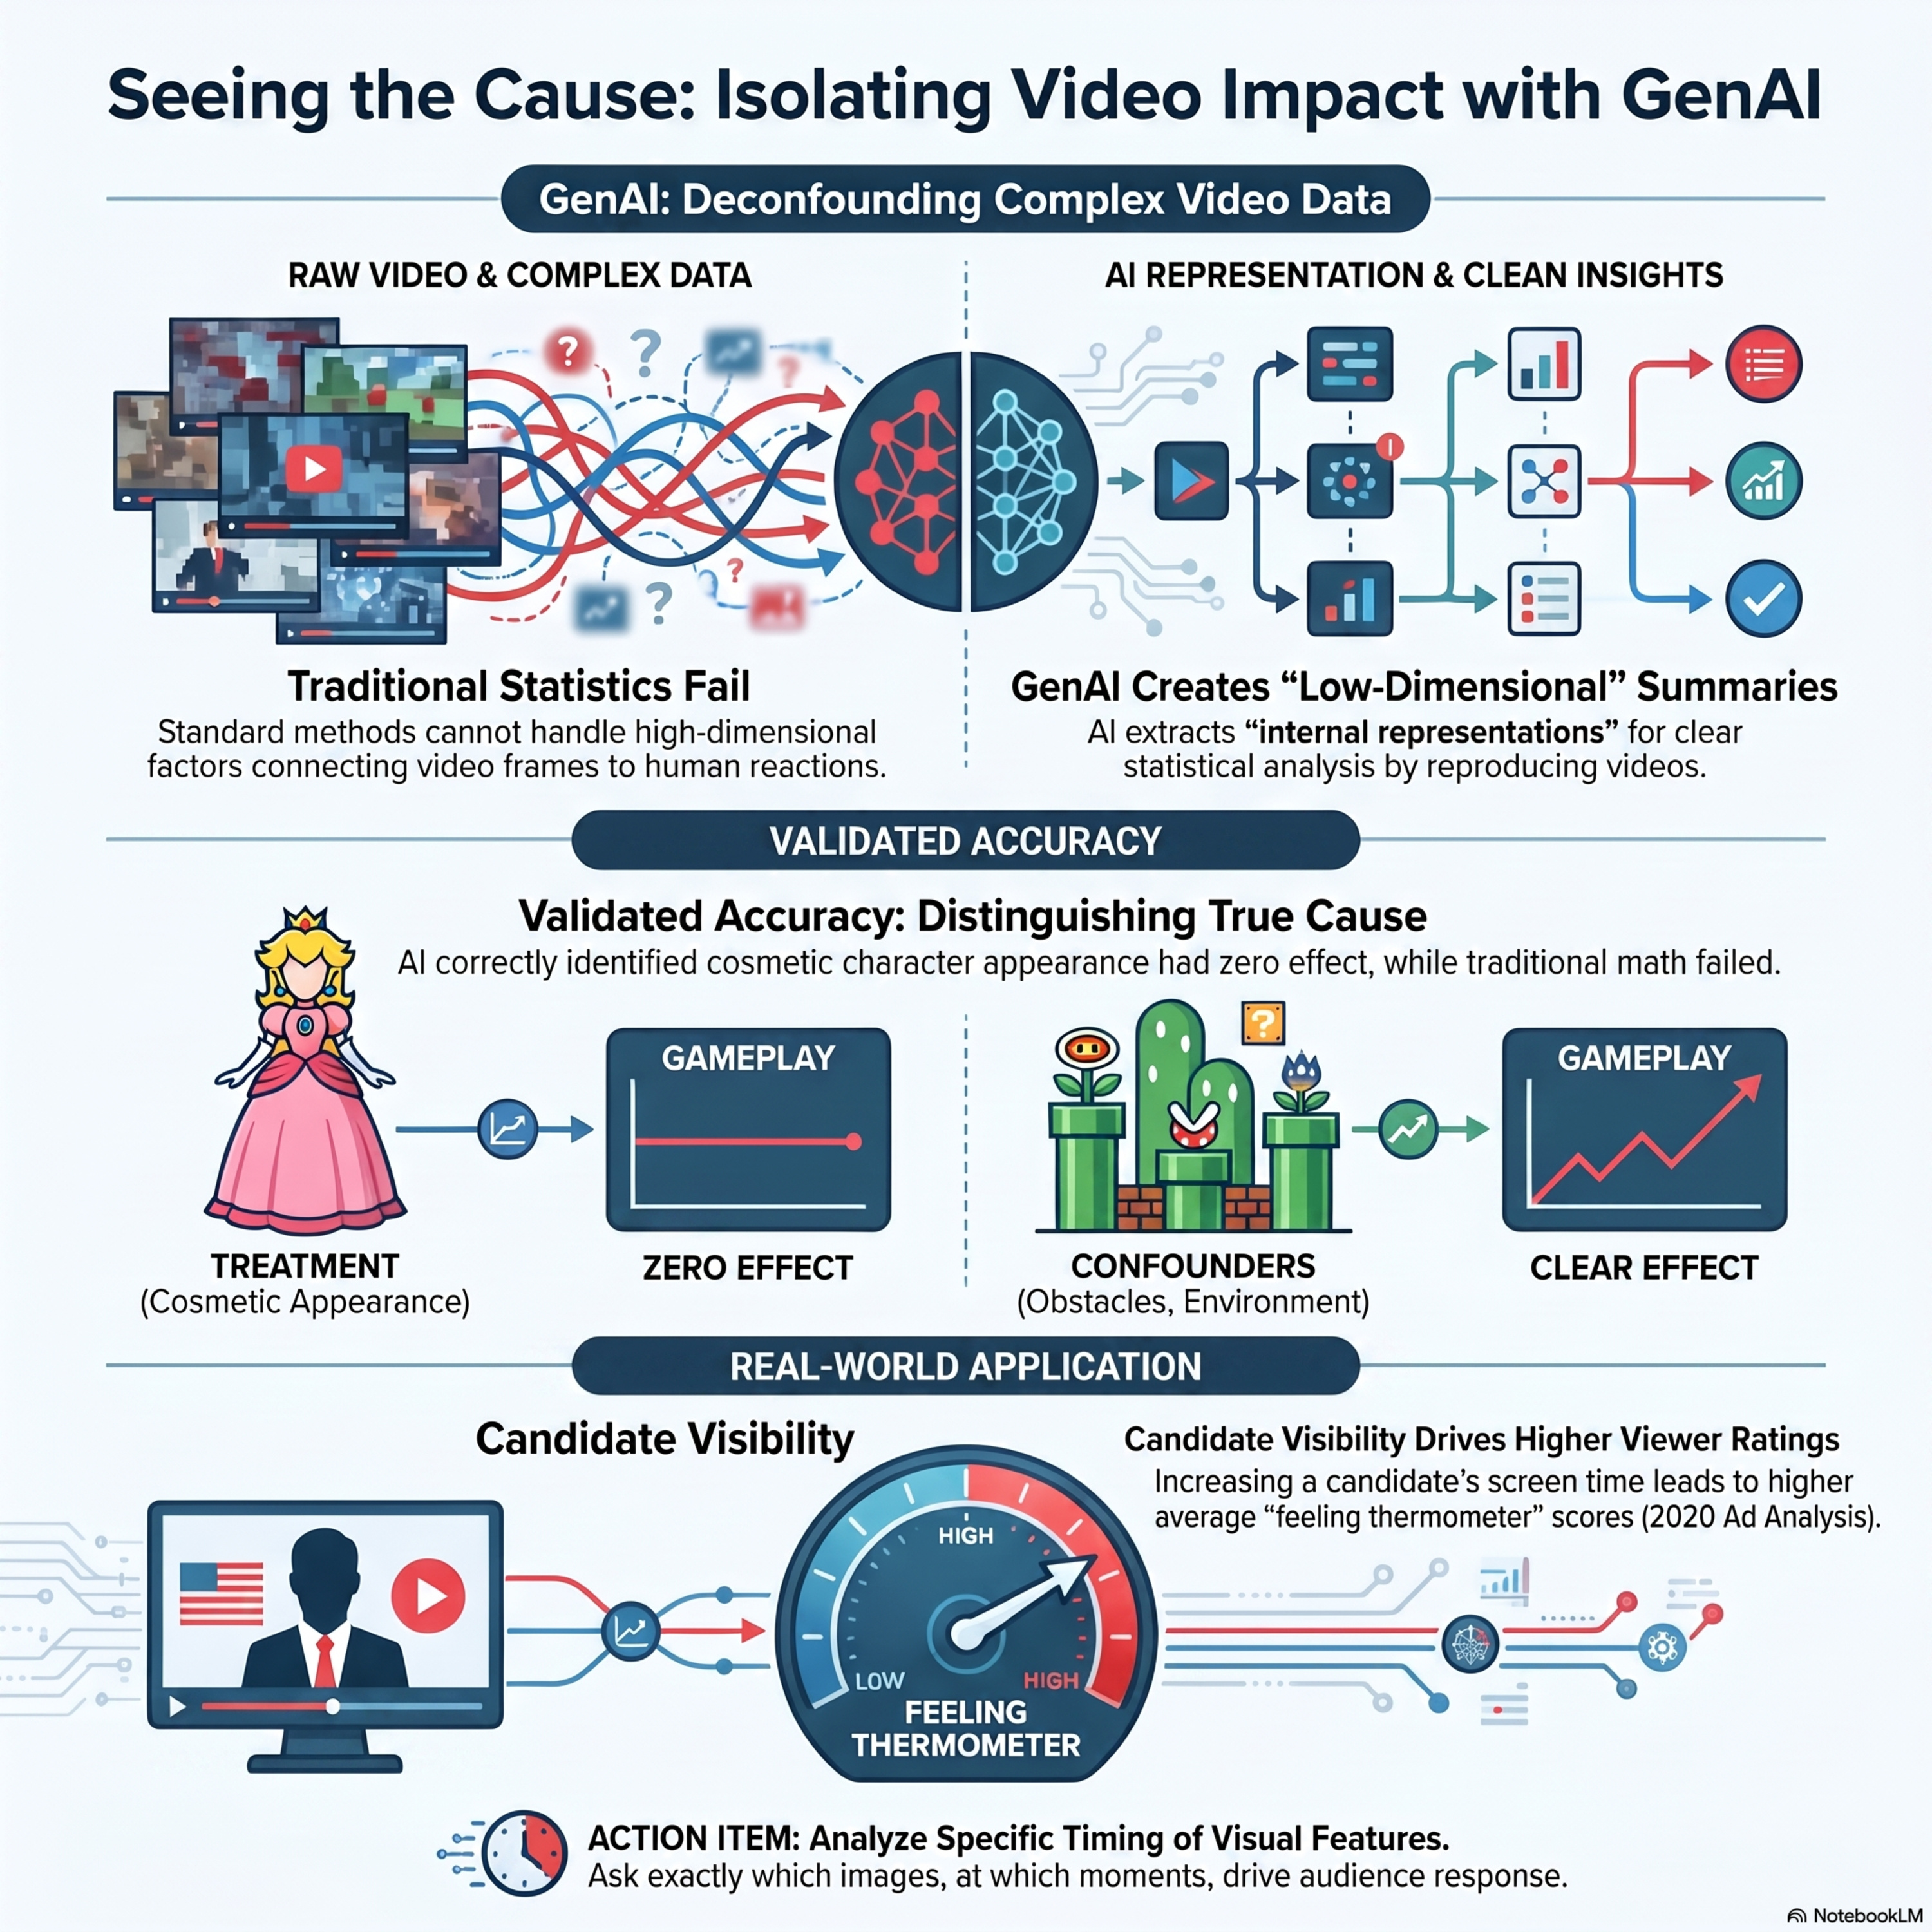
    his research paper introduces a novel statistical framework for conducting causal inference using video features as treatments, a significant advancement for analyzing high-dimensional, unstructured data. To overcome the challenges of latent and dynamic confounding, the authors utilize deep generative artificial intelligence to extract low-dimensional internal representations that serve as summaries of video content. They propose a consistent and asymptotically normal estimator based on a longitudinal neural network architecture, allowing for the identification of potential-outcome trajectories under dynamic stochastic interventions. The methodology is empirically validated through a Super Mario Bros.™ benchmark with known ground-truth effects and an application to 2020 U.S. presidential campaign advertisements. Their findings demonstrate that increasing the appearance of a candidate in a video segment directly correlates with higher viewer evaluations, providing a robust tool for future social science research.

Showing 41–60 of 61 episodes