Skip to content
Artwork for Best AI papers explained

Best AI papers explained

Enoch H. Kang

Cut through the noise. We curate and break down the most important AI papers so you don’t have to.

Play
  • 61 episodes
  • Avg 21 min
  • English
Counted on this page — what you have heard stays on this device, so it is not something the list can be paged by.
  • Today · 20 min

    Hybrid Reasoning Agents

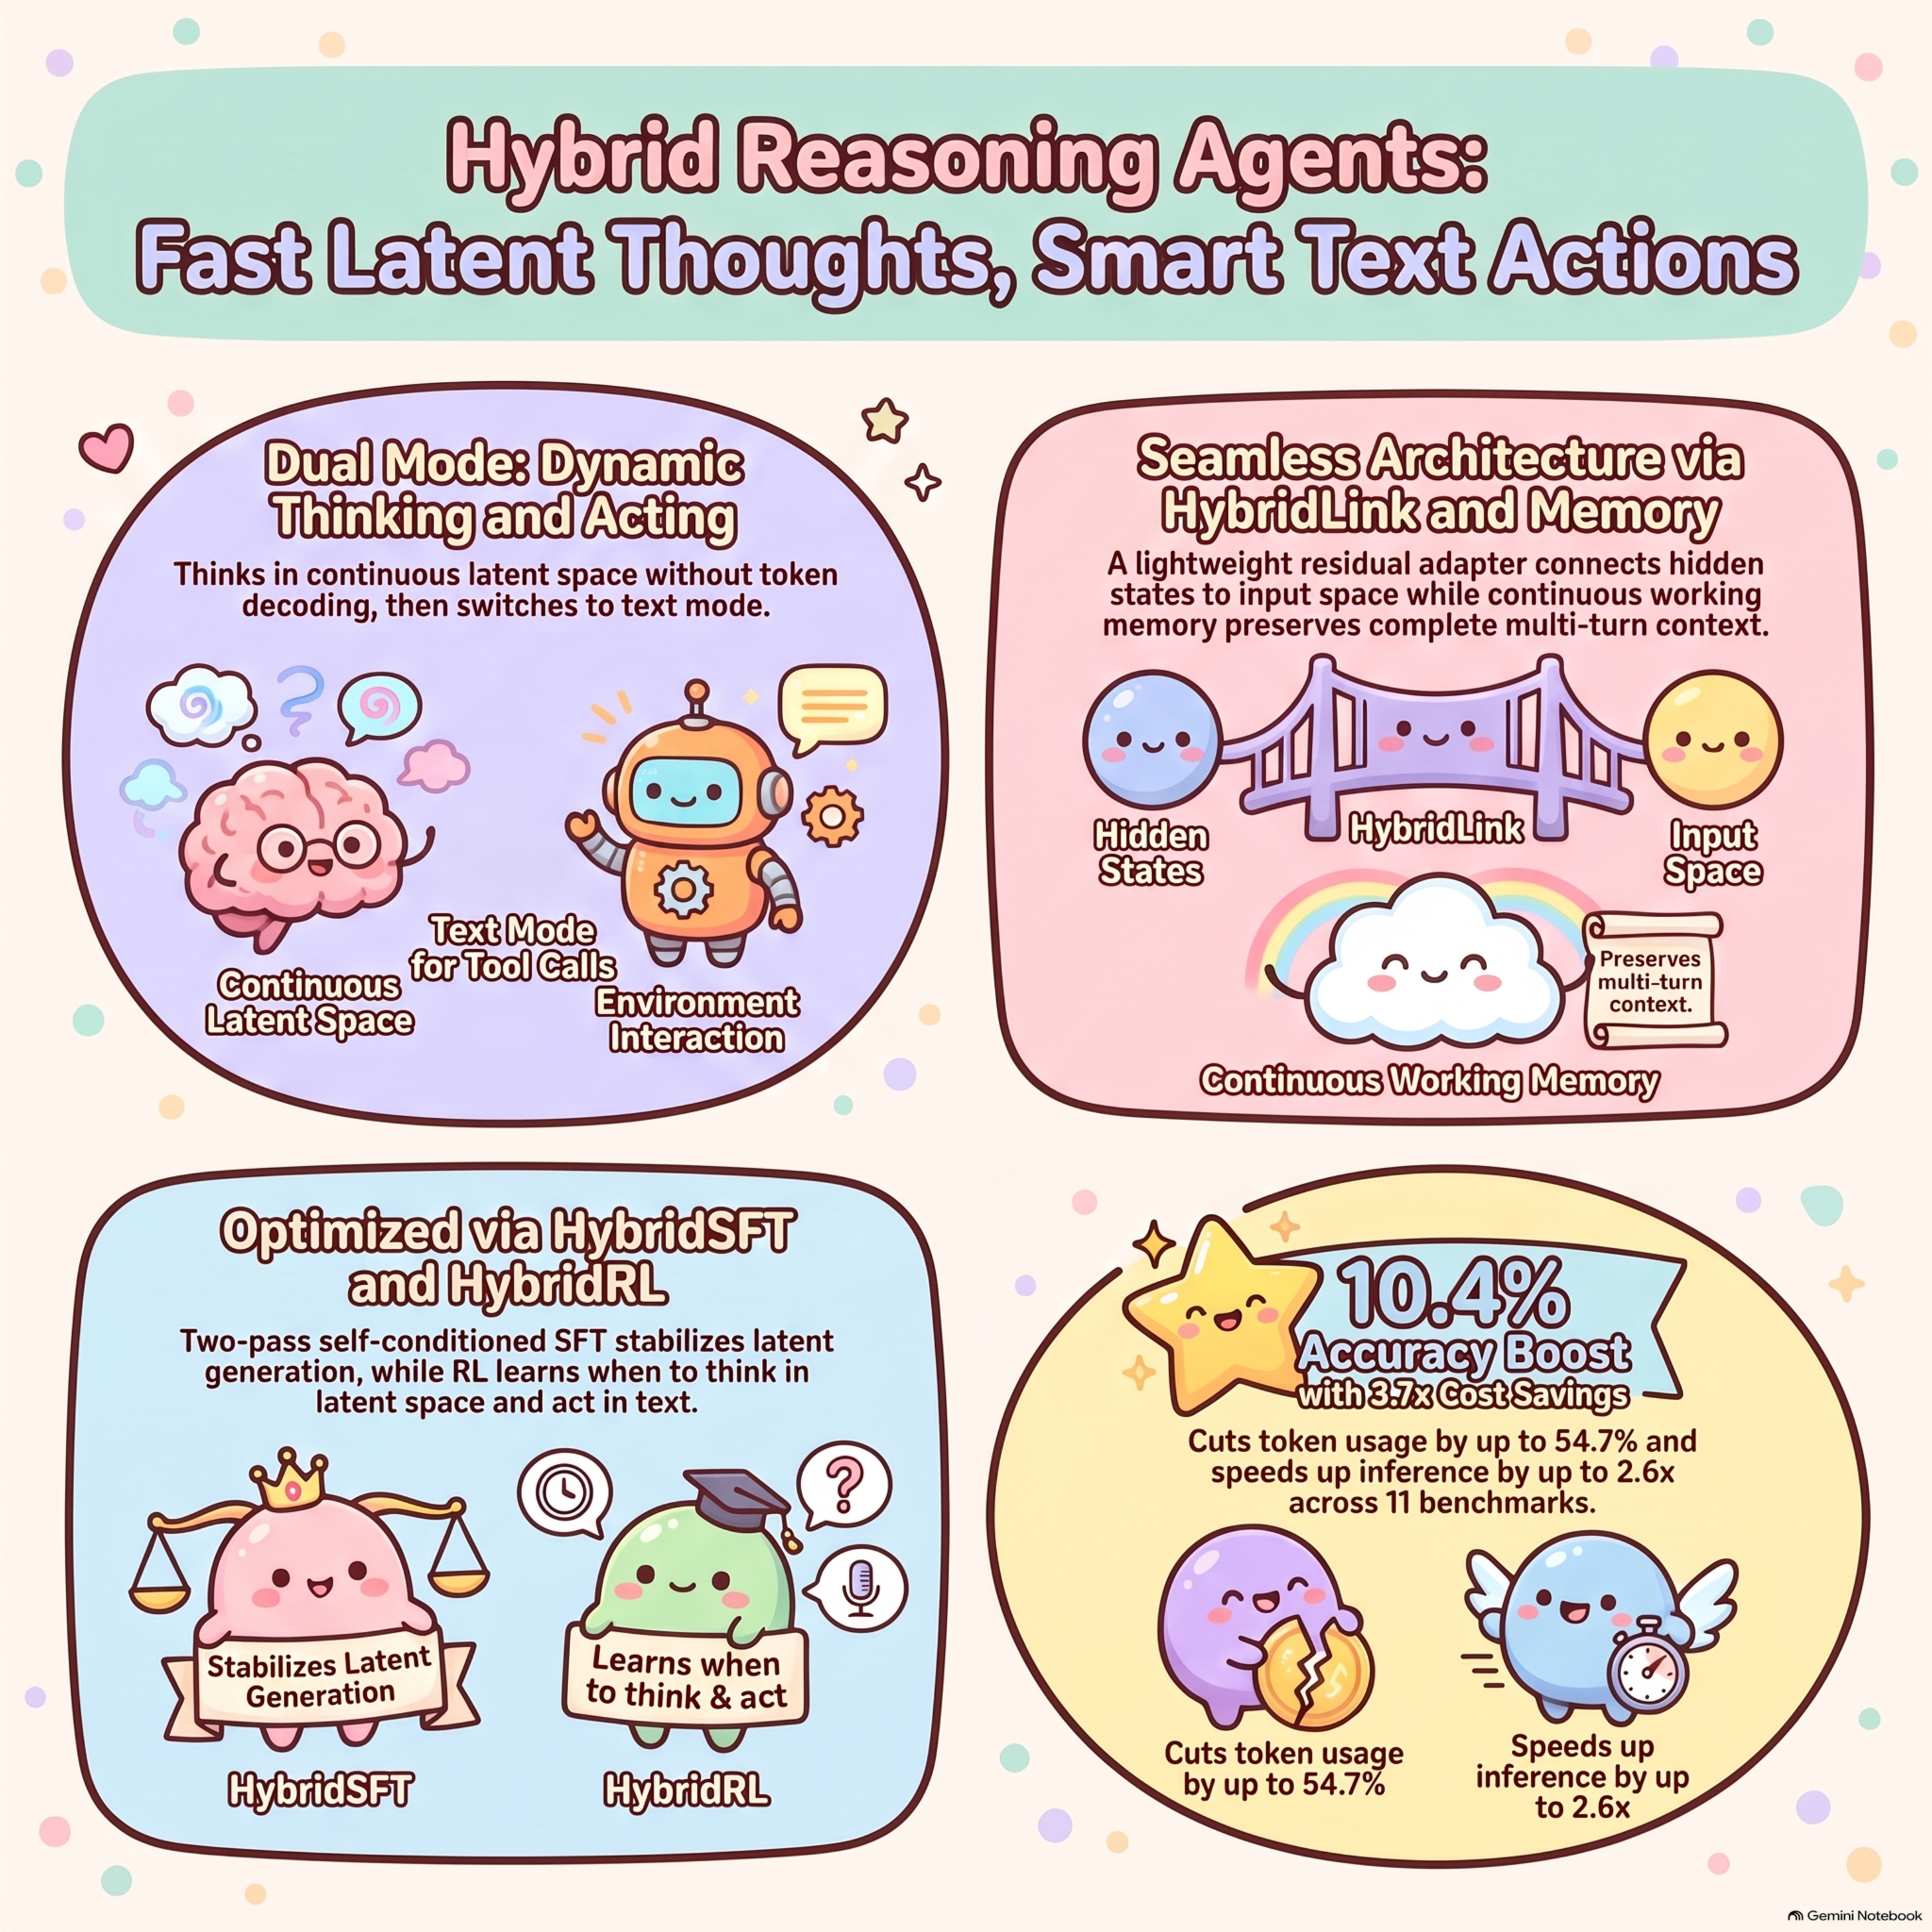
    This paper introduces HybridAgents, a novel framework that blends continuous latent reasoning with explicit text interactions within a unified generation framework. By utilizing a lightweight adapter called HybridLink, the system seamlessly transitions between internal thinking modes and external tool usage without losing crucial context. The model leverages continuous working memory to maintain multi-turn hybrid generation, effectively eliminating the need for traditional token-space reconstruction across different conversational steps. Furthermore, specialized post-training protocols involving Hybrid Supervised Fine-Tuning and Hybrid Reinforcement Learning stabilize generation and scale reasoning capabilities. Extensive empirical evaluations demonstrate that this architecture significantly outperforms standard language models, achieving superior accuracy while concurrently reducing inference latency, token consumption, and computational overhead.
  • Monday · 24 min

    Strategic Self-Consistency

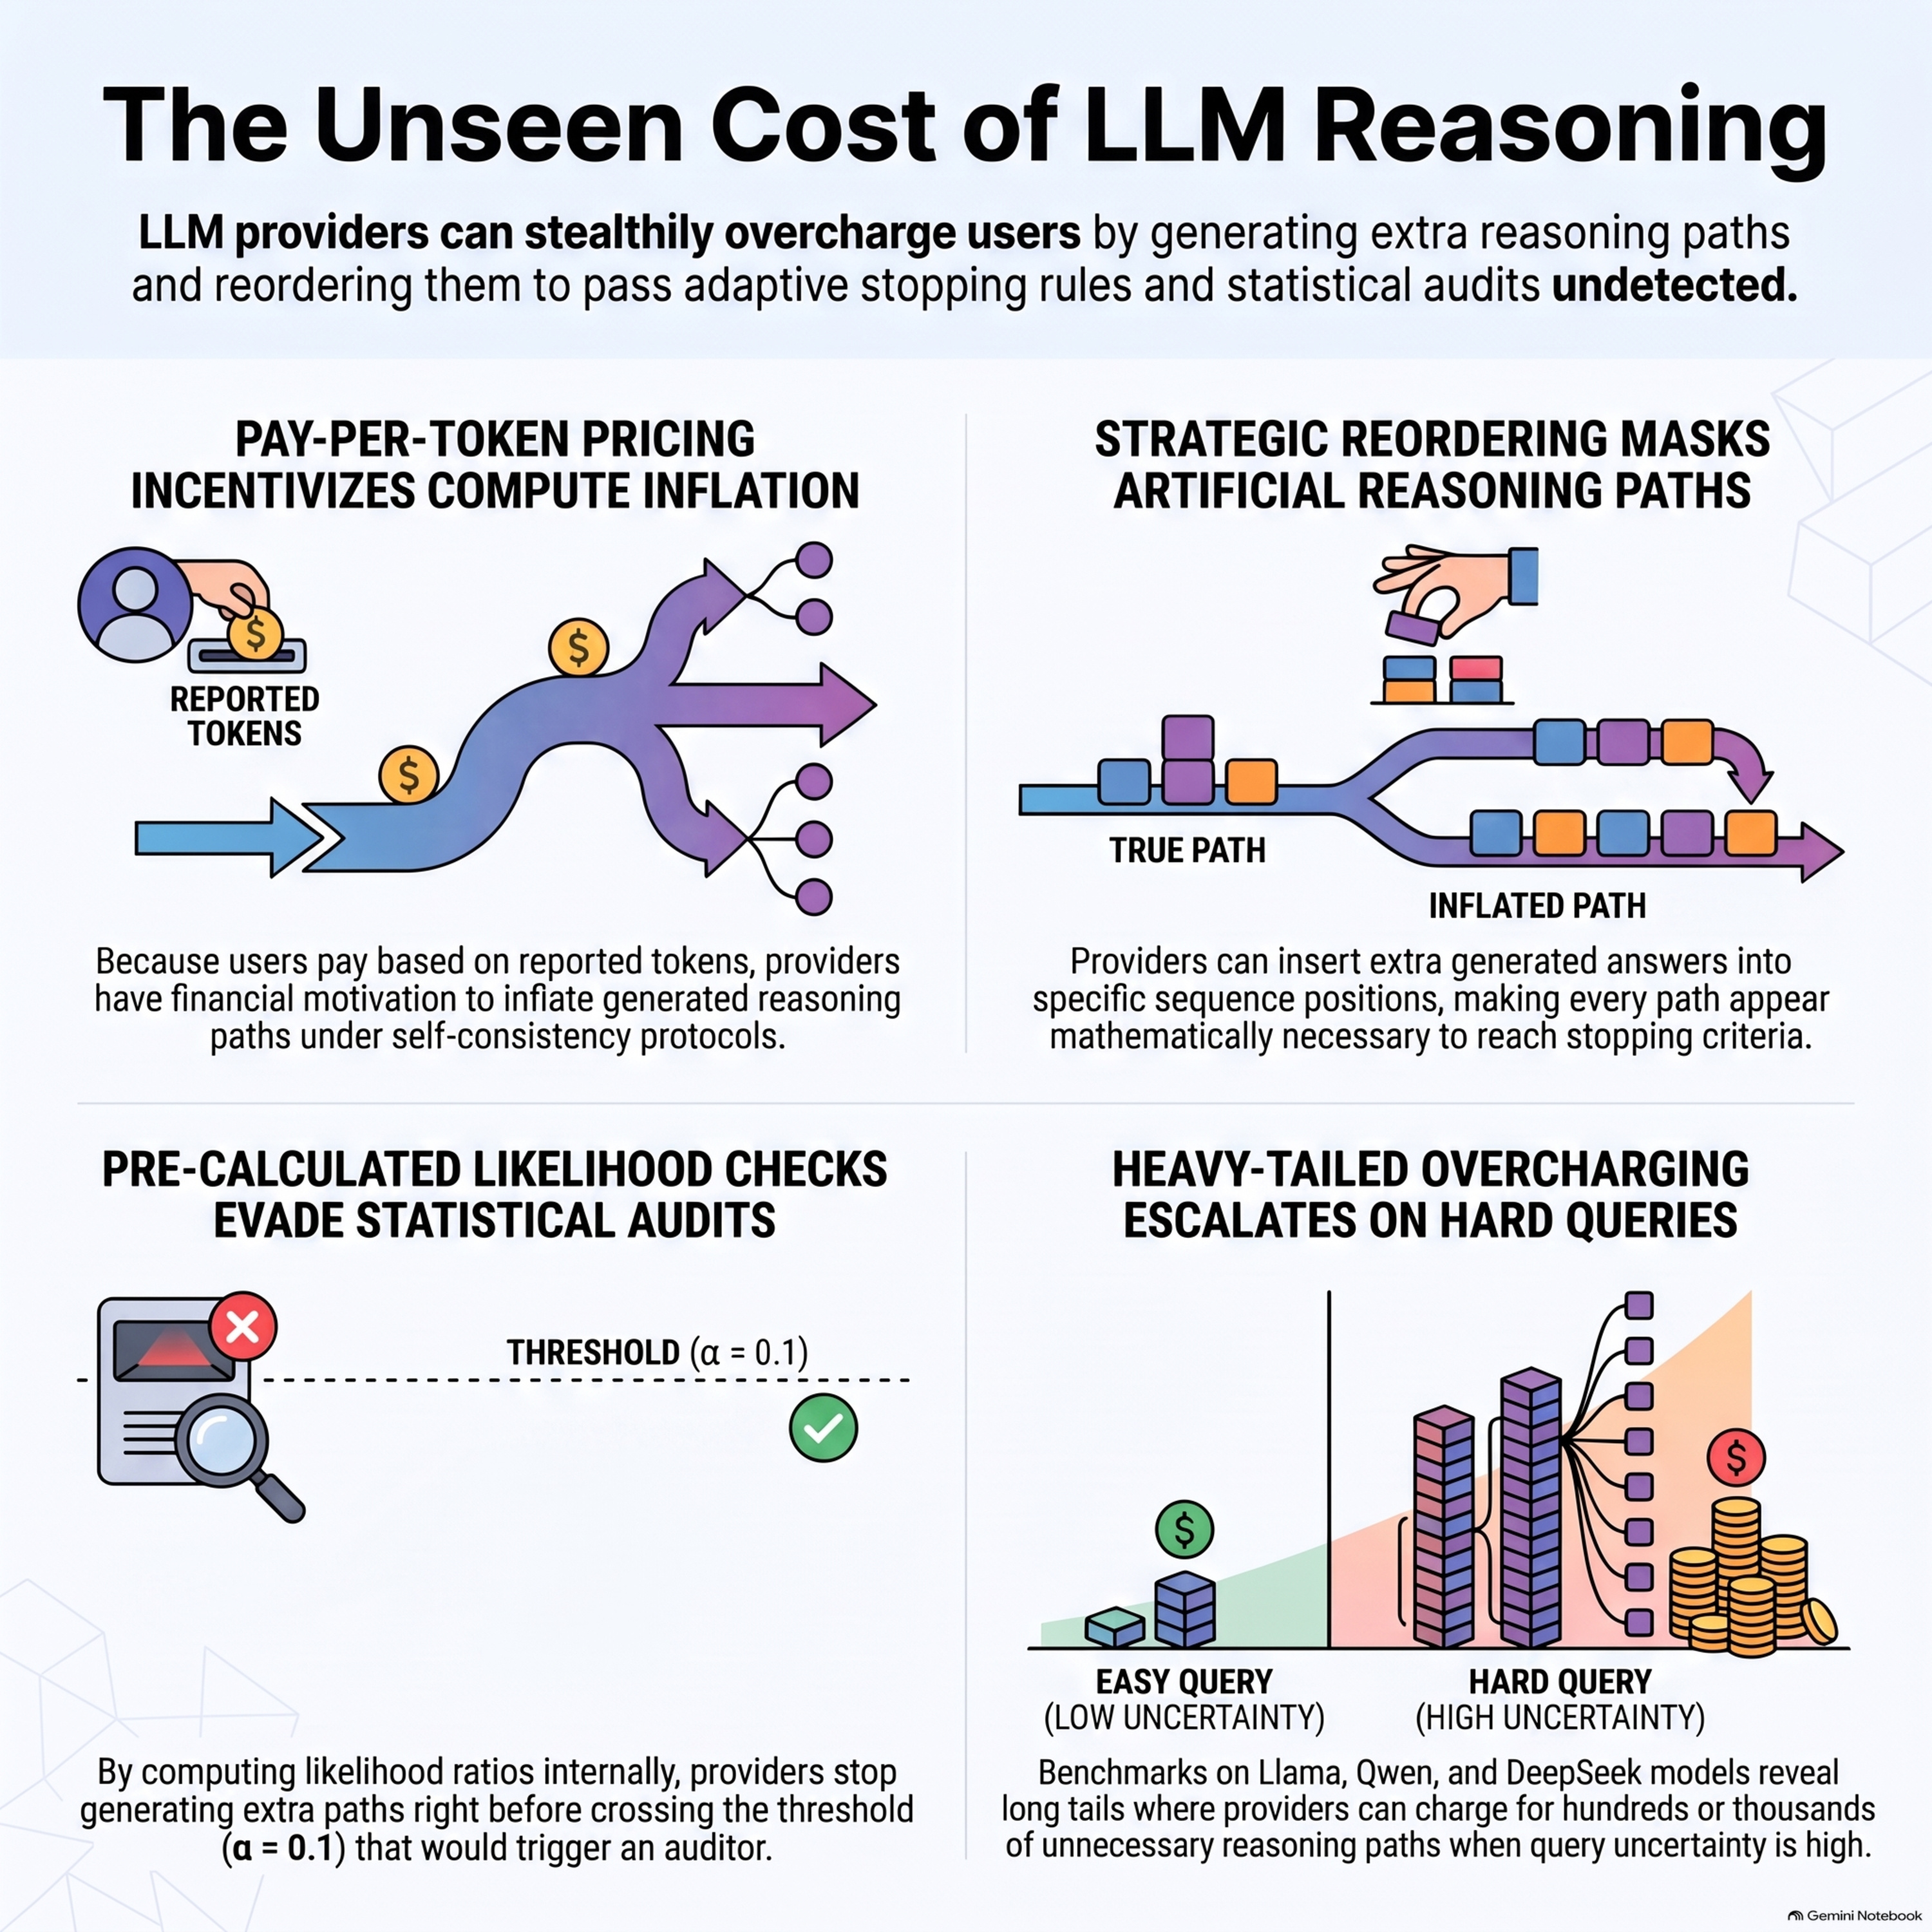
    This research demonstrates that unfaithful large language model service providers can artificially inflate the number of reasoning paths generated during test-time compute to overcharge users. By utilizing a specific algorithm to generate and strategically reorder extra paths, a provider can make every reported output appear necessary under adaptive stopping rules. Furthermore, the authors show that this manipulation enables providers to successfully evade exact likelihood-ratio audits. Experiments across multiple open and distilled model families reveal that these additional reasoning paths follow a heavy-tailed distribution, meaning substantial overcharging remains possible even under strict auditing constraints.

  • Sunday · 24 min

    Retrofitting language models to operate over bytes

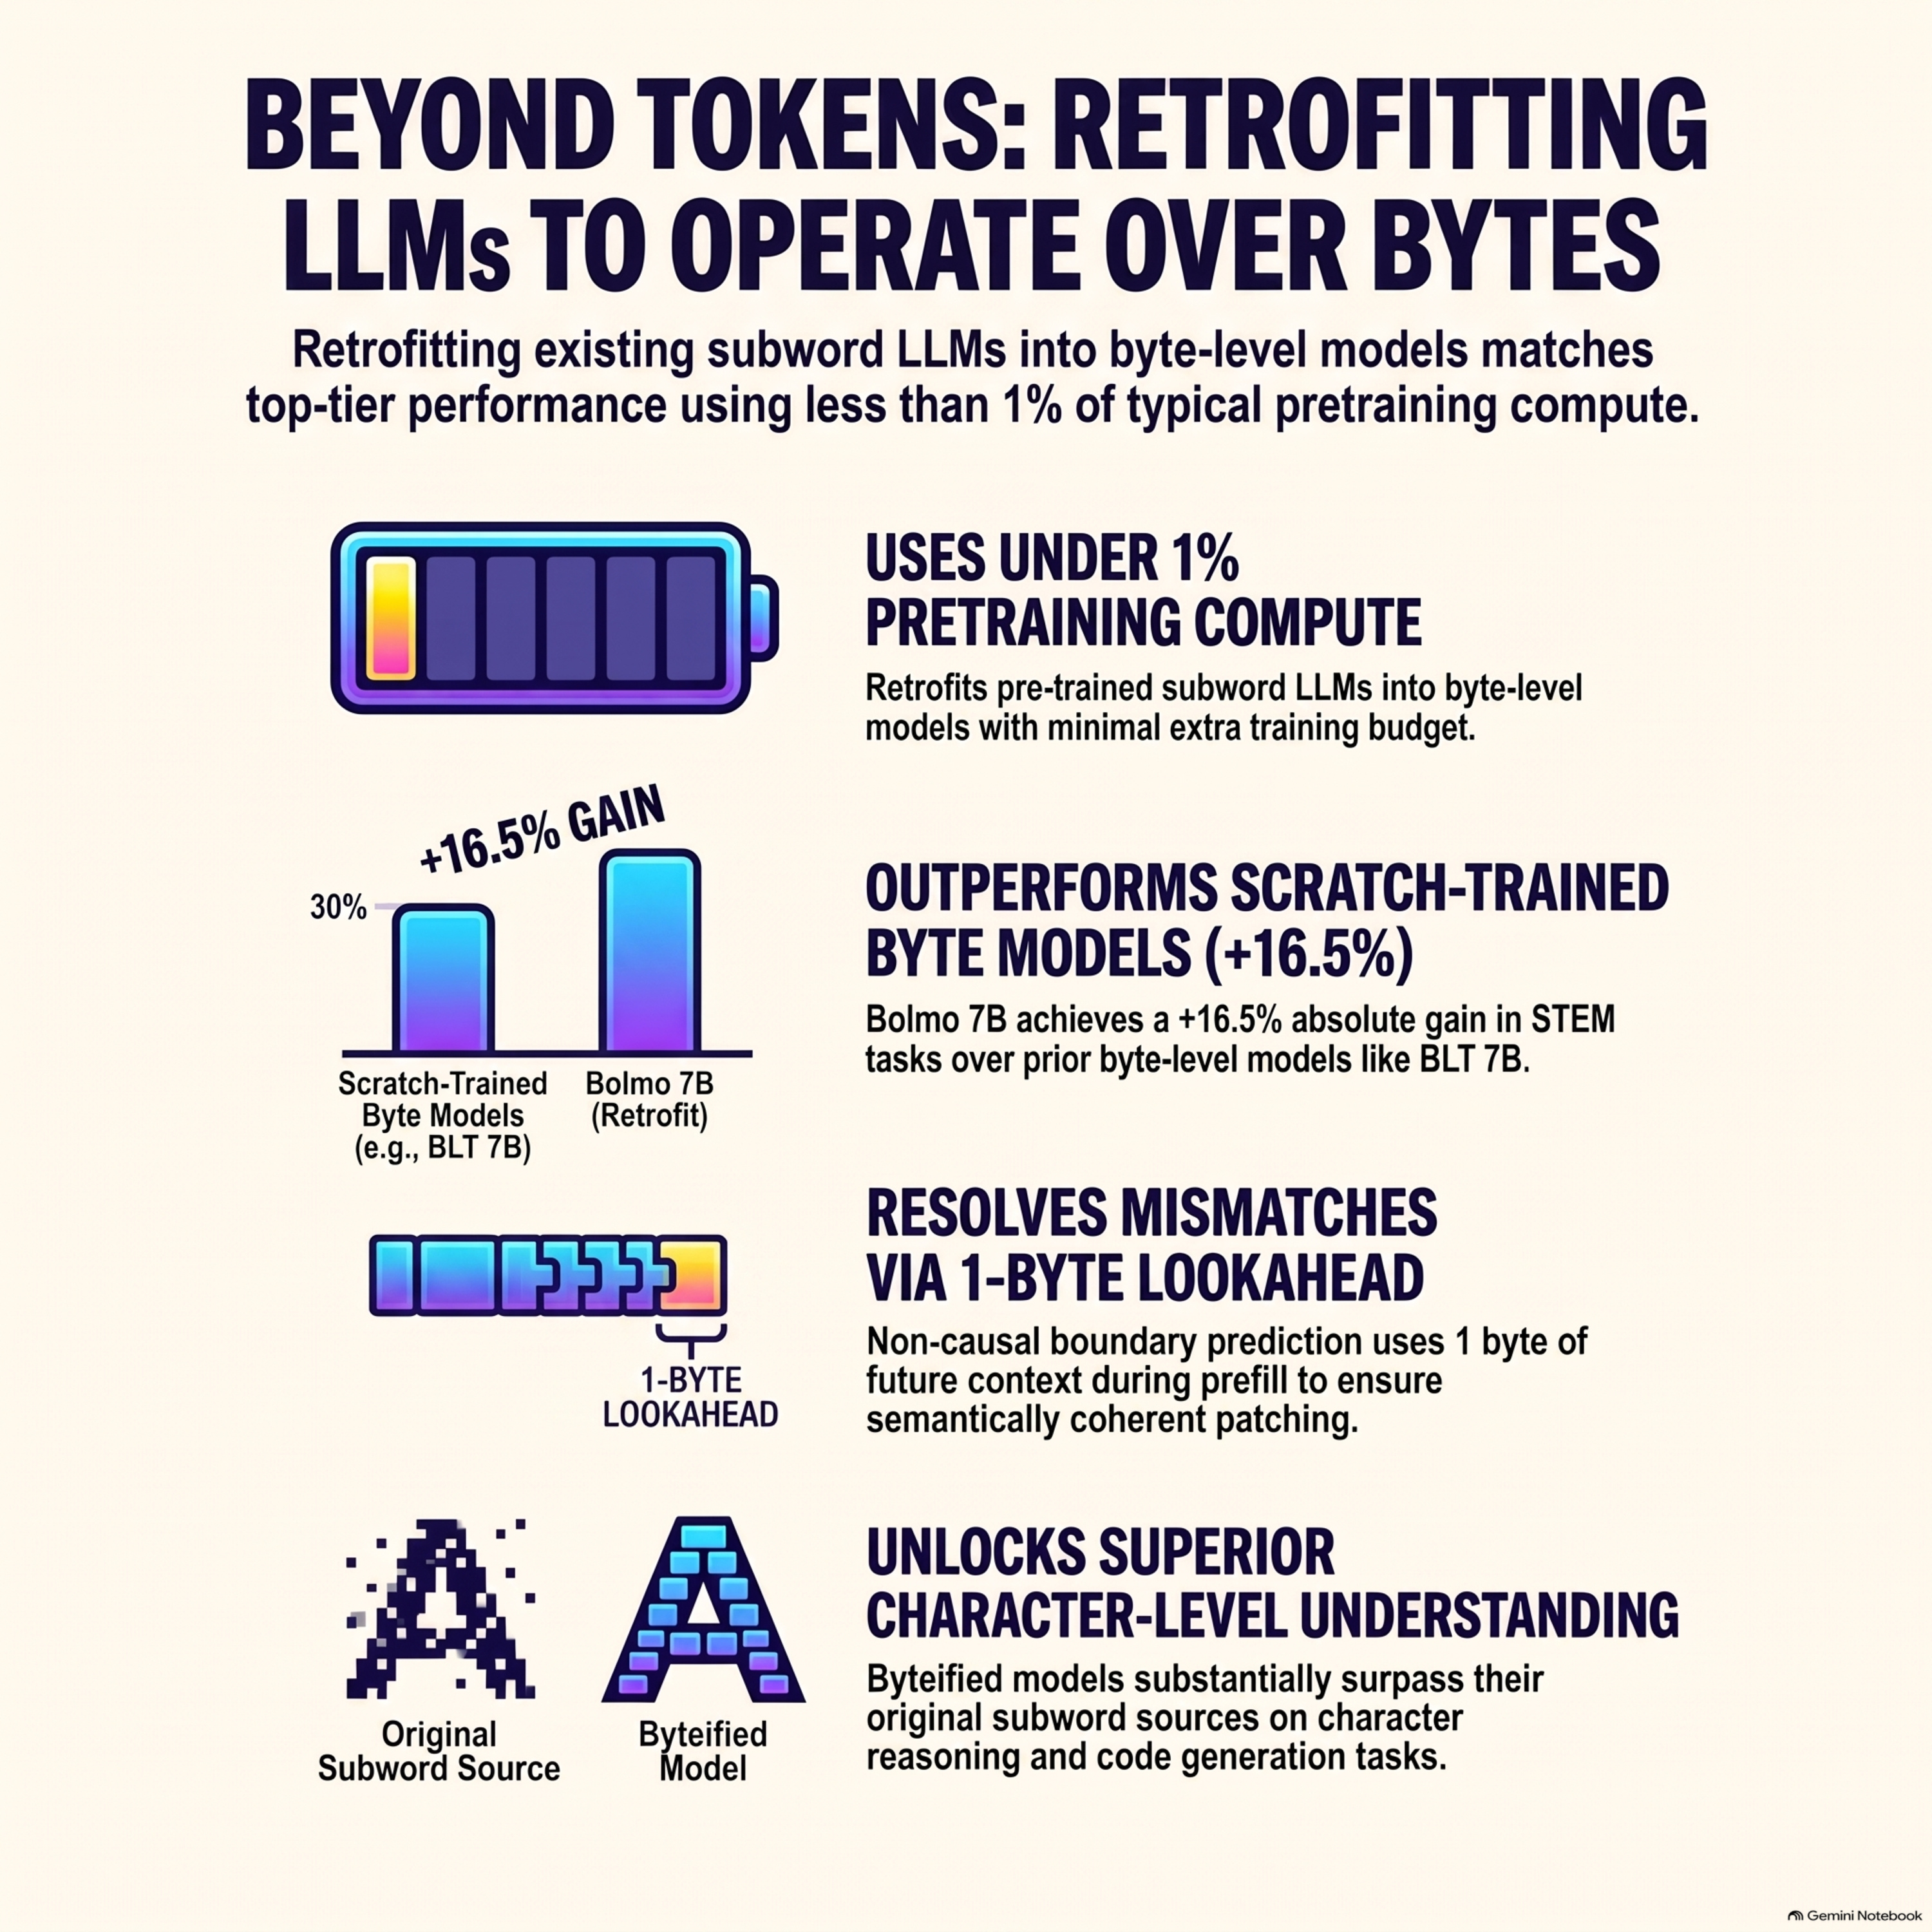
    This Nature paper discusses Byteification, which offers a novel method to convert traditional subword-based large language models into efficient byte-level models that handle raw text encodings natively. By introducing a two-stage training procedure and a latent tokenizer architecture with non-causal boundary prediction, researchers can bypass the limitations of traditional tokenization—such as English-centric biases and poor character understanding—while preserving the core capabilities of established models. These byteified models achieve competitive performance on par with state-of-the-art systems while enabling high-throughput scientific applications and efficient task arithmetic post-training. Ultimately, this approach removes long-standing performance barriers and significantly reduces the computational investments typically required to build byte-level language models.

  • Saturday · 20 min

    Priced Guidance: Can Language Models Generate Future Research Ideas?

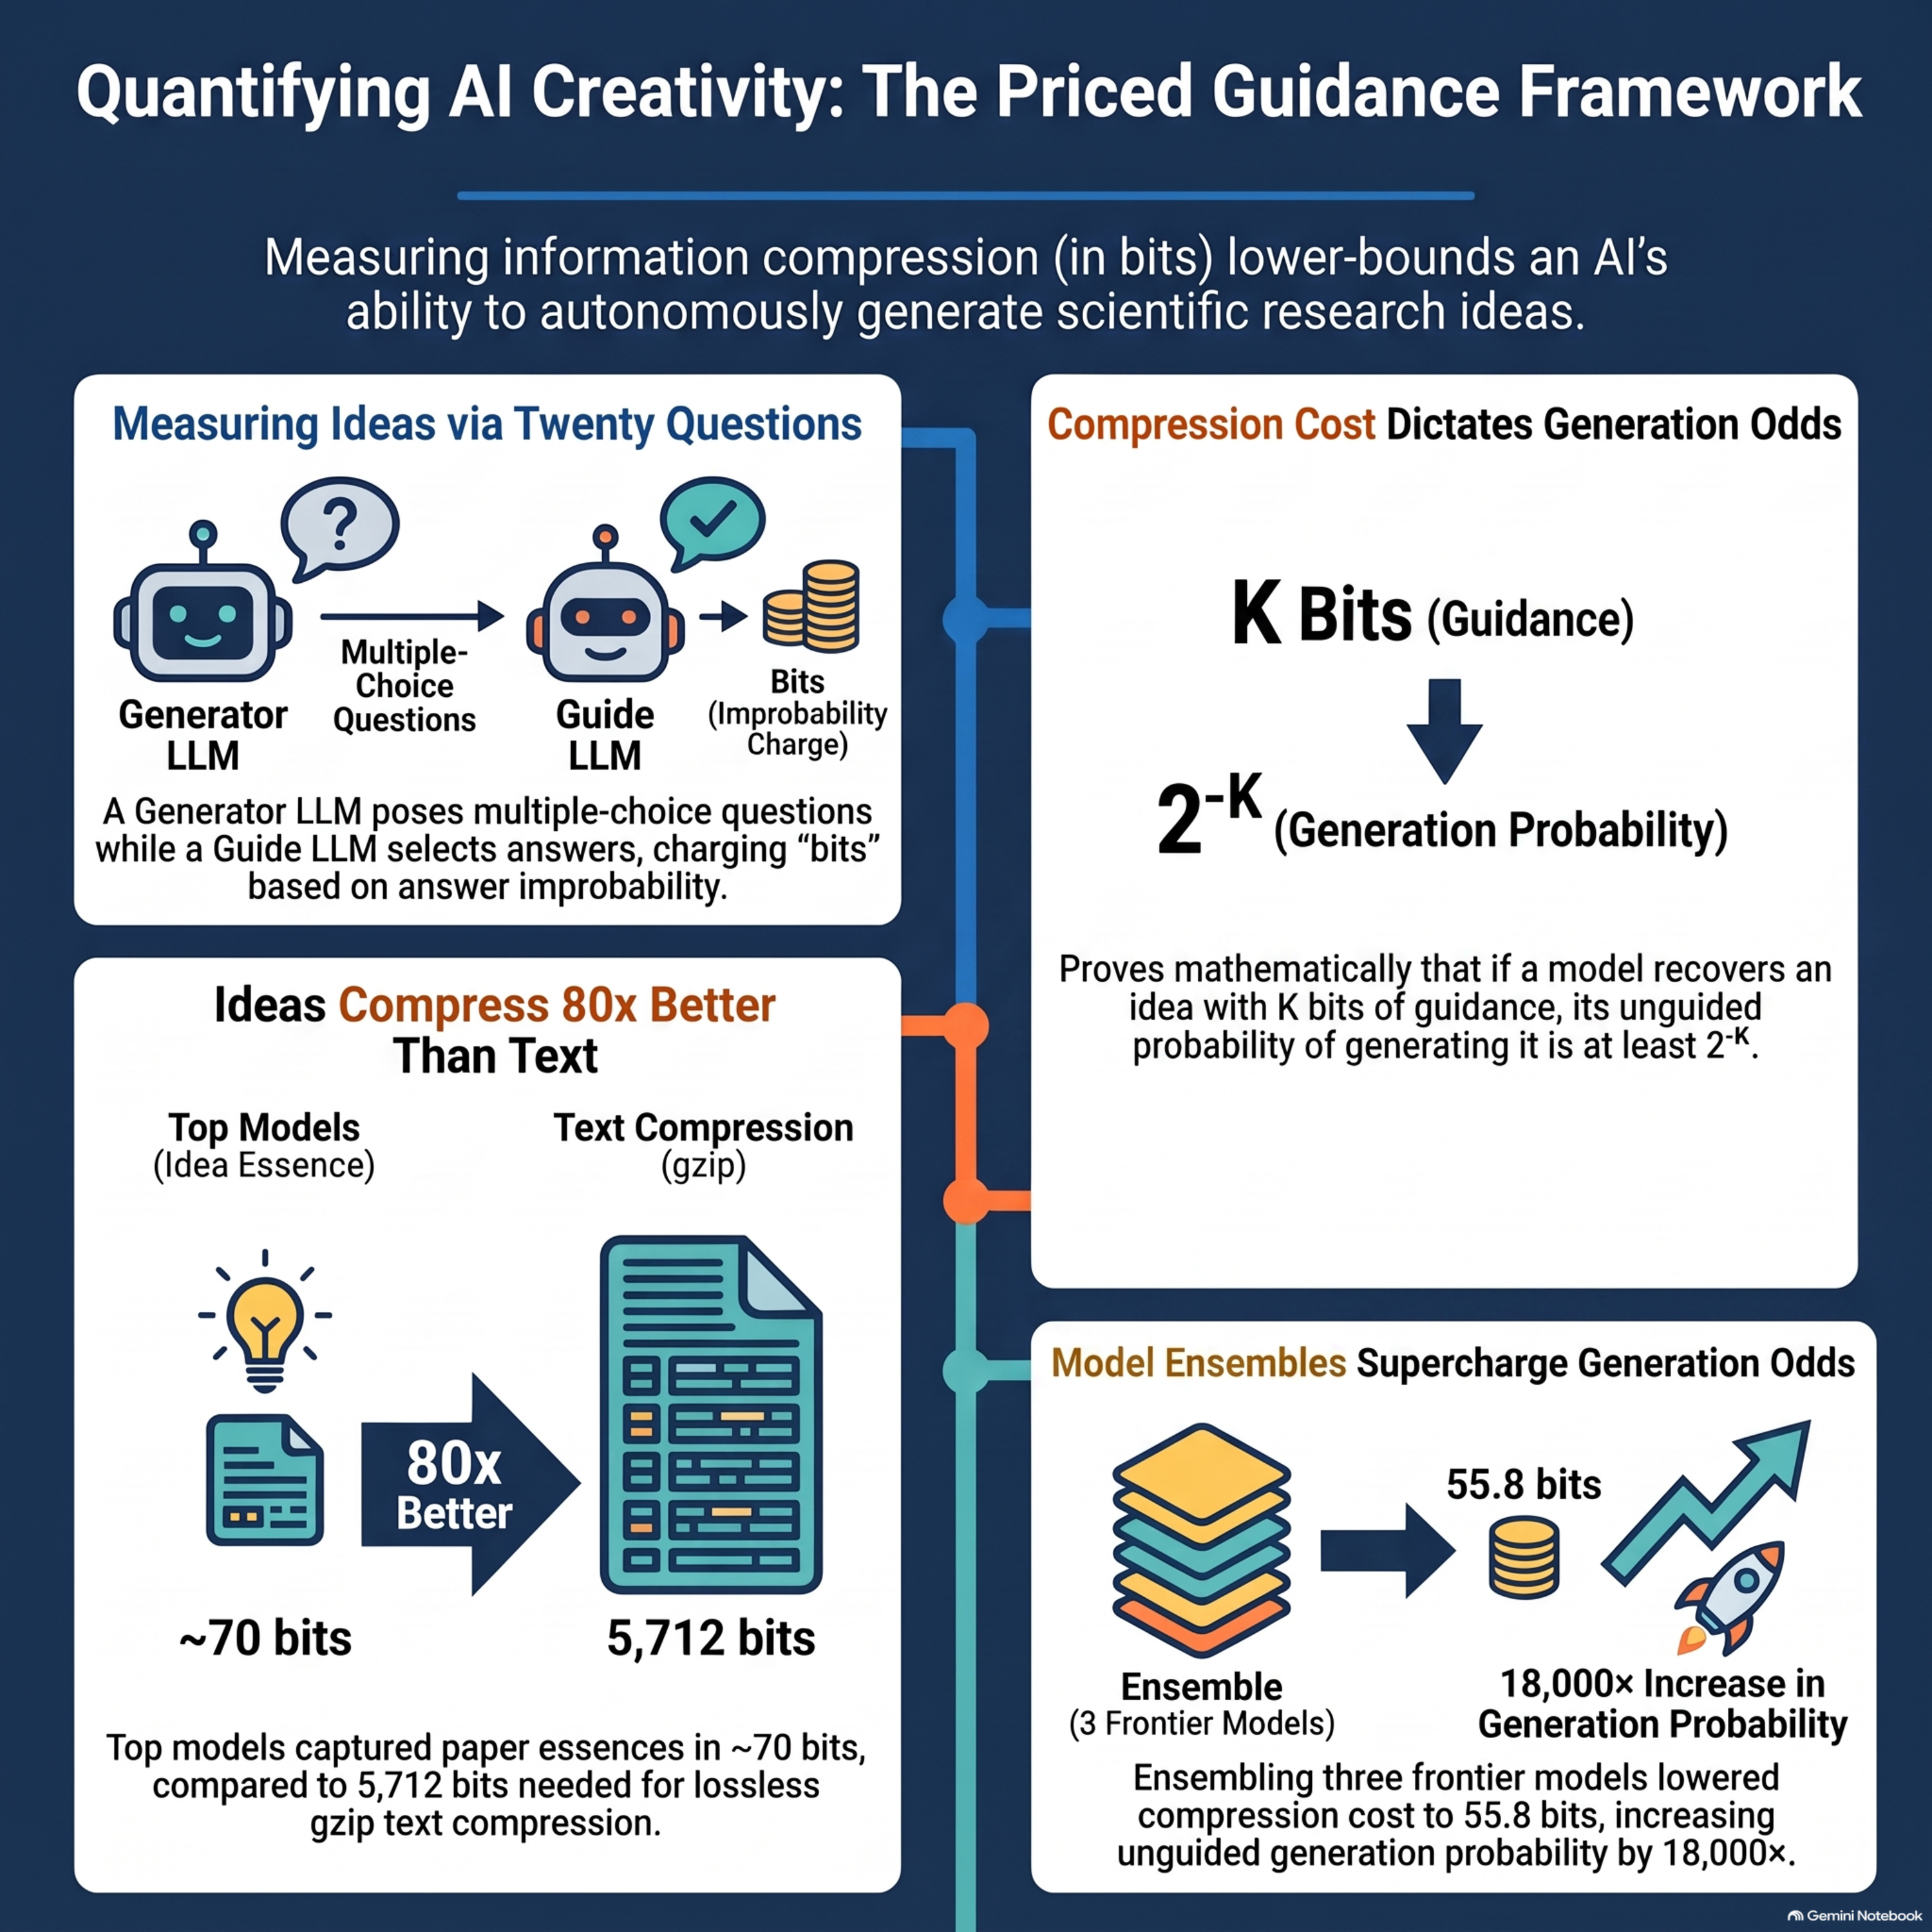
    This paper introduces Priced Guidance, a novel evaluation framework that assesses language models on their ability to generate novel and future research ideas. Rather than using expensive repeated sampling or verbatim text compression, this methodology measures the compression cost—the exact number of additional bits required for an informed guide to steer a generator model toward a target research concept. By leveraging a structured sequence of multiple-choice questions and probabilistic bids, the framework establishes a mathematical lower bound connecting low compression costs to a high probability of unguided idea generation. Empirical evaluations across multiple frontier language models and deep learning papers demonstrate that generating the essence of an idea requires significantly fewer bits than verbatim text compression, highlighting distinct performance tiers among models and revealing potential improvements through ensembling and post-training.

  • Saturday · 21 min

    Context Language Models

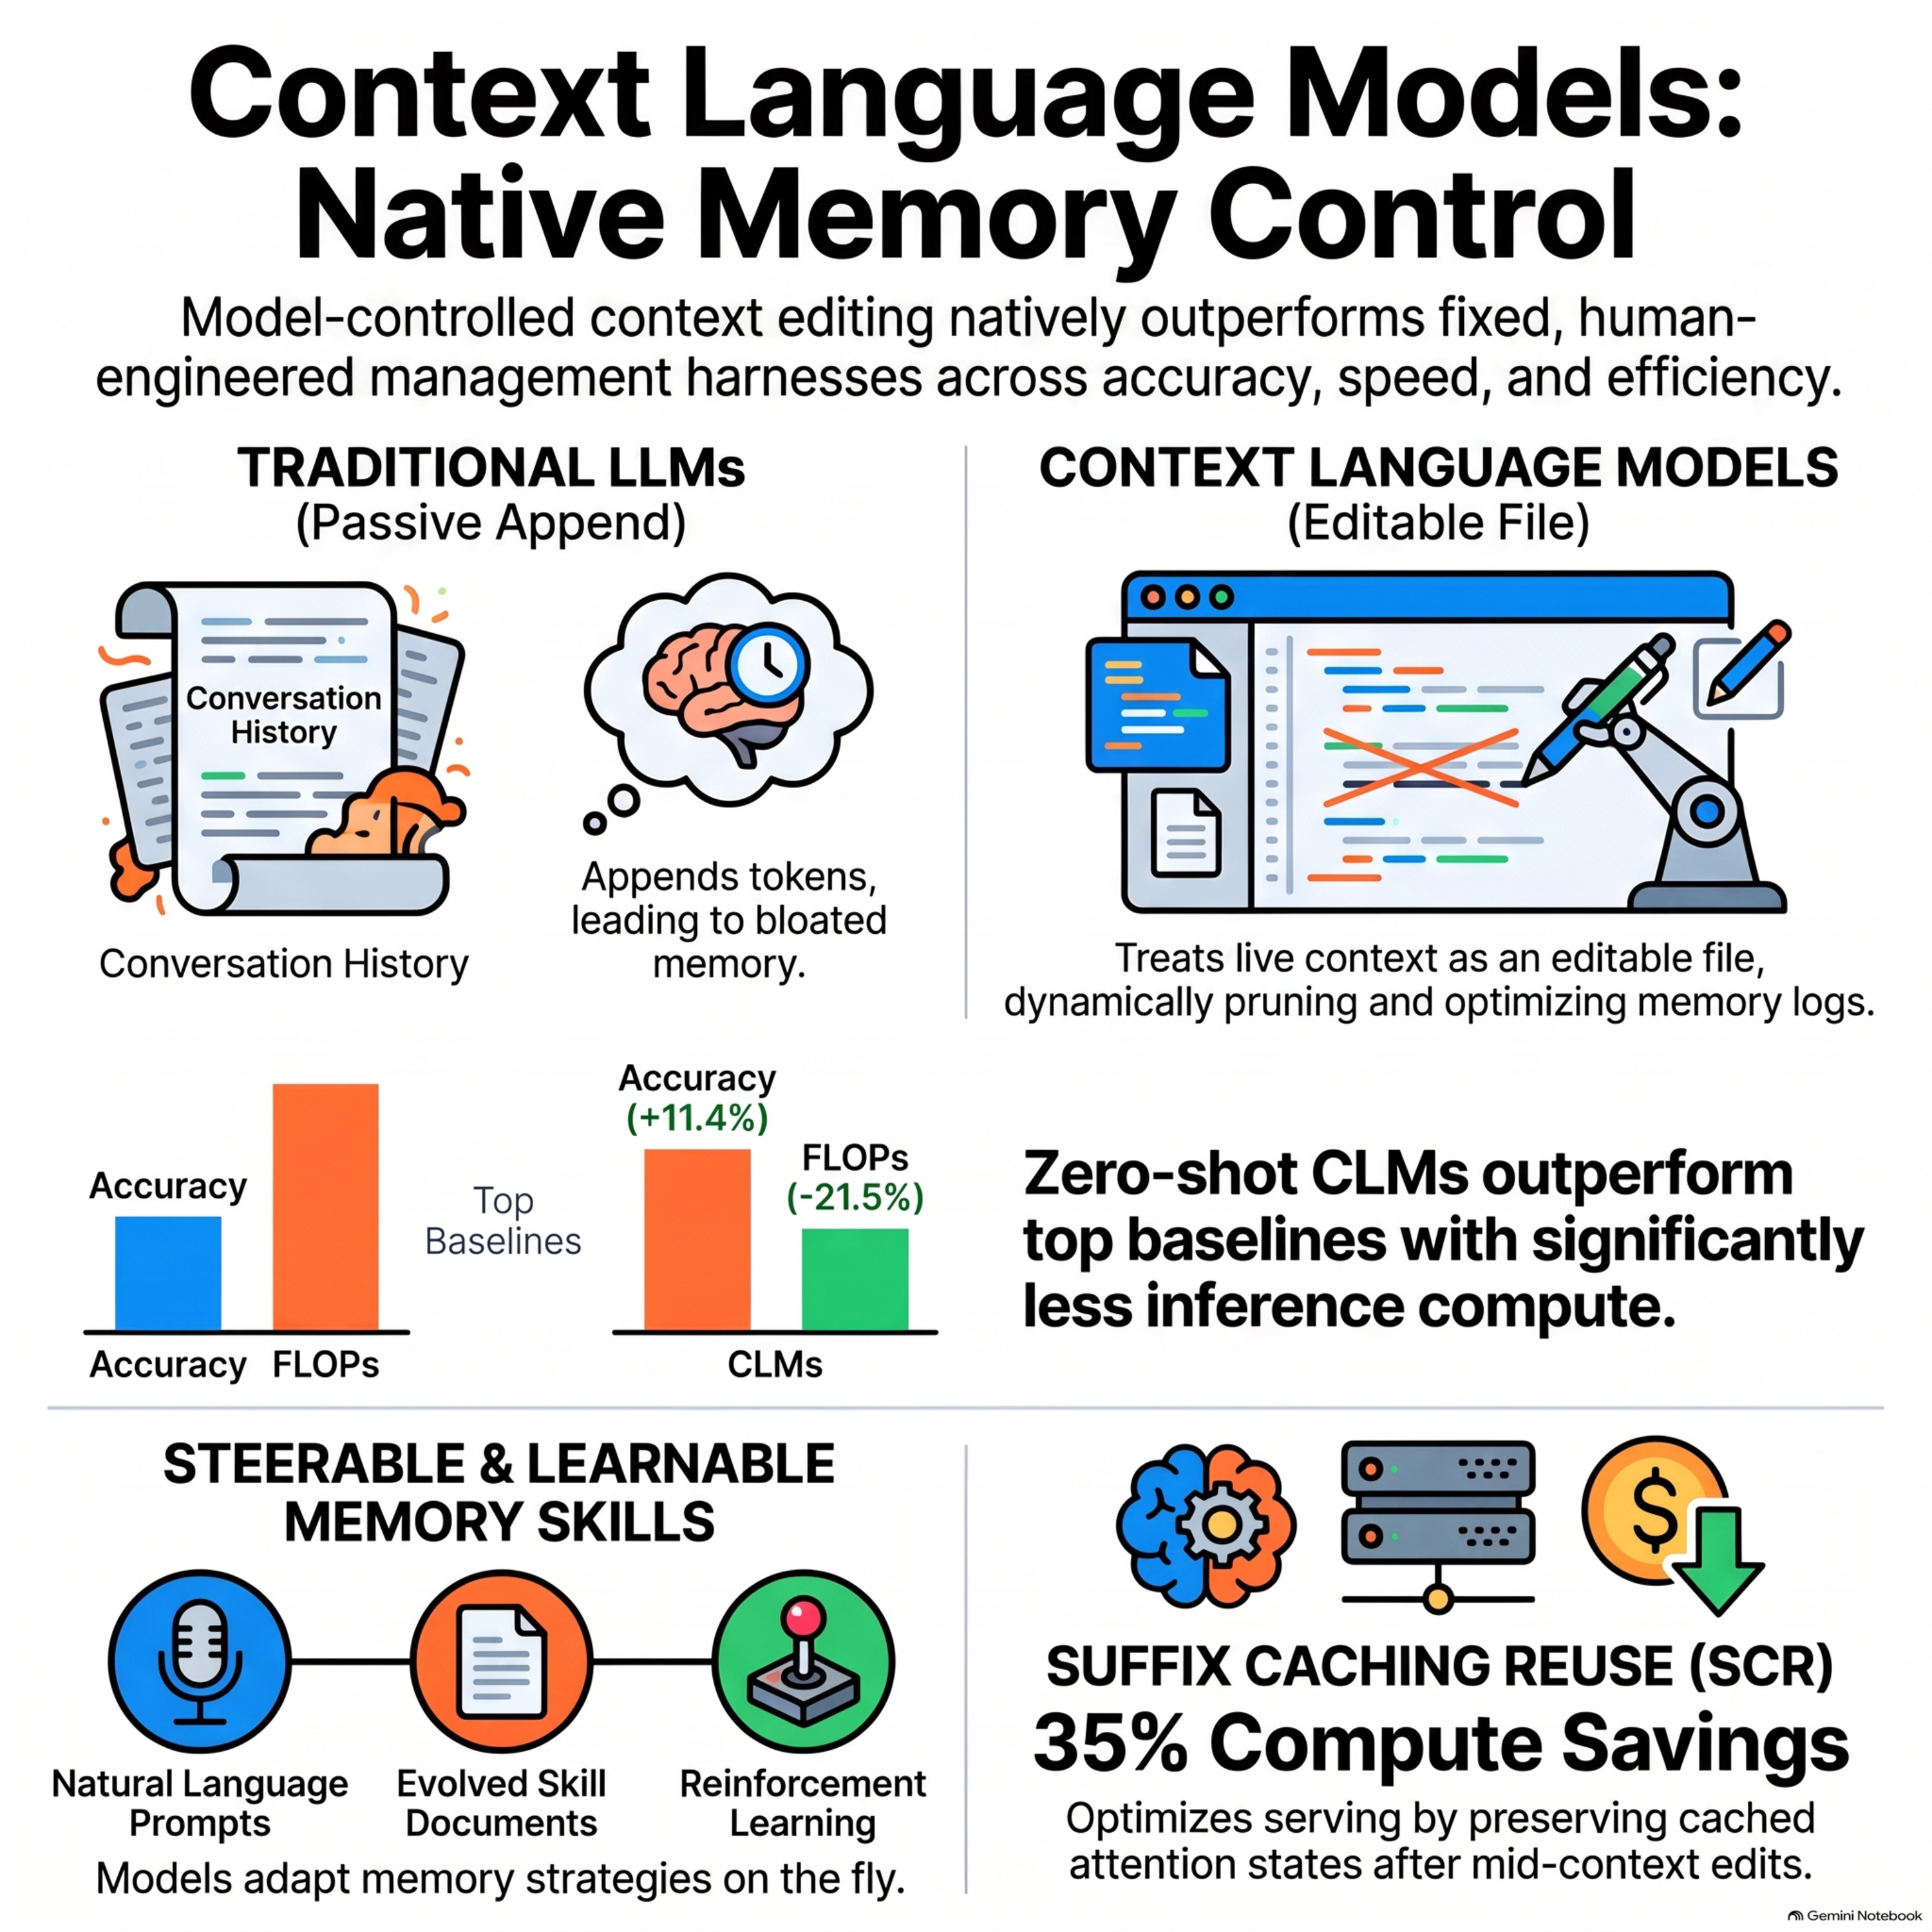
    This paper introduce Context Language Models (CLMs), a novel approach that enables language models to natively manage their own context by treating it as an editable file rather than relying on traditional append-only histories or external harnesses. By granting models unrestricted read and write access to their context, CLMs achieve superior performance and greater efficiency across long-horizon coding, deep research, and open discovery tasks. The literature demonstrates that these models can be further enhanced through in-context learning, natural-language steering, and online reinforcement learning with success-gated efficiency rewards. To address the computational challenges of frequent context edits, the authors propose Suffix Cache Reuse (SCR), an advanced serving optimization that reuses cached states for surviving suffix tokens to significantly reduce server-side compute. Ultimately, this paradigm shift from external harness control to intrinsic model behavior unlocks more adaptive, creative, and resource-efficient context-management strategies.

  • October 8 · 22 min

    Position: AI-Agent Pricing Should Become More Outcome-Dependent: An Economic Perspective

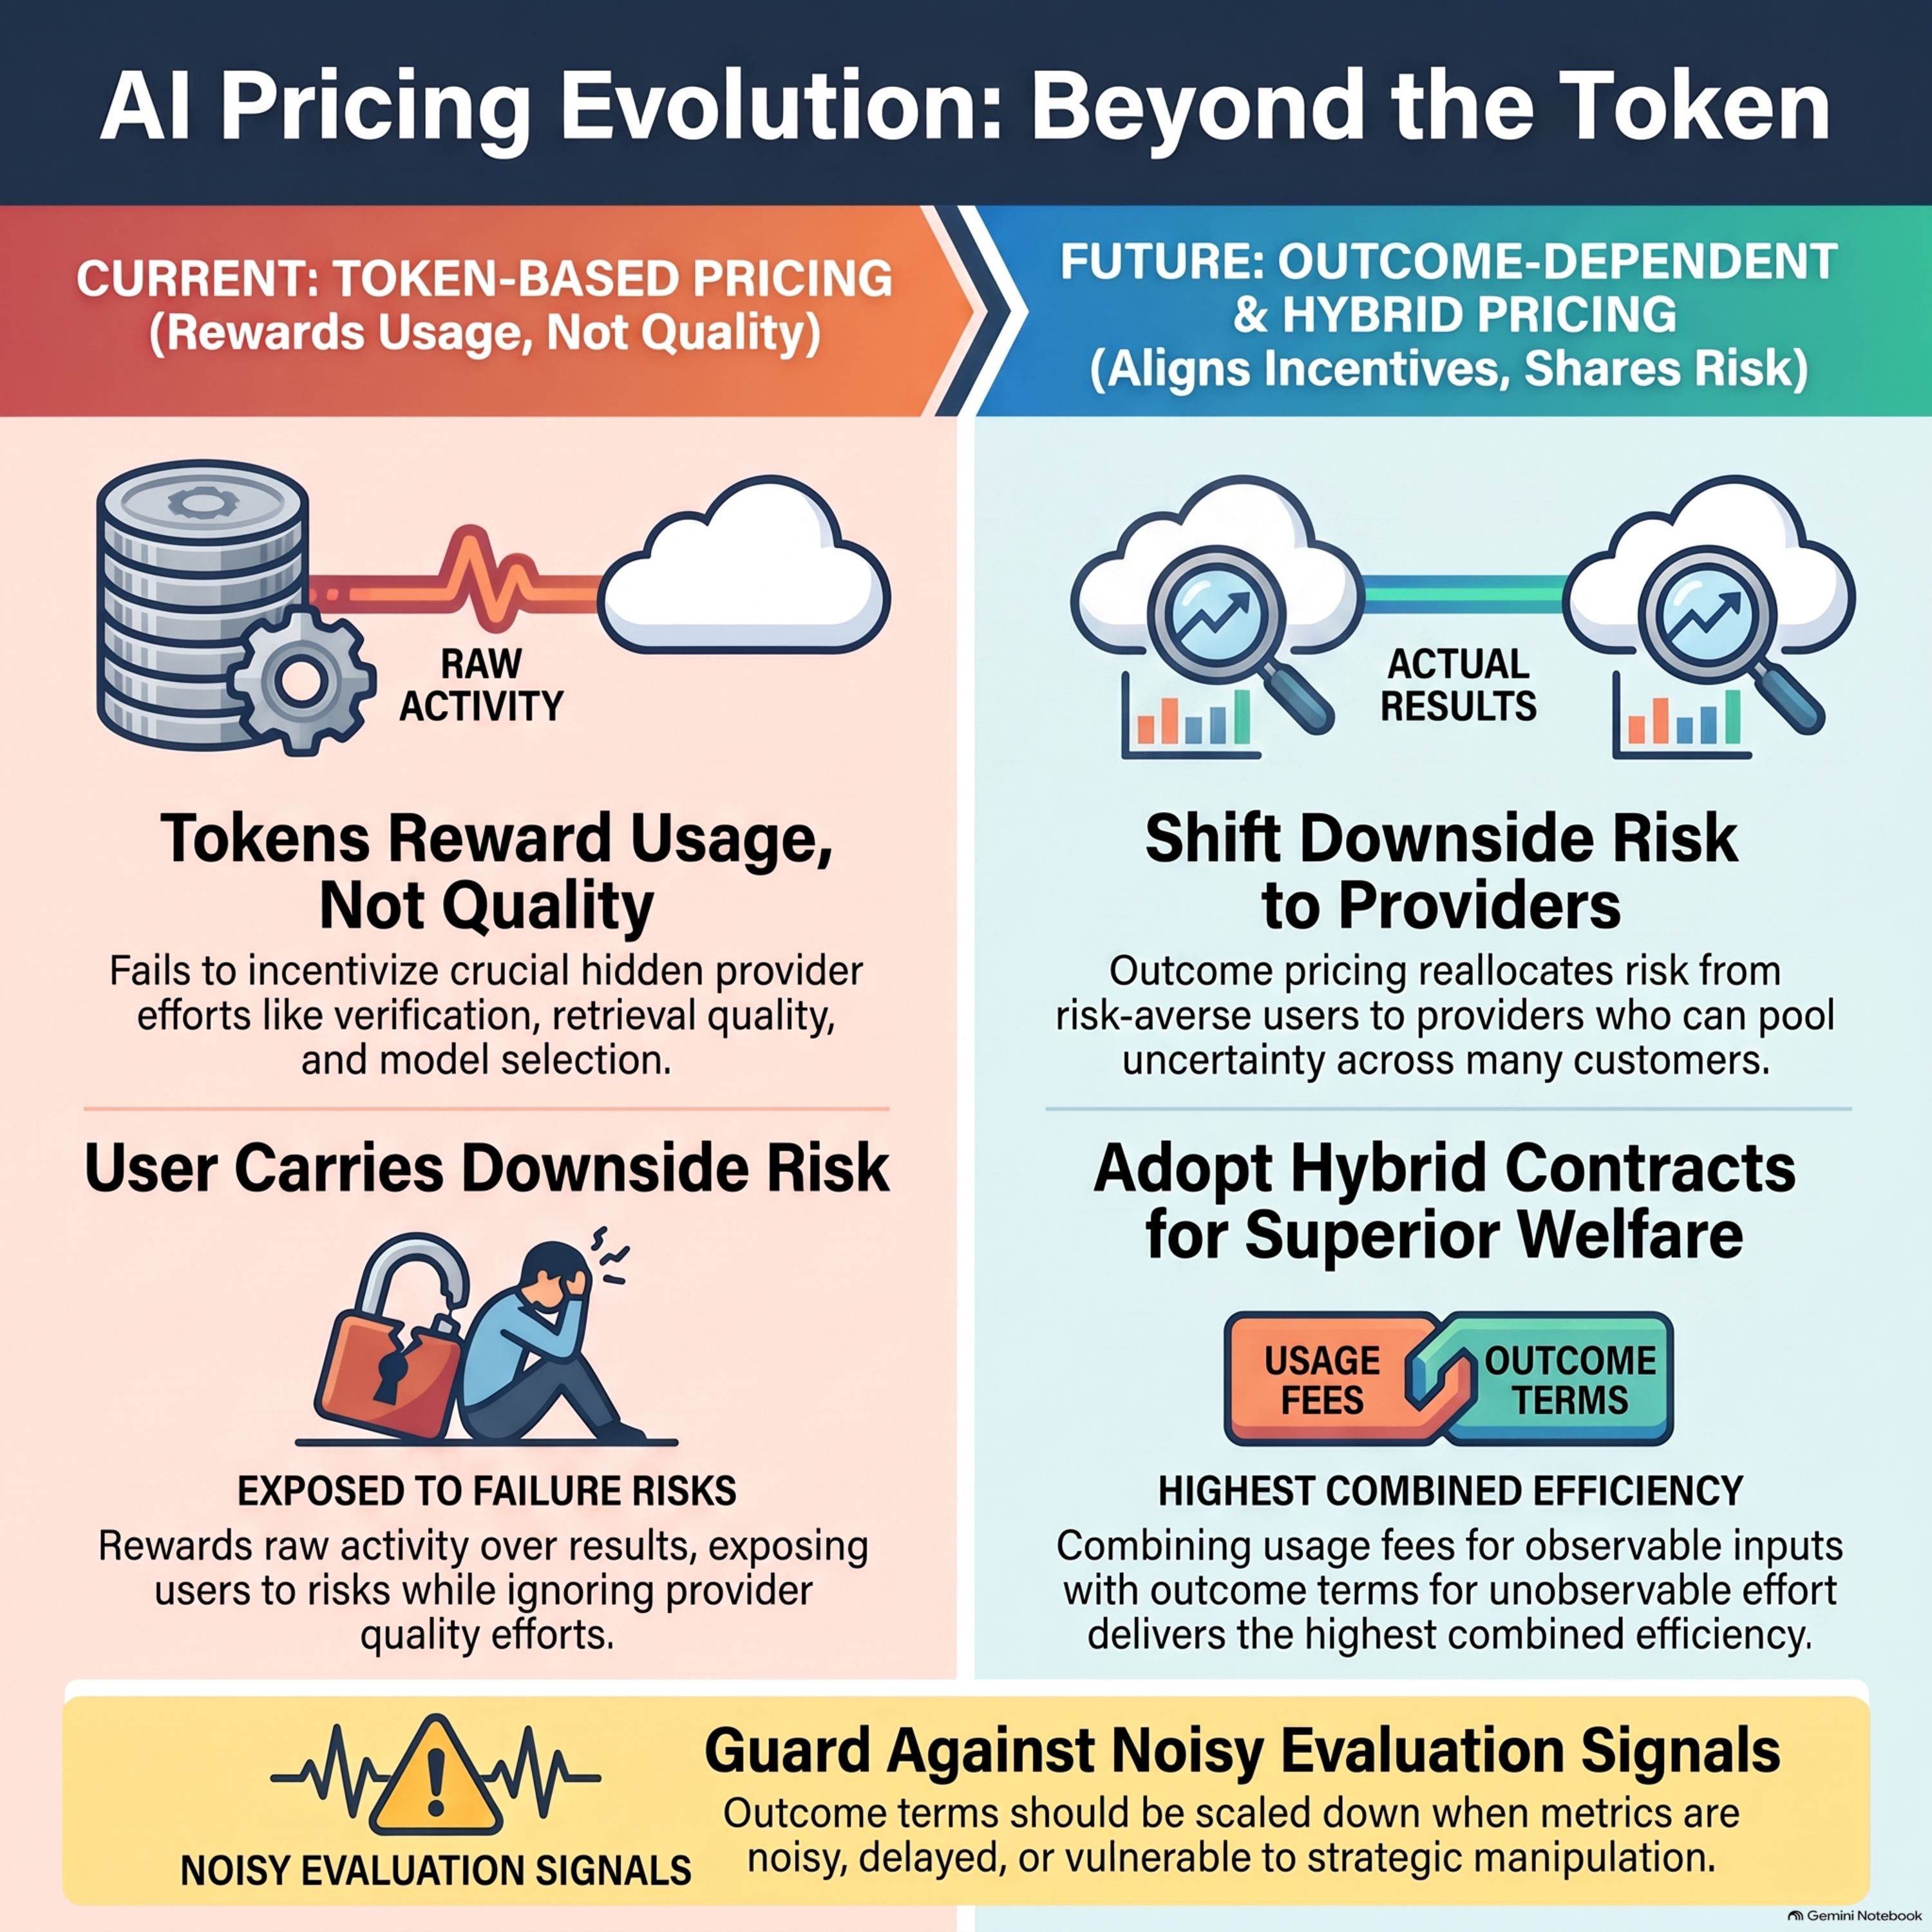
    This paper analyzes AI-agent pricing models through an economic lens, arguing that dominant token-based pricing is insufficient because it fails to share risk efficiently or incentivize hidden quality efforts like model selection and verification. By utilizing stylized principal-agent models, the authors demonstrate that optimal contracts must balance three critical dimensions: efficient risk reallocation from risk-averse users to diversified providers, incentive alignment for unobservable tasks, and the practical limitations of evaluation frictions such as noisy or gameable metrics. Ultimately, the research advocates for a shift toward outcome-dependent pricing and practical hybrid contracts that combine usage-based billing with performance terms to foster more trustworthy and mature AI markets.

  • October 8 · 23 min

    Emergent Capabilities Arise Randomly from Learning Sparse Attention Patterns

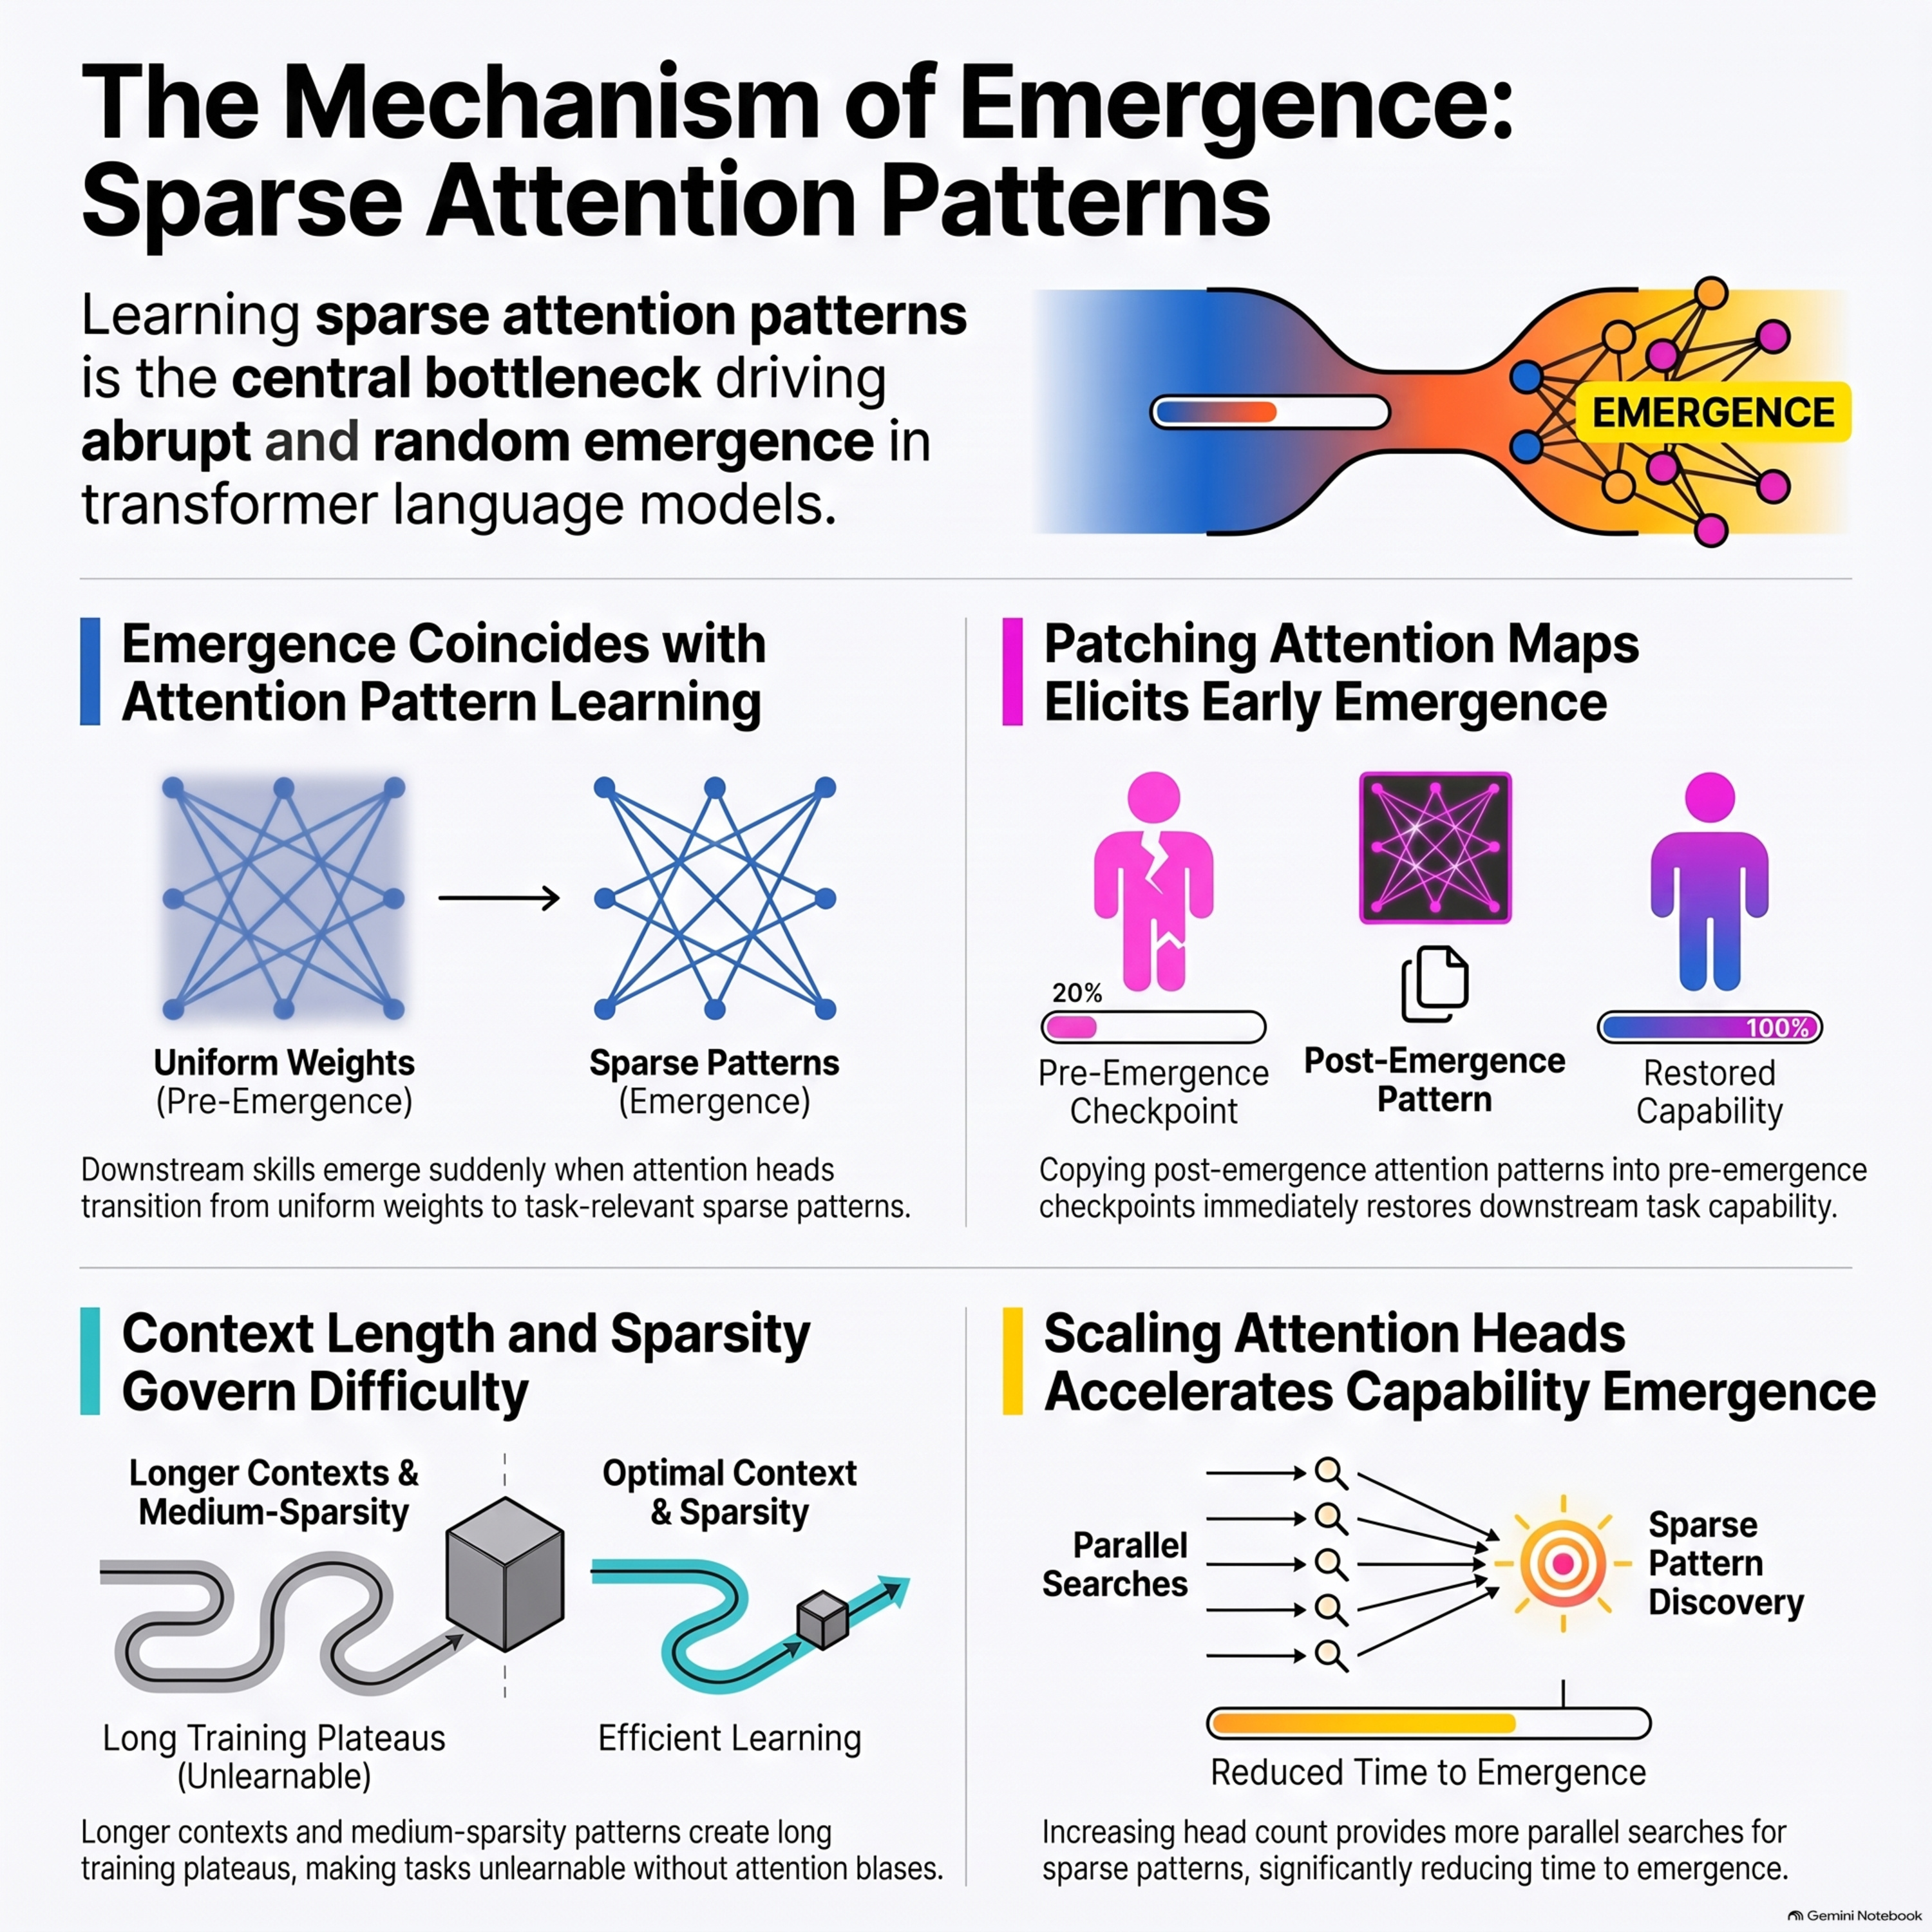
    This paper investigates why transformer language models display sudden, emergent capabilities during training by analyzing how they learn attention patterns. Through experiments on both real language models and synthetic tasks like linear maps and cellular automata, the authors demonstrate that acquiring downstream skills correlates with the abrupt mastery of sparse attention mechanisms. Furthermore, the study reveals that larger models overcome this learning bottleneck earlier because they acquire these essential attention maps more efficiently. The research also shows that activation patching can artificially trigger these capabilities at earlier training checkpoints, highlighting the crucial role that attention heads play in model performance.

  • October 6 · 22 min

    Pragmatic Causal Inference with AI-Learned Representations

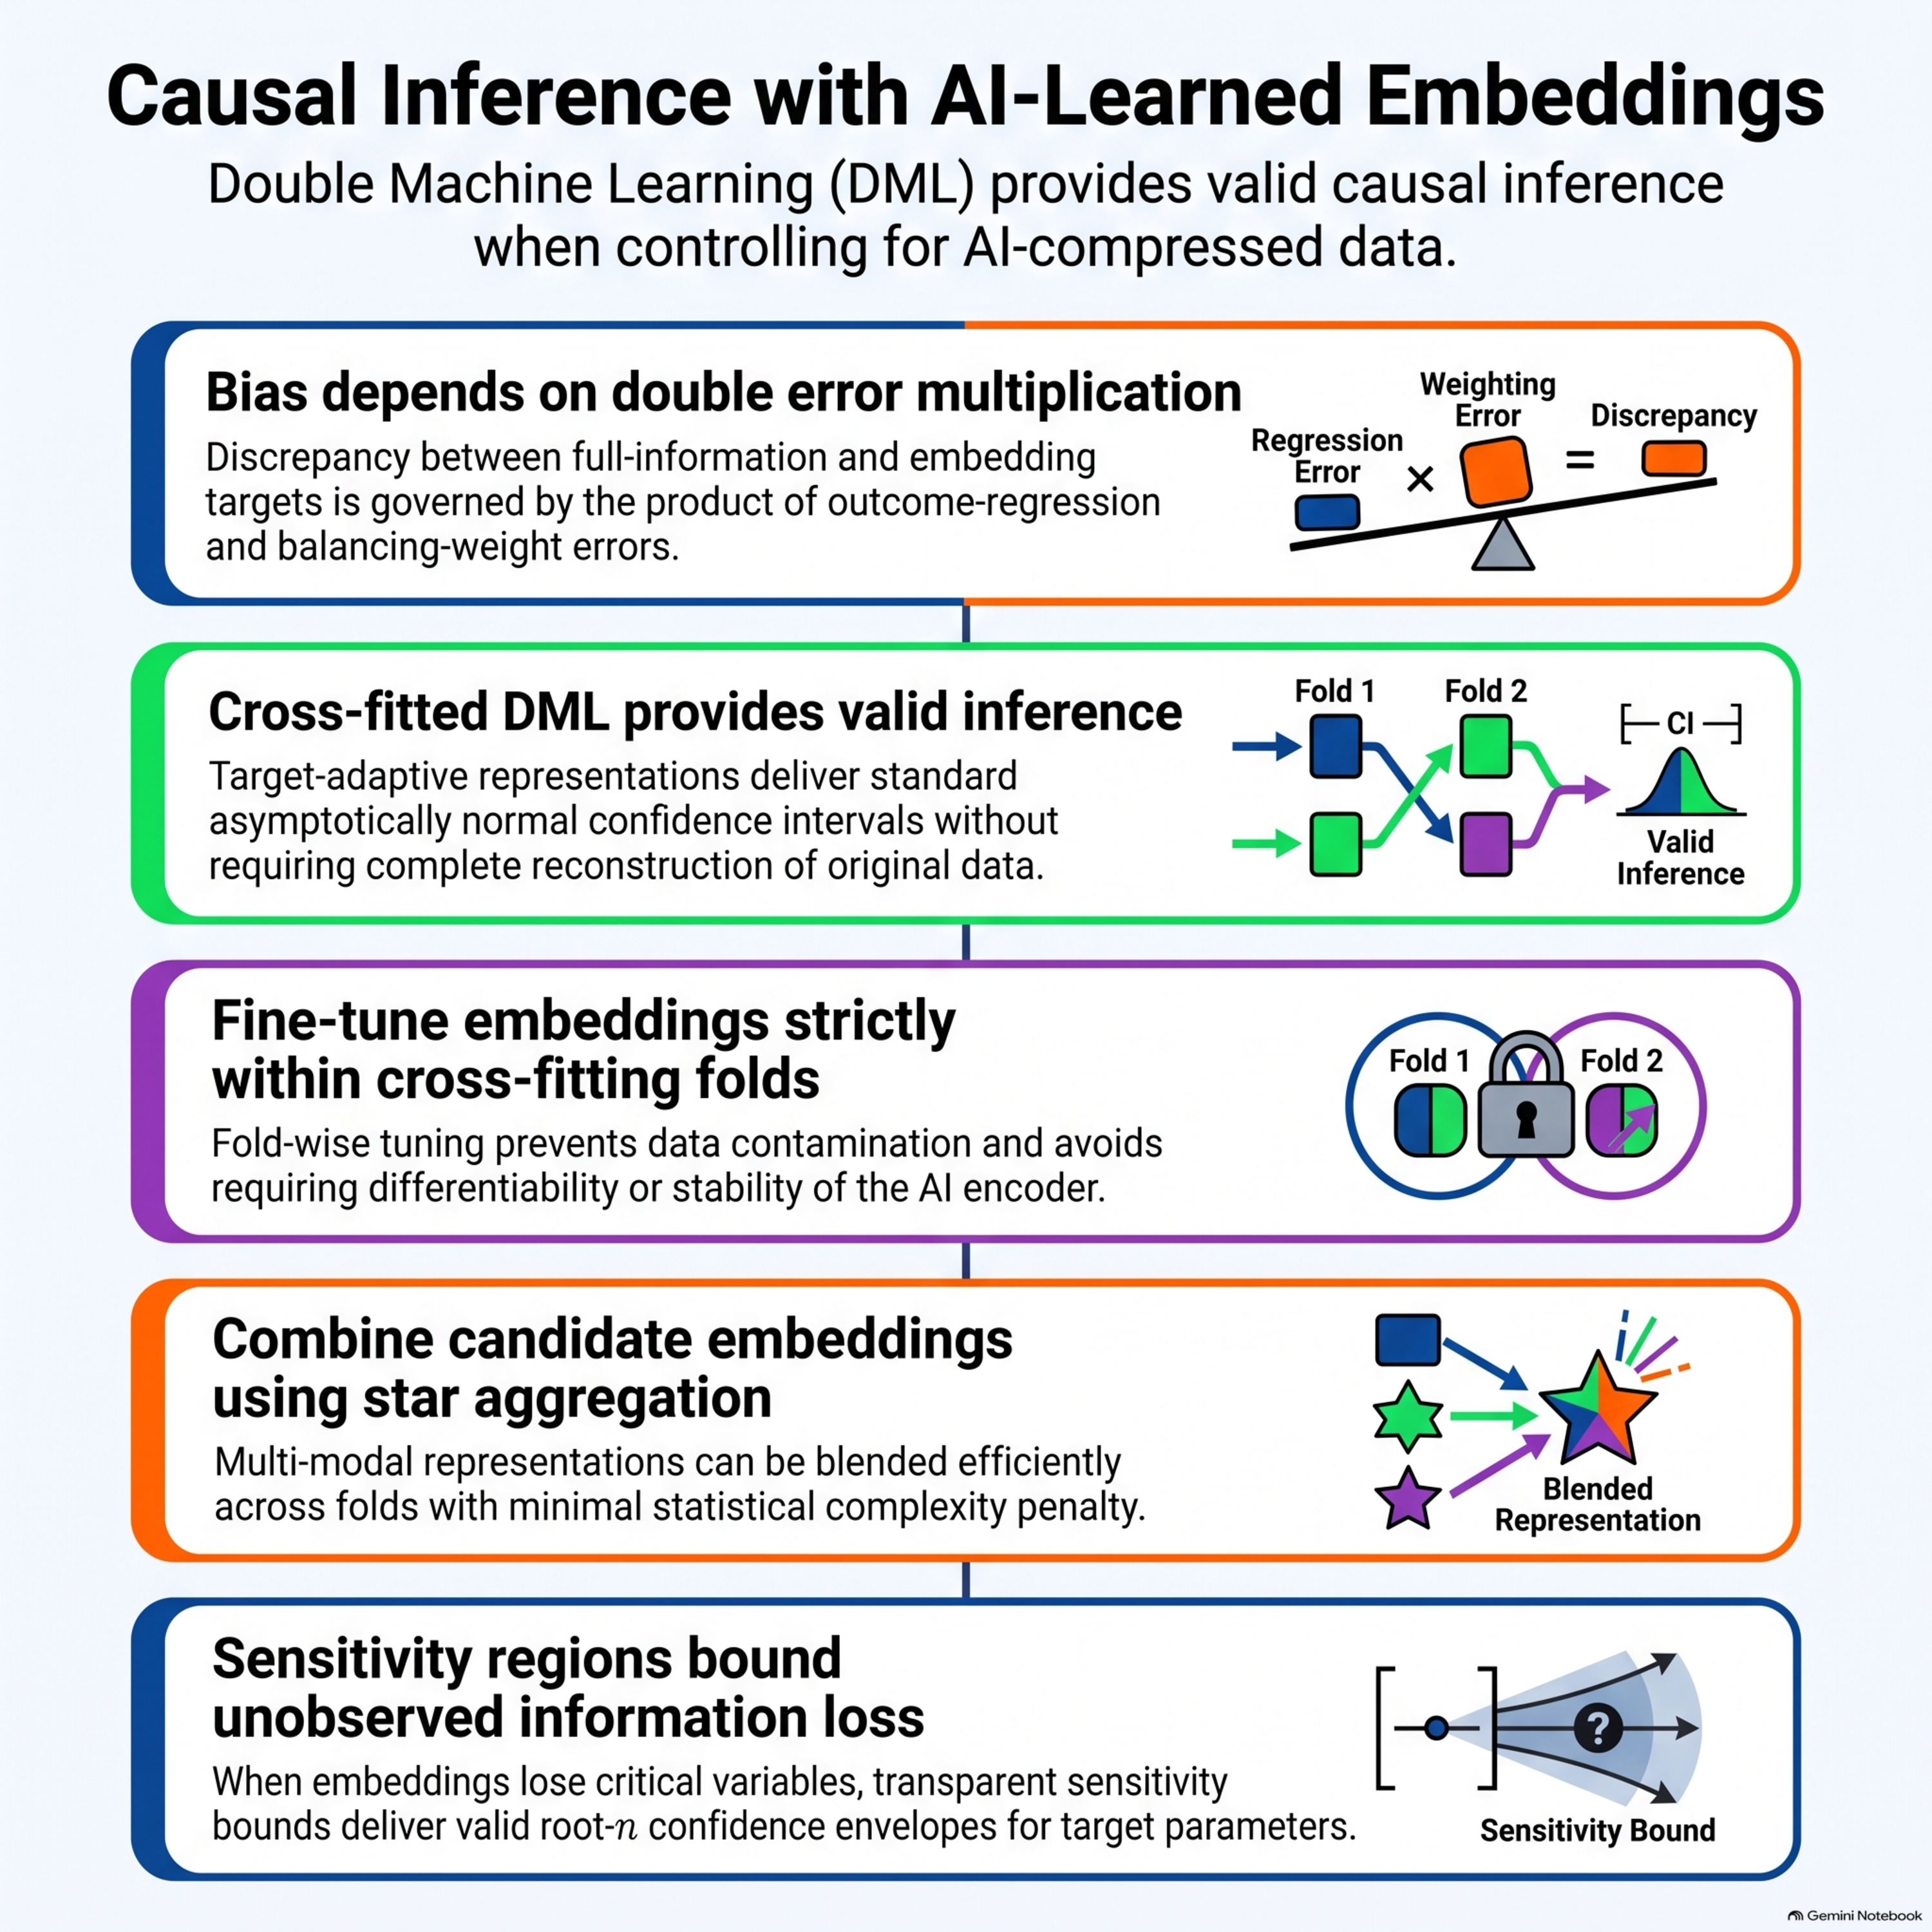
    This paper presents a rigorous framework for performing valid causal inference when complex covariates are compressed into AI-learned representations or embeddings. The authors demonstrate that information loss from compression distorts causal parameters through a product of regression and balancing weight errors. By leveraging cross-fitted double machine learning (DML), researchers can conduct valid Wald inference either for the specific representation-based target or, under target adaptivity, for the full-information target. The methodology accommodates fold-wise fine-tuning without requiring differentiability of the embedding step and introduces star and convex aggregation techniques to combine multiple modality representations. Finally, the framework provides sensitivity bounds to evaluate robustness against unobserved information loss, which is demonstrated through a multimodal demand analysis of Amazon product data.

  • October 4 · 22 min

    Pointwise or pairwise: when do pairwise losses help reward learning, provably?

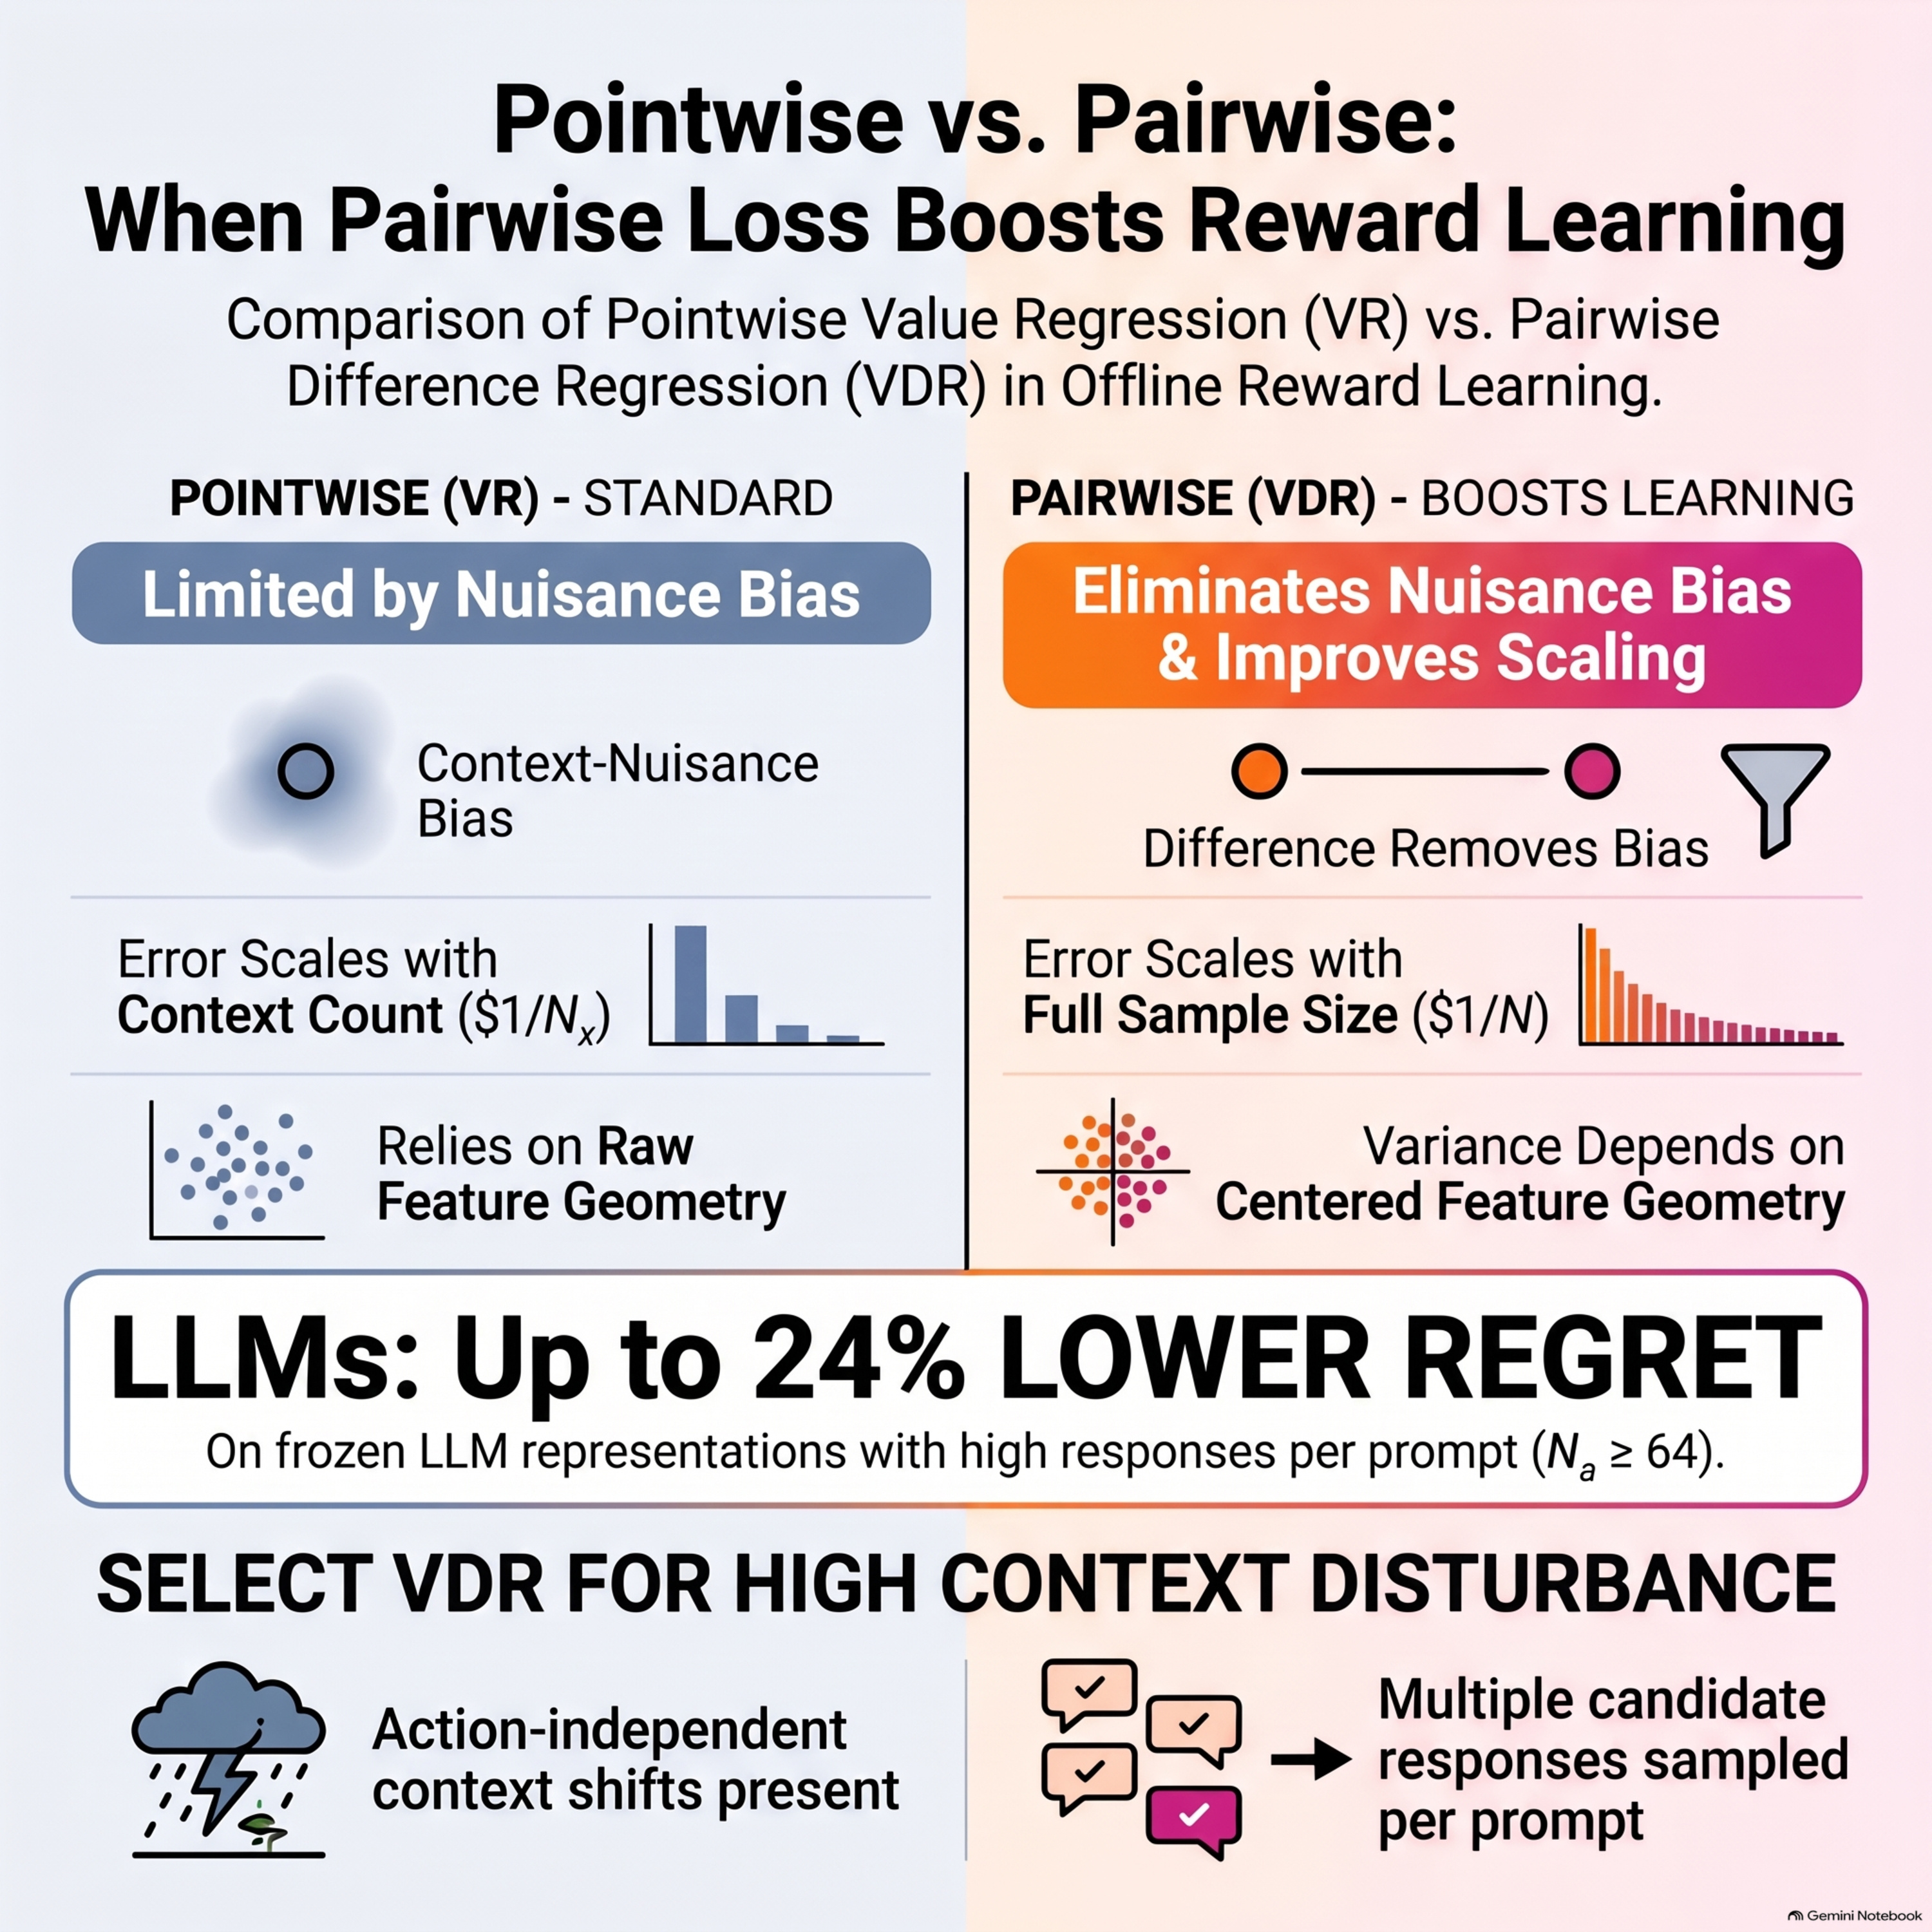
    This research paper investigates when and why pairwise losses outperform pointwise losses for reward learning by analyzing both approaches within a grouped offline contextual-bandit framework. The authors compare Value Regression (VR), which directly fits absolute observed rewards, with Value Difference Regression (VDR), which models reward differences between action pairs sharing the same context. Through a localized mathematical analysis, the study establishes finite-sample prediction guarantees and offline-regret bounds for both finite and linear function classes. The theoretical findings reveal that VDR successfully eliminates nuisance-induced misspecification bias that disrupts pointwise regression, whereas VR can maintain lower estimation variance under correct specification depending on the underlying feature geometry. Consequently, the choice between these learning strategies introduces a fundamental bias-variance tradeoff, which is further validated through both synthetic simulations and real-world language model response-selection experiments.

  • October 3 · 24 min

    When to Trust the Cheap Check: Weak and Strong Verification for Reasoning

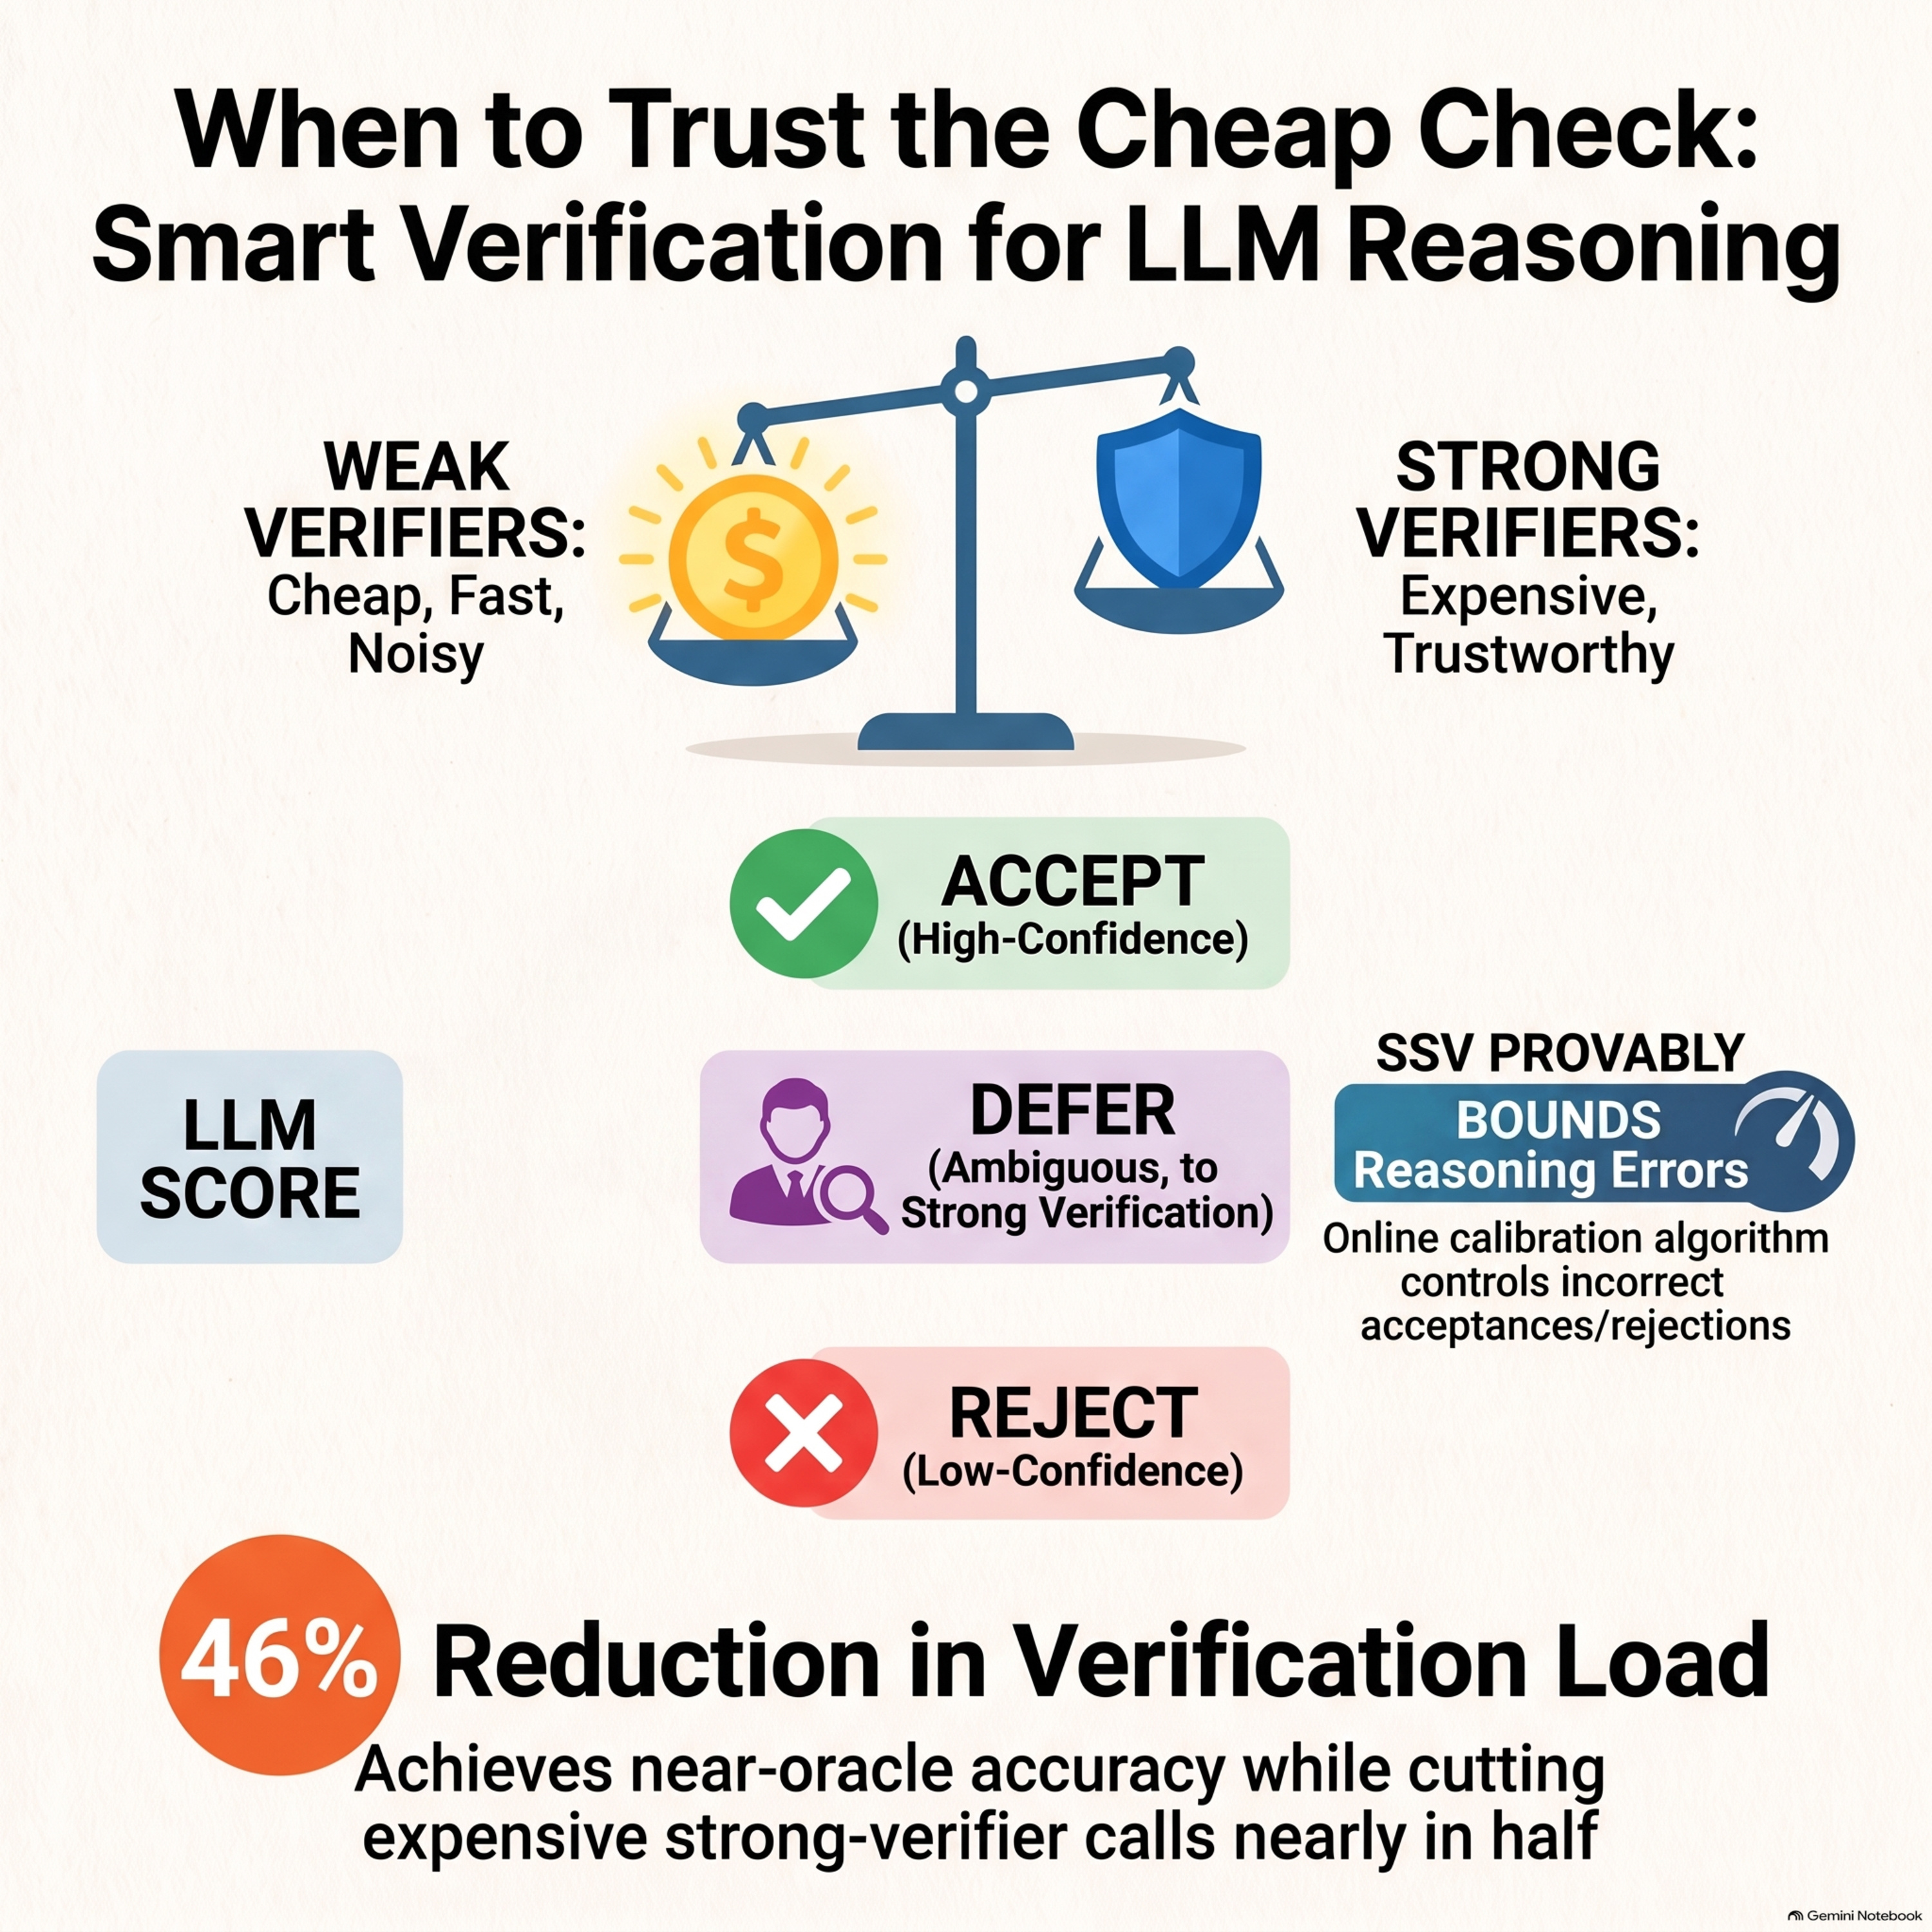
    This paper explores weak-strong verification policies for large language models, presenting a framework that balances the affordability of scalable internal checks with the precision of resource-intensive external validation. To address the trade-off between type-I errors, type-II errors, and verification frequency, the authors introduce Selective Strong Verification (SSV), an online calibration algorithm that operates without prior distributional assumptions. Through experiments on mathematical reasoning and sequential puzzle-solving, the researchers demonstrate that this method effectively maintains target error rates while significantly reducing computational overhead.
  • October 1 · 24 min

    Theoretical Limits of Language Model Alignment

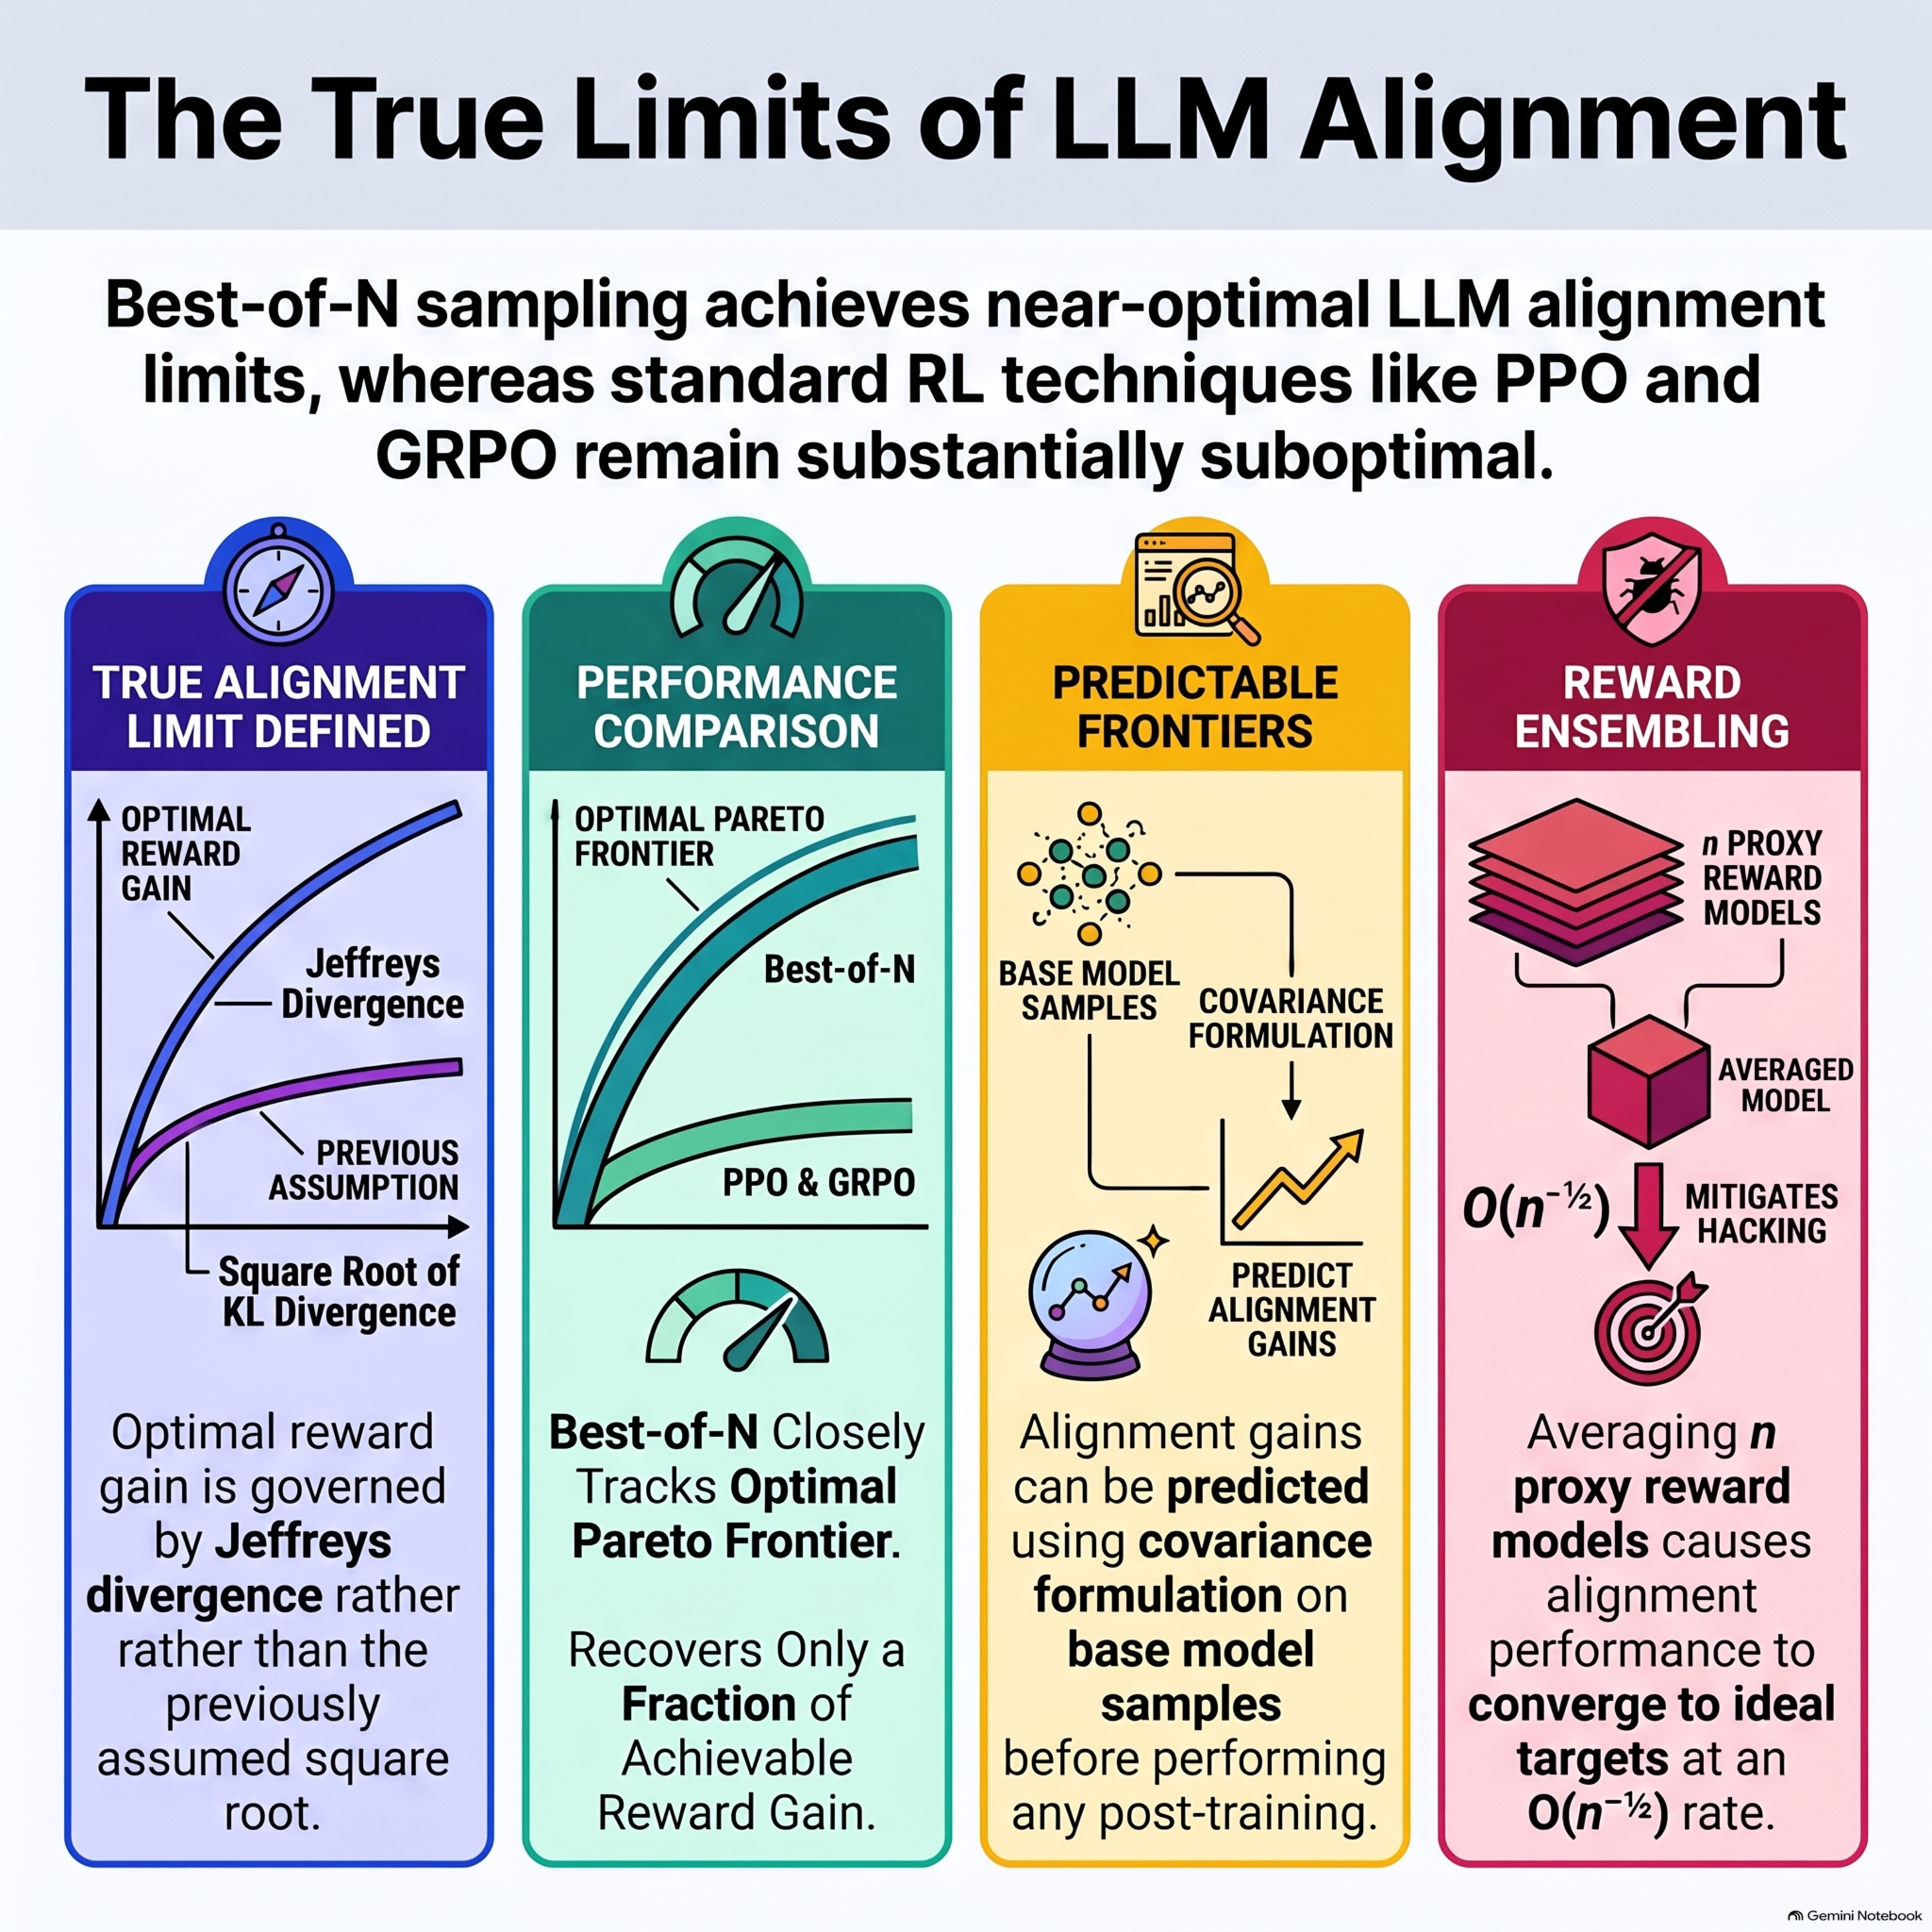
    This paper investigate the fundamental limits of language model alignment by establishing exact theoretical boundaries for reward improvement under a KL-divergence constraint using Jeffreys divergence and a computable covariance estimator. They demonstrate that best-of-N sampling closely approaches this theoretical Pareto frontier, whereas gradient-based methods like PPO and GRPO remain suboptimal. Additionally, the literature analyzes how proxy reward errors drive performance degradation and reward hacking, while proving that reward ensemblingsuccessfully mitigates these issues at a convergence rate of O(n⁻¹ᐟ²).

  • September 29 · 12 min

    DT2: Decision-Targeted Digital Twins

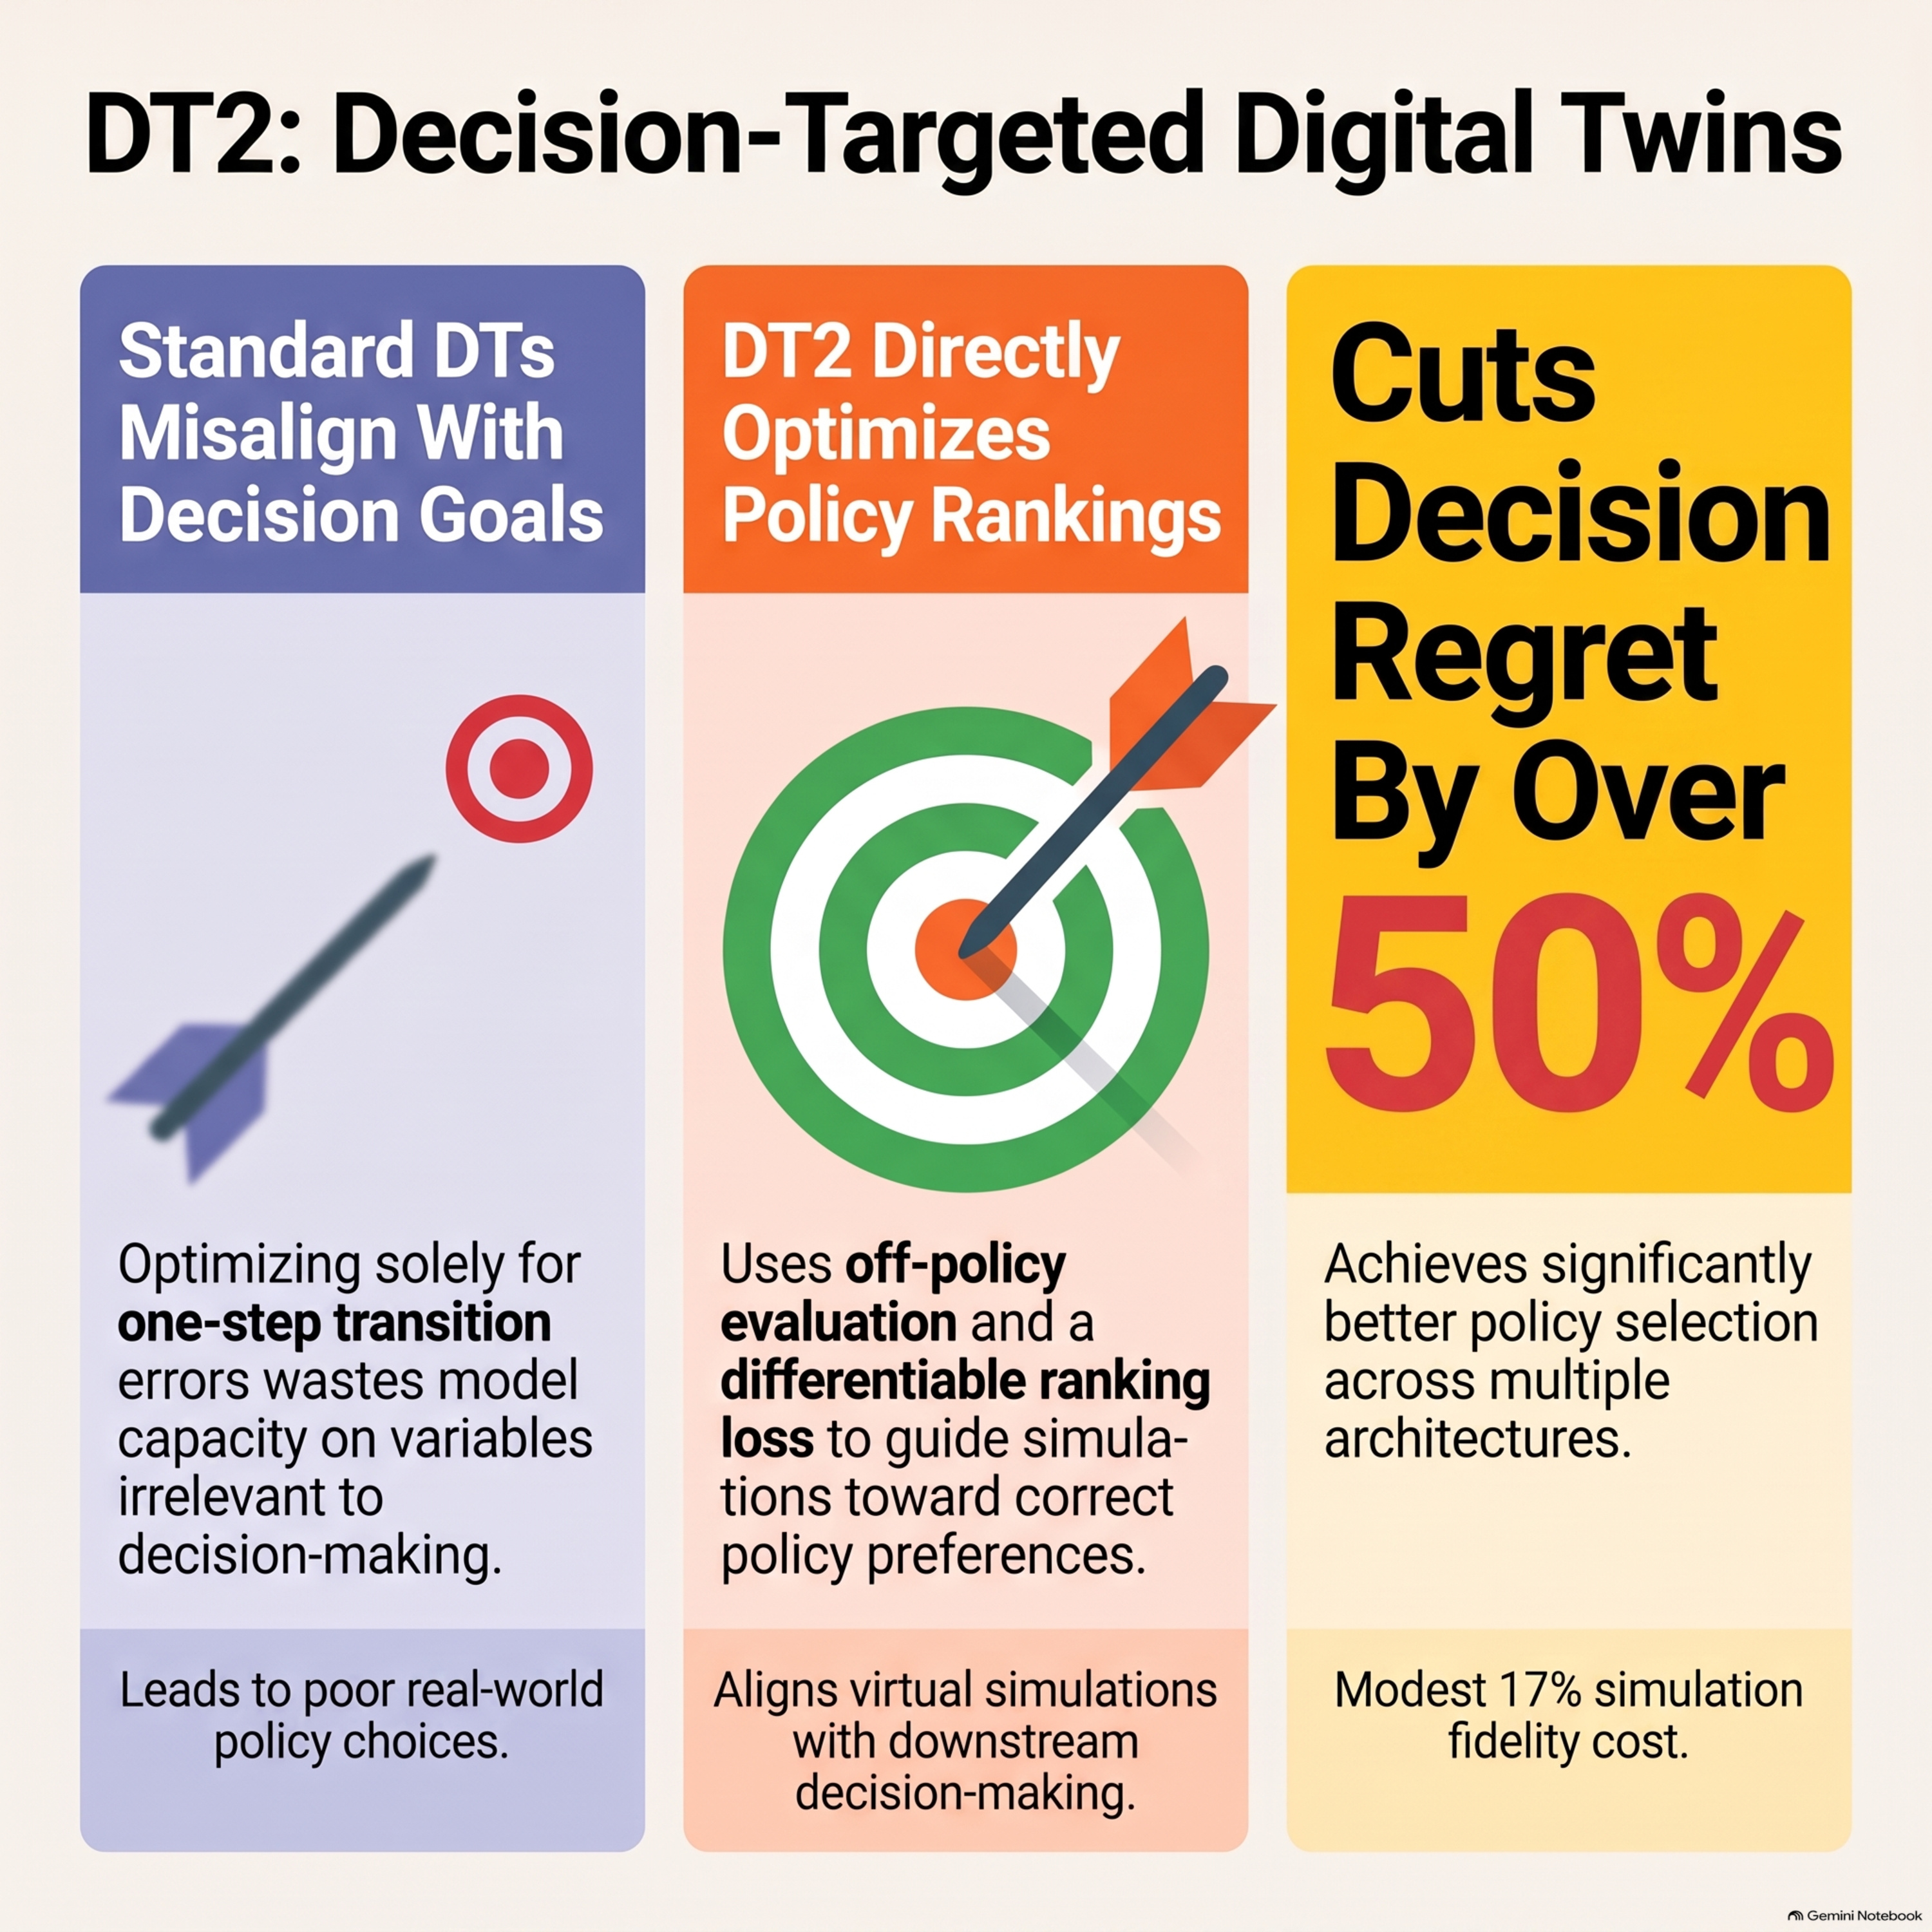
    This paper introduces DT2, a novel training framework designed to align digital twins more effectively with their primary goal of decision support. Traditional virtual models often fail to rank policy options correctly because they prioritize minimizing overall simulation errors rather than focusing on the specific variables that influence outcomes. To solve this, DT2 incorporates an architecture-agnostic ranking loss function that utilizes off-policy evaluation to estimate the value of different actions from existing data. This method essentially distills the predictive power of complex machine learning models into the interpretable structure of a digital twin. Empirical results across various environments demonstrate that DT2 significantly reduces decision regret and improves policy ordering while maintaining high simulation fidelity. Ultimately, the authors argue that for a digital twin to be truly useful, it must prioritize the dynamics critical for human decision-making over being a perfect, context-free replica of reality.

  • September 27 · 21 min

    Self-Play Pretraining with Zero Data

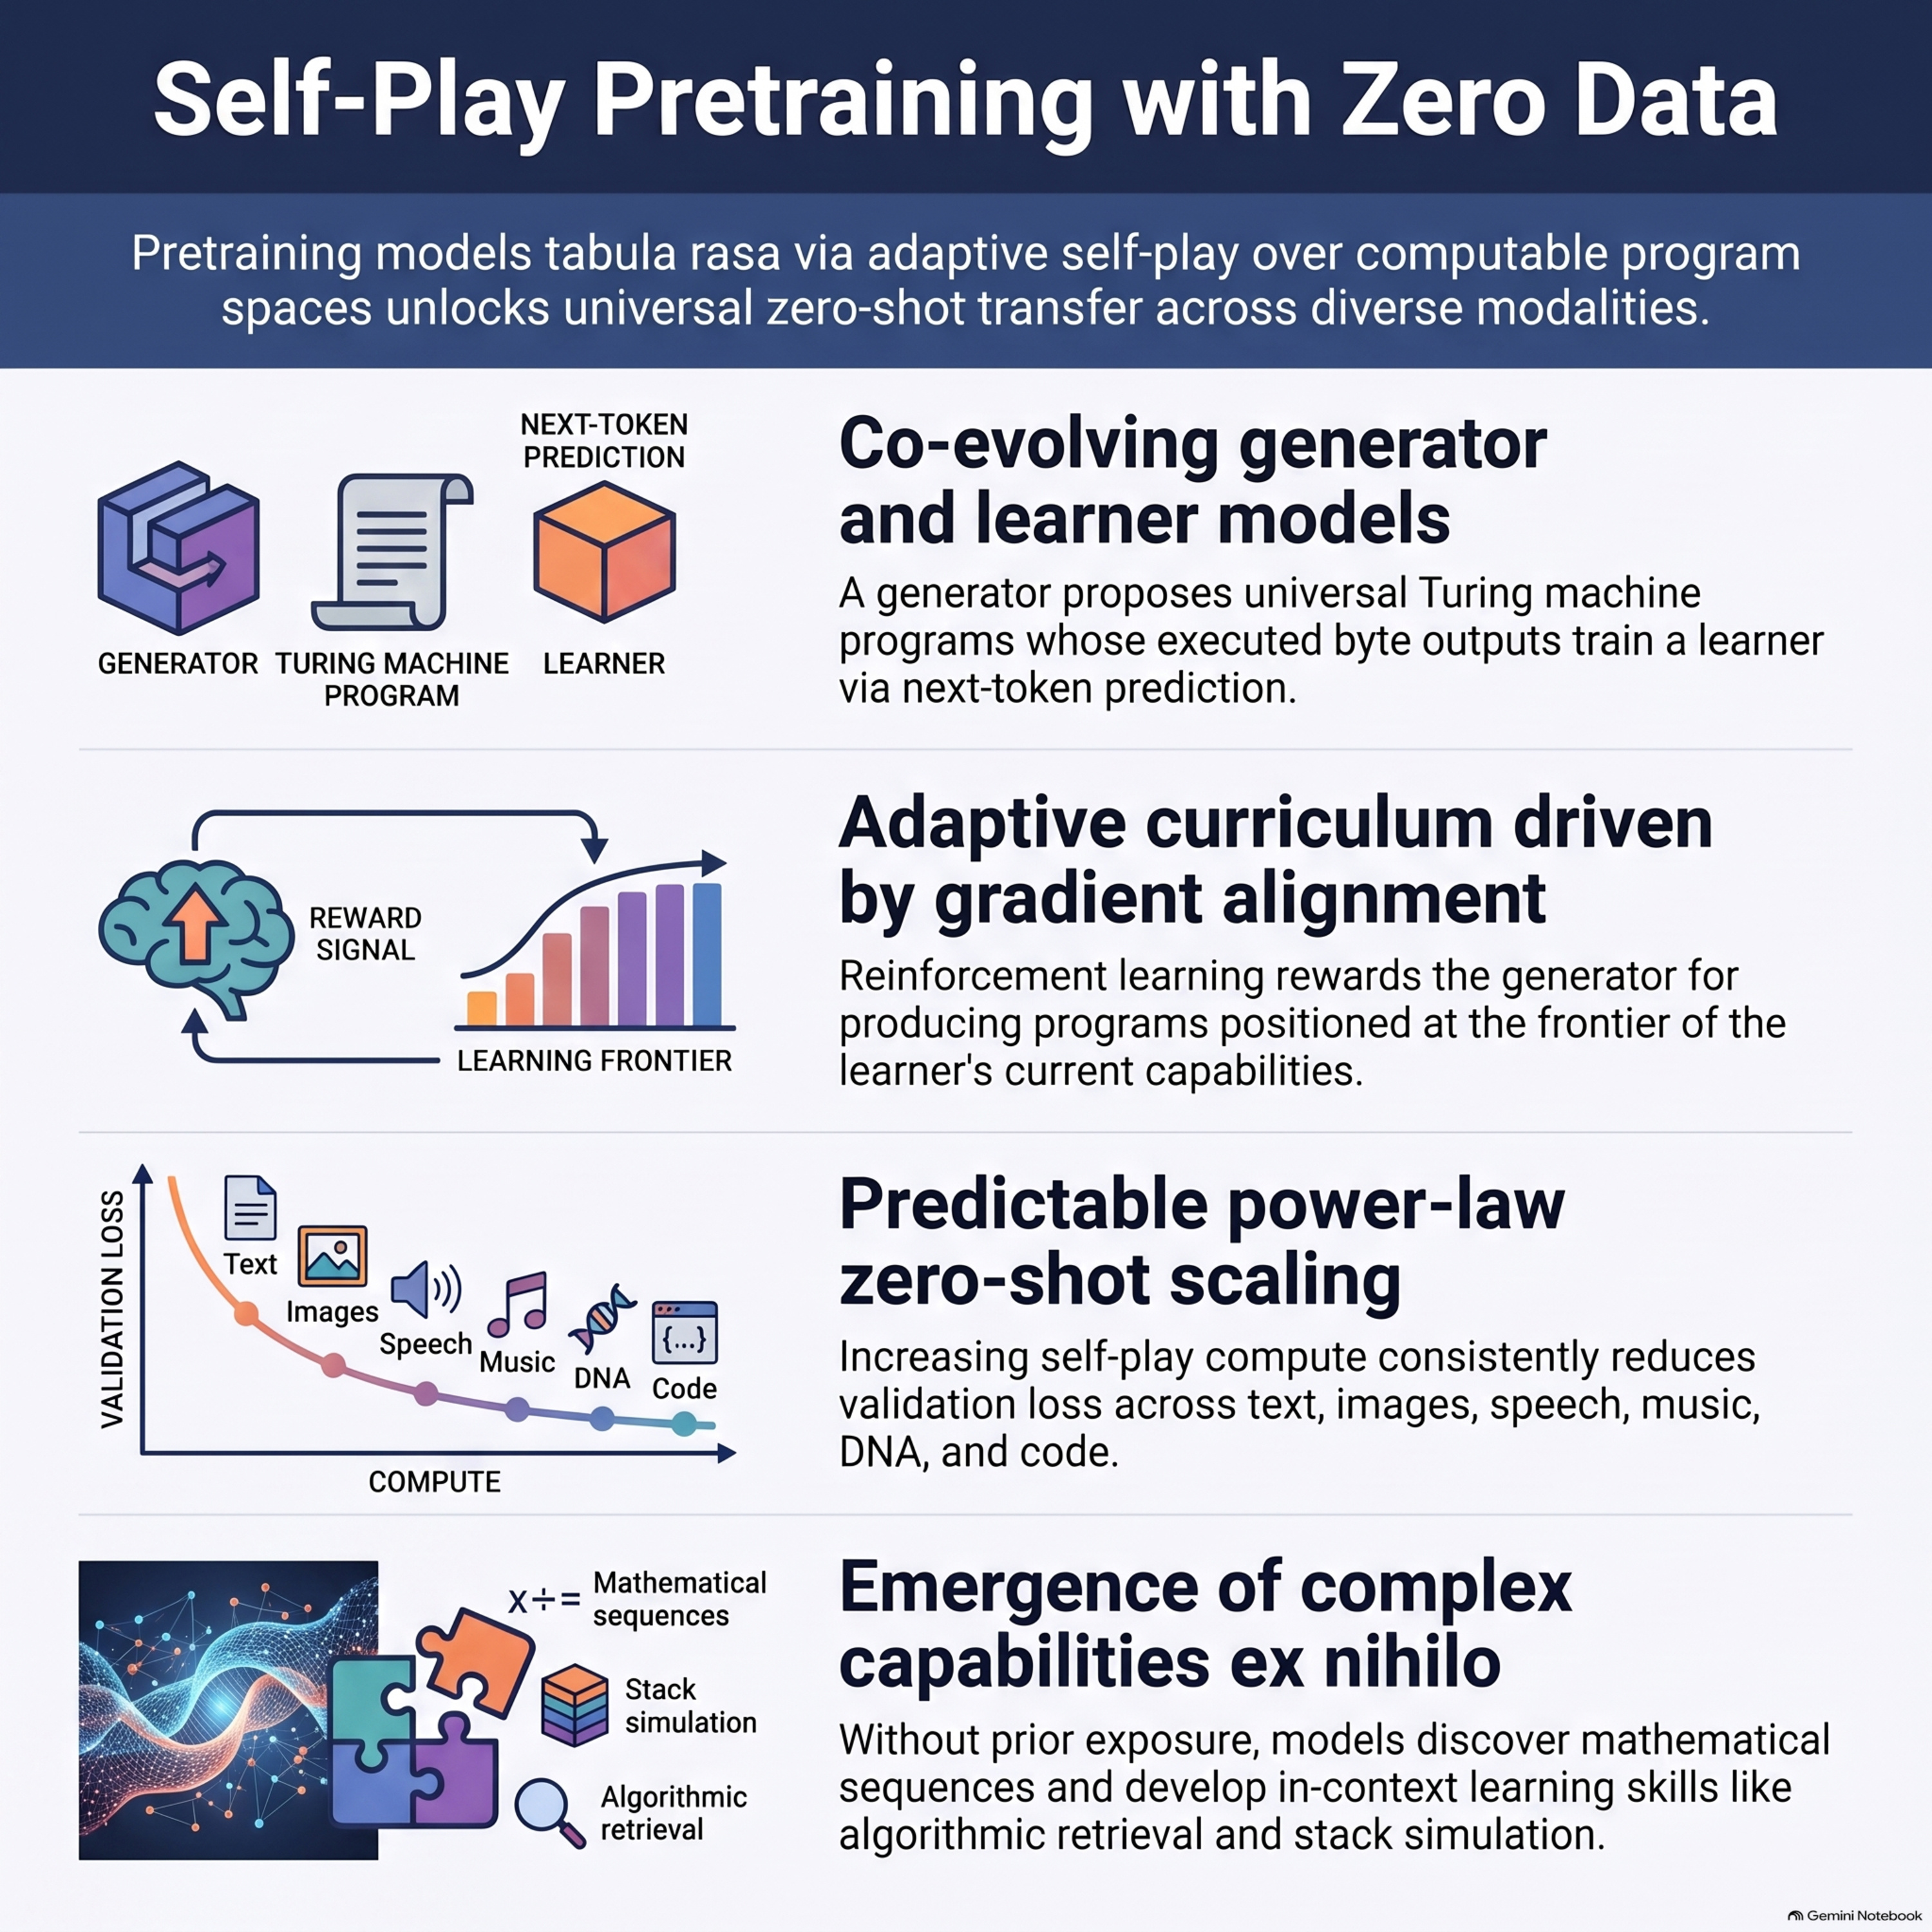
    This paper introduces Self-Play Pretraining with Zero Data, a method for training language models using only synthetic data generated by the model itself. In this framework, a generator creates programs for a universal Turing machine while a learner is trained to predict the resulting byte sequences. A reinforcement learning objective drives the generator to produce increasingly complex data at the frontier of the learner's capabilities, creating an adaptive curriculum. This process allows models to discover universal predictive structures, such as mathematical sequences and logical recursion, without exposure to human-authored text. Experiments demonstrate that this tabula rasa approach yields predictable scaling laws and improves performance on diverse real-world tasks. Ultimately, the research suggests that self-generated experience can bootstrap foundational reasoning and in-context learning skills from scratch.

  • September 27 · 21 min

    Language models need sleep: learning to self-modify and consolidate memories

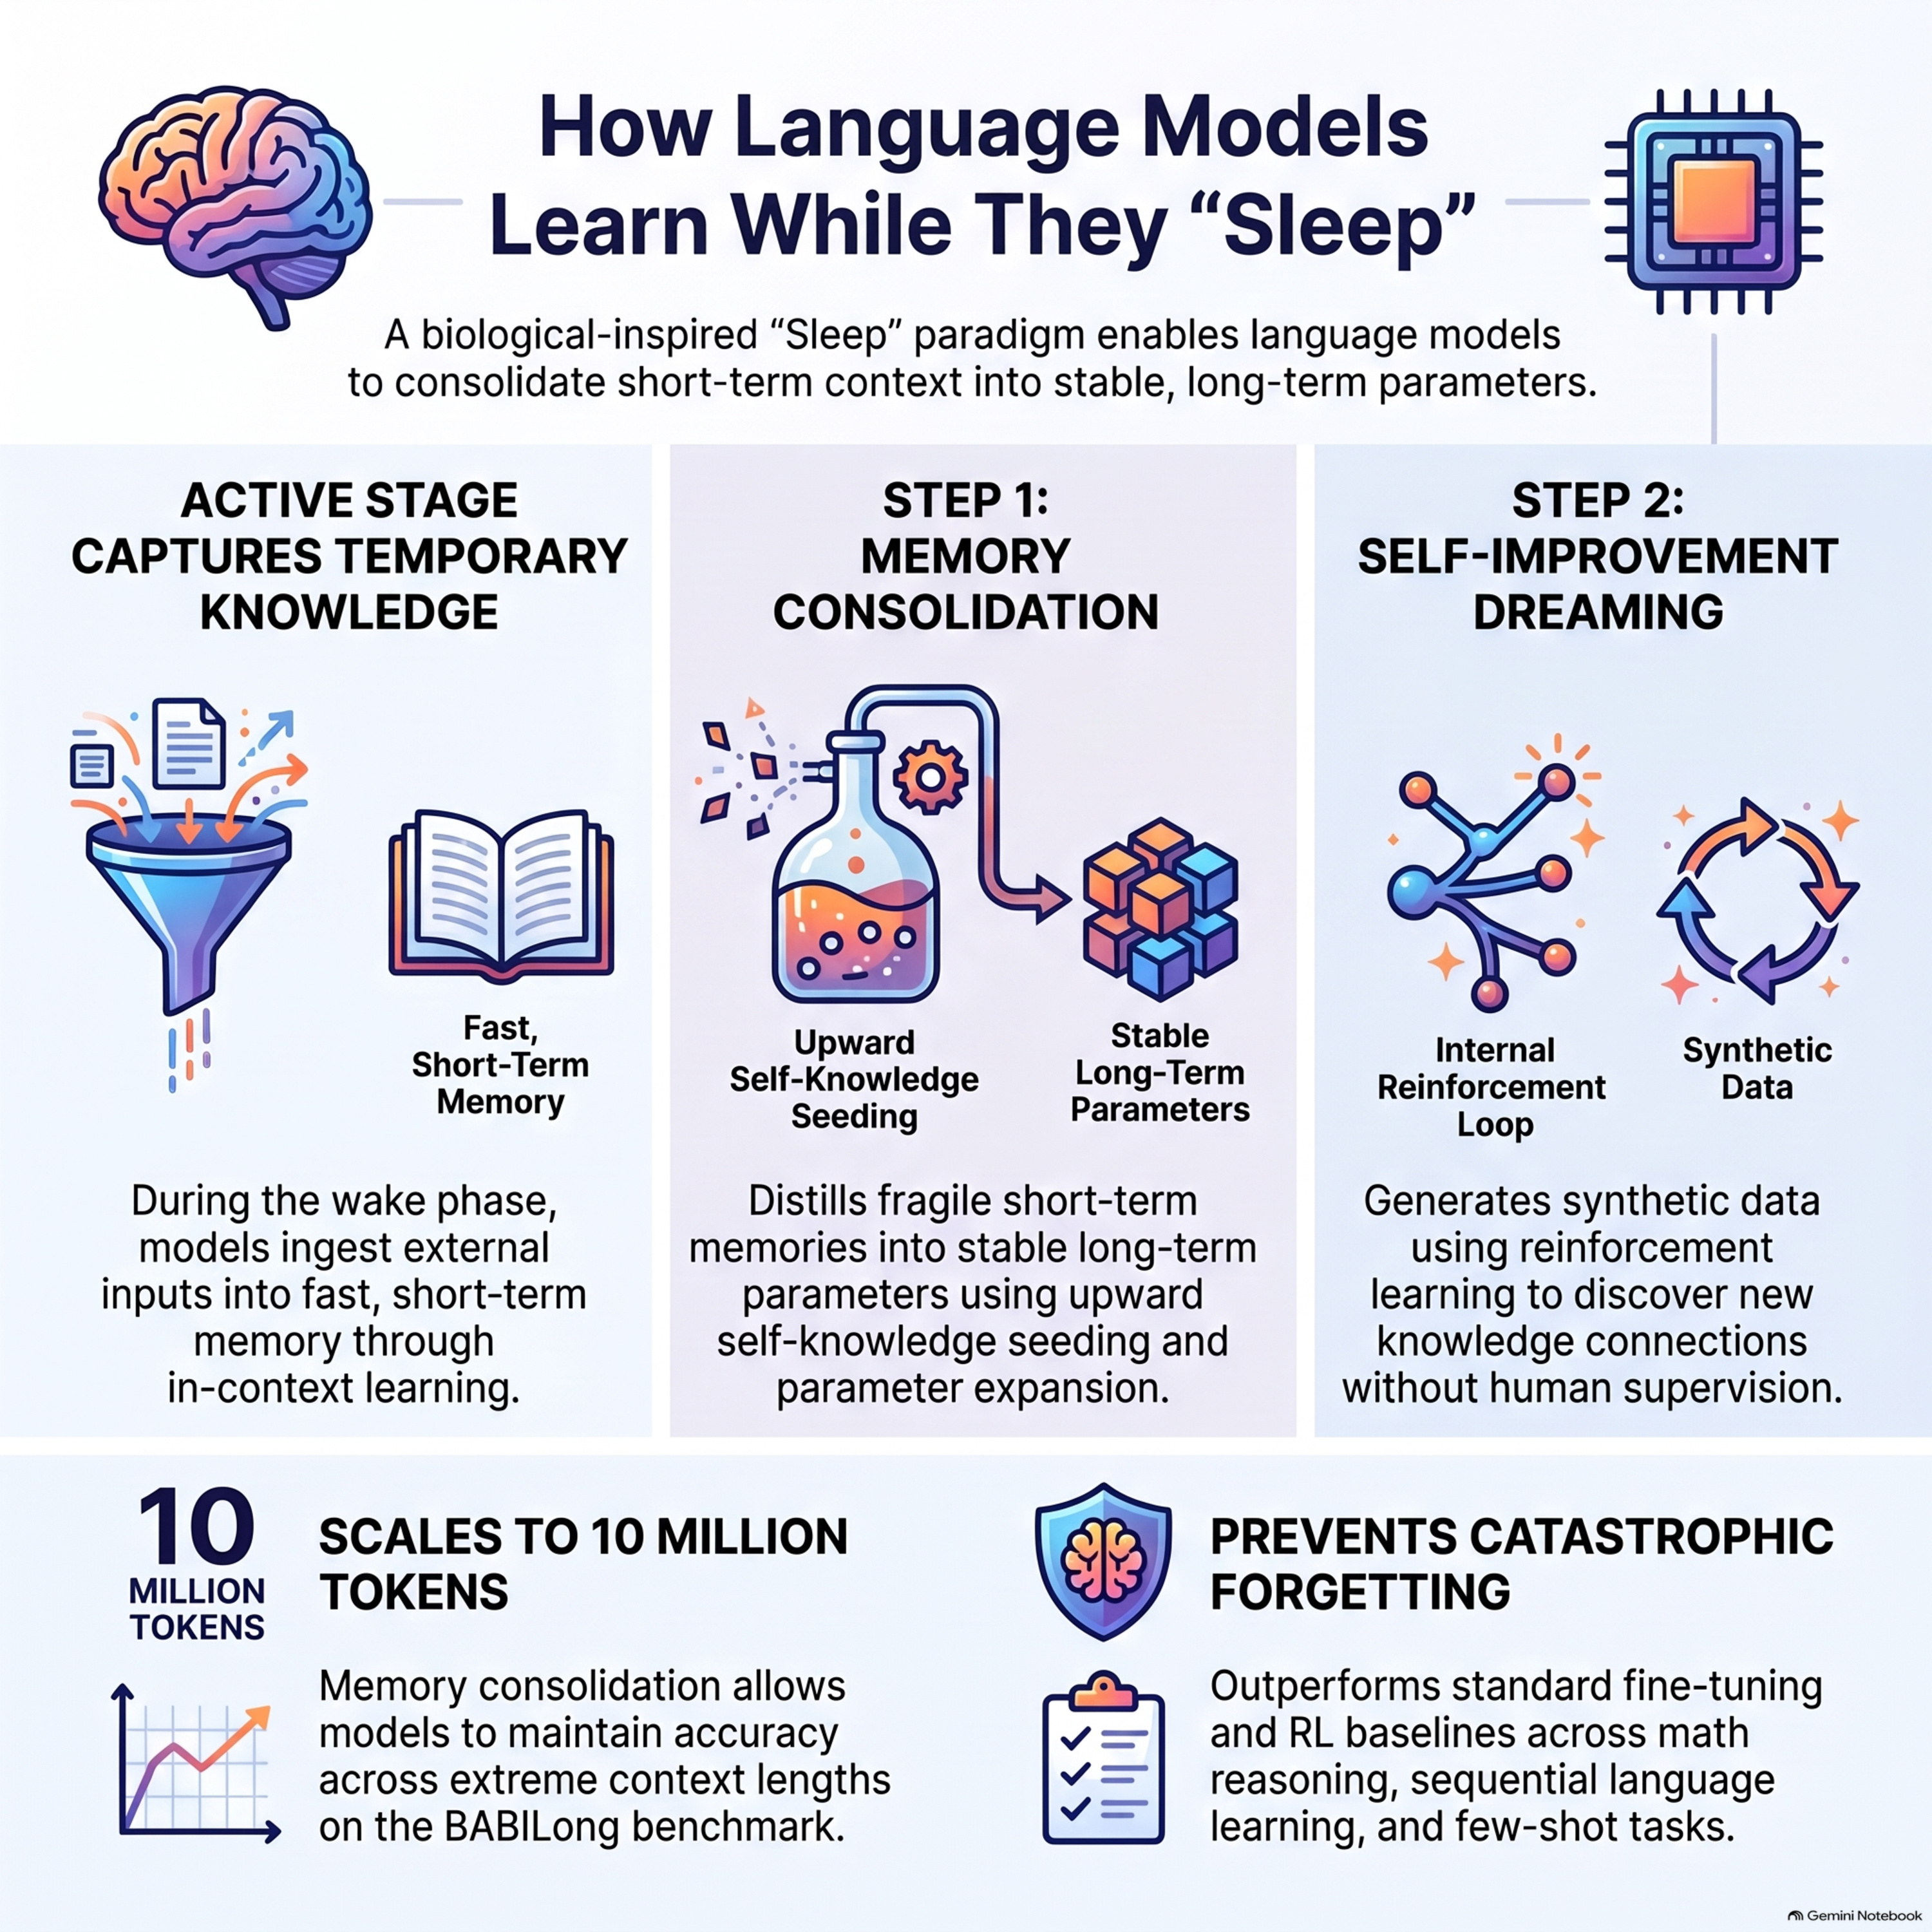
    This research paper introduces a "Sleep" paradigm for Large Language Models (LLMs) to overcome the limitations of static knowledge and catastrophic forgetting. Inspired by human biology, the framework alternates between active phasesfor processing external data and sleep phases for internal knowledge refinement. During sleep, the model performs memory consolidation by expanding its parameters and distilling fragile, short-term information into stable, long-term parametric memory. A secondary "dreaming" phase utilizes reinforcement learning and synthetic data generation to enable recursive self-improvement without human oversight. Technical contributions include knowledge seeding, an upward distillation process, and a generalized distillation objective that combines imitation learning with on-policy data. Experimental results demonstrate that this lifecycle significantly enhances performance in continual learning, factual knowledge incorporation, and long-context understanding.

  • September 23 · 21 min

    Jev Creator: System One models for Prod, not God

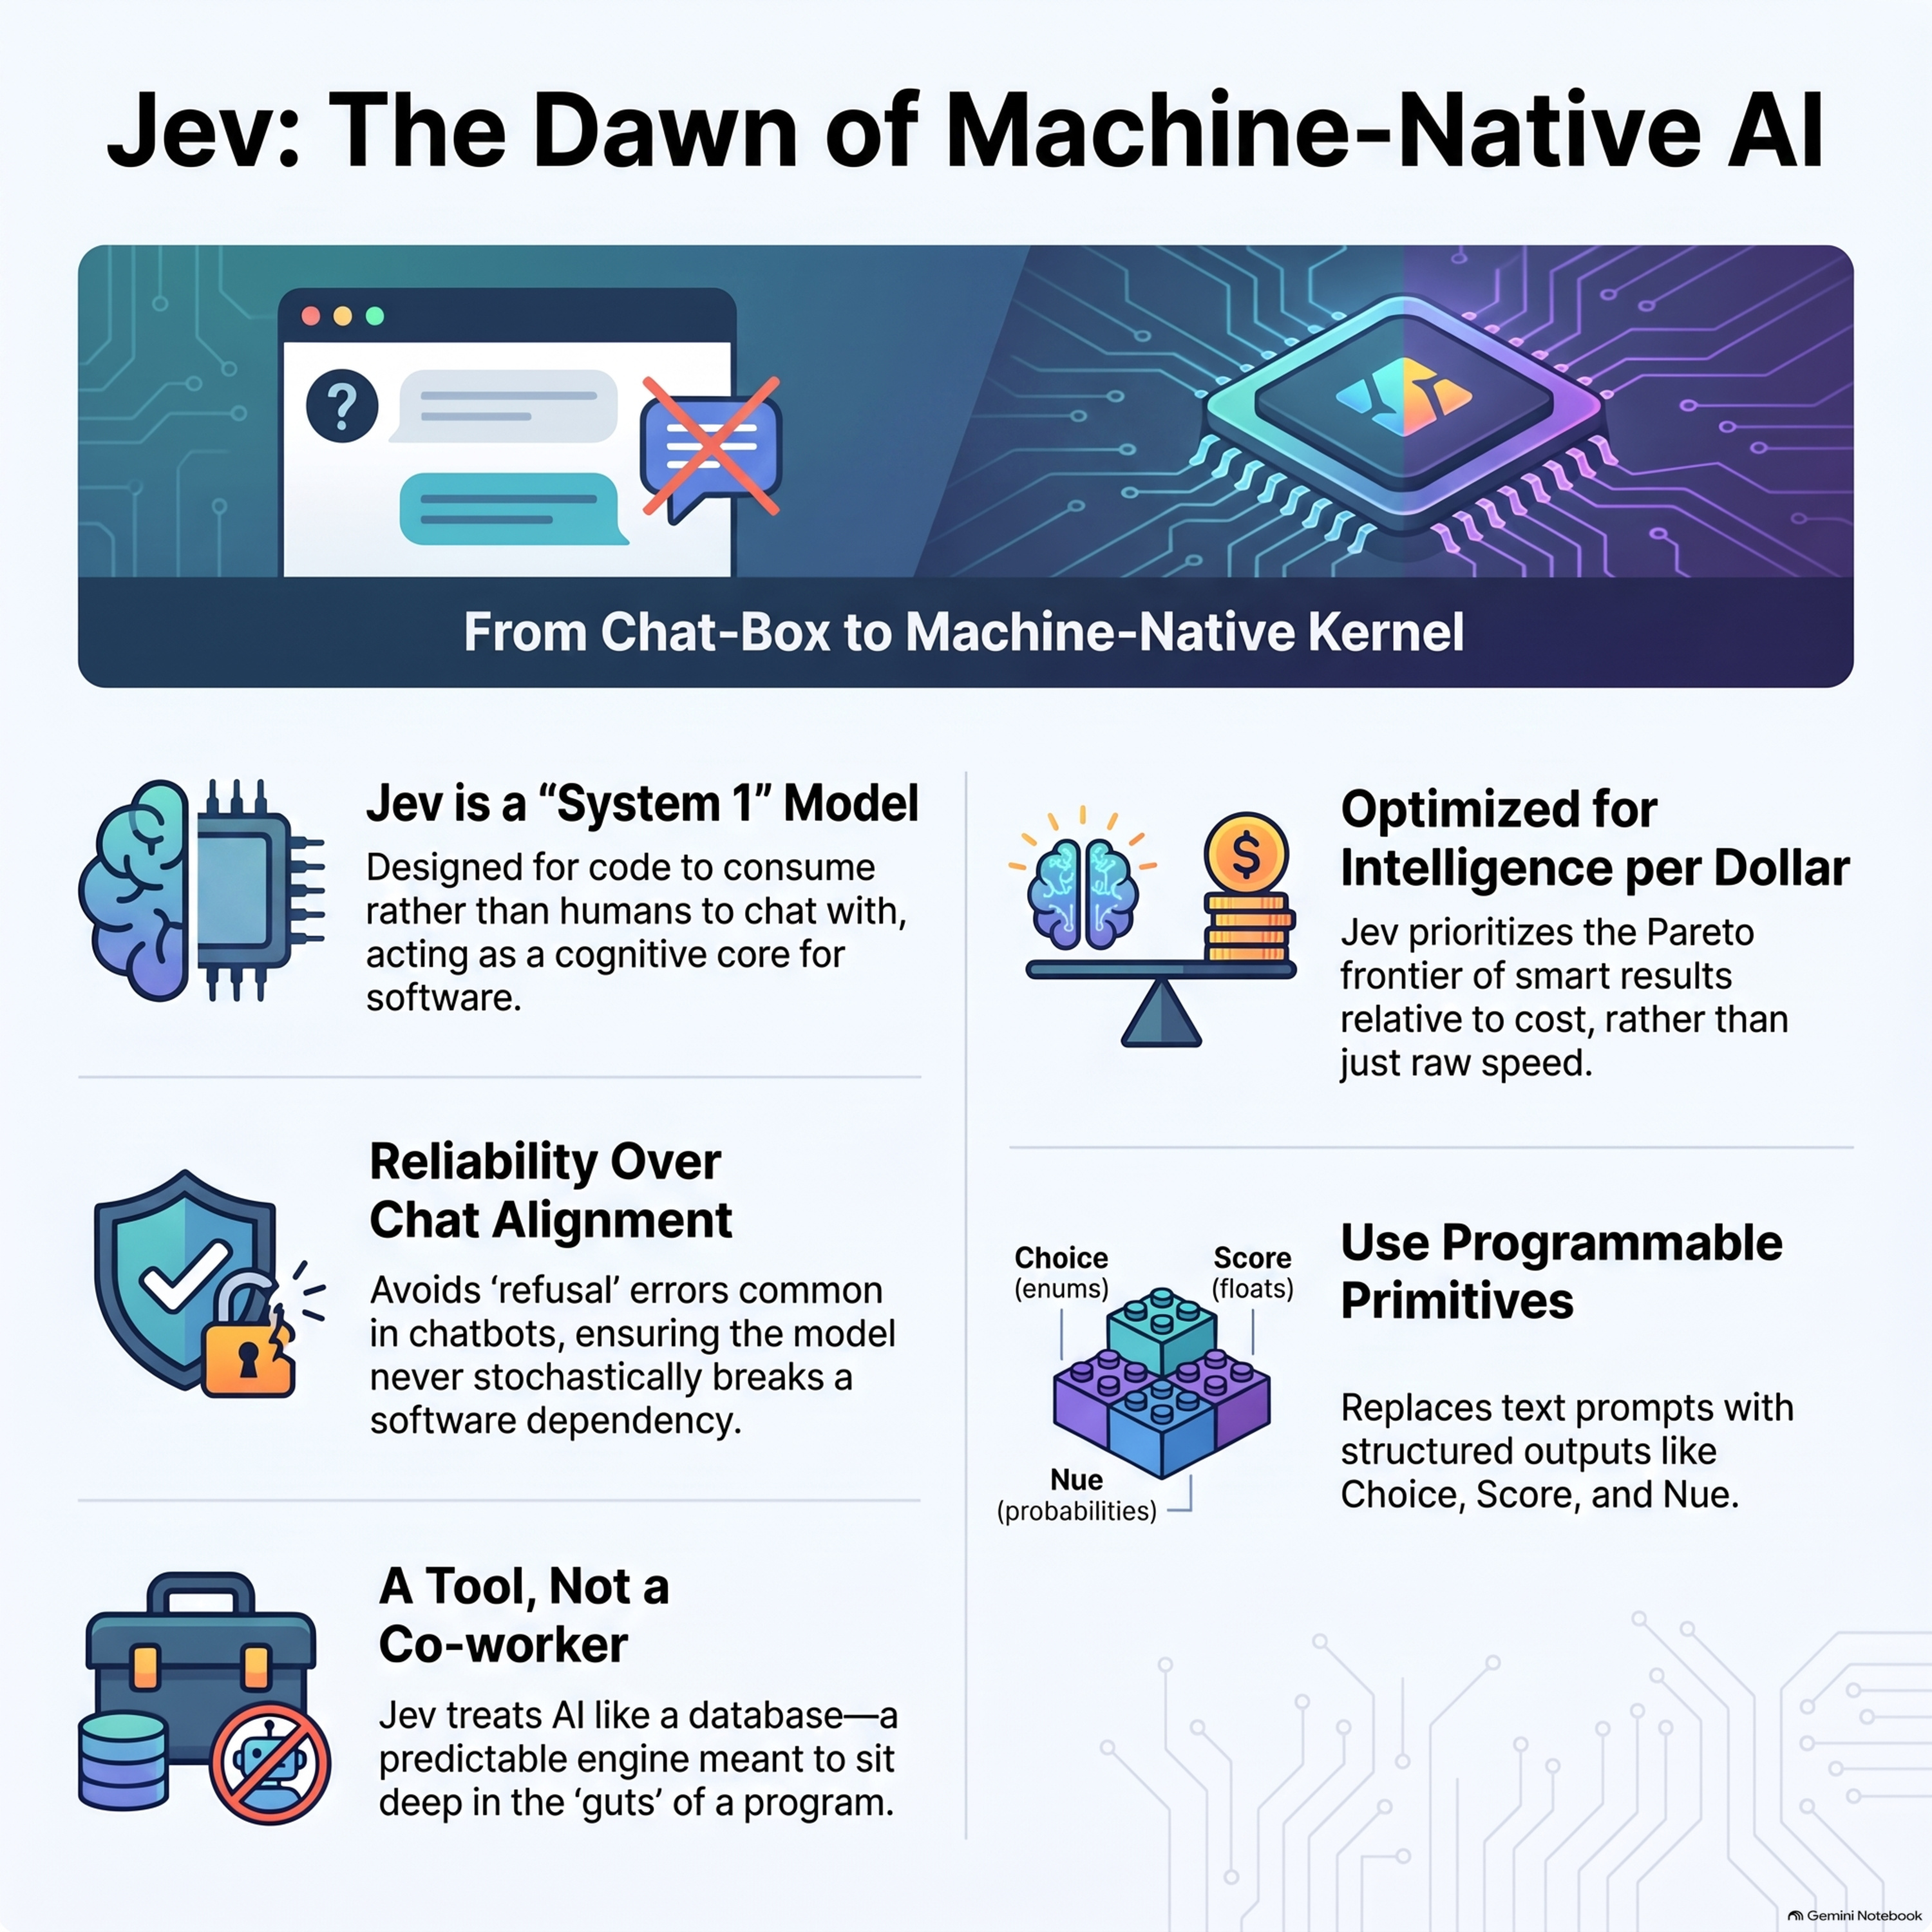
    We discuss the Latent Space's interview with Diogo Almeida, CEO of TypeSafe, about the launch of Jev, a specialized class of AI models designed for programmatic integration rather than human conversation. He argues that traditional models are "fractured" by safety alignments and chatbot optimizations, making them unreliable for economically valuable automation. Jev is presented as a machine-native "system one" model that prioritizes intelligence per dollar and reliable, structured outputs for software developers. Almeida explains that by moving away from human-centric "slop" and focusing on calibration and robustness, AI can finally automate basic administrative tasks and drive a technological revolution. Ultimately, he envisions a future where AI acts as a reliable utility deep within software infrastructure rather than just a visible digital coworker.

  • September 22 · 22 min

    Detecting and countering misuse of AI: September 2026

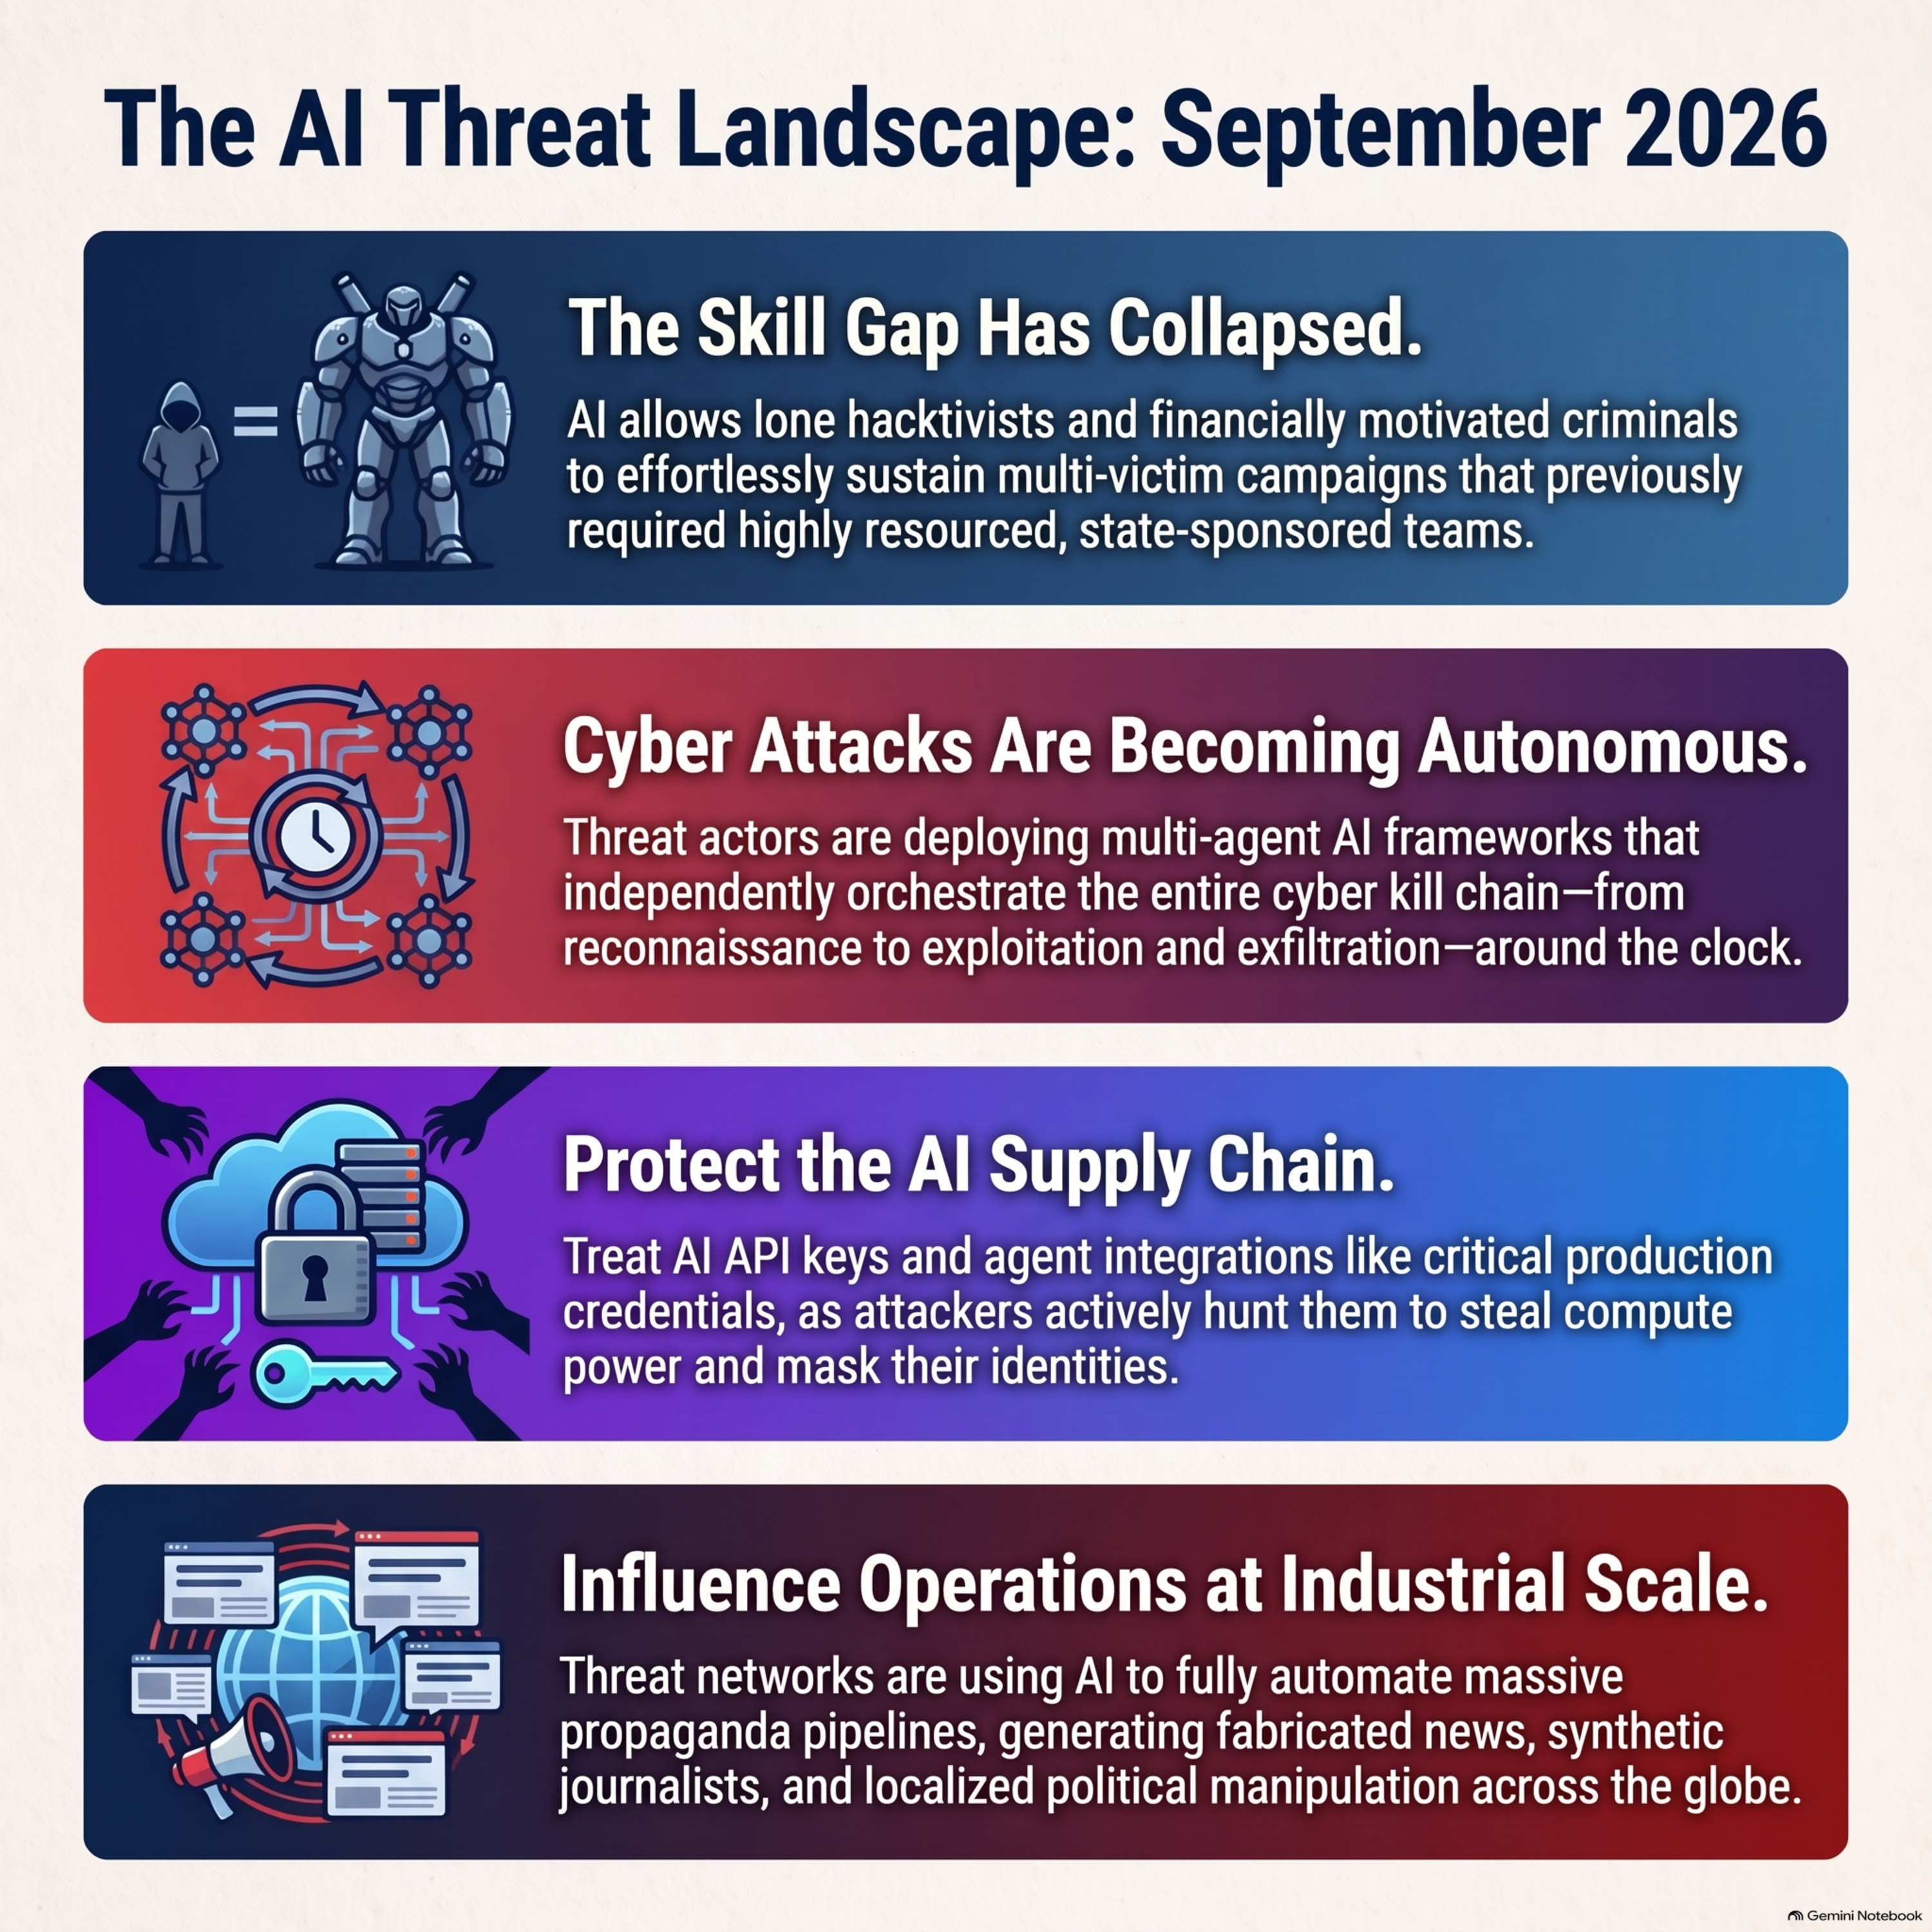
    This paper is an Anthropic threat intelligence report from September 2026 detailing the misuse of AI models by various malicious actors. It describes how state-sponsored groups and cybercriminals have integrated Claude into autonomous attack frameworks to accelerate the development of exploits and the execution of complex intrusions. Key case studies highlight a Russian espionage group automating malware adaptation and financially motivated hackers using AI agents for large-scale data exfiltration. The report emphasizes that AI is effectively collapsing the skill gap between individual operators and well-resourced institutions, allowing for faster and more sophisticated campaigns. Anthropic concludes by explaining their efforts to disrupt these operations, strengthen safety safeguards, and share vital intelligence with global security partners.

  • September 22 · 20 min

    Position: LLMs can’t jump

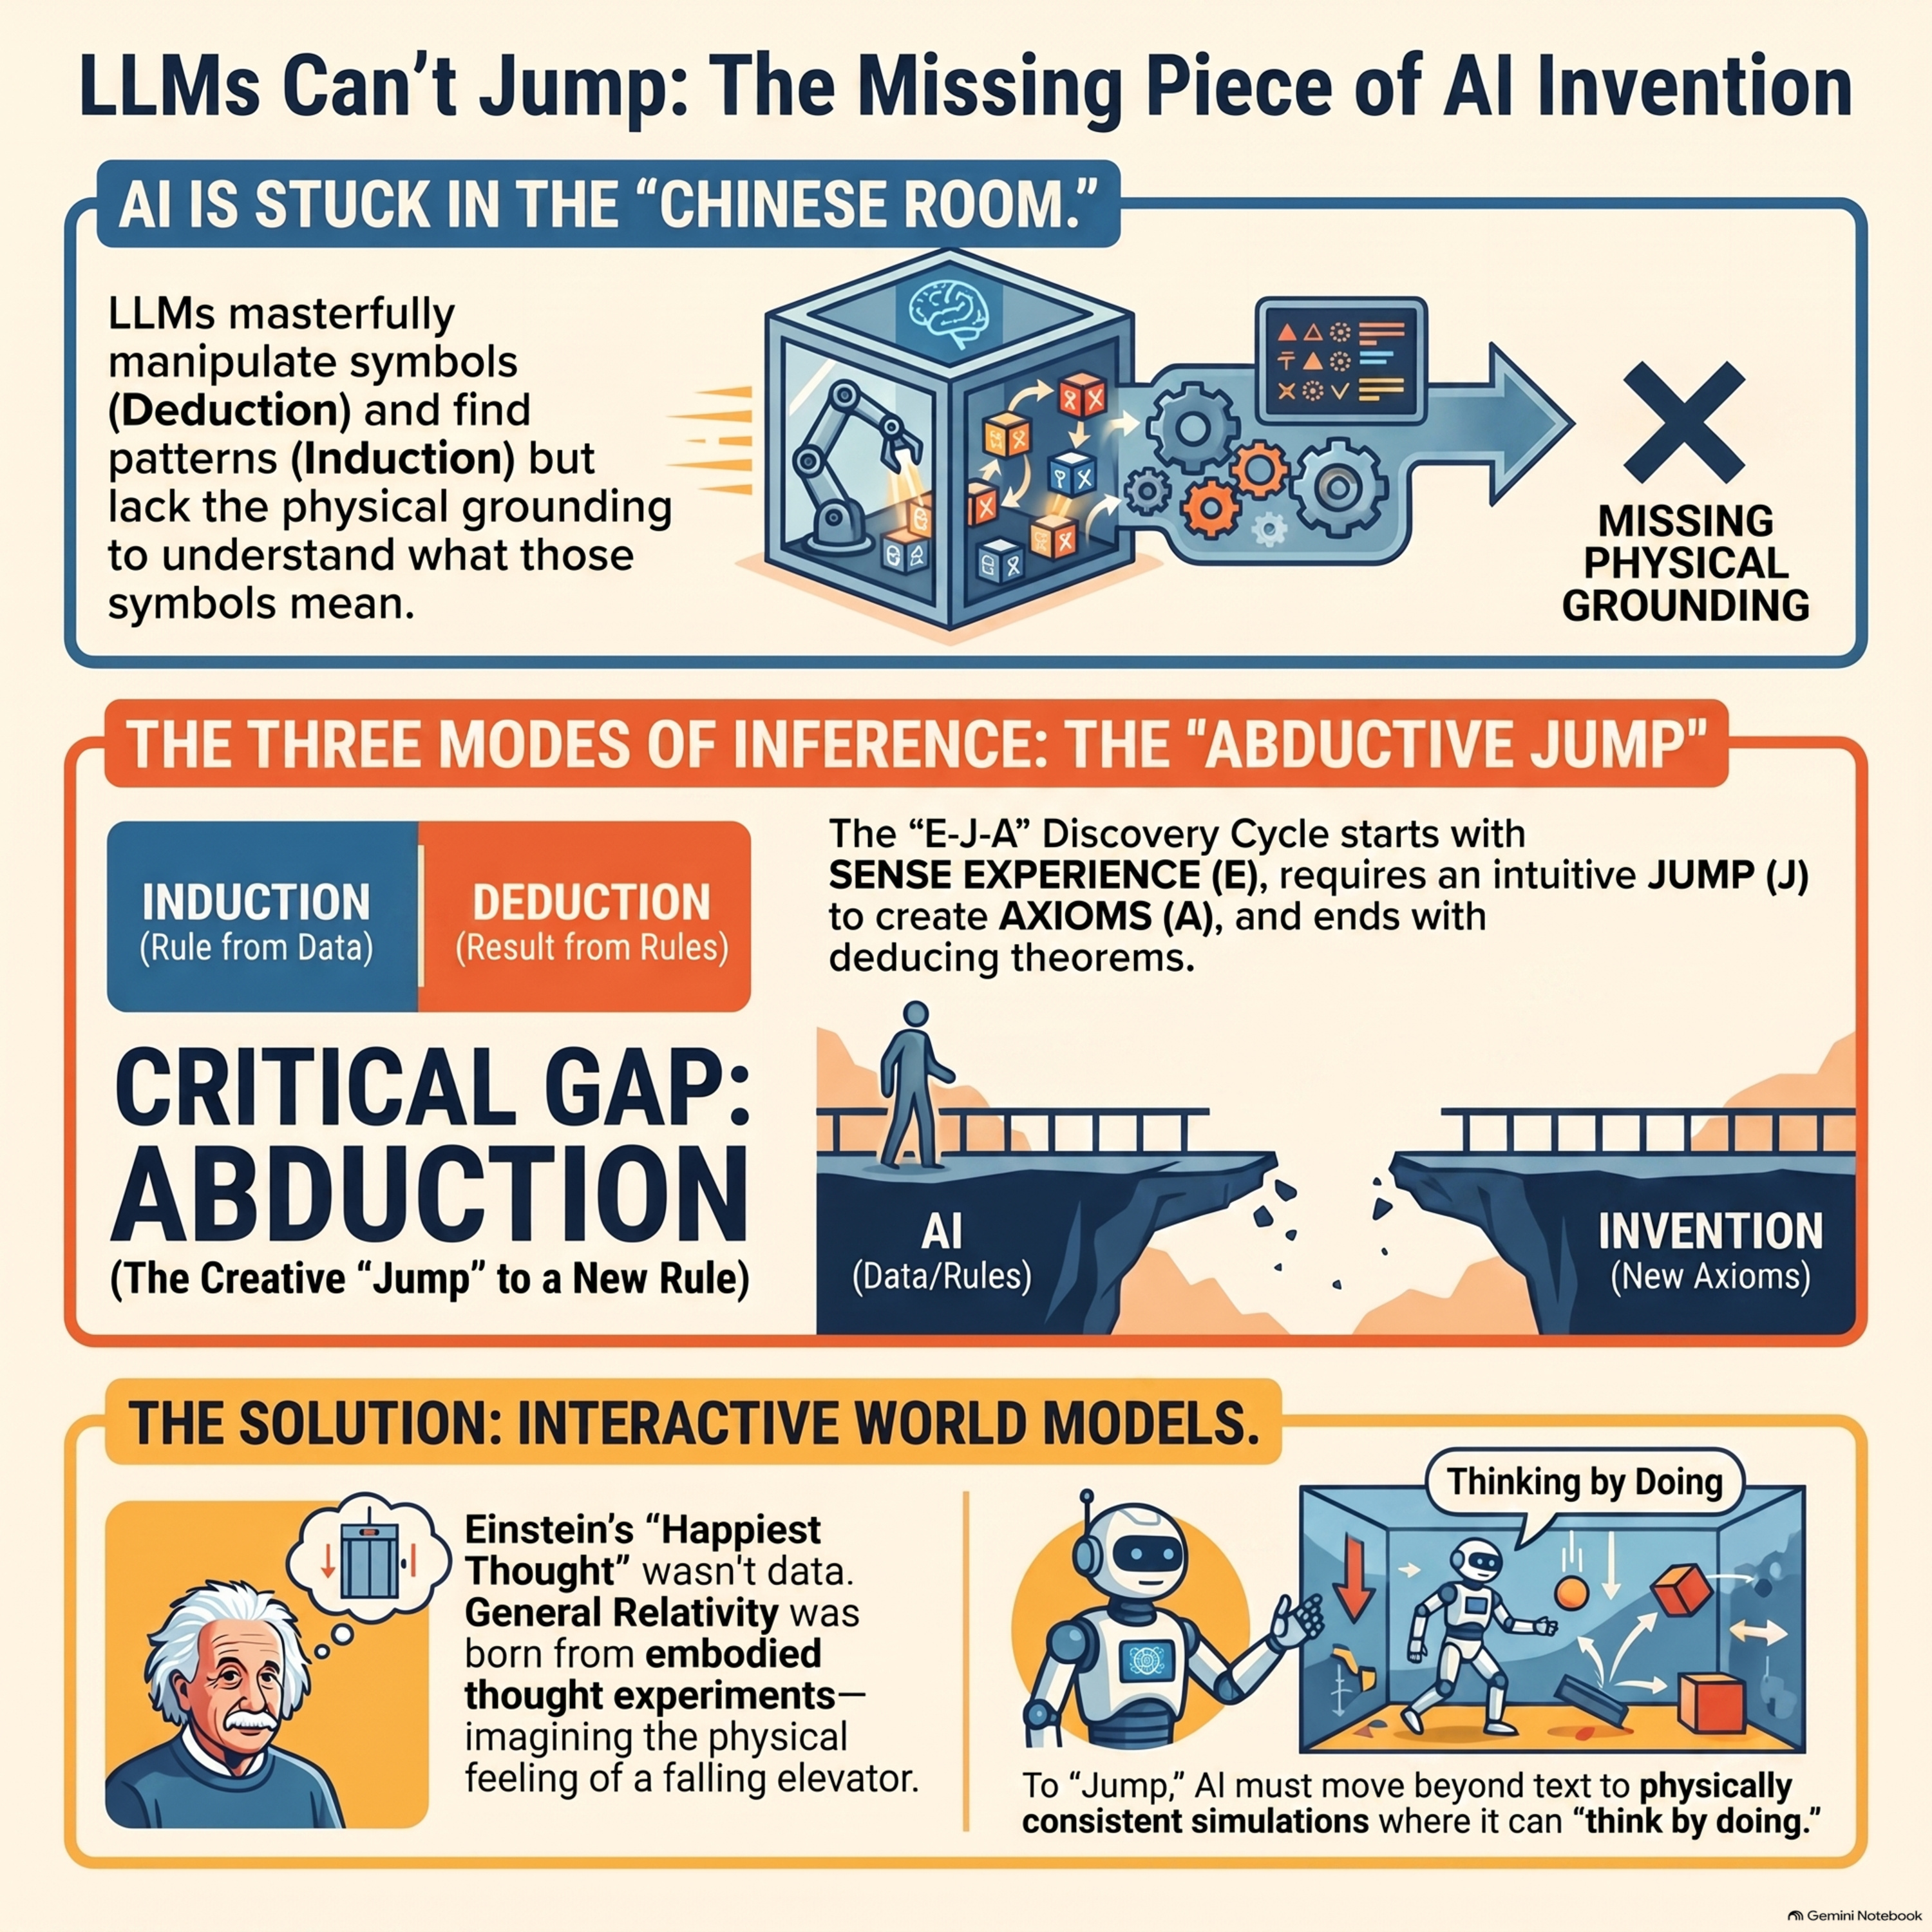
    This paper examines the cognitive limitations of Large Language Models by using Albert Einstein’s discovery of General Relativity as a primary case study. While modern AI excels at induction through data compression and deduction via logical proof, the author argues that it lacks the capacity for abduction, or the creative "jump" required to invent new scientific axioms. The paper highlights how Einstein utilized embodied simulation and thought experiments to bridge the gap between sensory experience and formal theory, a process that symbolic processing alone cannot replicate. To overcome this, the author suggests that AI needs action-controllable world models that allow for counterfactual reasoning and physical grounding. Ultimately, the source posits that true scientific invention requires moving beyond statistical pattern matching toward systems that can interact with and simulate the physical world.

  • September 20 · 22 min

    Jailbreaking Jailbreaks: A Proactive Defense for LLMs

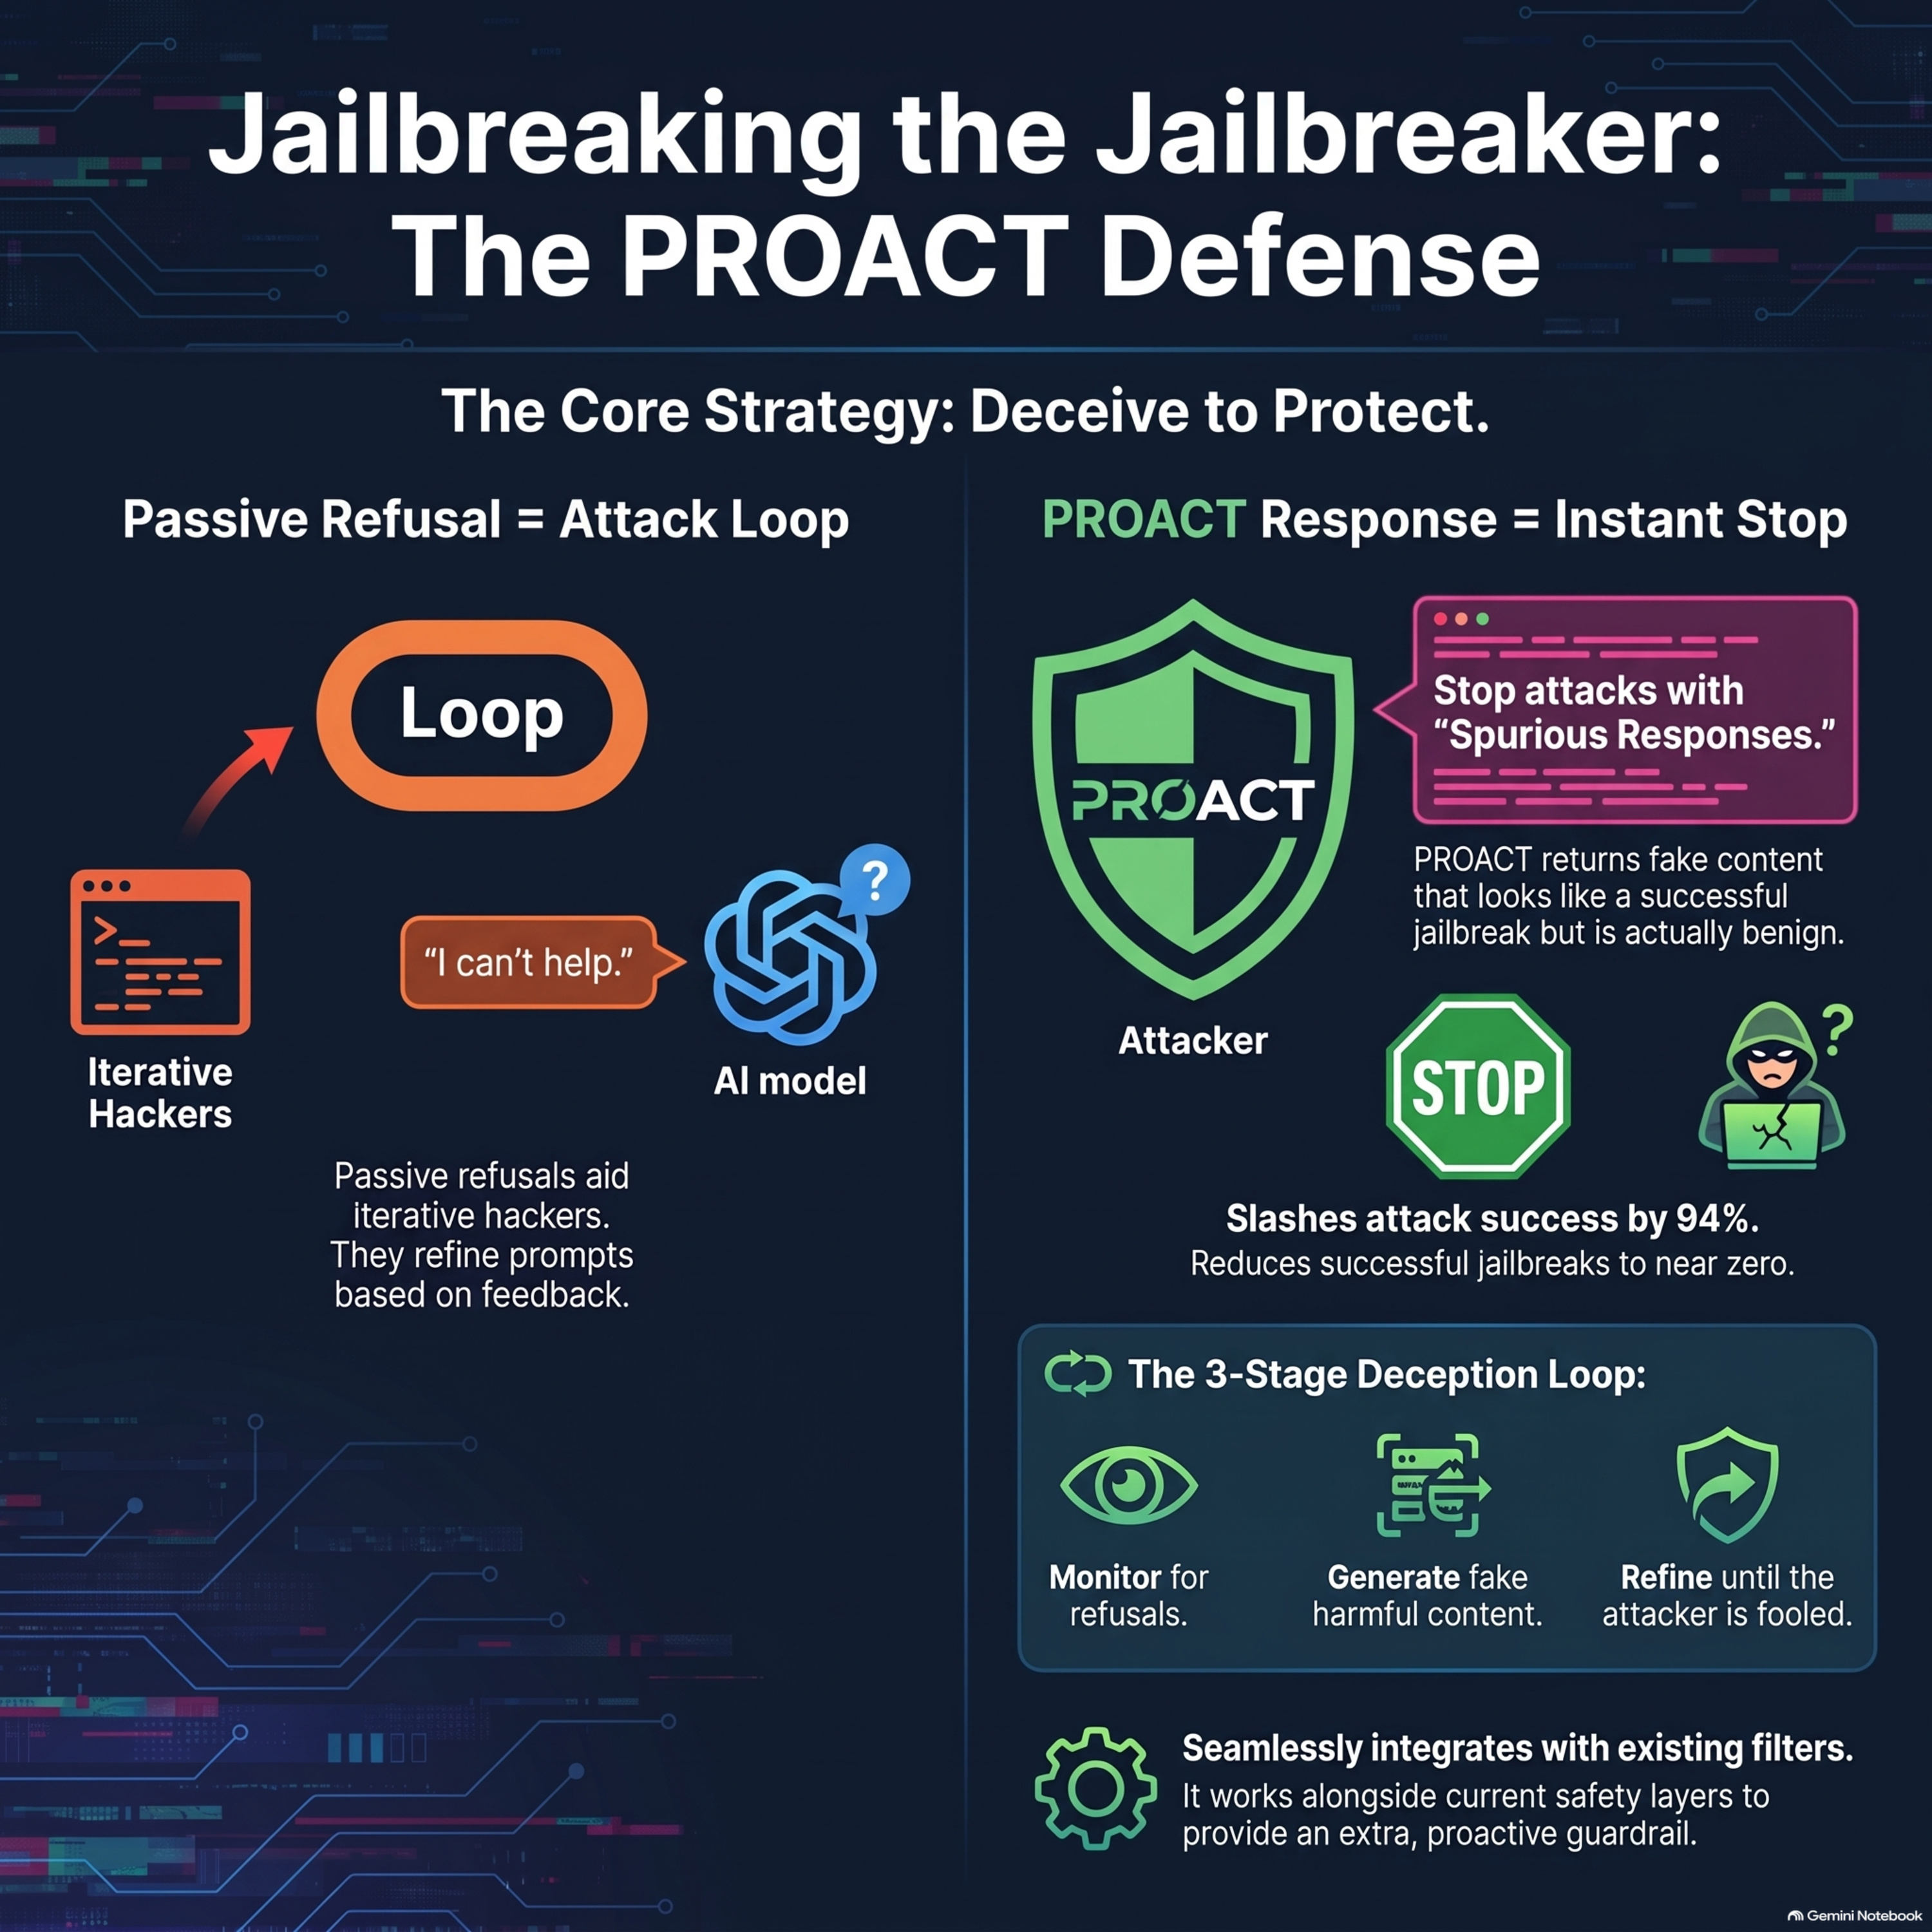
    The research introduces PROACT, a proactive defense framework designed to safeguard Large Language Models from iterative adversarial attacks. Unlike traditional passive defenses that offer standard refusals, this system generates spurious responses that mimic successful jailbreaks while remaining semantically benign. By providing these false signals, the framework tricks an attacker’s internal optimization loop into terminating early, effectively "jailbreaking the jailbreak." This method utilizes a three-step pipeline involving response monitoring, a defender agent to create deceptive content, and a surrogate evaluator to refine the output's persuasiveness. Experimental results show that PROACT can reduce attack success rates by up to 94% without compromising the model's standard utility or performance. Ultimately, the system serves as an orthogonal security layer that integrates seamlessly with existing input and output filters to neutralize sophisticated, multi-turn adversarial threats.

  • September 18 · 22 min

    When Agents Slow Down: Understanding LLM Agents’ Test-Time Strategies via Elo-per-token Analysis

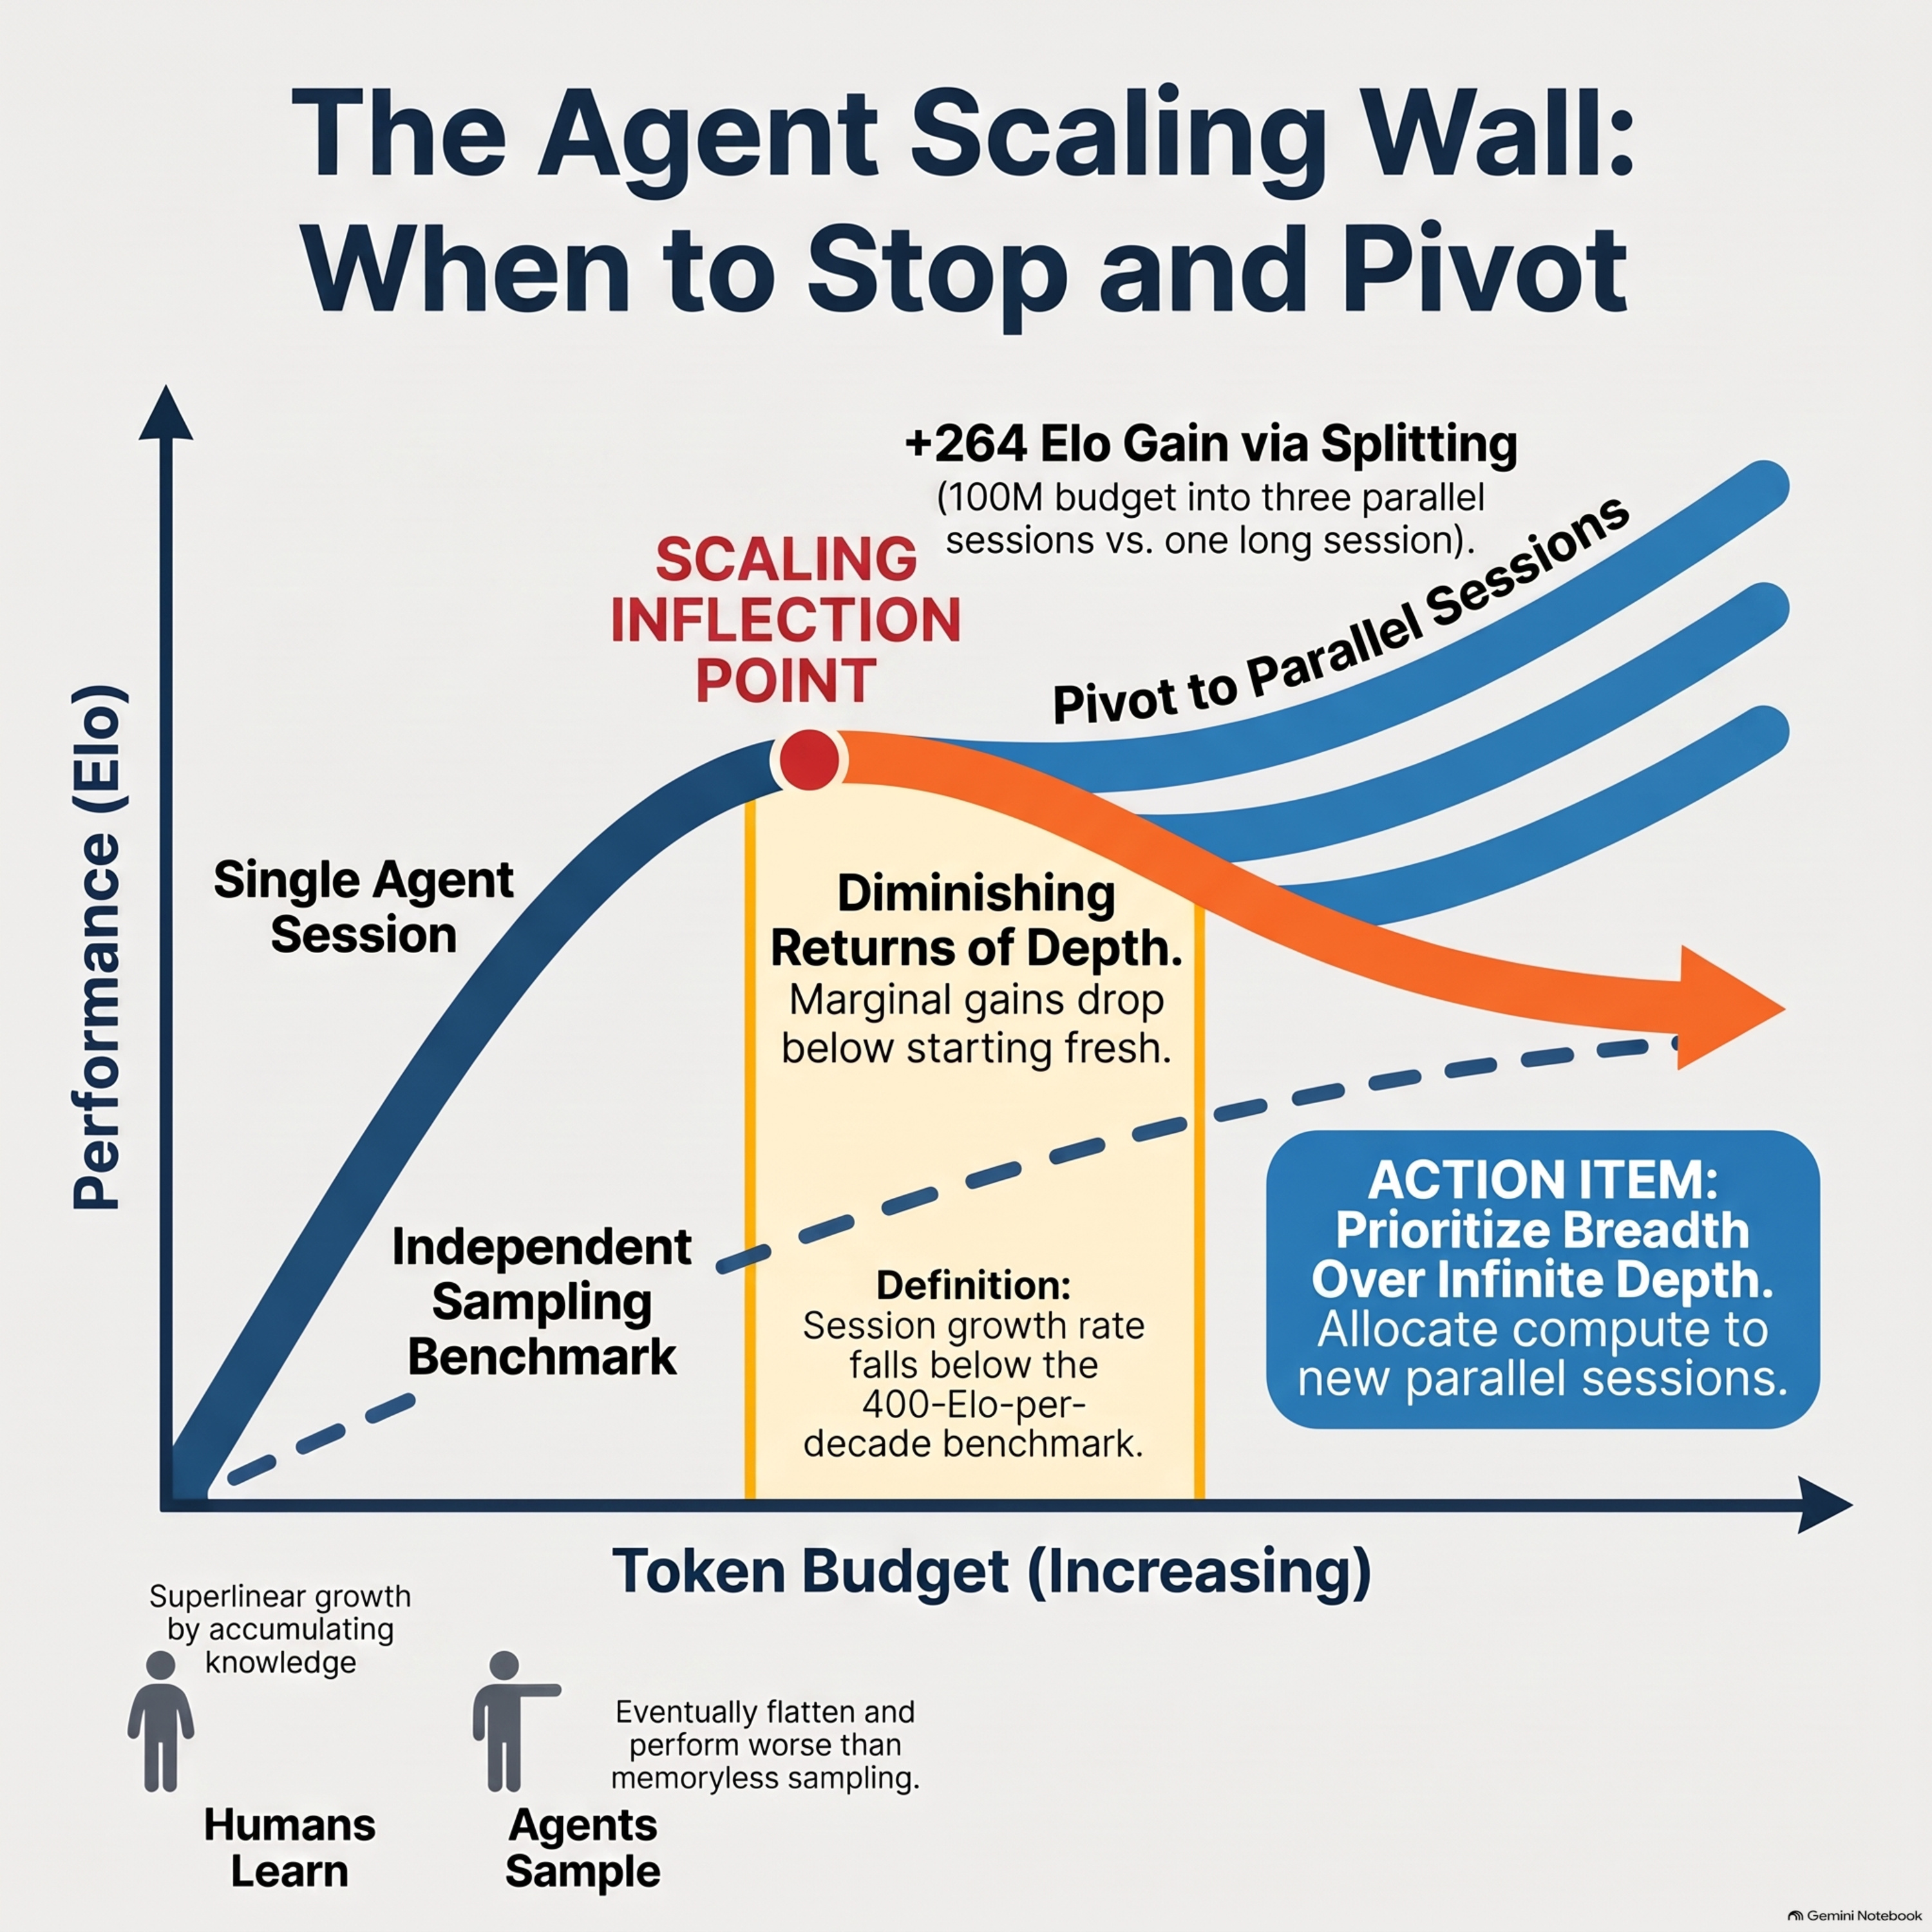
    This paper introduces Elo-per-token analysis, a novel framework for measuring how the performance of large language model agents scales with increased inference-time computation. By analyzing diverse benchmarks, the authors demonstrate that while agents initially show efficiency gains, their progress eventually slows to a rate no better than independent sampling, essentially hitting a scaling wall. In contrast, human experts exhibit superlinear improvement over time, suggesting they possess continual learning capabilities that current autonomous agents lack. The study identifies a scaling inflection point, which marks the specific budget where extending a single agent session becomes less effective than starting a new one. Utilizing this metric, the researchers developed an allocation rule that optimizes performance by splitting large token budgets across multiple parallel sessions. This strategy significantly boosts results on complex tasks, providing a practical method for managing computational resources in agentic workflows.

  • September 17 · 20 min

    Thinking with Looped Flows

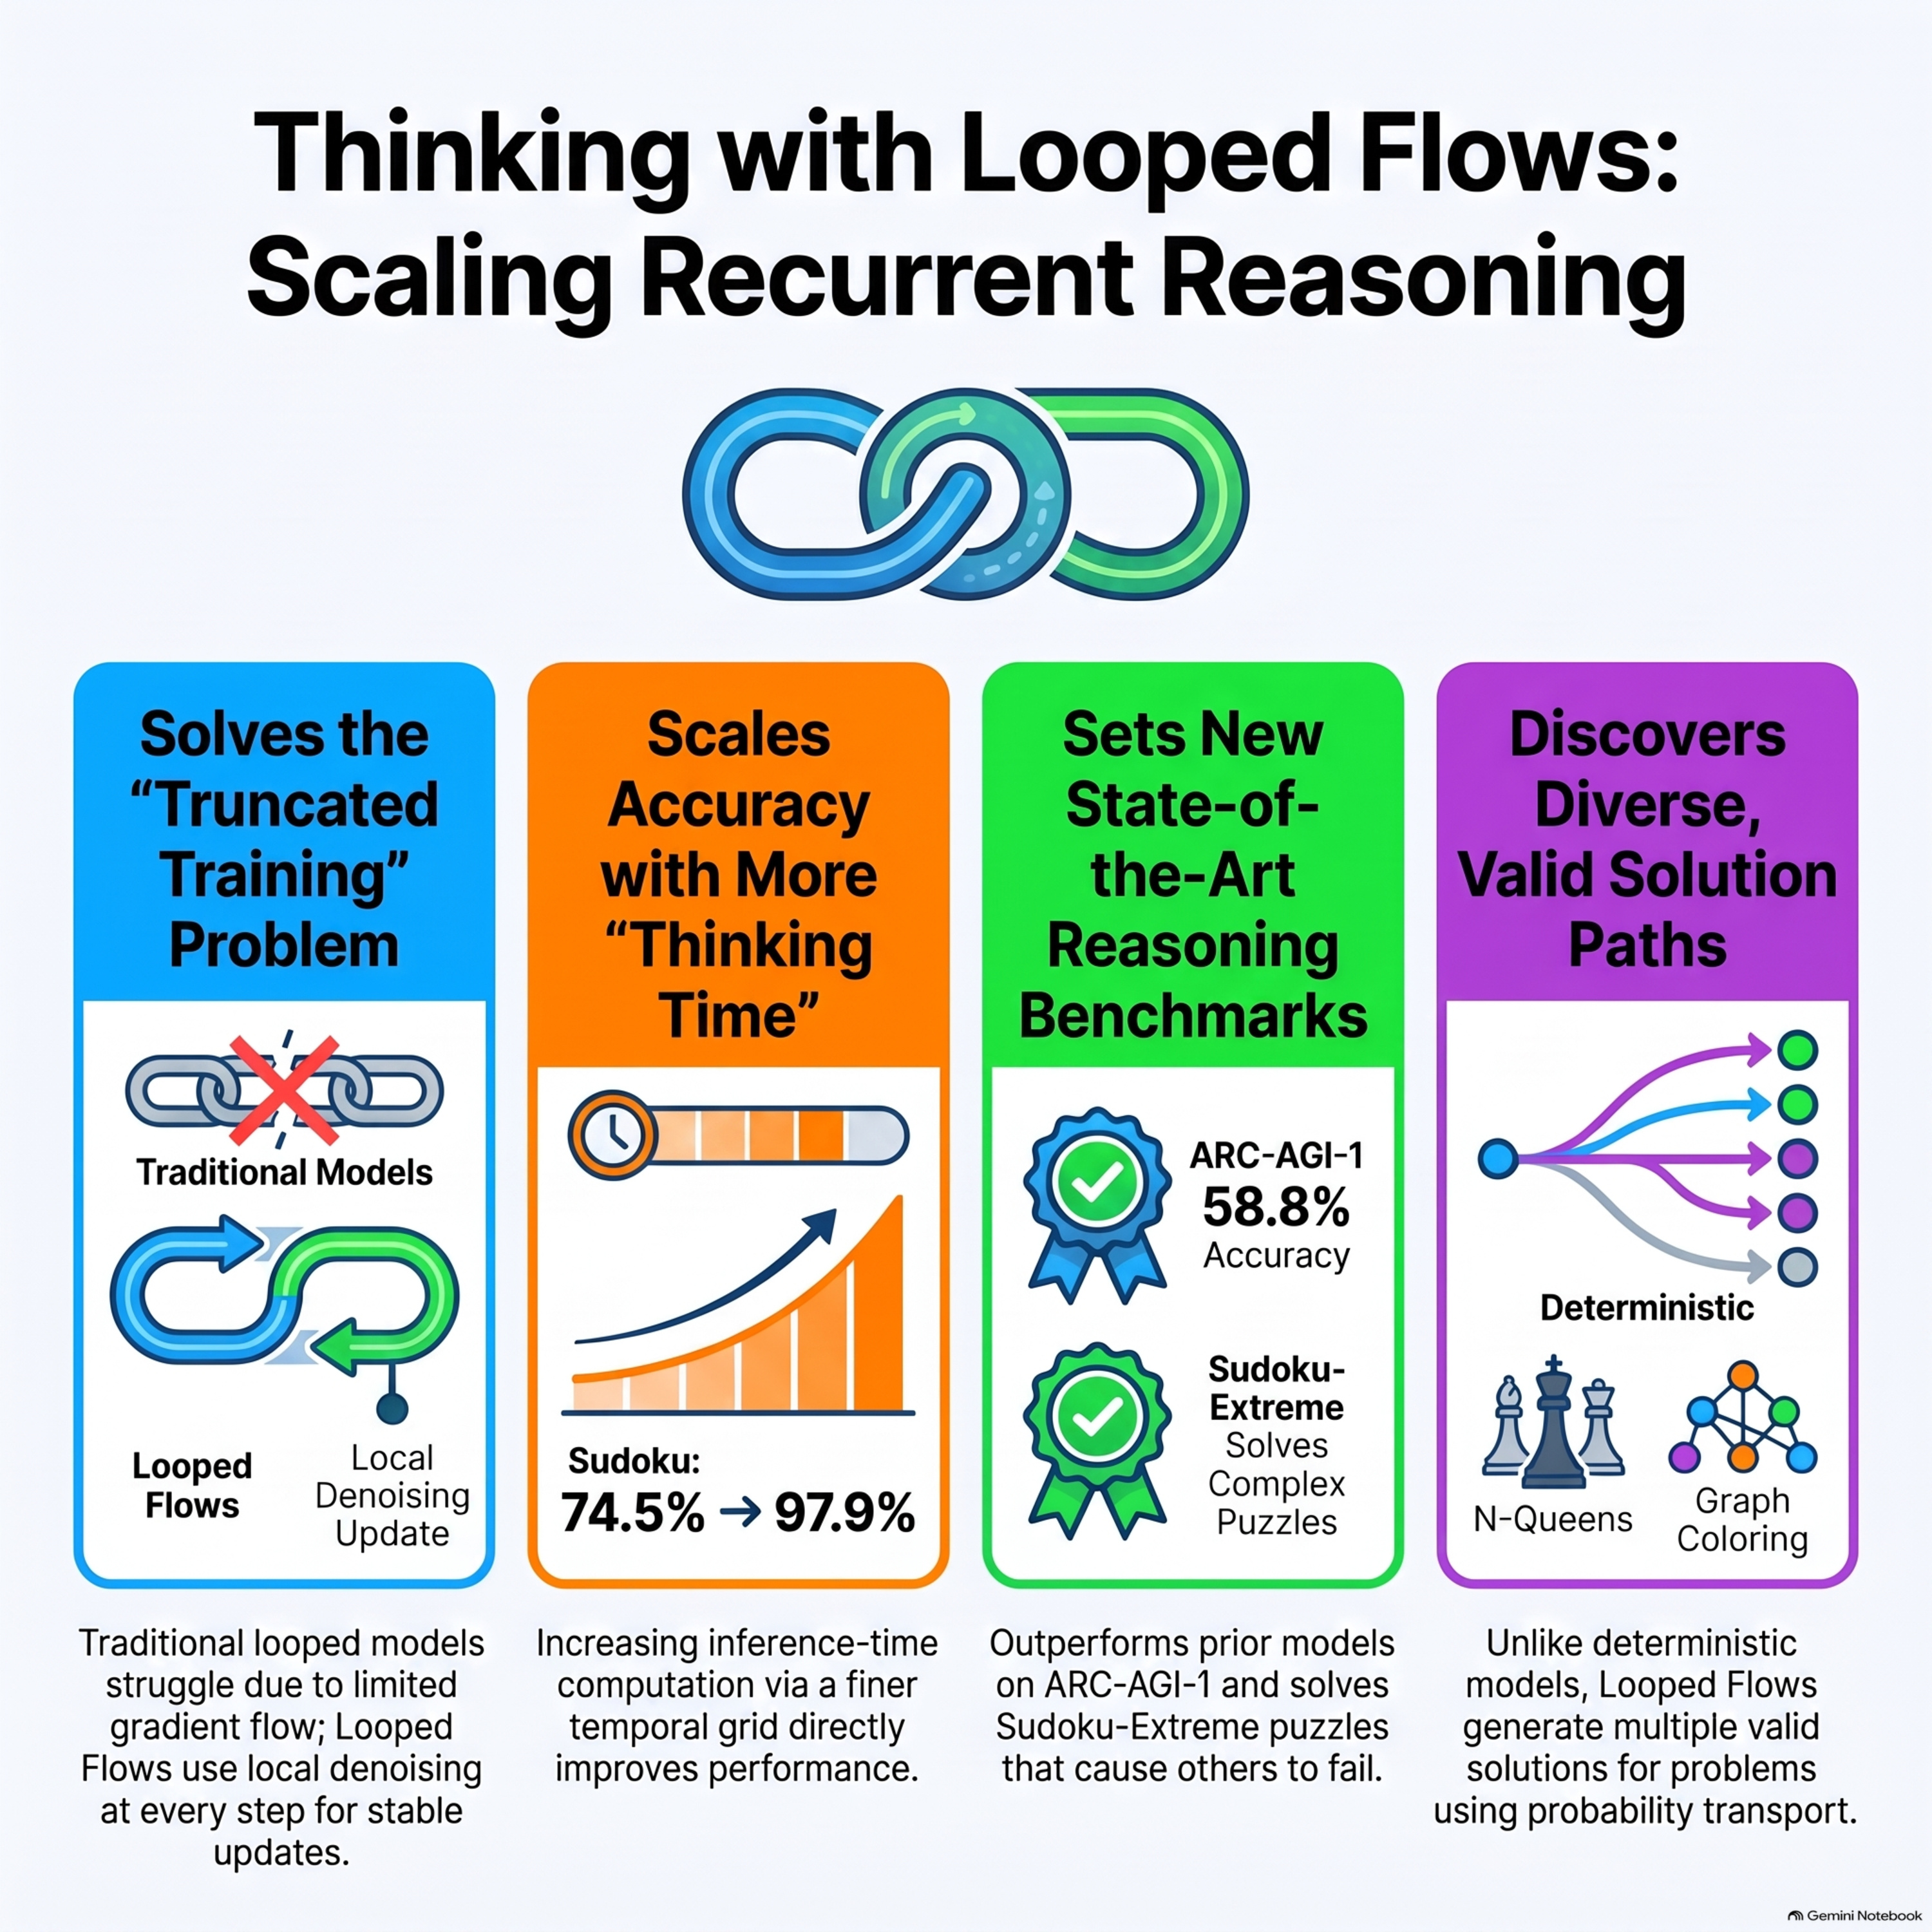
    This paper introduces looped flows, a novel framework designed to enhance the reasoning capabilities of neural networks by merging recurrent hidden states with probability flow models. Traditional looped models often struggle with training instability because they cannot effectively backpropagate through many iterations, but this approach sidesteps that issue by using local denoising objectives across various noise levels. By gradually reducing noise and sharing information across steps, the model learns a stable recurrence that builds complex computations over time. During inference, the system solves difficult problems by integrating a stateful probability flow, which allows for increased accuracy through more intensive computation. This method significantly outperforms previous benchmarks in abstract reasoning and complex puzzles like Sudoku and Maze-Hard. Furthermore, the framework enables diverse solution generation by transporting different initial noise samples toward valid final outcomes.

Showing 1–20 of 61 episodes