High-Value Training Data from Noisy, Diverse Sources
transcript
show notes
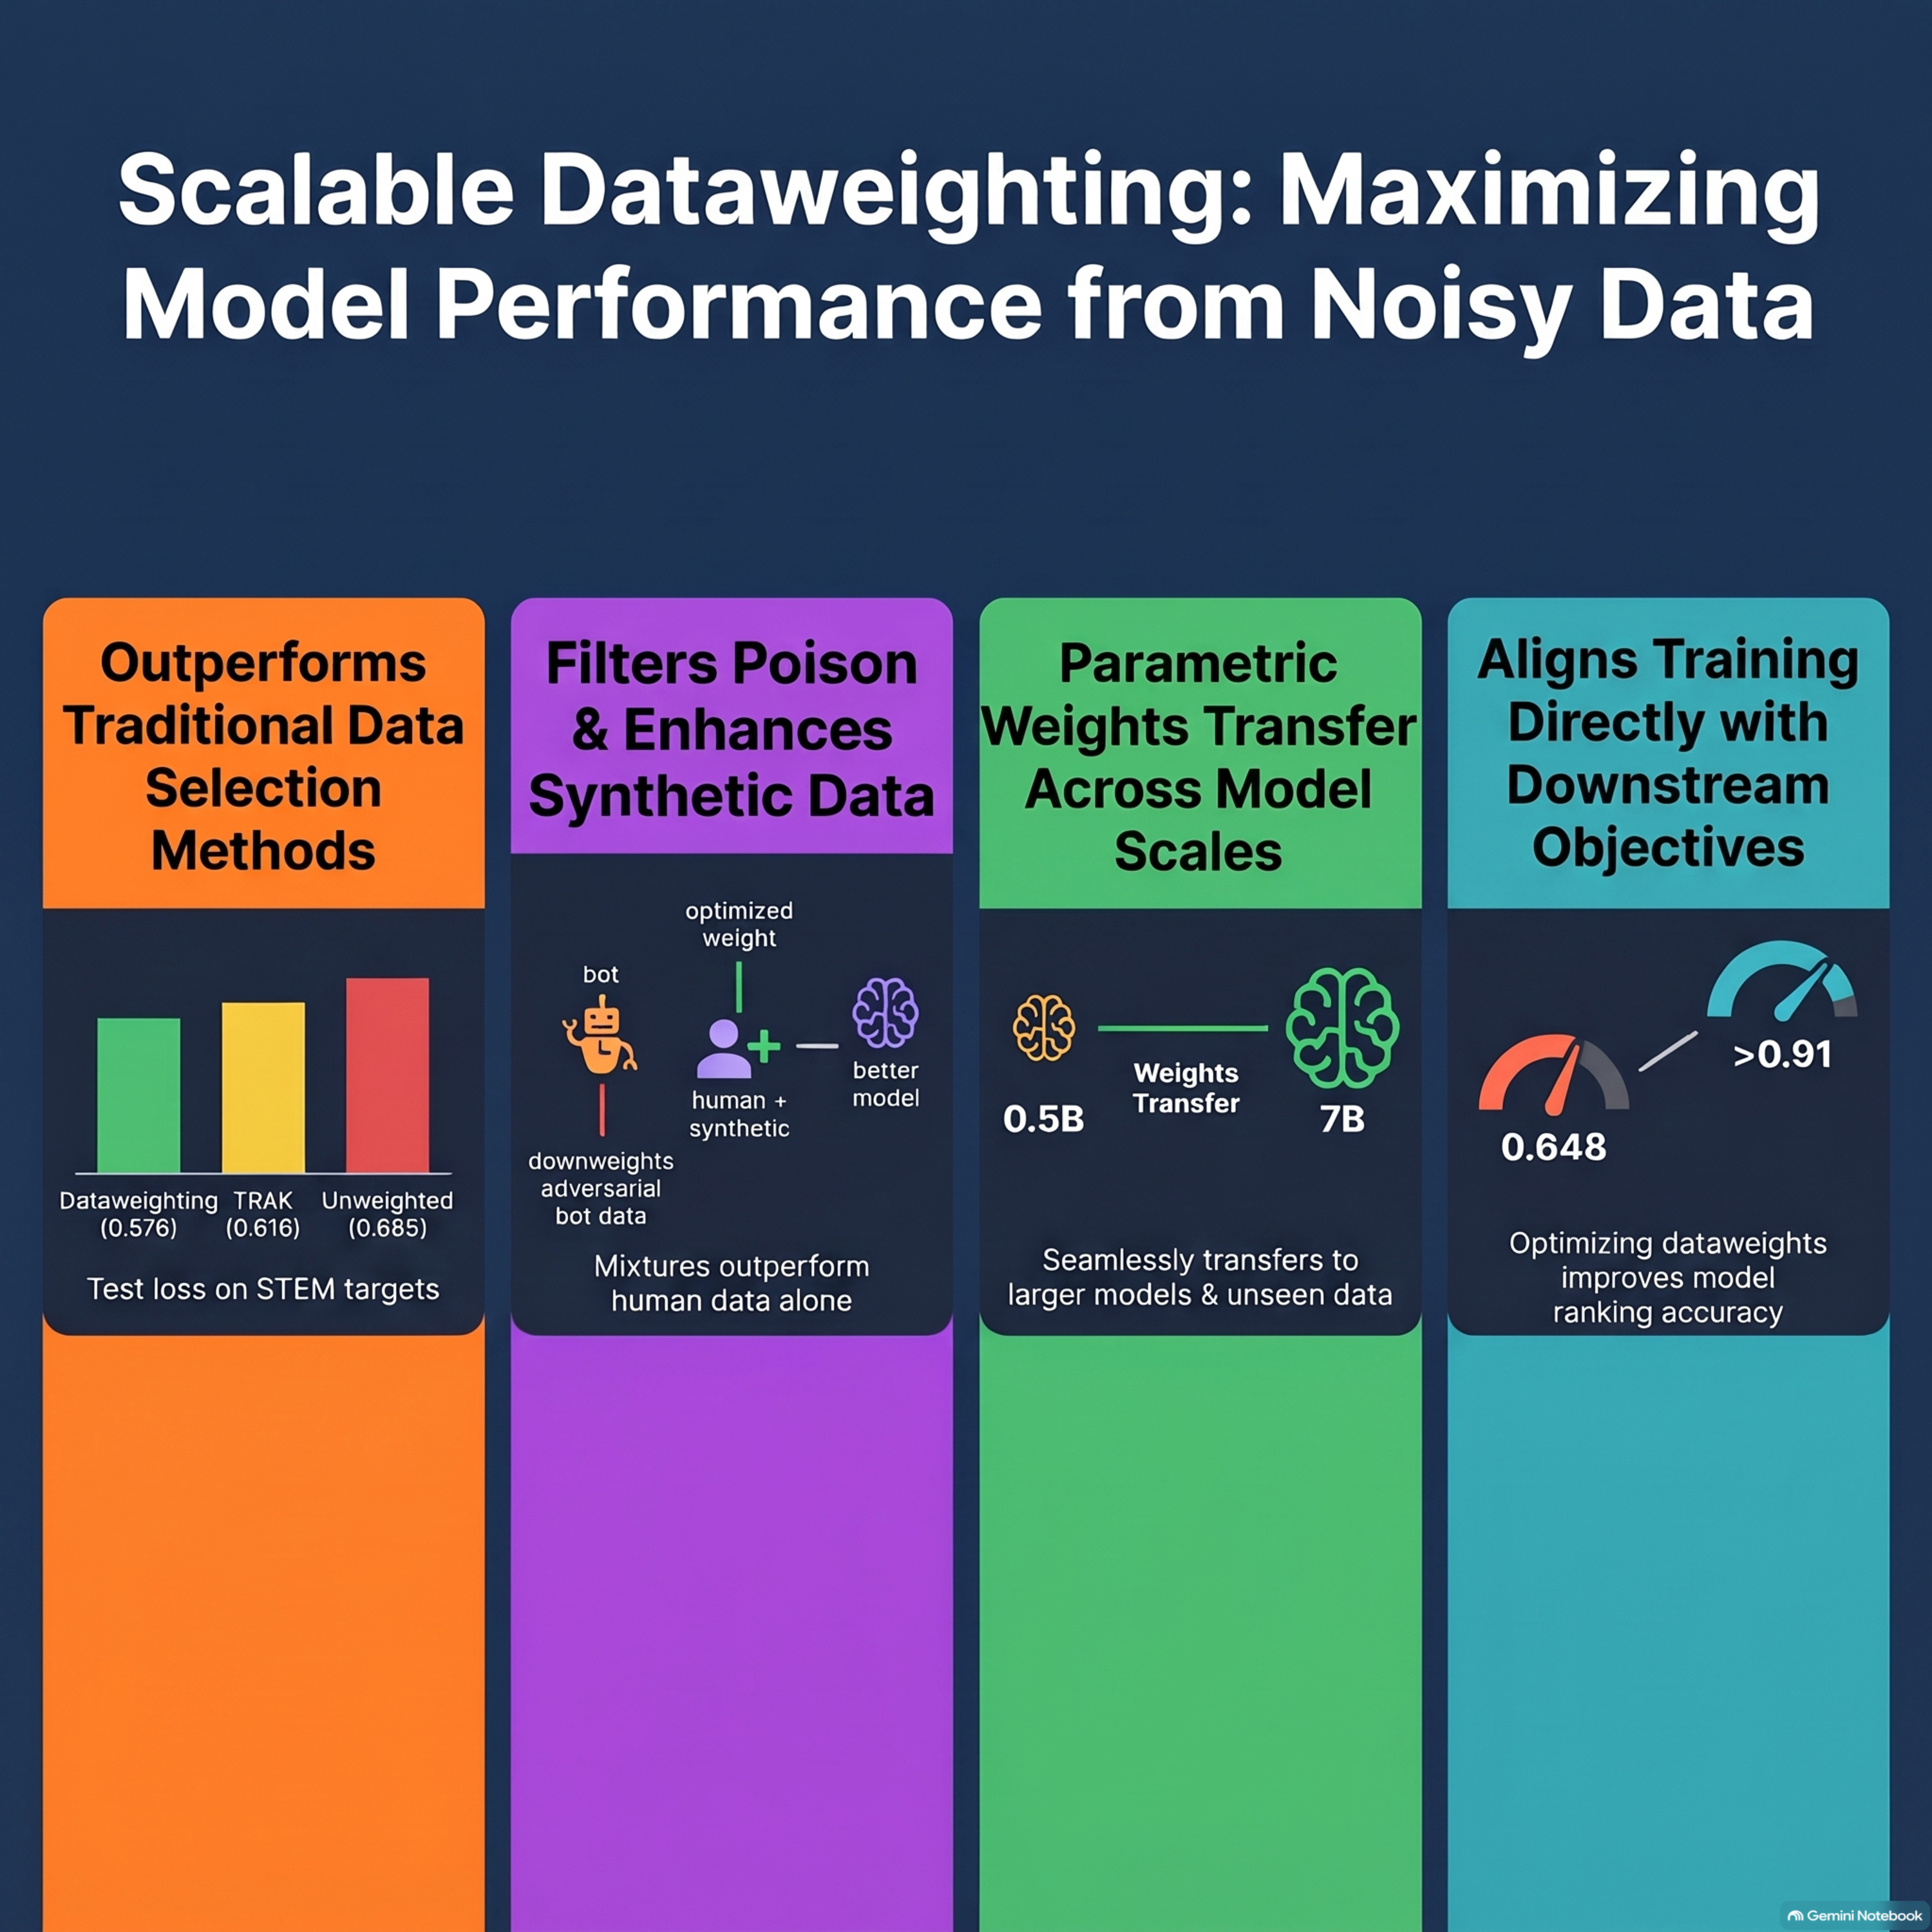
Training advanced machine learning models typically relies on vast, heterogeneous datasets containing noisy, adversarial, or mismatched data. To address this challenge, the authors introduce dataweighting, a scalable framework that assigns specific weights to training examples based on their actual impact on performance. Instead of relying on manual heuristics or aggressive data filtering, this method uses metagradient descent to dynamically optimize training weights against a small, high-quality target dataset. Furthermore, the approach implements parametric dataweights that successfully transfer across different model scales and generalize to previously unseen training inputs. Ultimately, this technique improves model performance across various applications, successfully integrating synthetic supervision and optimizing complex downstream objectives like ranking accuracy.