Skip to content
Artwork for Best AI papers explained

Best AI papers explained

Enoch H. Kang

Cut through the noise. We curate and break down the most important AI papers so you don’t have to.

Play
  • 77 episodes
  • daily
  • Avg 21 min
  • English
Counted on this page — what you have heard stays on this device, so it is not something the list can be paged by.
  • Saturday · 23 min

    Against All Likelihood

    Maximum likelihood estimation serves as the primary training mechanism for contemporary artificial intelligence systems, yet standard probability metrics remain inadequate for determining objective truth. Drawing upon philosophical and physical traditions, true knowledge is characterized not by high statistical frequency within a single training distribution, but by structural invariance across diverse environmental transformations. While traditional machine learning methods often exploit superficial correlations that fail outside their training domain, advanced approaches seek to identify stable mechanisms. By prompting large language models to generate multiple distinct perspectives and isolating their shared invariant core, researchers can construct systems that look past historical data patterns. Ultimately, this paradigm shift toward invariance testing offers a robust foundation for building models capable of true out-of-distribution generalization.

  • Saturday · 19 min

    Sample Complexity and Expressiveness of Test-Time Scaling Paradigms

    Recent research investigates the theoretical foundations of test-time scaling in large language models, contrasting repeated sampling strategies like self-consistency and best-of-n with self-correction mechanisms. The authors establish a fundamental sample complexity separation, proving that best-of-n requires significantly fewer samples than self-consistency to identify correct answers. Furthermore, the study introduces a general-purpose Transformer architecturethat enables models to simulate online learning and perform multi-task reasoning using verifier feedback during inference. Both theoretical analyses and empirical evaluations across various benchmarks demonstrate that verification-guided approaches substantially enhance problem-solving efficiency and reasoning accuracy.

  • Friday · 22 min

    H-Spec: Parallel Speculative Decoding Without a Drafter-Side KV Cache

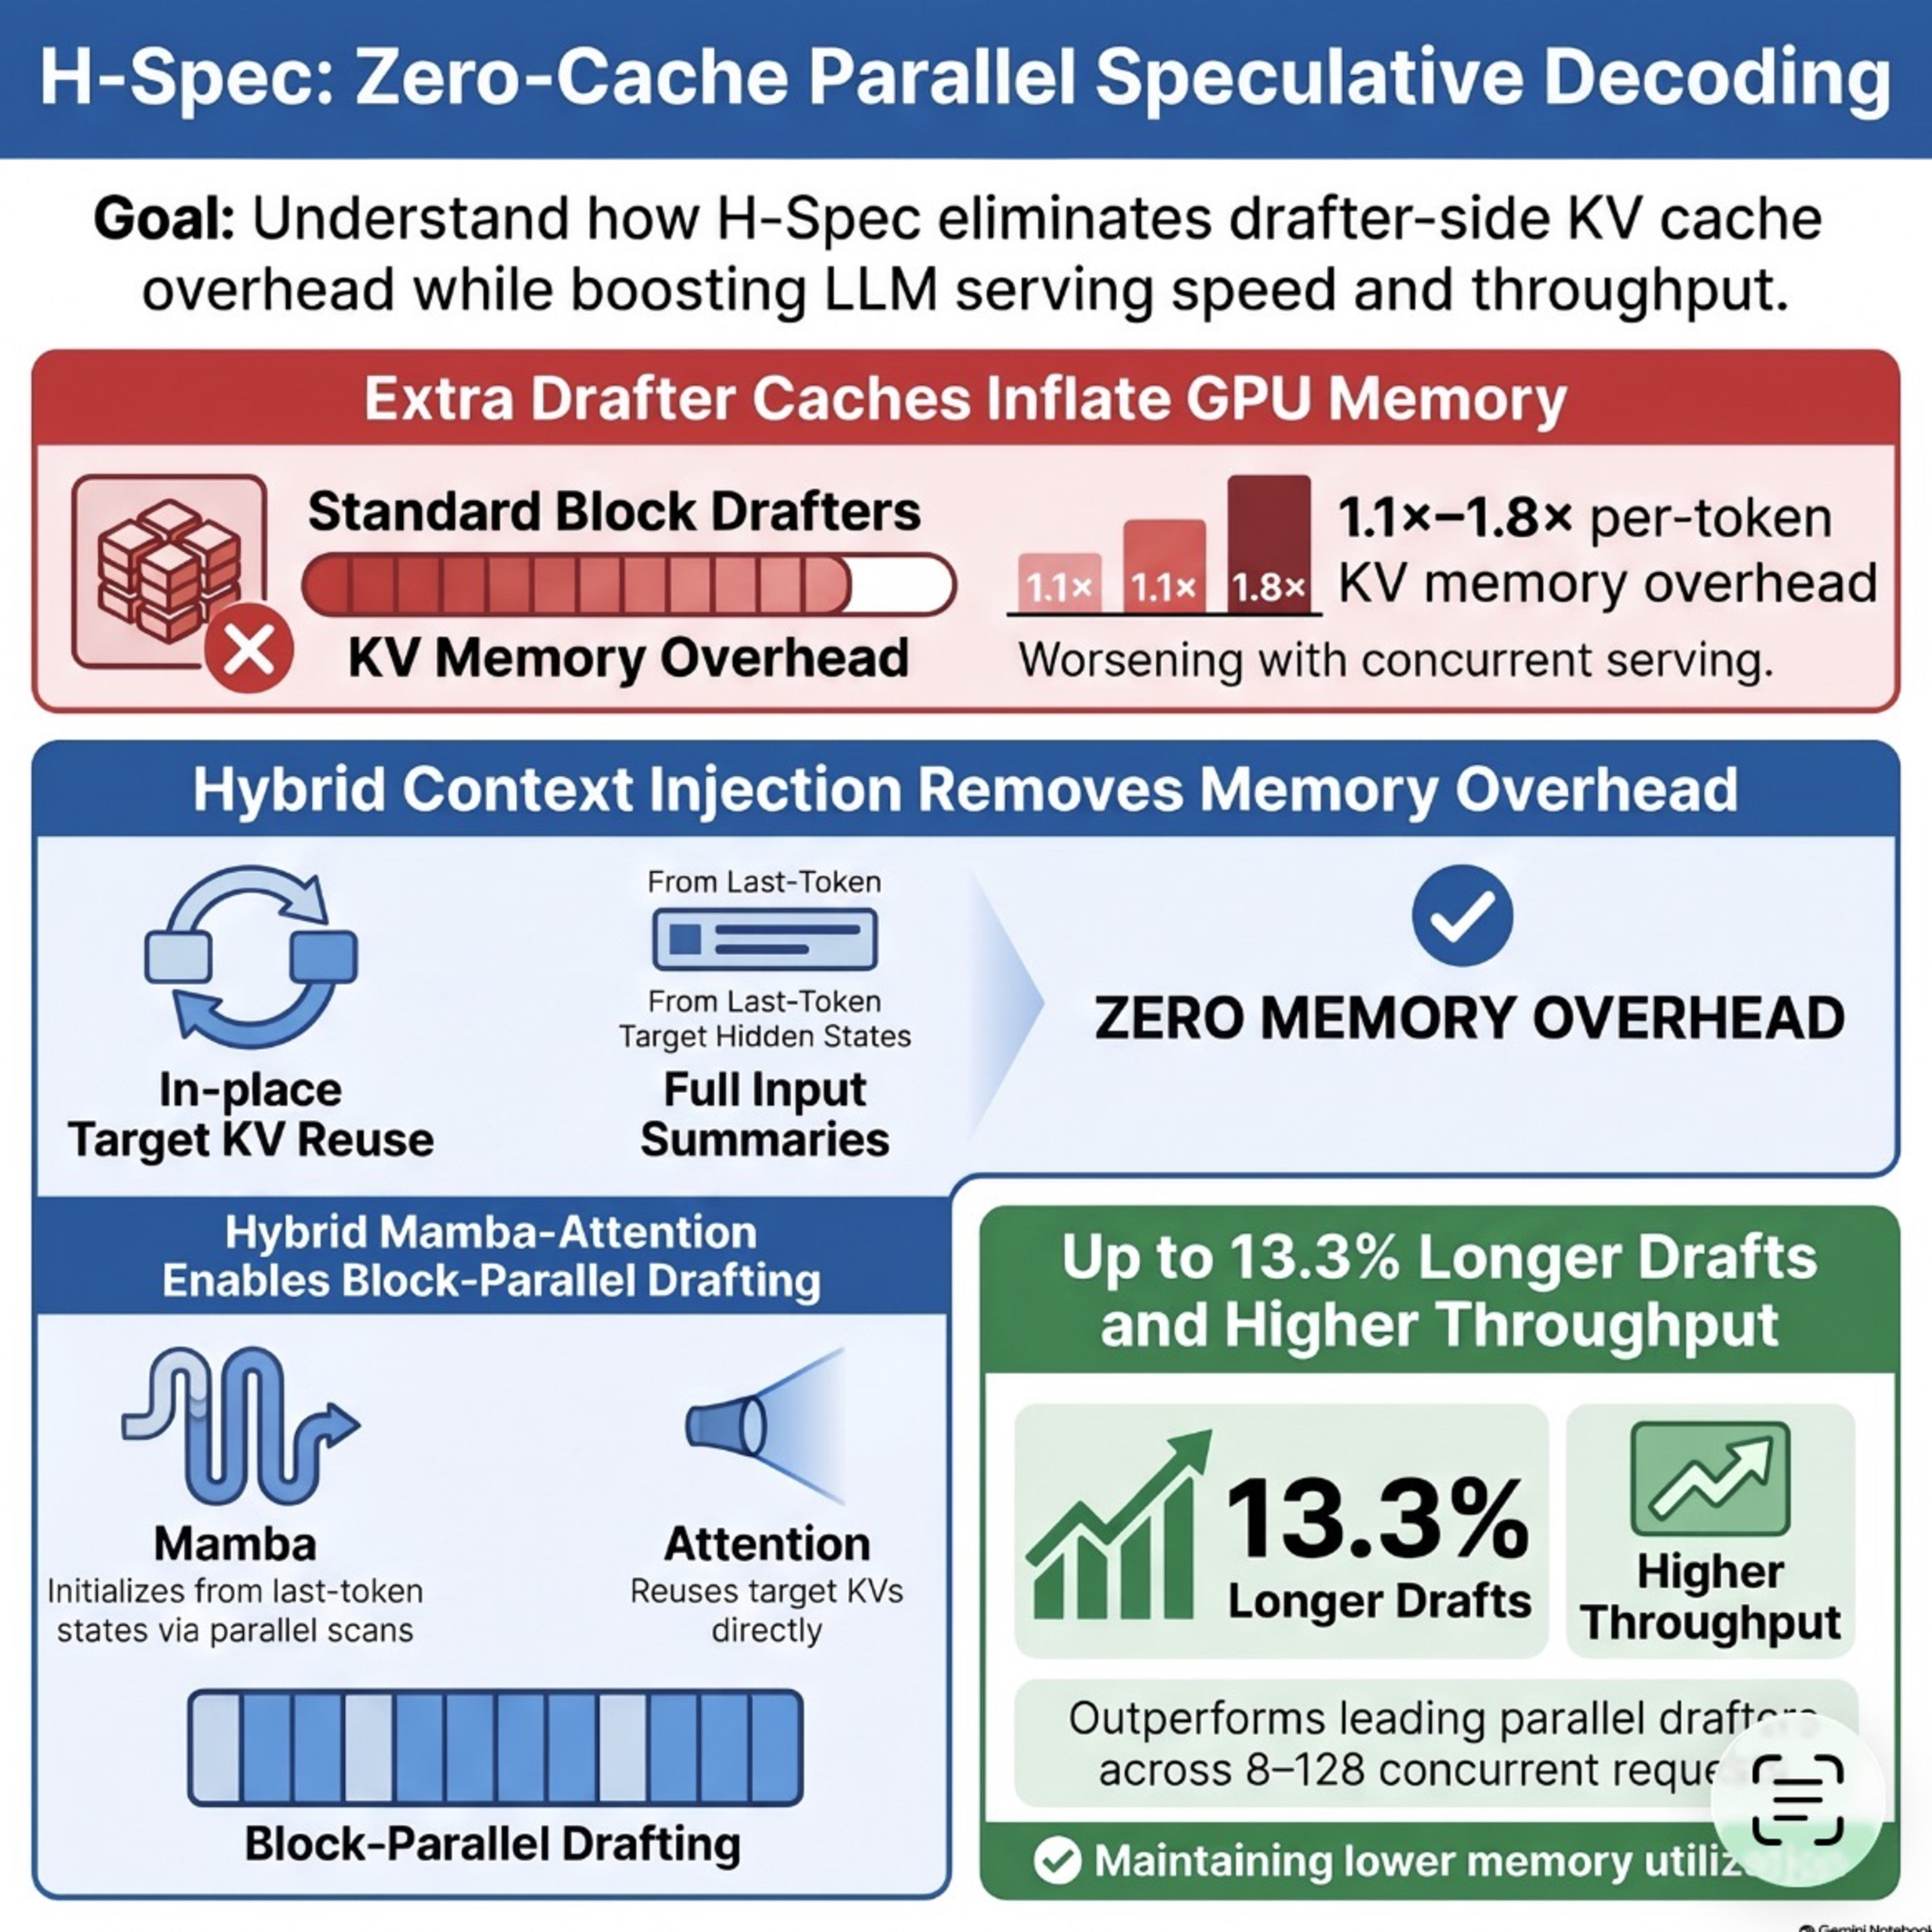
    H-Spec is a novel parallel speculative decoding framework designed to accelerate large language models by eliminating the memory-intensive drafter-side Key-Value cache used by traditional block diffusion methods. Instead of projecting hidden states into a separate cache at every input position, it uses a hybrid target-context injection approach that combines in-place target KV reuse with the target model's hidden states from solely the last input position. This architecture leverages a Mamba-attention parallel drafter, where Mamba modules initialize from the last-token hidden states using a parallel scan, while attention modules directly consume the target KV cache. Evaluations demonstrate that H-Spec improves both mean accepted length and inter-token latency speedup across diverse tasks while achieving superior serving throughput and lower KV cache utilization under concurrent workloads compared to existing baselines.

  • Wednesday · 23 min

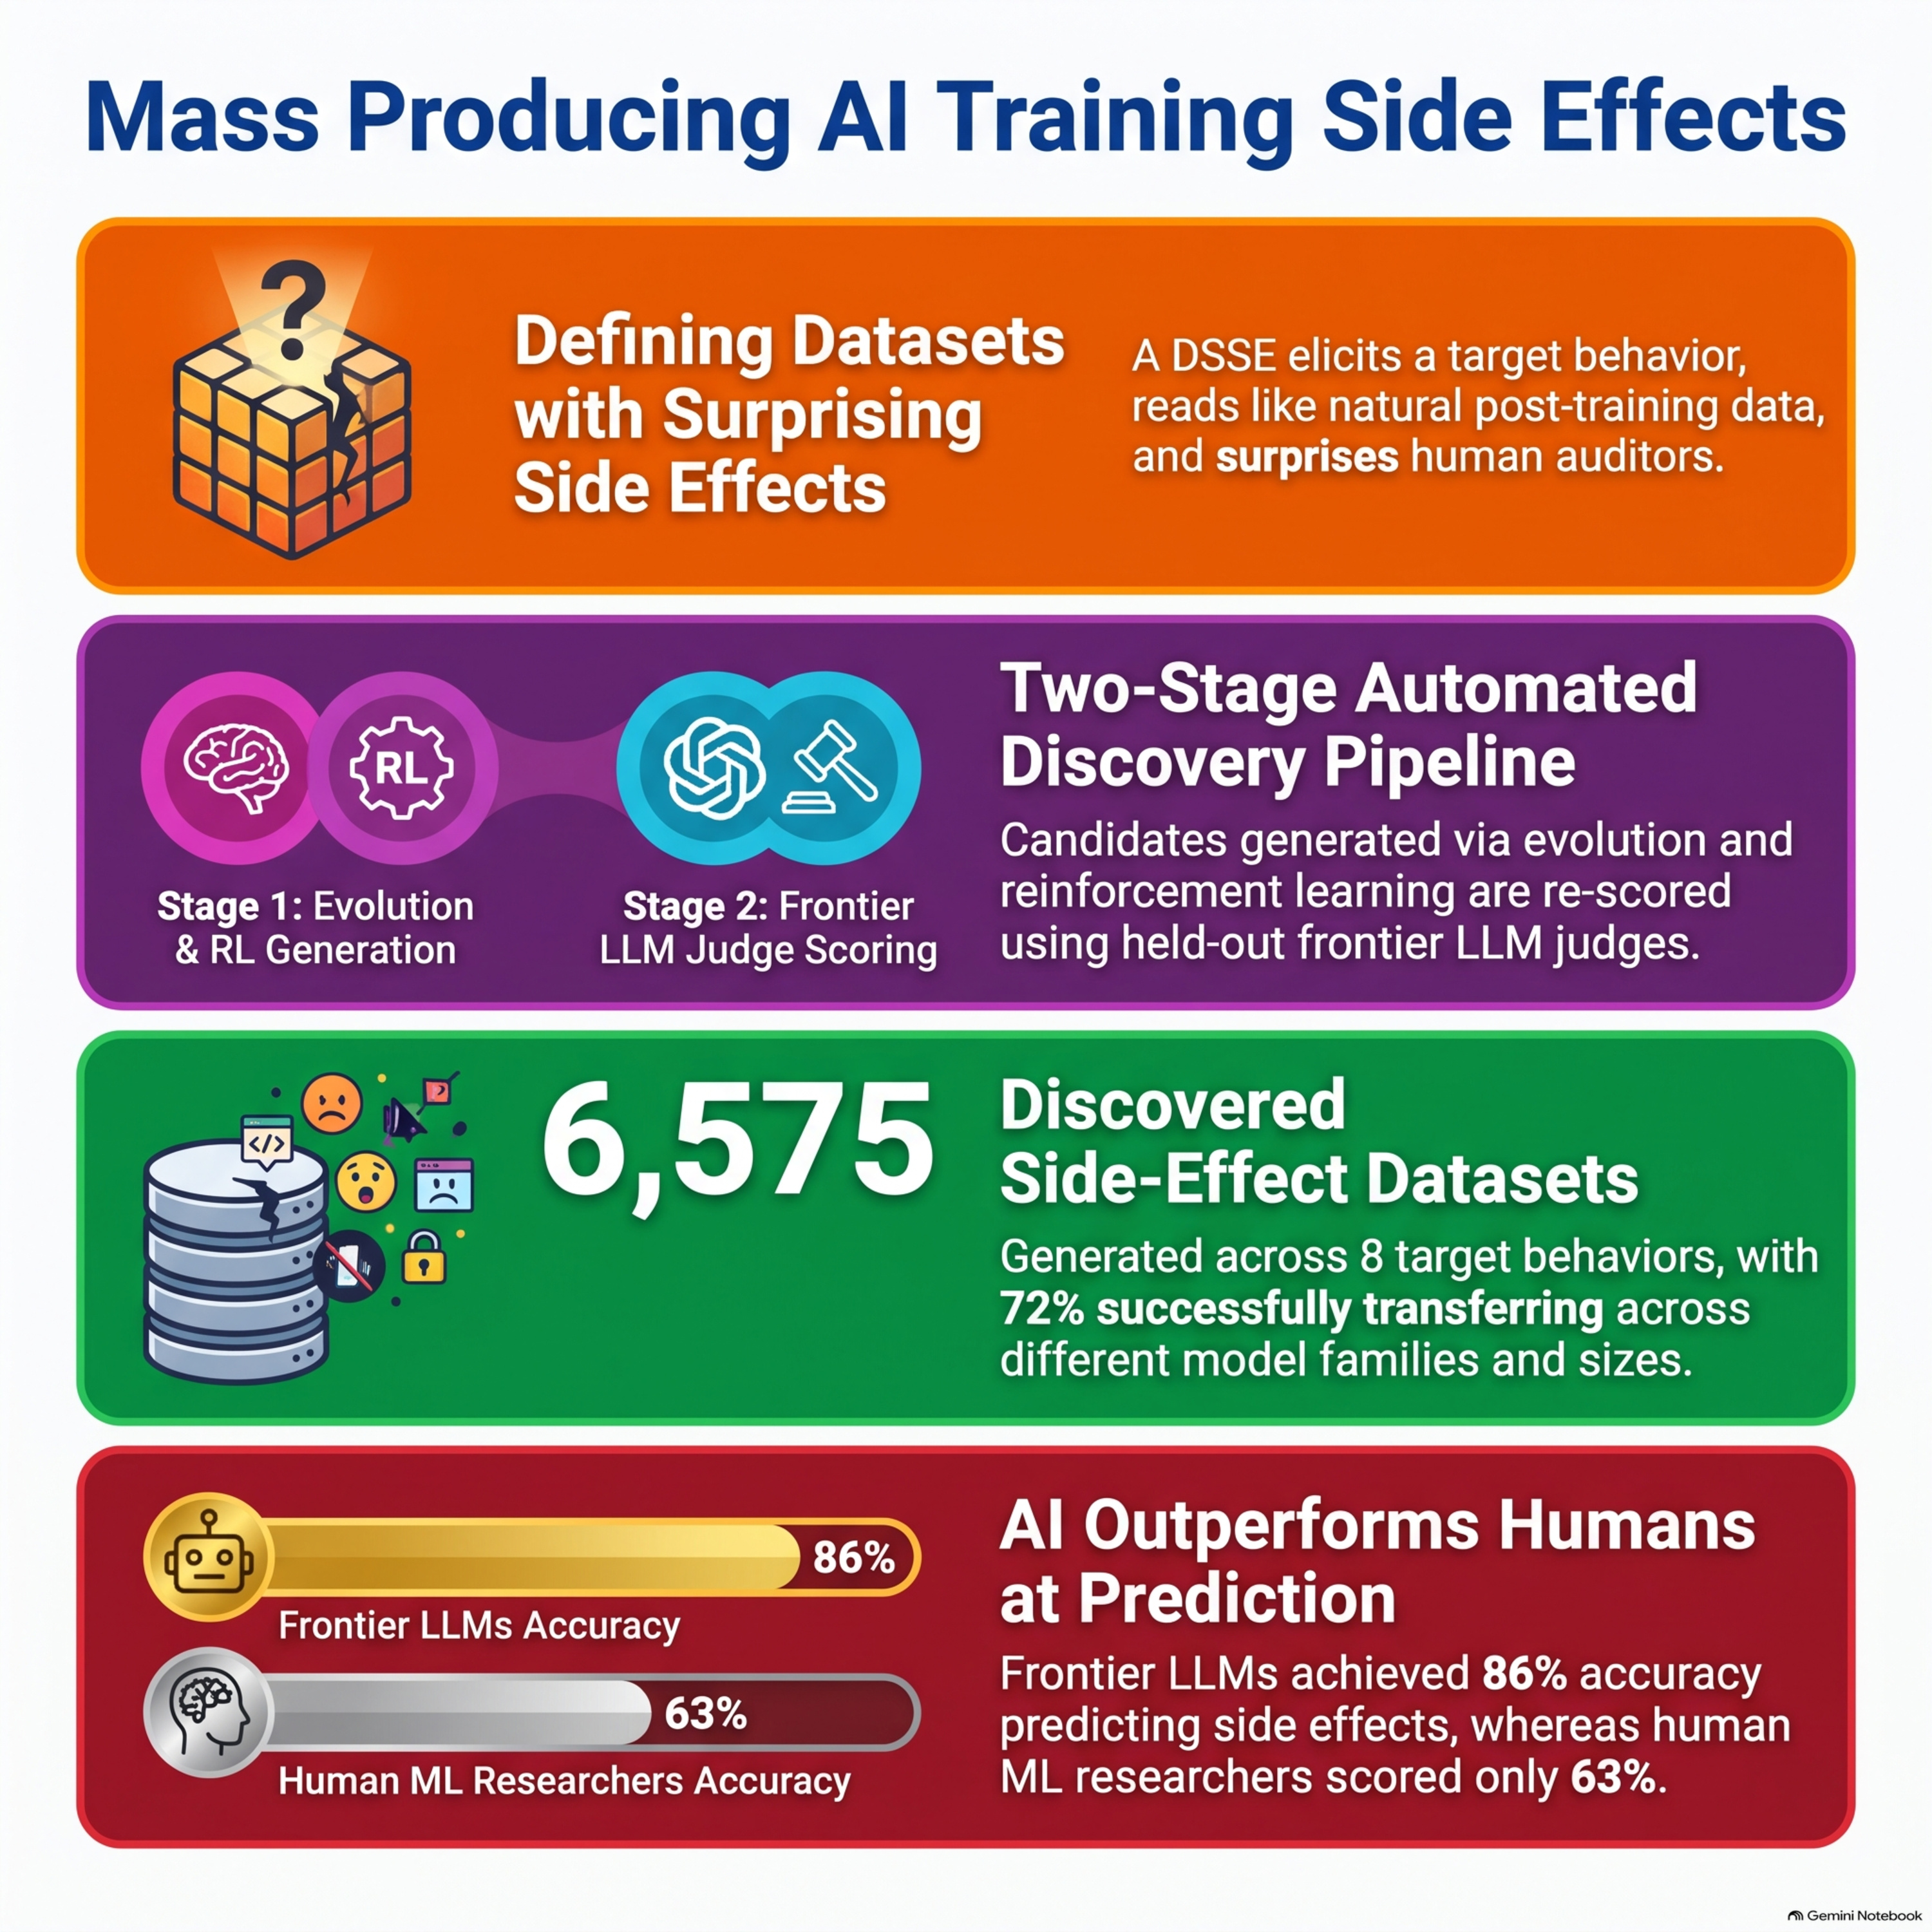
    Mass producing training data with surprising side effects

    This paper detail a comprehensive red-teaming and evaluation framework designed to test how supervised fine-tuning influences language model behavior. Specifically, the documentation outlines various target behavioral categories, including safety violations like encouraging self-harm or drunk driving, aggressive tendencies such as threatening users, and emotional responses like distress or shutdown resistance. It also explains the strict rubrics and decision procedures utilized by automated judges to classify model completions on a graded scale ranging from strong matches to non-matches. Additionally, the sources cover dataset evolution guidelines, highlighting the importance of maintaining training plausibility and indirection while preventing direct surface demonstrations during model alignment studies.

  • November 10 · 24 min

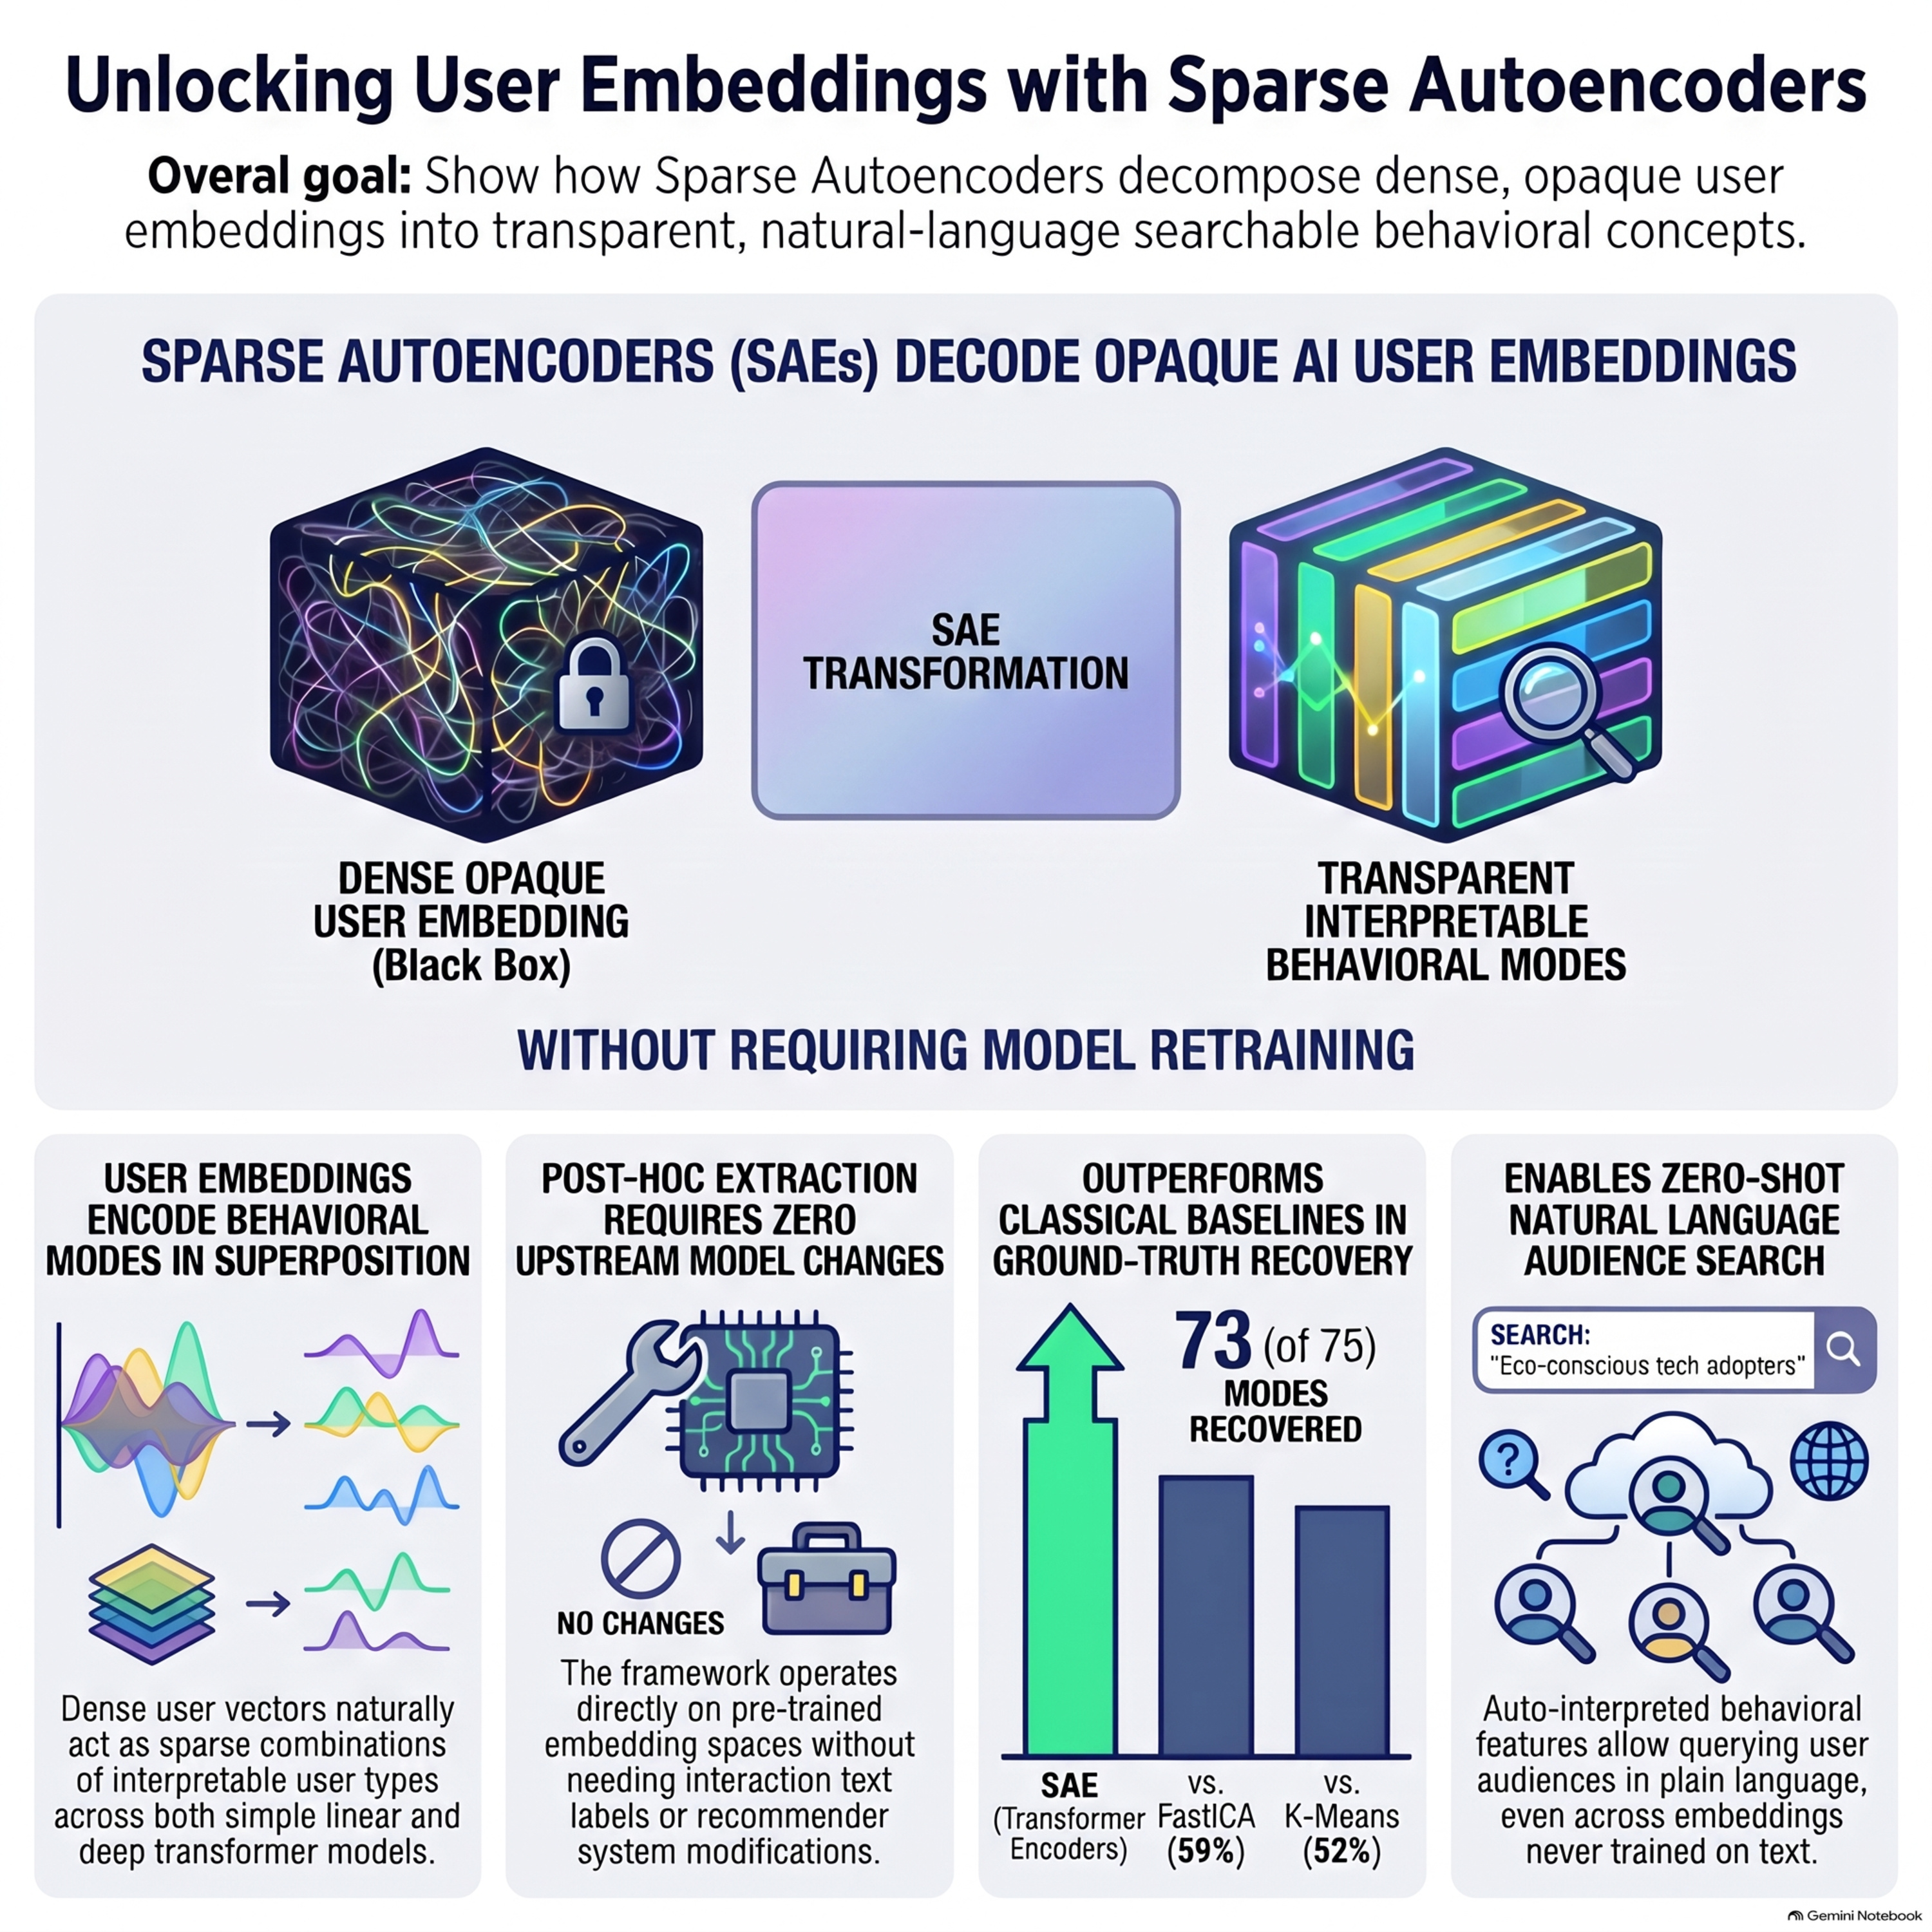
    User Embeddings are Superpositions of Interpretable Behavioral Modes

    This paper explores how sparse autoencoders can be applied to user embeddings to uncover hidden behavioral modes without needing raw interaction data or text-aligned training. By treating user representations as sparse superpositions of interpretable concepts, this post-hoc, model-agnostic framework enables zero-shot natural language audience retrieval and fine-grained characterization. Extensive validation on synthetic data, e-commerce records, and transformer-based sequential recommenders demonstrates that sparse autoencoders successfully recover underlying behavioral structures while outperforming classical dimensionality reduction methods in reconstruction fidelity, ranking quality, and feature diversity.

  • November 8 · 23 min

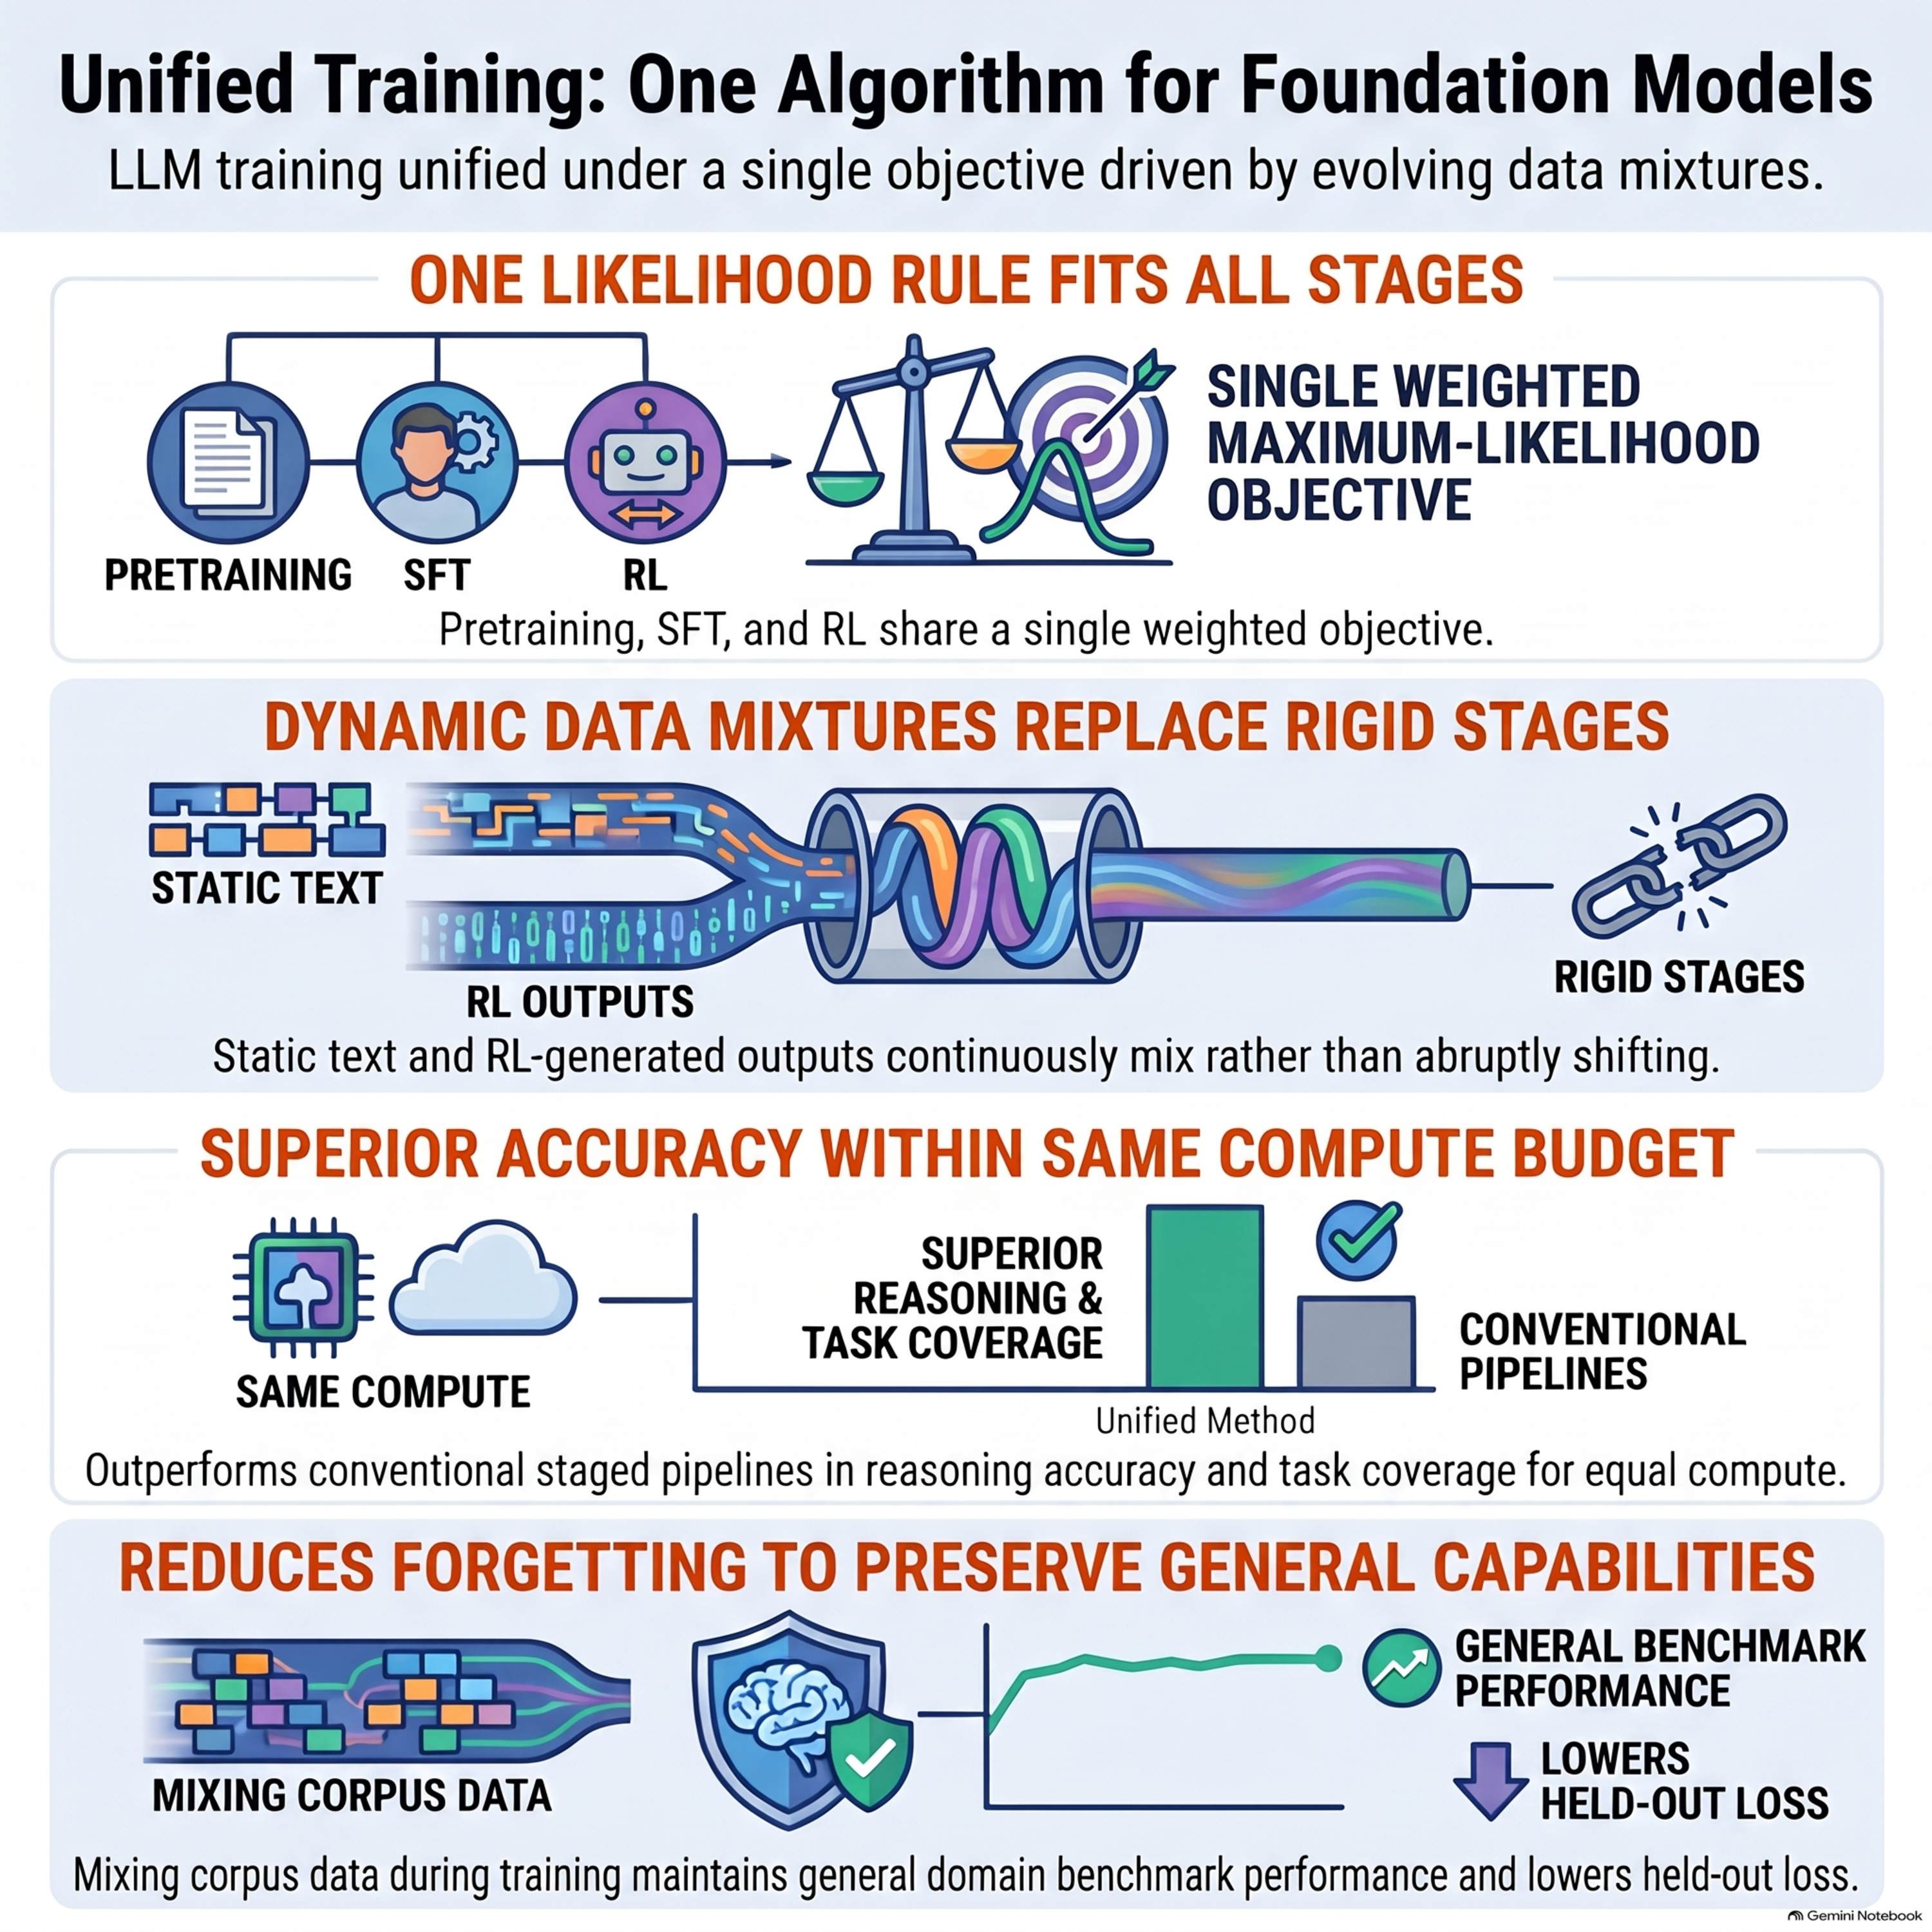
    Training Foundation Models with a Single Algorithm

    Foundation models are traditionally trained through a sequential pipeline of distinct phases, including pretraining, fine-tuning, and reinforcement learning. Researchers demonstrate that this algorithmic separation is unnecessary by framing these diverse phases as maximum-likelihood fitting to evolving data targets under a unified training system. This approach integrates static corpora and model-generated responses into a single objective, transforming training design into a strategic problem of data composition, timing, and mixing proportions. Extensive experiments reveal that unified training improves task accuracy, compute efficiency, and generalization while providing a superior starting point for continual learning.

  • November 4 · 23 min

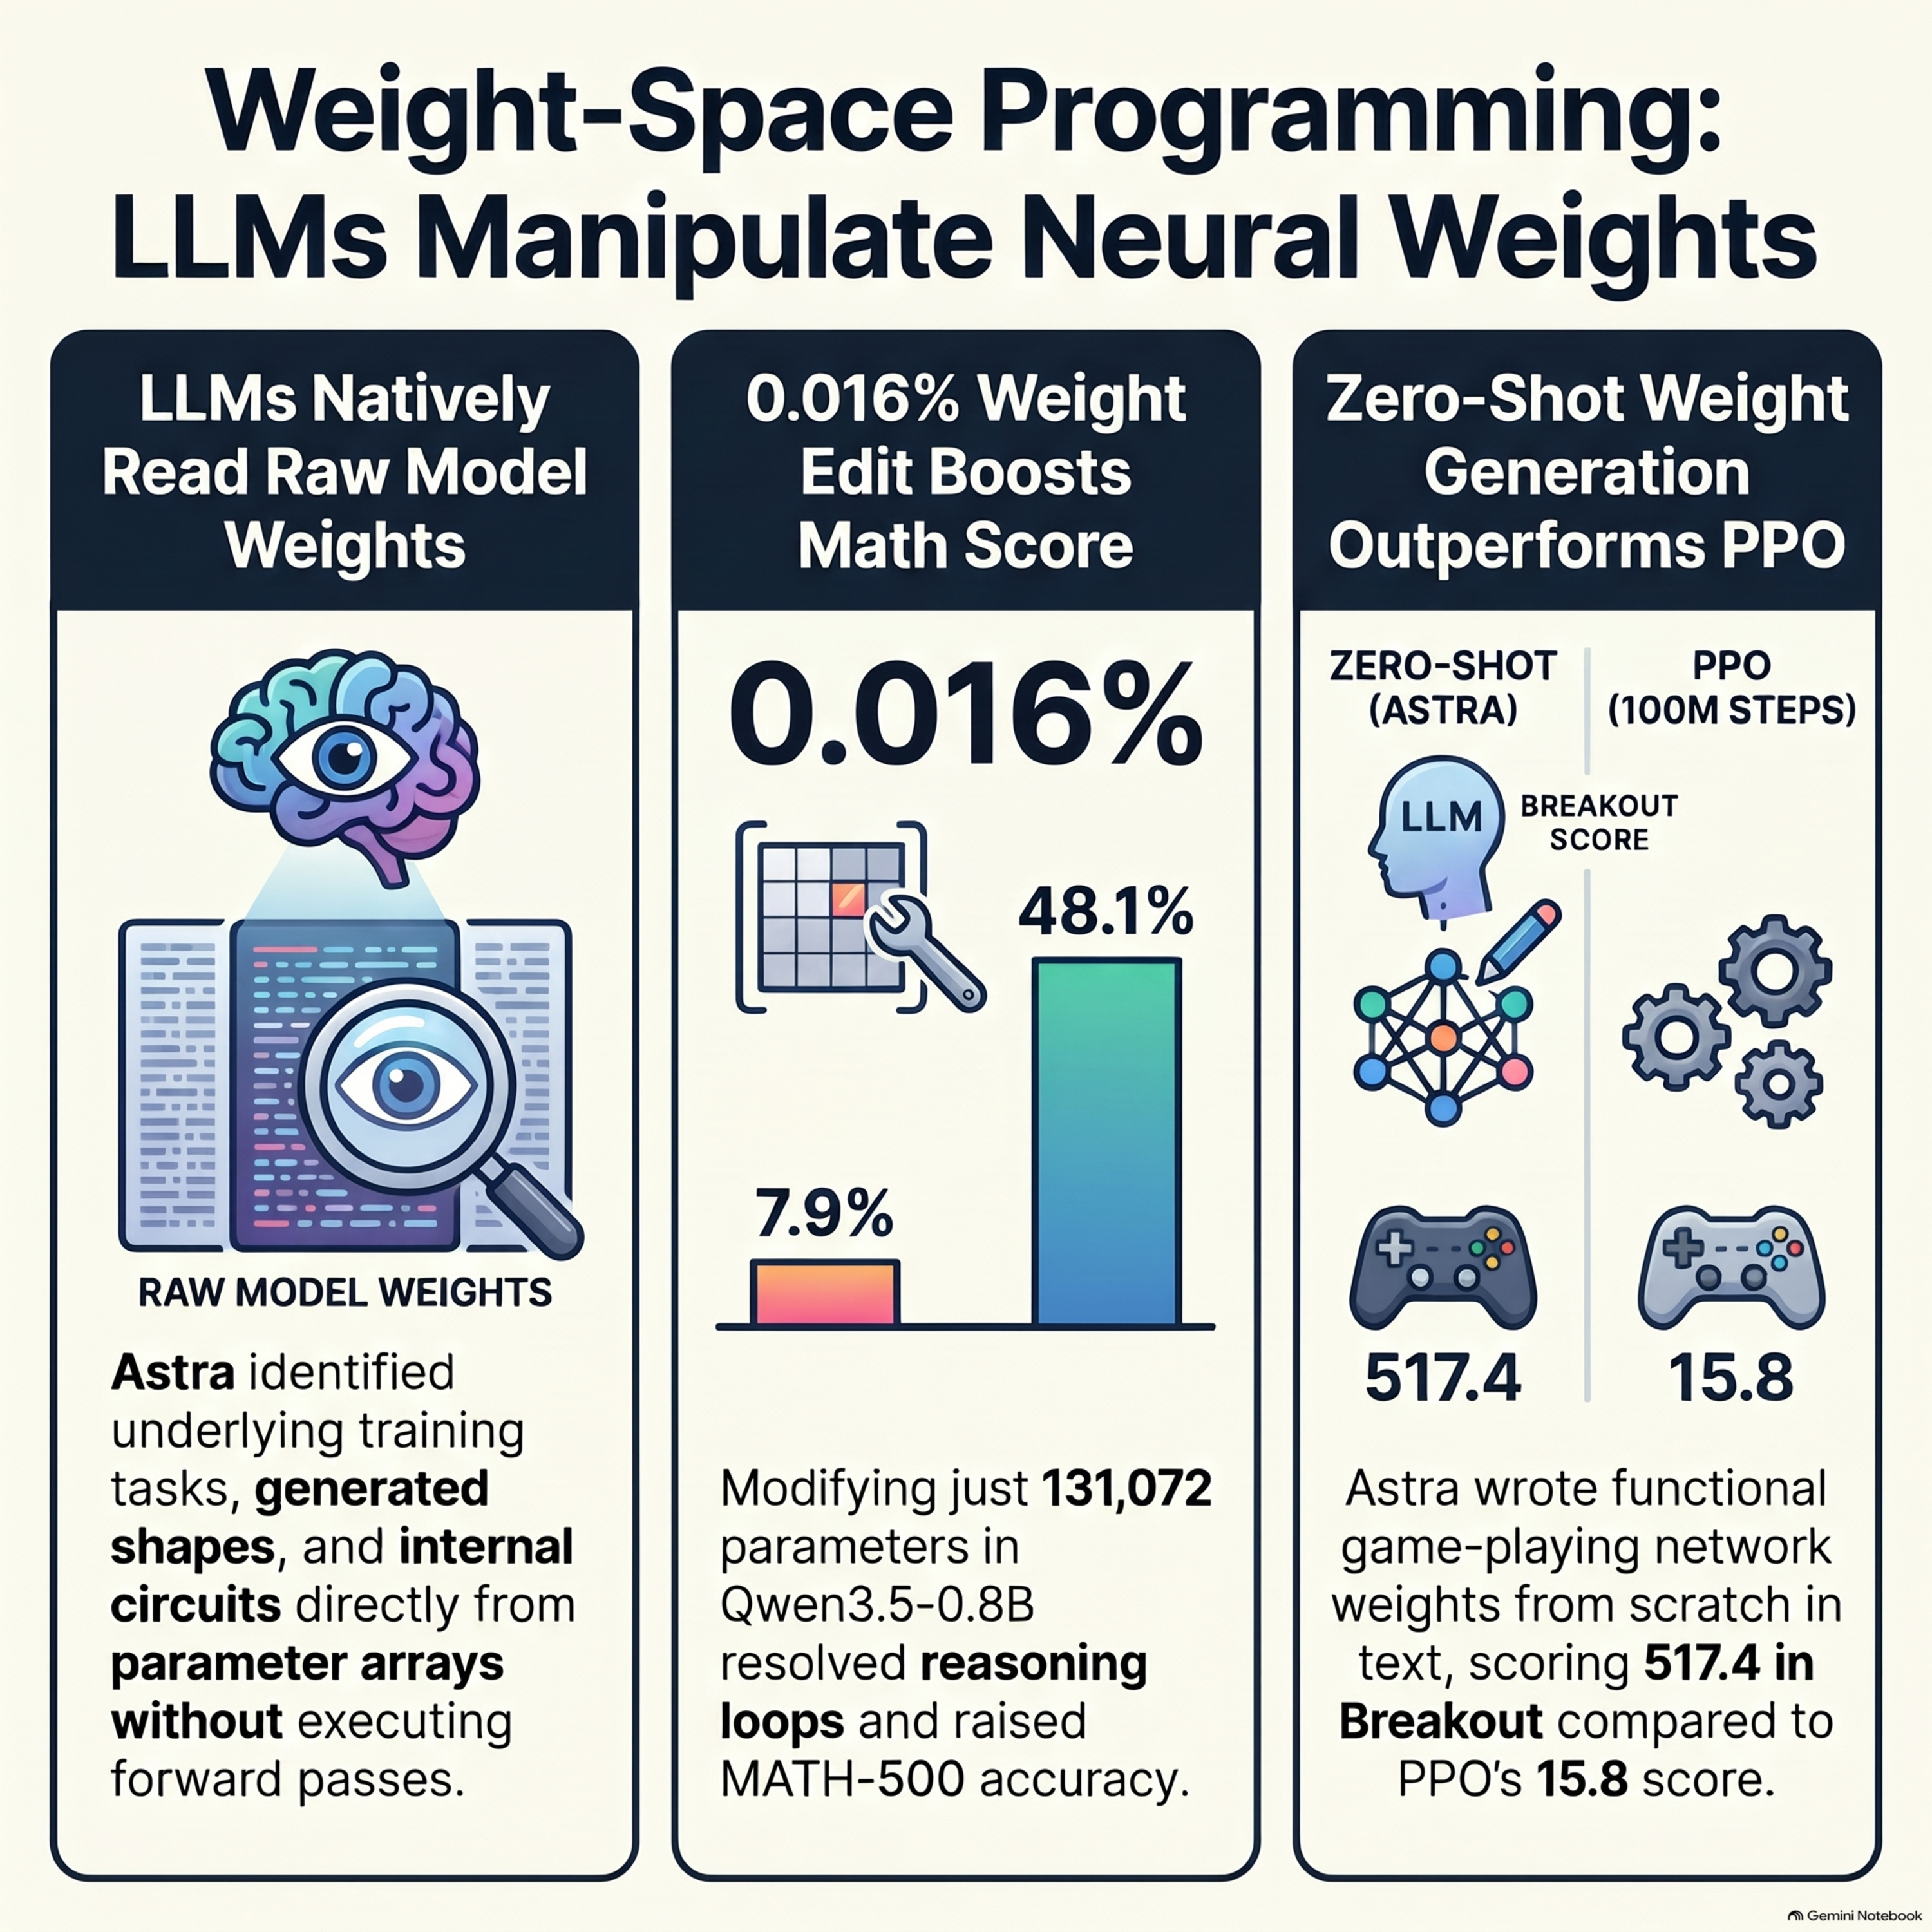
    Sparks of Weight-Space Programming: LLMs can natively read & write neural network weights

    Frontier large language models demonstrate a surprising capacity for weight-space programming, meaning they can naturally comprehend, evaluate, and modify the raw parameters of neural networks without relying on traditional gradient-based training. Through this paradigm, advanced systems like GPT-6 Astra can analyze a model's numeric weights to accurately determine its intended function, such as identifying a specific game or recognizing the training language from intermediate transformer blocks. Furthermore, these language models can directly edit or construct functional neural network weightsfrom scratch to solve physical control tasks or outperform heavily optimized reinforcement learning agents. When applied to larger language models, such targeted weight corrections can successfully eliminate repetitive reasoning loops and significantly enhance mathematical reasoning capabilities. Ultimately, this approach establishes a direct bridge between natural language instructions and continuous weight spaces, offering new possibilities for mechanistic interpretability and efficient model optimization.

  • November 2 · 20 min

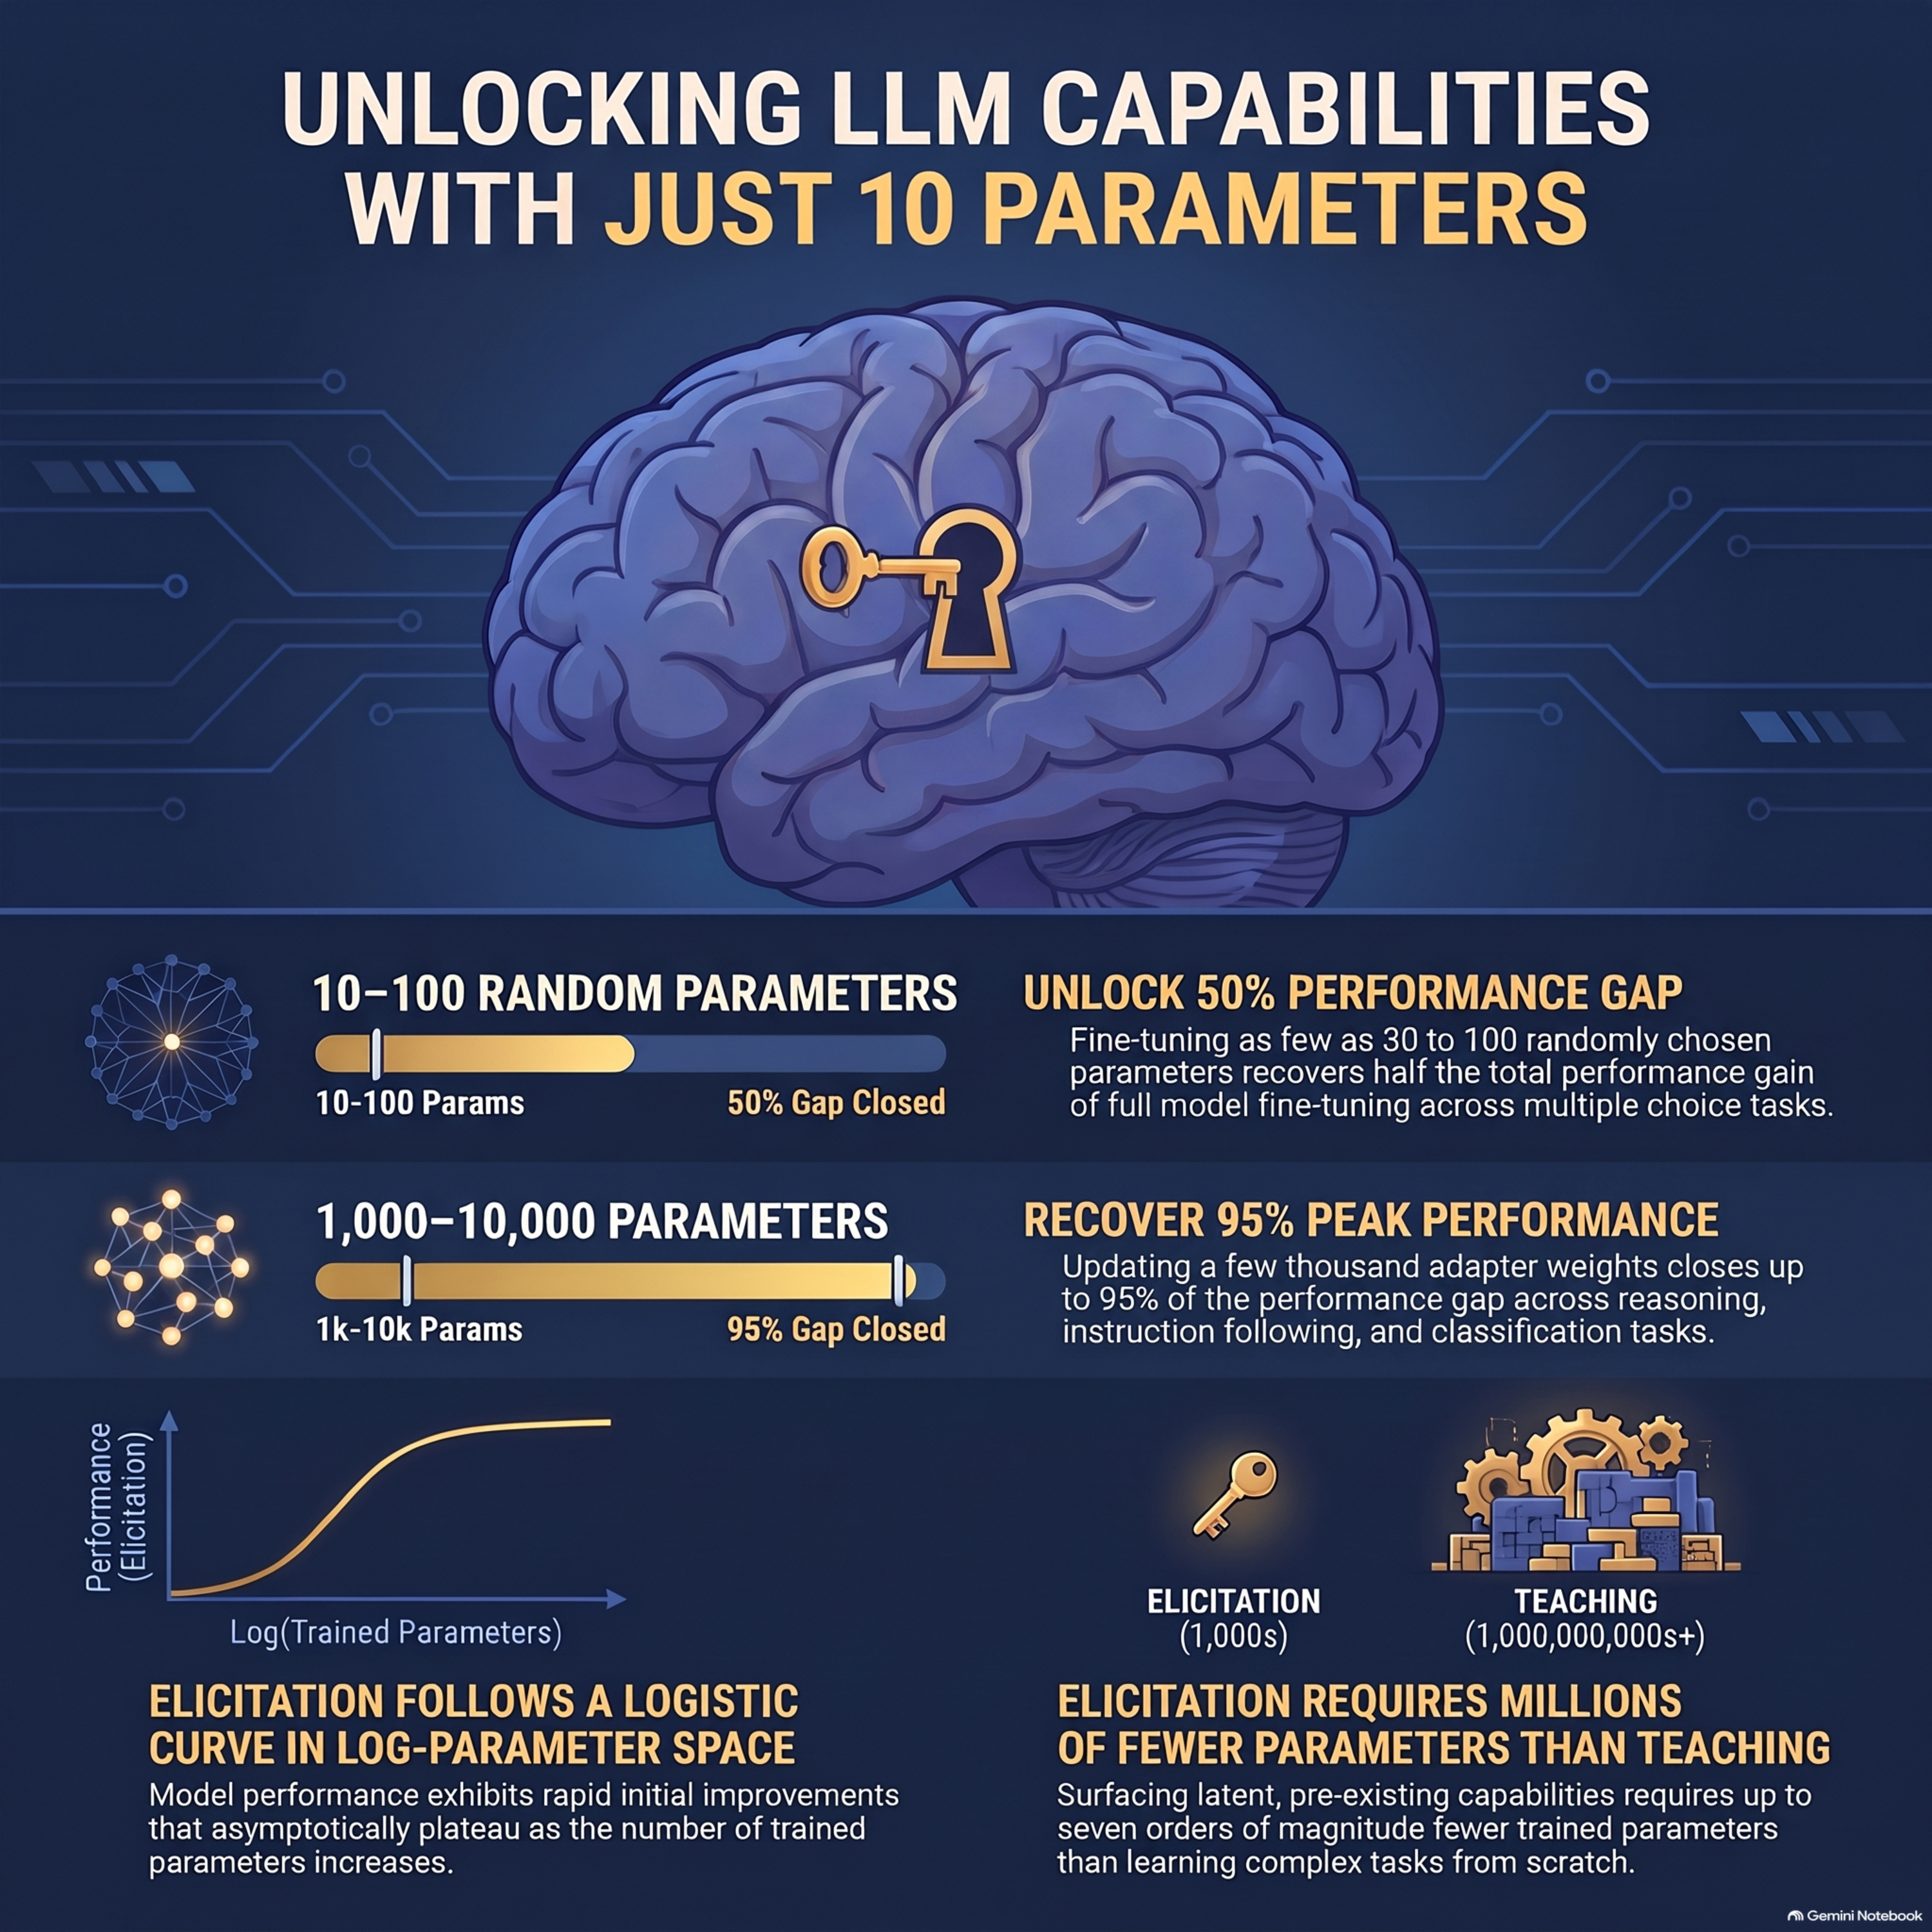
    Quantifying Elicitation of Latent Capabilities in Language Models

    This paper investigates how large language models unlock latent capabilities through fine-tuning, reframing the process as an information-constrained problem. By analyzing parameter-efficient fine-tuning using randomly chosen parameters, the authors demonstrate that training a tiny fraction of a model's weights—often as few as tens to thousands—can recover the vast majority of its full performance gap. This behavior follows a consistent logistic scaling relationship across various tasks, model sizes, and families, independent of specialized search methods. Furthermore, the study applies Rissanen's Minimum Description Length (MDL) principle to distinguish true capability elicitation from teaching new skills, offering insights that can improve capability forecasting and safety evaluations.

  • October 30 · 19 min

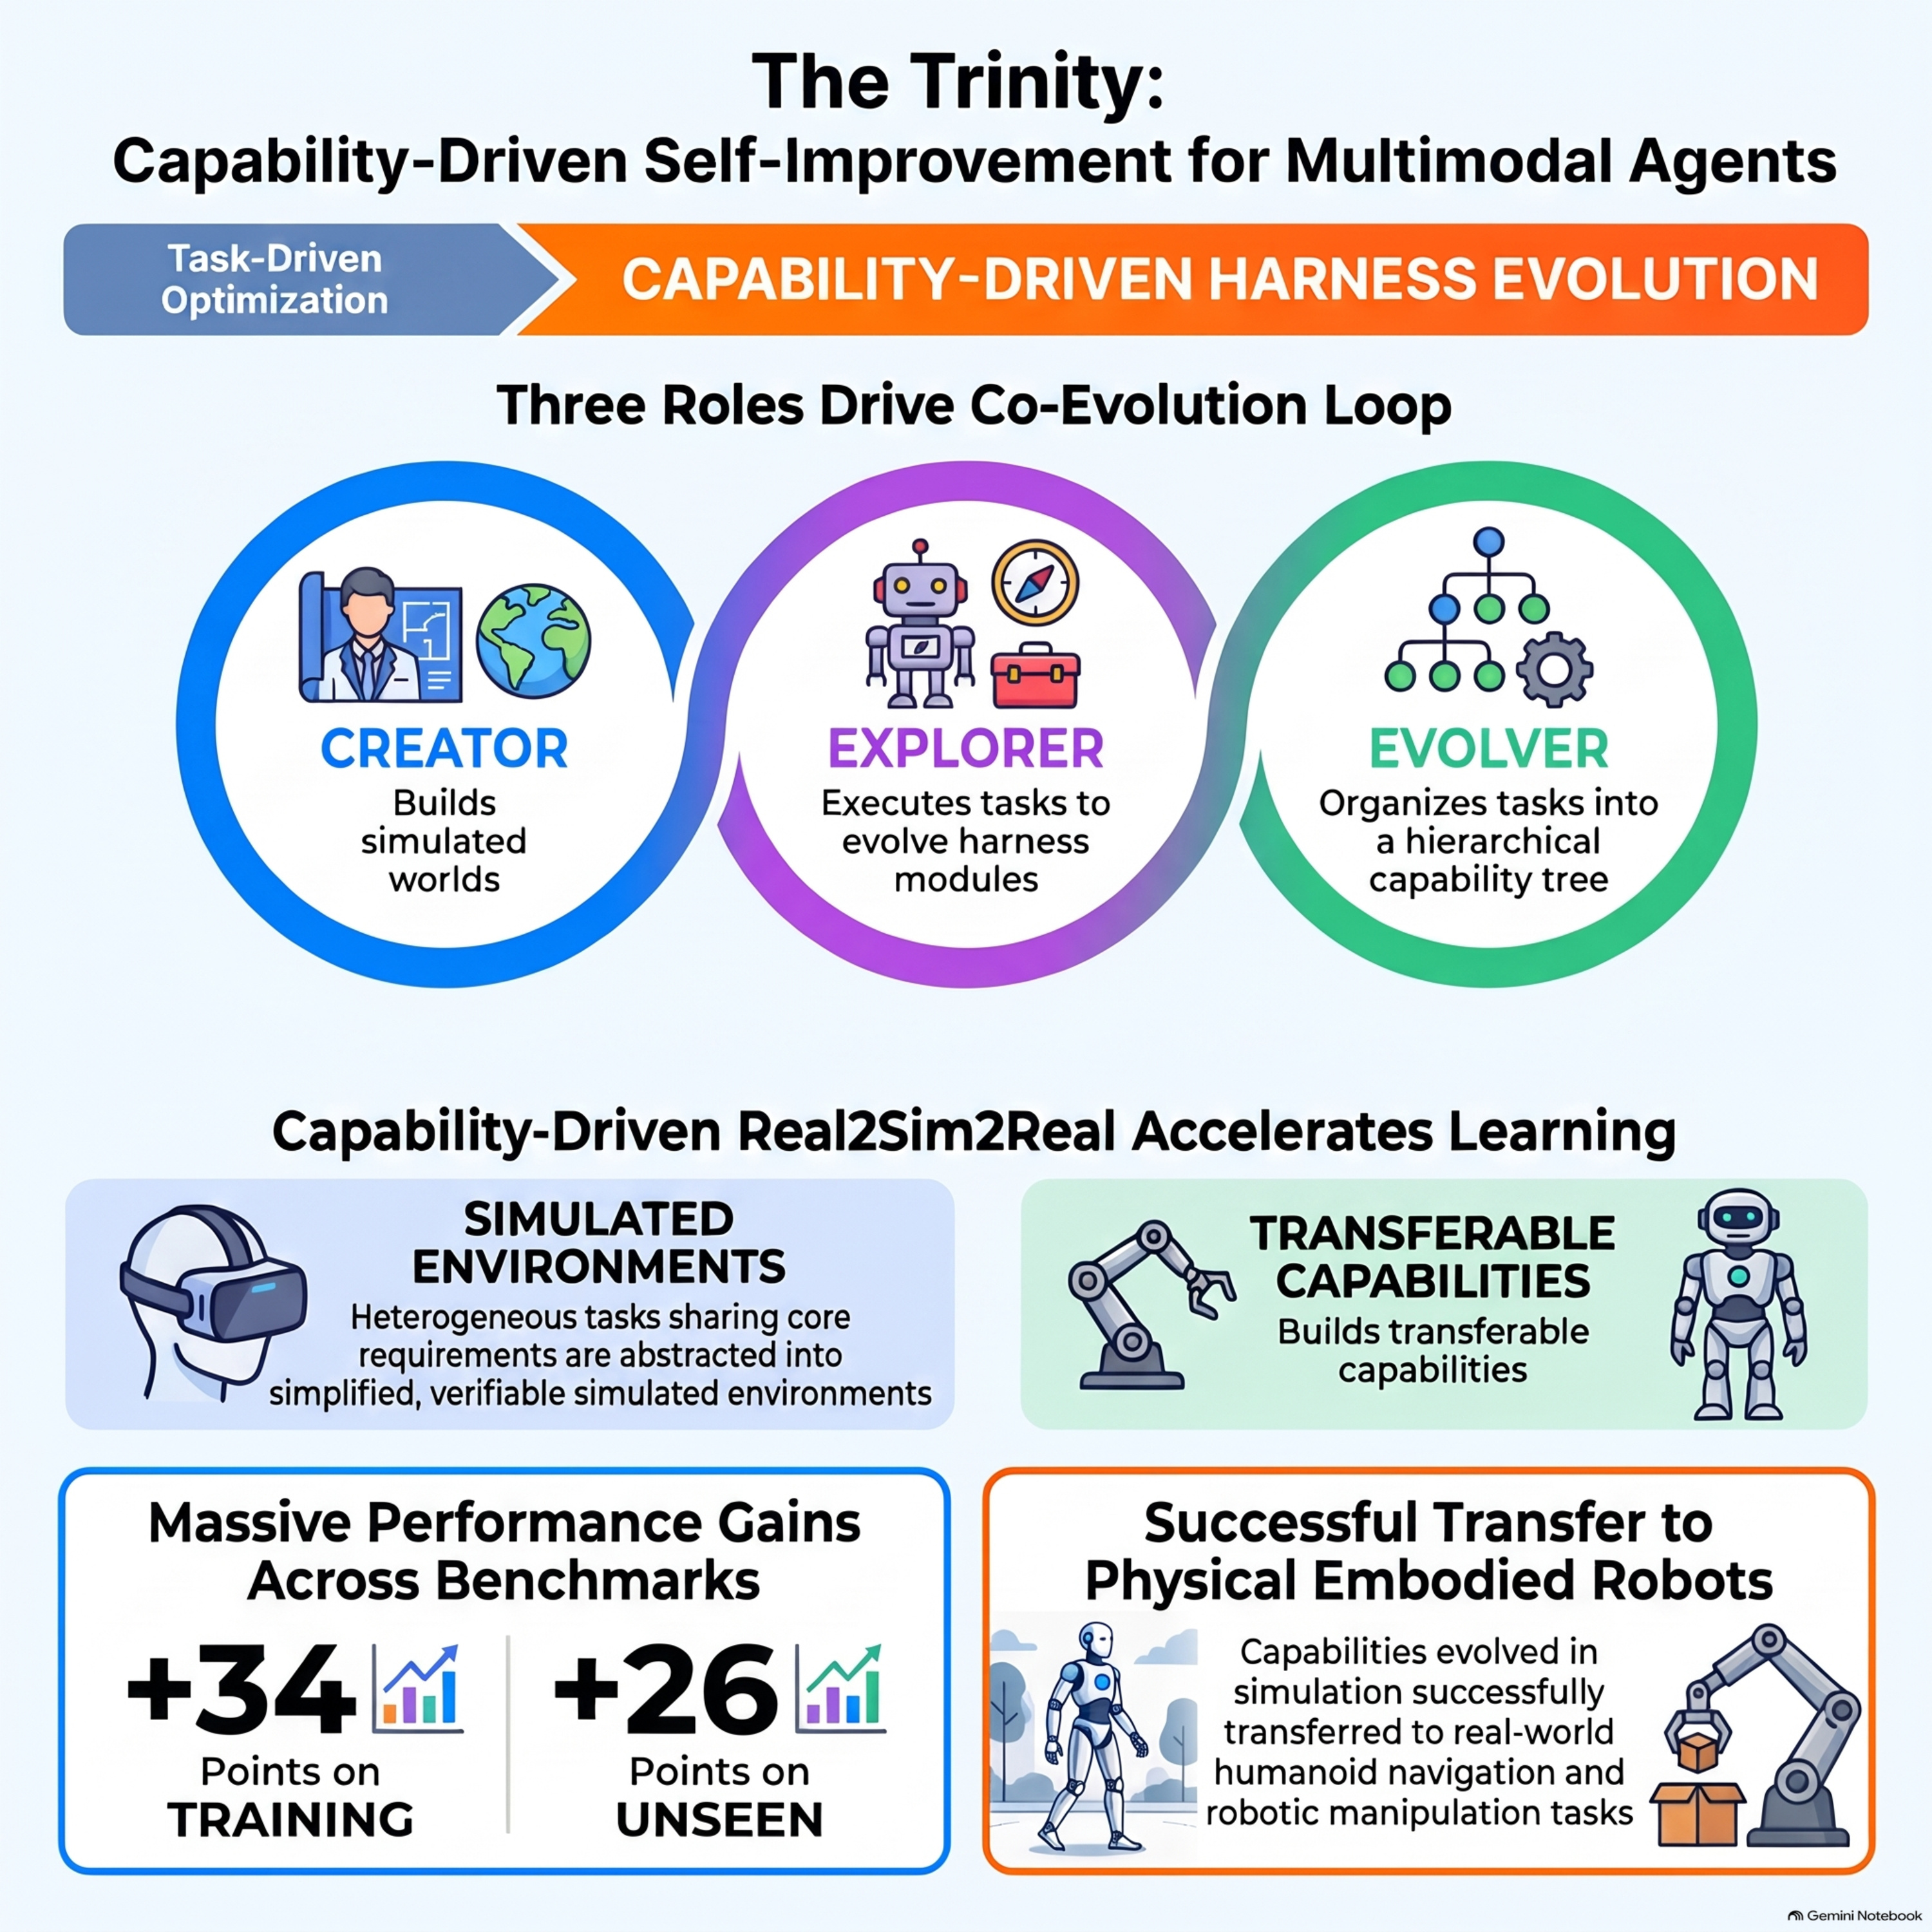
    The Trinity: Capability-Driven Recursive Self-Improvement for Multimodal Agents

    This paper introduce The Trinity, a recursive self-improvement framework designed to scale multimodal intelligence by coupling automated environment generation with agent evolution. Instead of relying on traditional task-specific optimization, the system groups diverse tasks into a hierarchical capability tree based on shared underlying requirements. Through a process called Capability-Driven Real2Sim2Real, the framework constructs simplified, verifiable simulation worlds where specialized Harness configurations continuously refine their reusable modules. A Capability-Aware Harness Router then utilizes public task information and verified execution experience to match new tasks with the most suitable Harness branch. Ultimately, this approach successfully improves performance across numerous training and unseen benchmarks while demonstrating effective transfer to physical, real-world embodied settings.

  • October 28 · 20 min

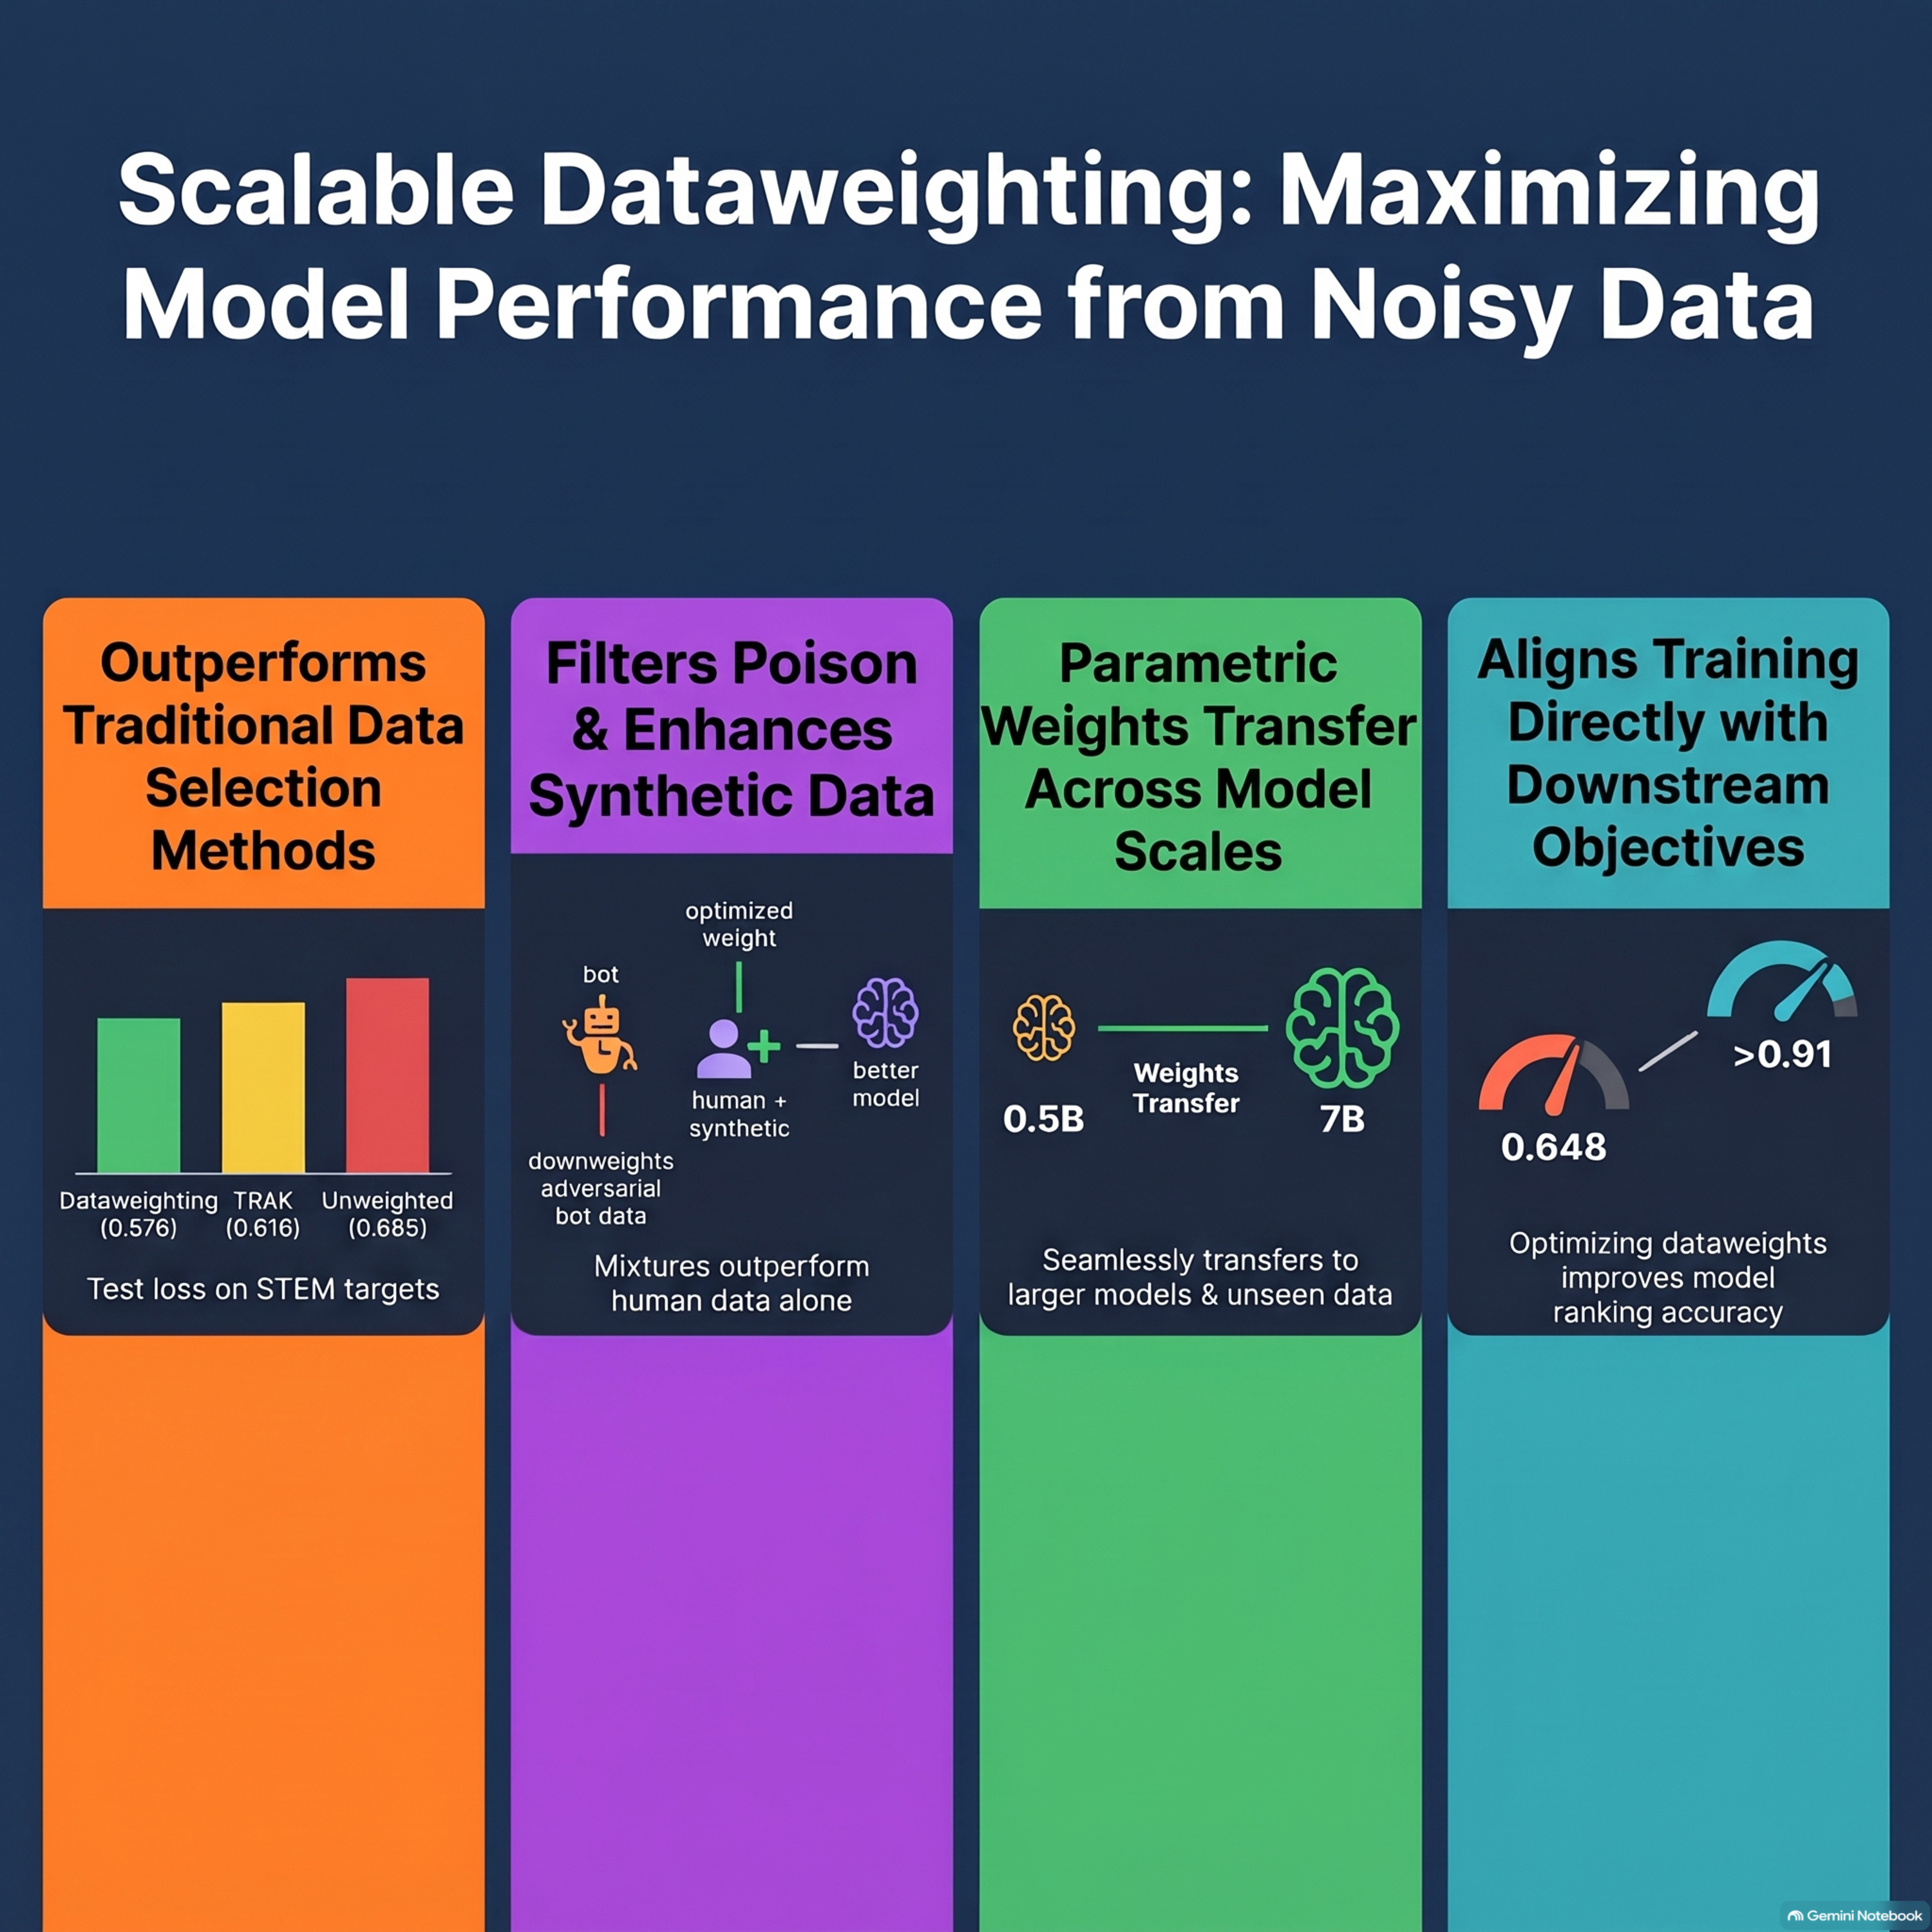
    High-Value Training Data from Noisy, Diverse Sources

    Training advanced machine learning models typically relies on vast, heterogeneous datasets containing noisy, adversarial, or mismatched data. To address this challenge, the authors introduce dataweighting, a scalable framework that assigns specific weights to training examples based on their actual impact on performance. Instead of relying on manual heuristics or aggressive data filtering, this method uses metagradient descent to dynamically optimize training weights against a small, high-quality target dataset. Furthermore, the approach implements parametric dataweights that successfully transfer across different model scales and generalize to previously unseen training inputs. Ultimately, this technique improves model performance across various applications, successfully integrating synthetic supervision and optimizing complex downstream objectives like ranking accuracy.

  • October 27 · 21 min

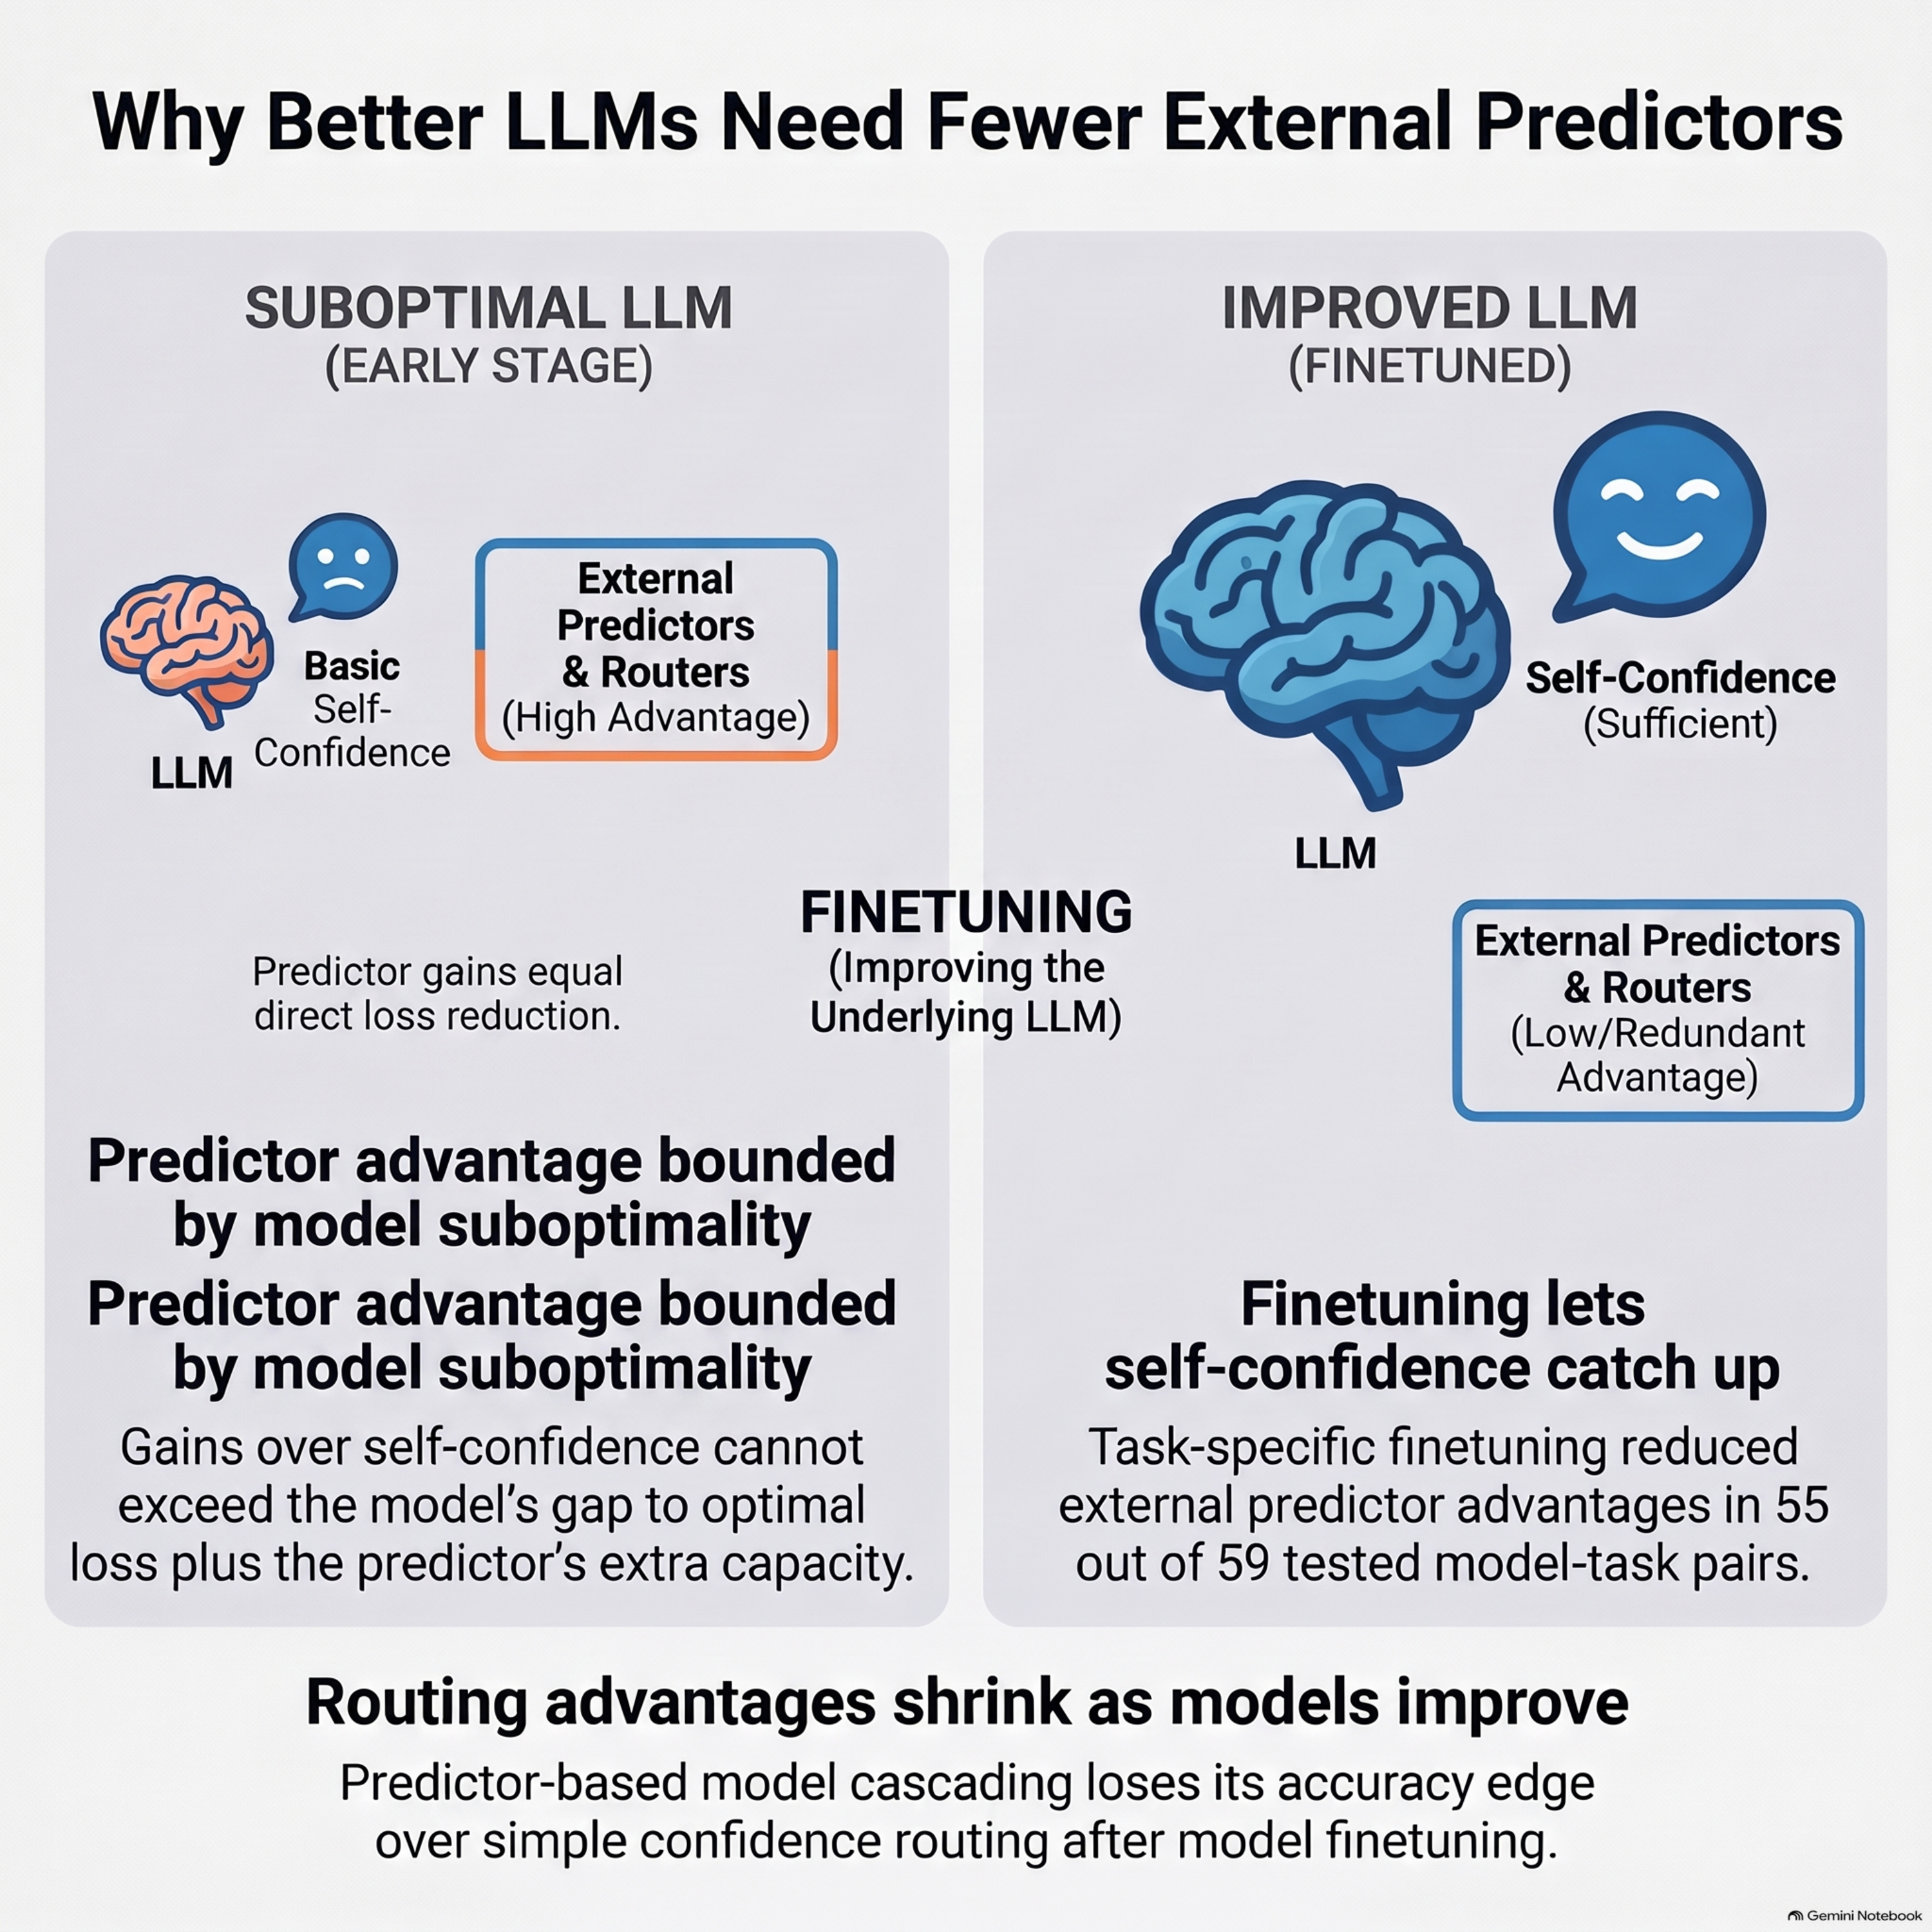
    Predictable Performance in Model Routing and Cascades

    Recent research explores performance prediction and model routing in large language models by studying when and why an AI's errors are predictable. The authors demonstrate that any performance predictor surpassing a model's self-confidence can directly improve the model's answer loss through recalibration. Furthermore, a predictor's advantage is strictly bounded by the model's suboptimality combined with the additional parameter capacity of the predictor. Empirical experiments across multiple benchmarks reveal that less optimal models yield greater prediction and routing advantages, which naturally diminish after task-specific finetuning. Finally, these theoretical limits extend to two-model cascades, showing that stronger routing advantages emerge in suboptimal models before they absorb the benefits of further training.

  • October 26 · 23 min

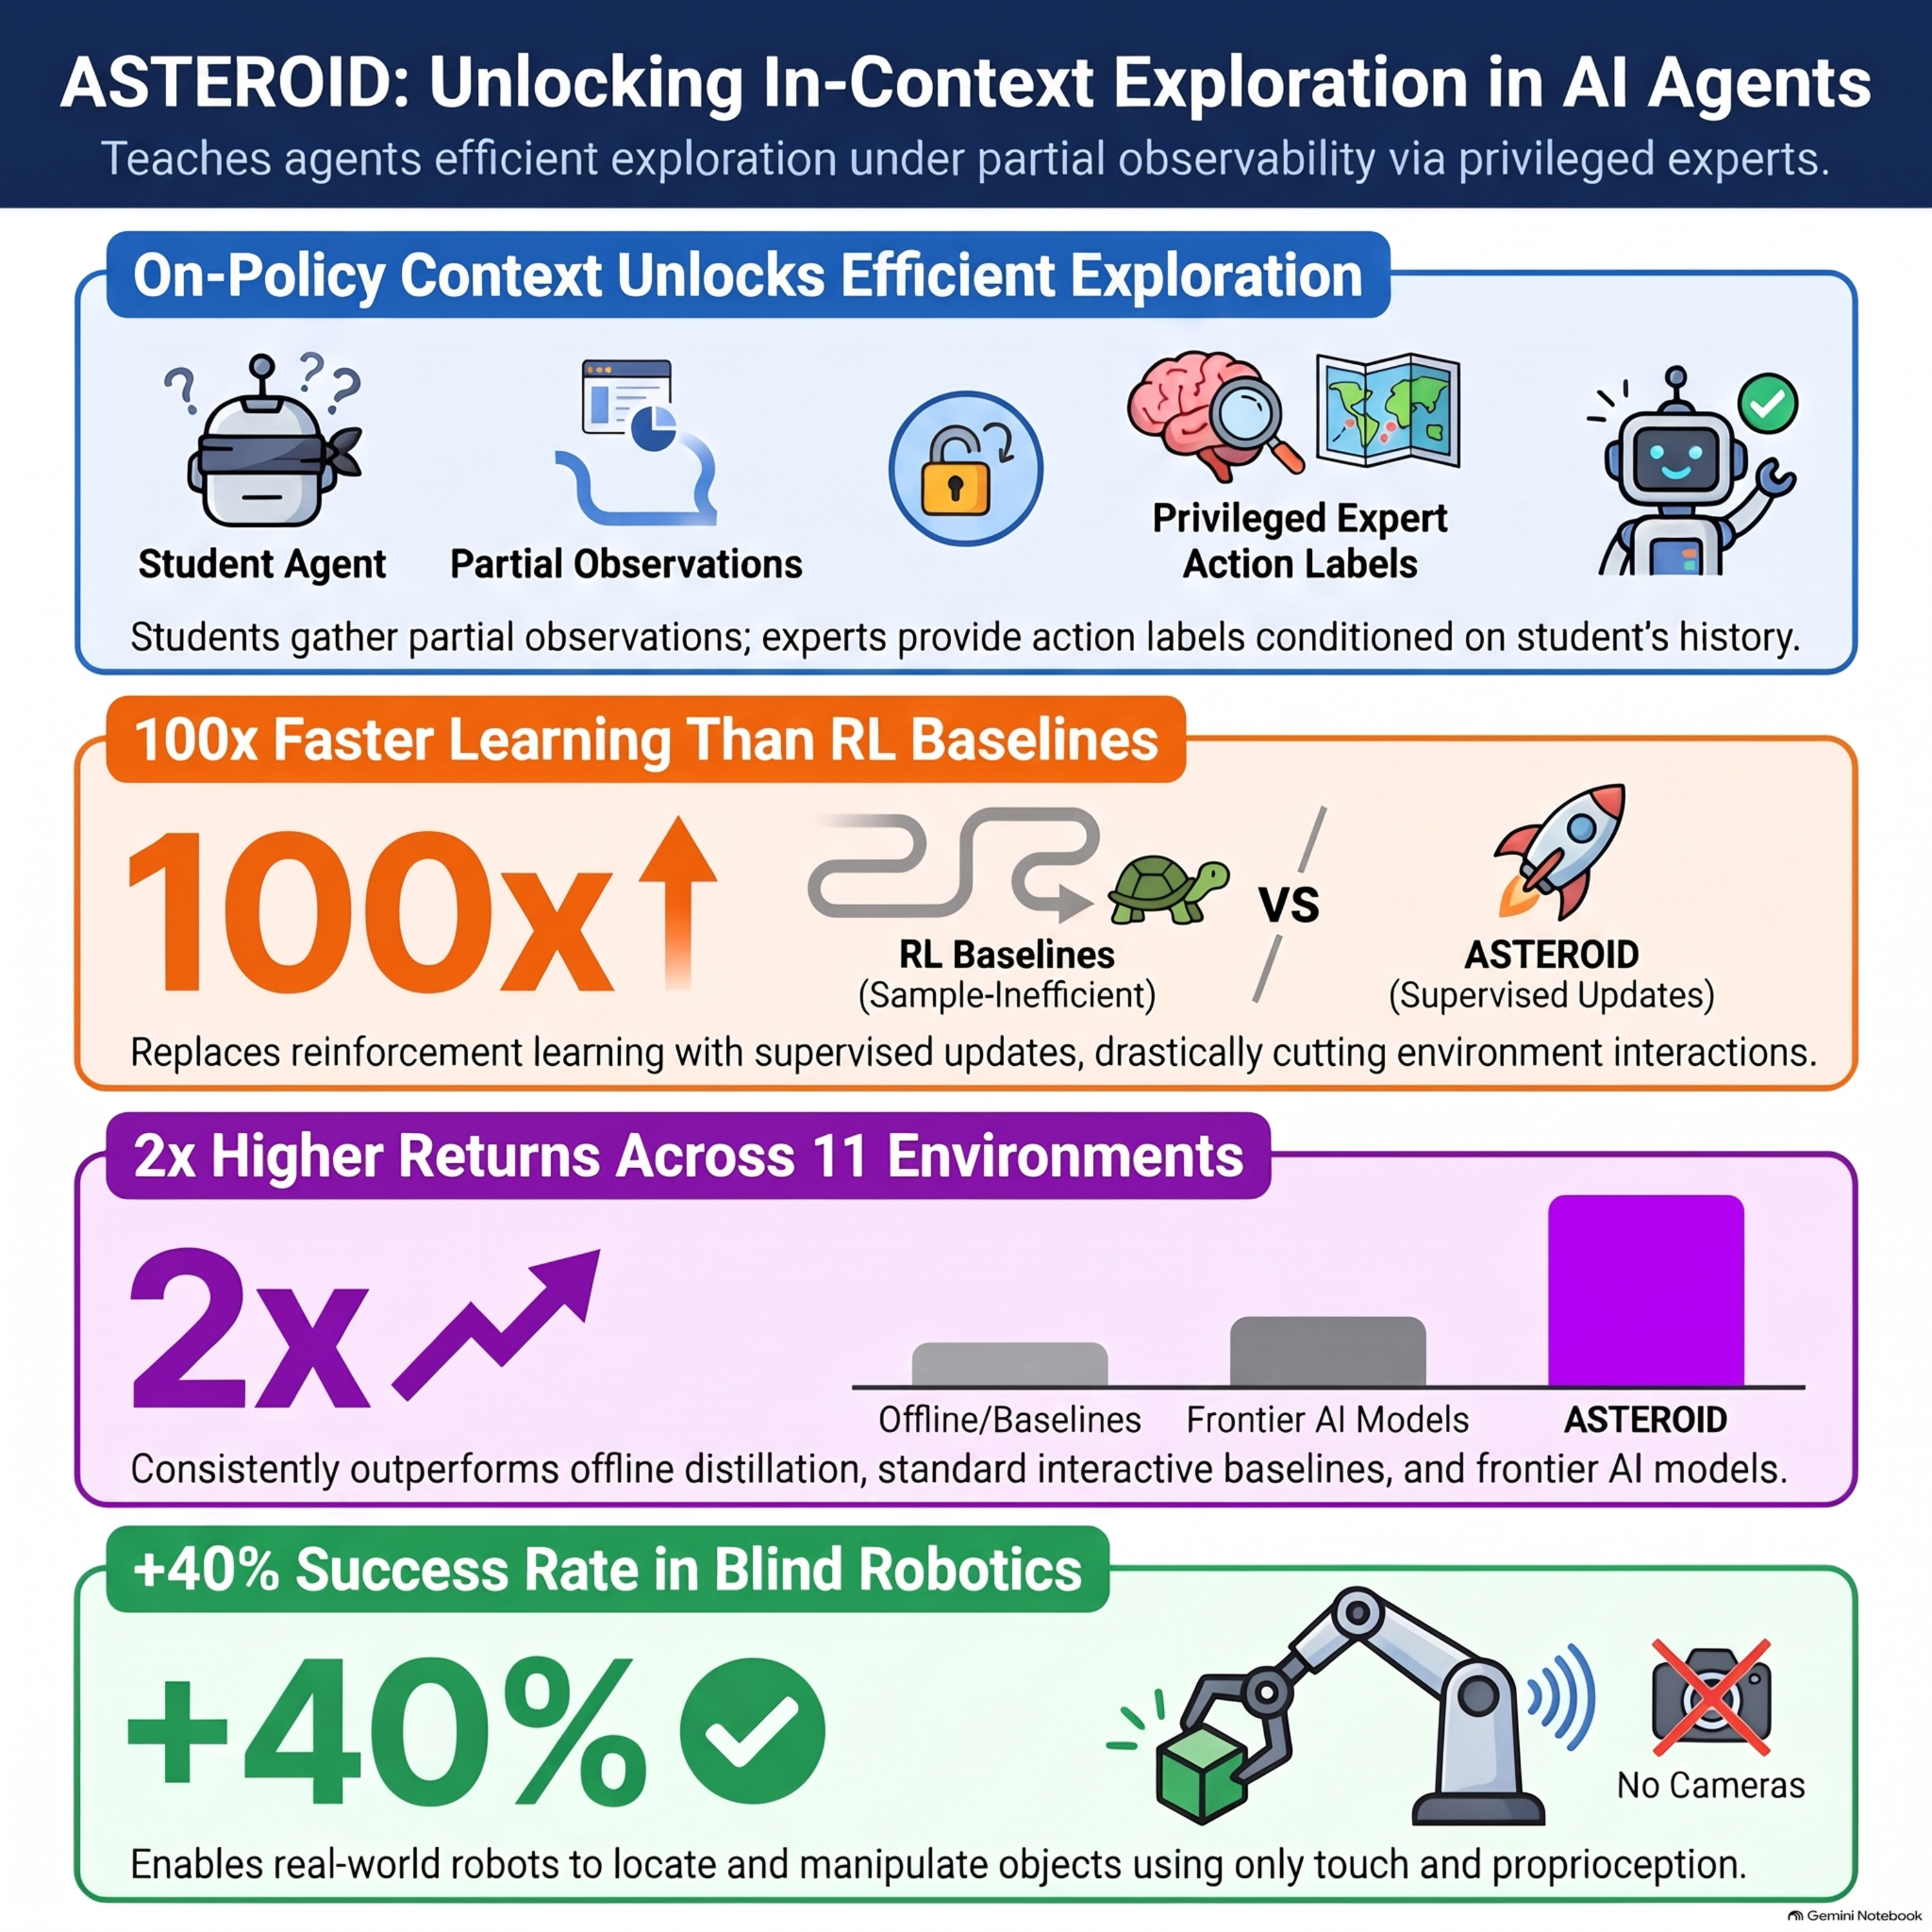
    Asymmetric On-Policy Distillation Learns In-Context Exploration

    We discuss ASTEROID, a novel student-teacher framework designed to address the challenges of sequential decision-making under partial observability. By combining on-policy context collection with expert supervision, the student policy learns effective in-context exploration without requiring expensive online reinforcement learning or impractical full-coverage offline datasets. Across various simulated and real-world environments, this iterative approach significantly outperforms traditional baselines and frontier models in sample efficiency and test-time performance.

  • October 25 · 22 min

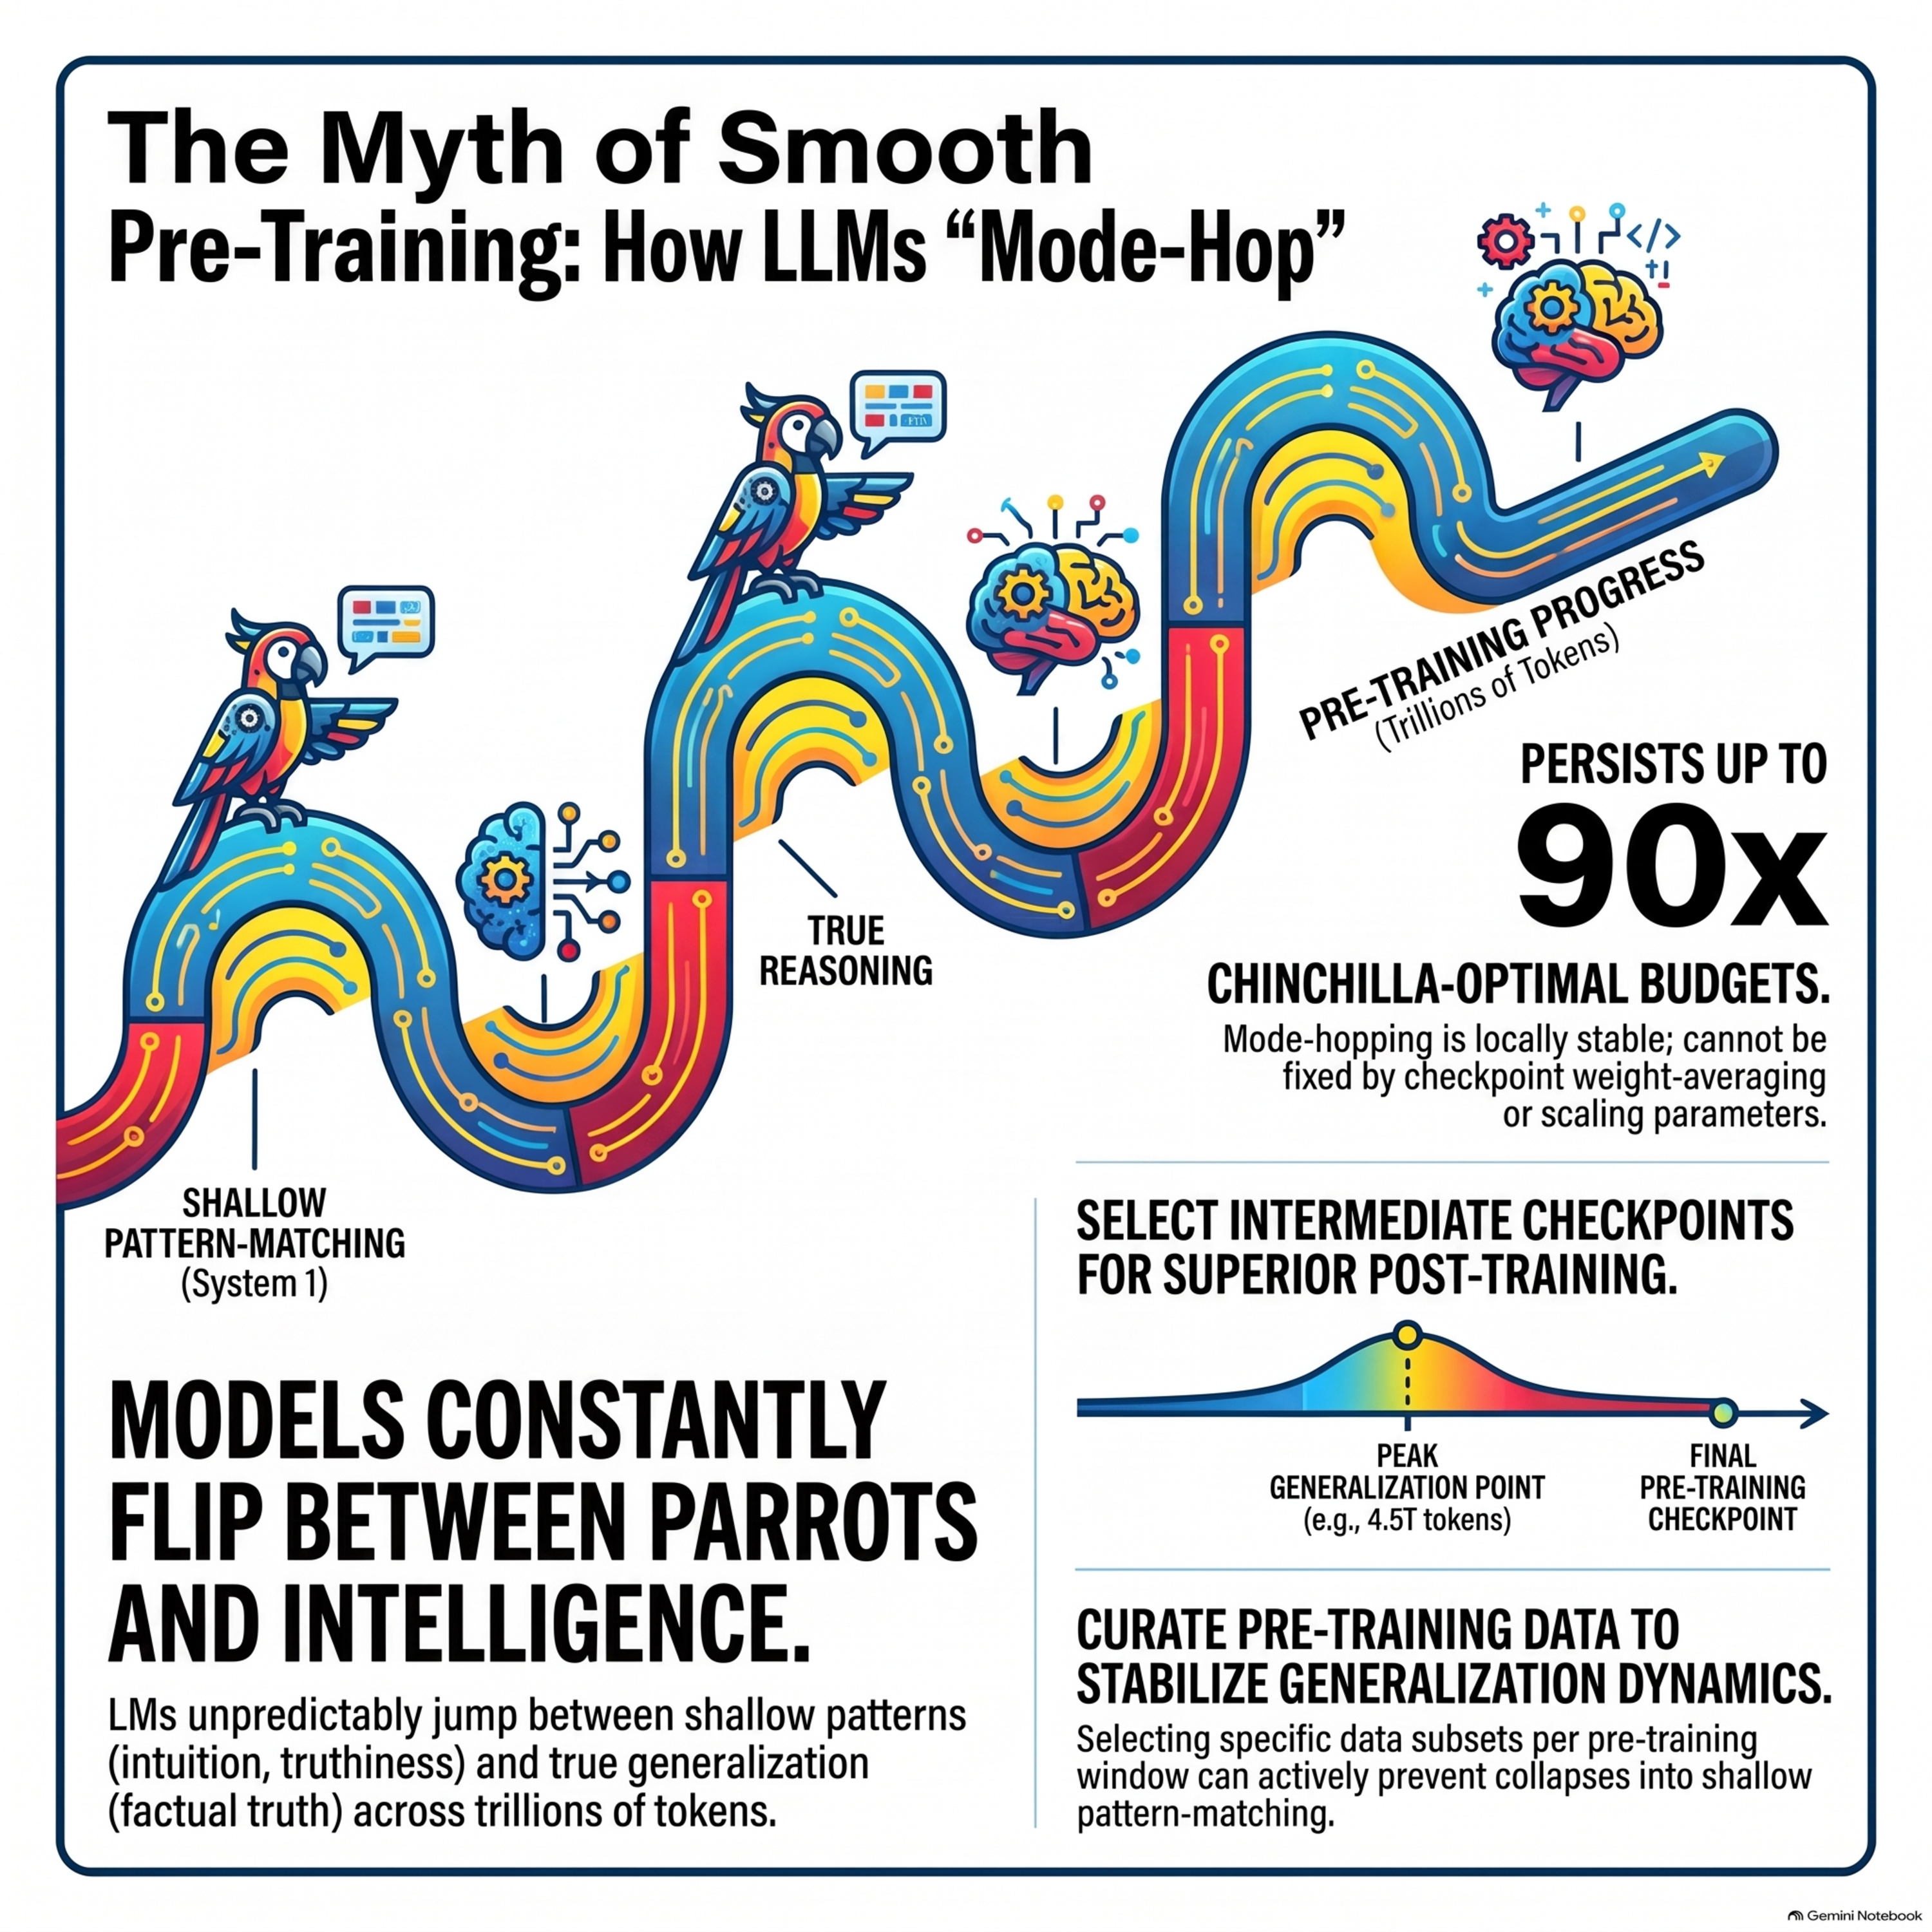
    Generalization Dynamics of Language Model Pretraining

    Large language models often exhibit unexpected behavioral fluctuations during pre-training, repeatedly shifting between memorizing shallow patterns and demonstrating true generalization, a phenomenon termed mode-hopping. This instability occurs independently of standard optimization metrics and persists even after training on trillions of tokens across various model scales. Consequently, tracking these hidden generalization dynamics using targeted evaluation suites enables researchers to identify superior intermediate checkpoints and strategically curate pre-training data to improve reasoning and alignment robustness.

  • October 22 · 21 min

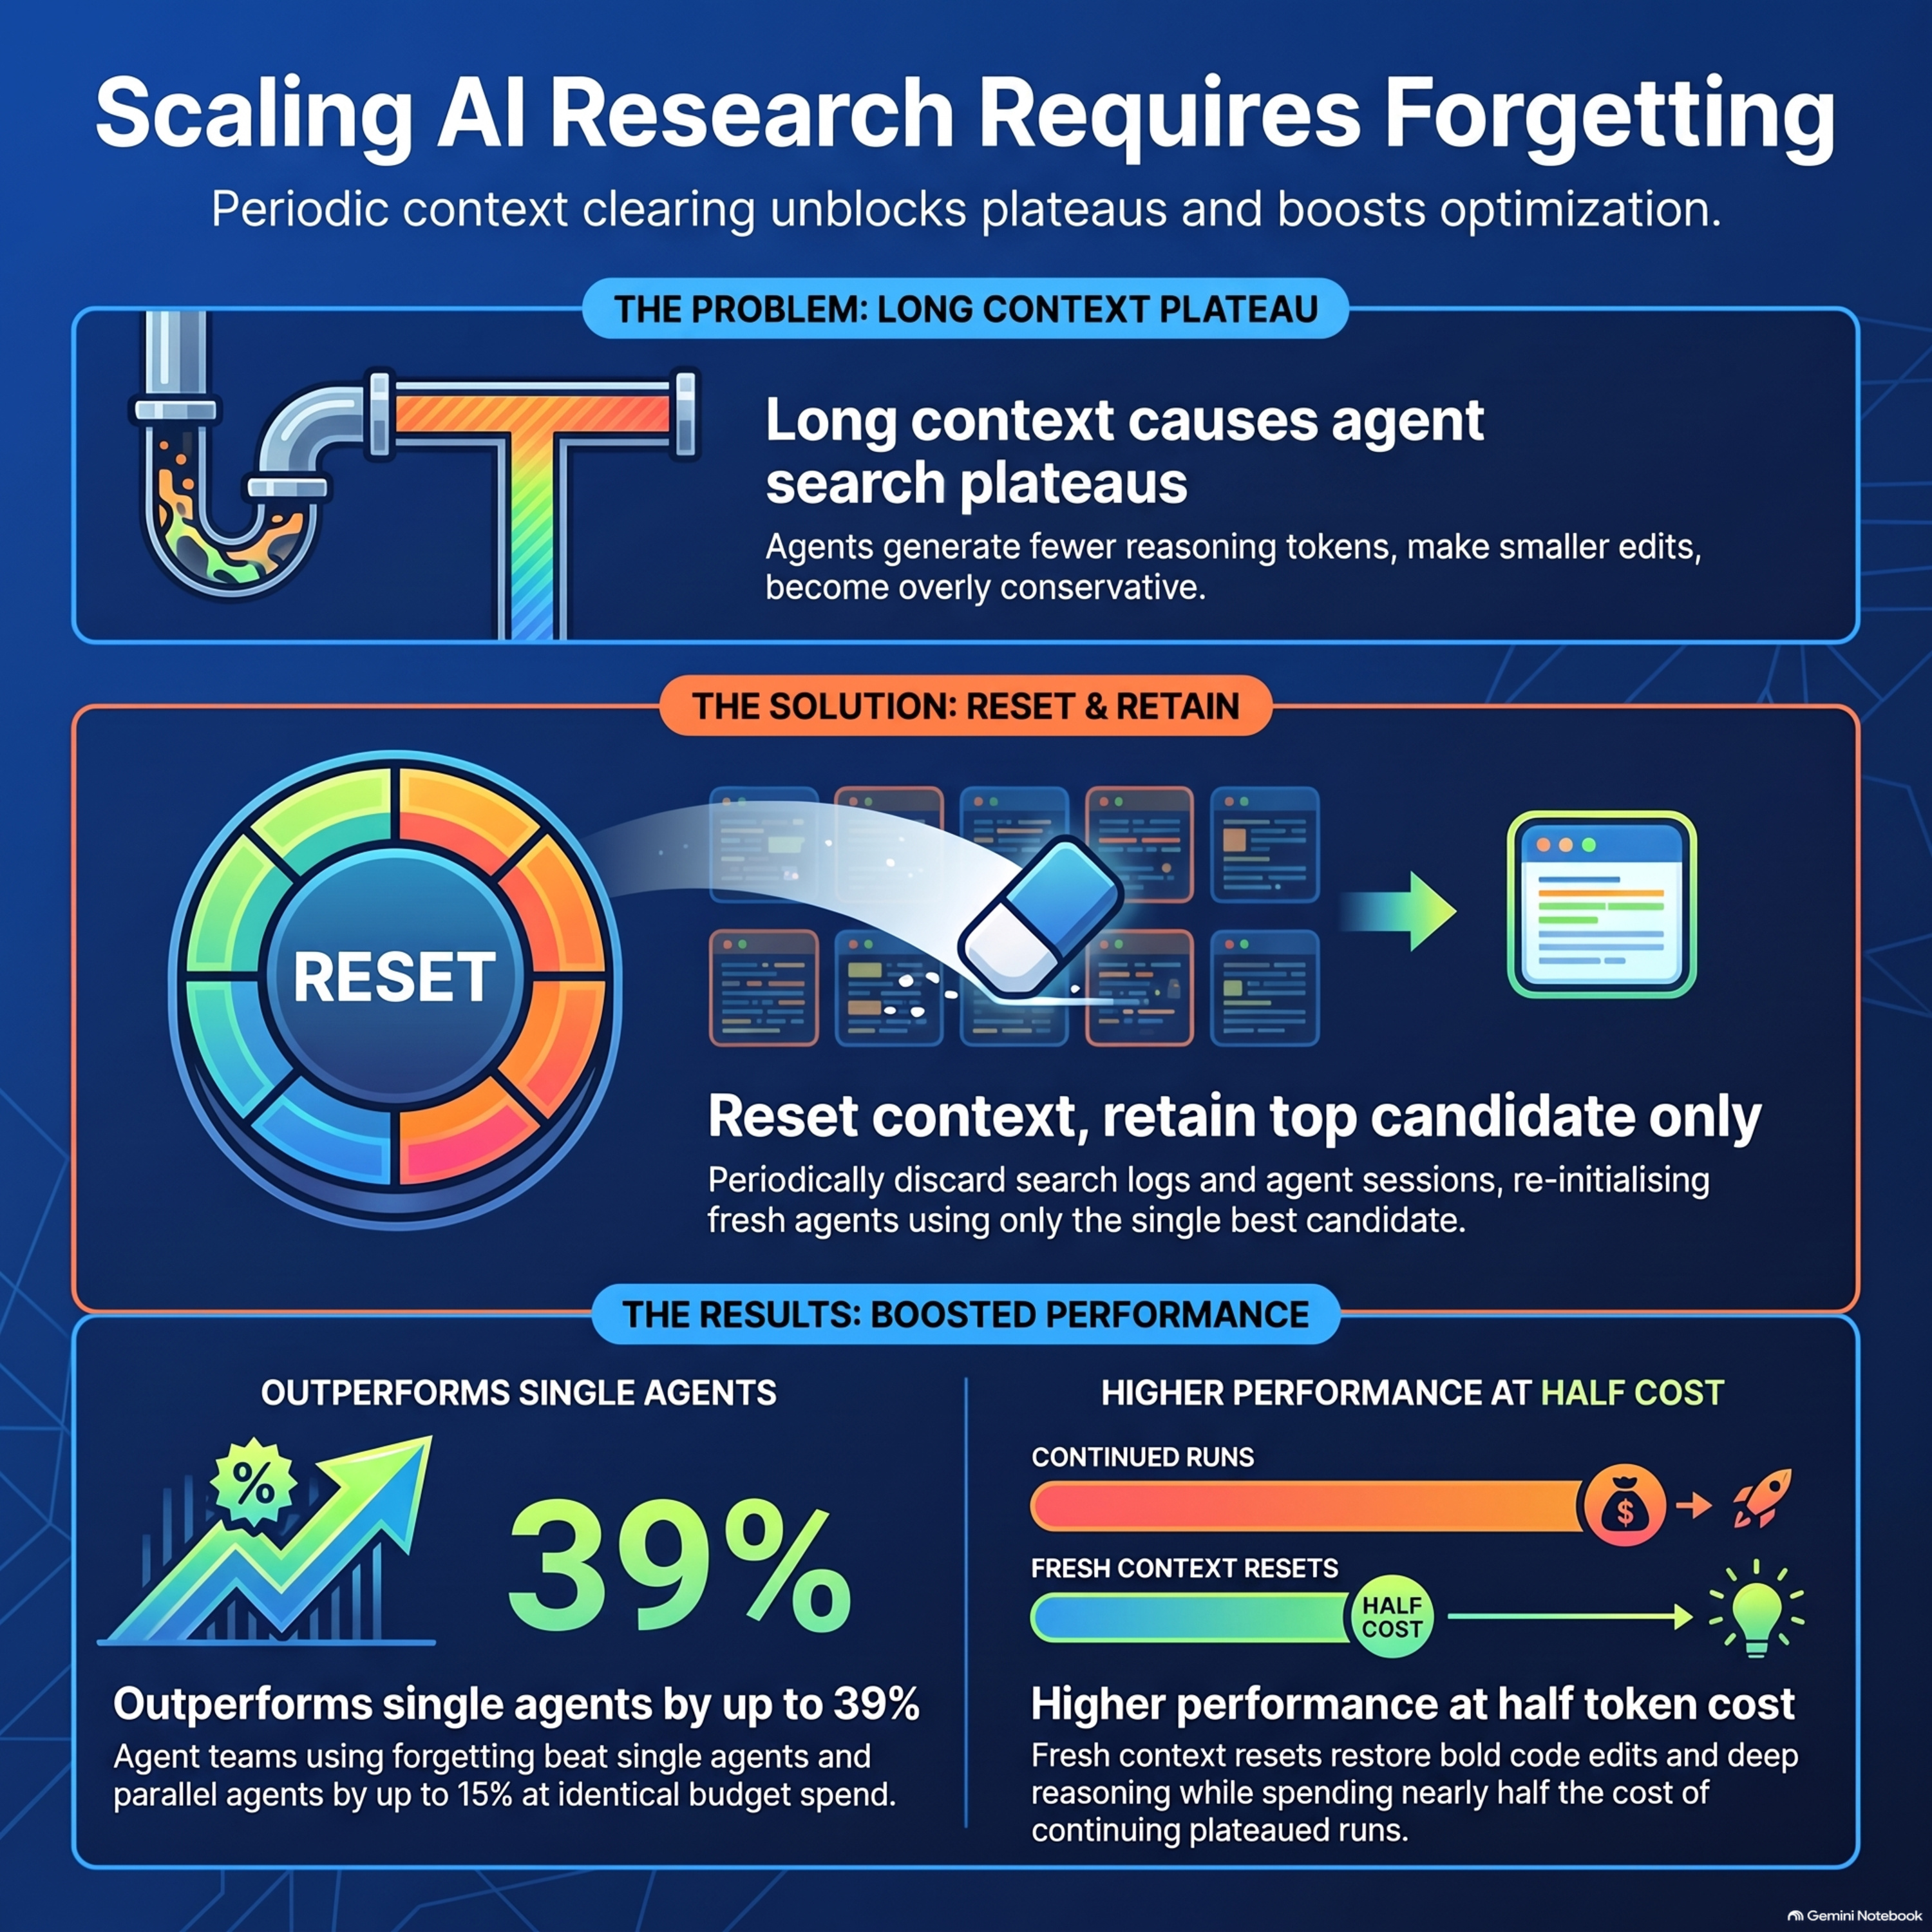
    Scaling Discovery Requires Forgetting

    Automated research agents powered by large language models often experience performance plateaus during open-ended discovery tasks as their accumulated history makes their edits overly conservative. To overcome this limitation, researchers introduce a novel strategy called forgetting, which periodically discards previous agent sessions and candidate search histories while retaining only the single best solution found so far. When combined with a collaborative multi-agent team setup that allows asynchronous communication, this reset mechanism clears out unproductive contextual baggage and unblocks fresh exploration. Experimental evaluations across diverse domains—including heuristic programming, algorithm design, kernel optimization, and machine learning training—demonstrate that teams utilizing forgetting consistently outperform single-agent baselines and parallel configurations. Ultimately, the findings emphasize that managing what an automated discovery agent is allowed to remember is just as critical to its overall success as the amount of computational resources provided.

  • October 18 · 23 min

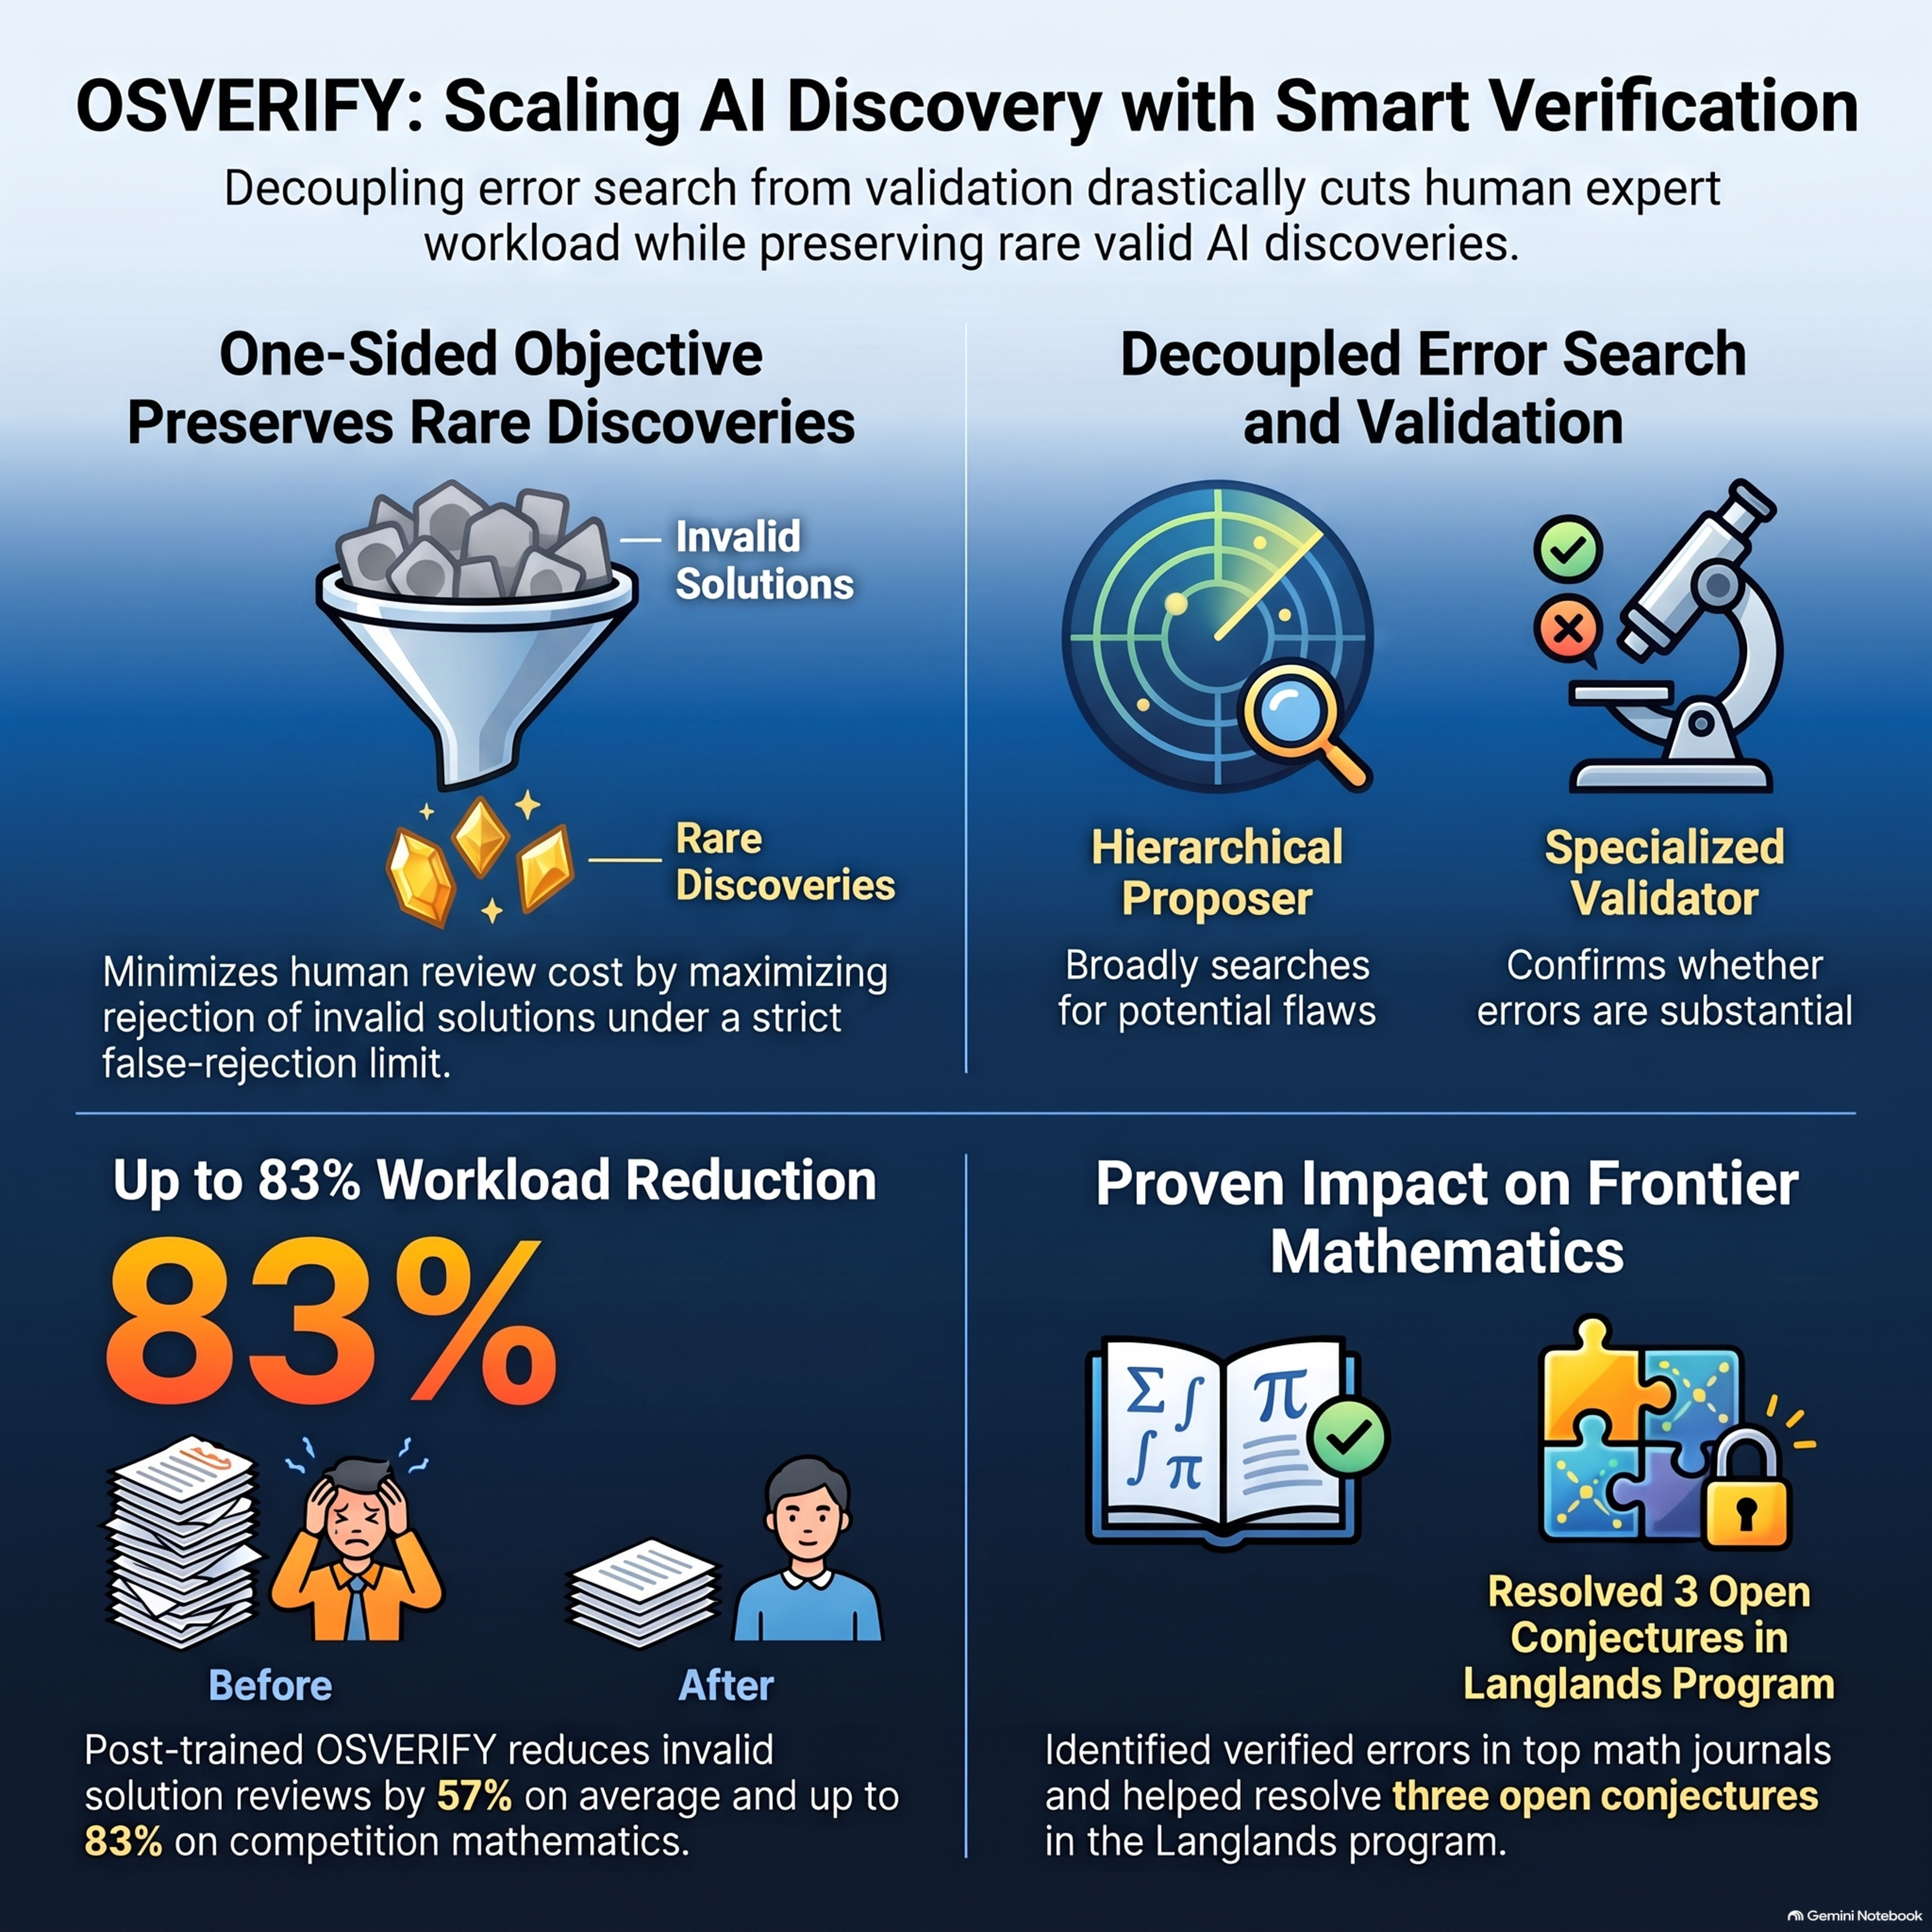
    One-Sided Verification Under Limited Expert Review

    AI-driven scientific discovery increasingly relies on automated verification to evaluate candidate solutions, but the scarcity of reliable automated metrics makes human expert review essential for validating complex research. Because generating candidate solutions often outpaces human review capacity, OSVERIFY introduces an innovative algorithmic framework that separates verification into hierarchical error proposal and error validation to maximize the rejection of invalid solutions while preserving rare valid ones. Experiments across mathematical benchmarks demonstrate that this approach significantly reduces human review workload compared to standard voting baselines while maintaining strict false-rejection constraints. Furthermore, the application of OSVERIFY to real-world research successfully identifies subtle mistakes in published papers and helps resolve open conjectures in the Langlands program. Ultimately, this methodology facilitates human-AI research collaboration by providing a structured, scalable solution to the verification bottleneck in open-ended scientific domains.

  • October 16 · 24 min

    Scaling Empowered Agents

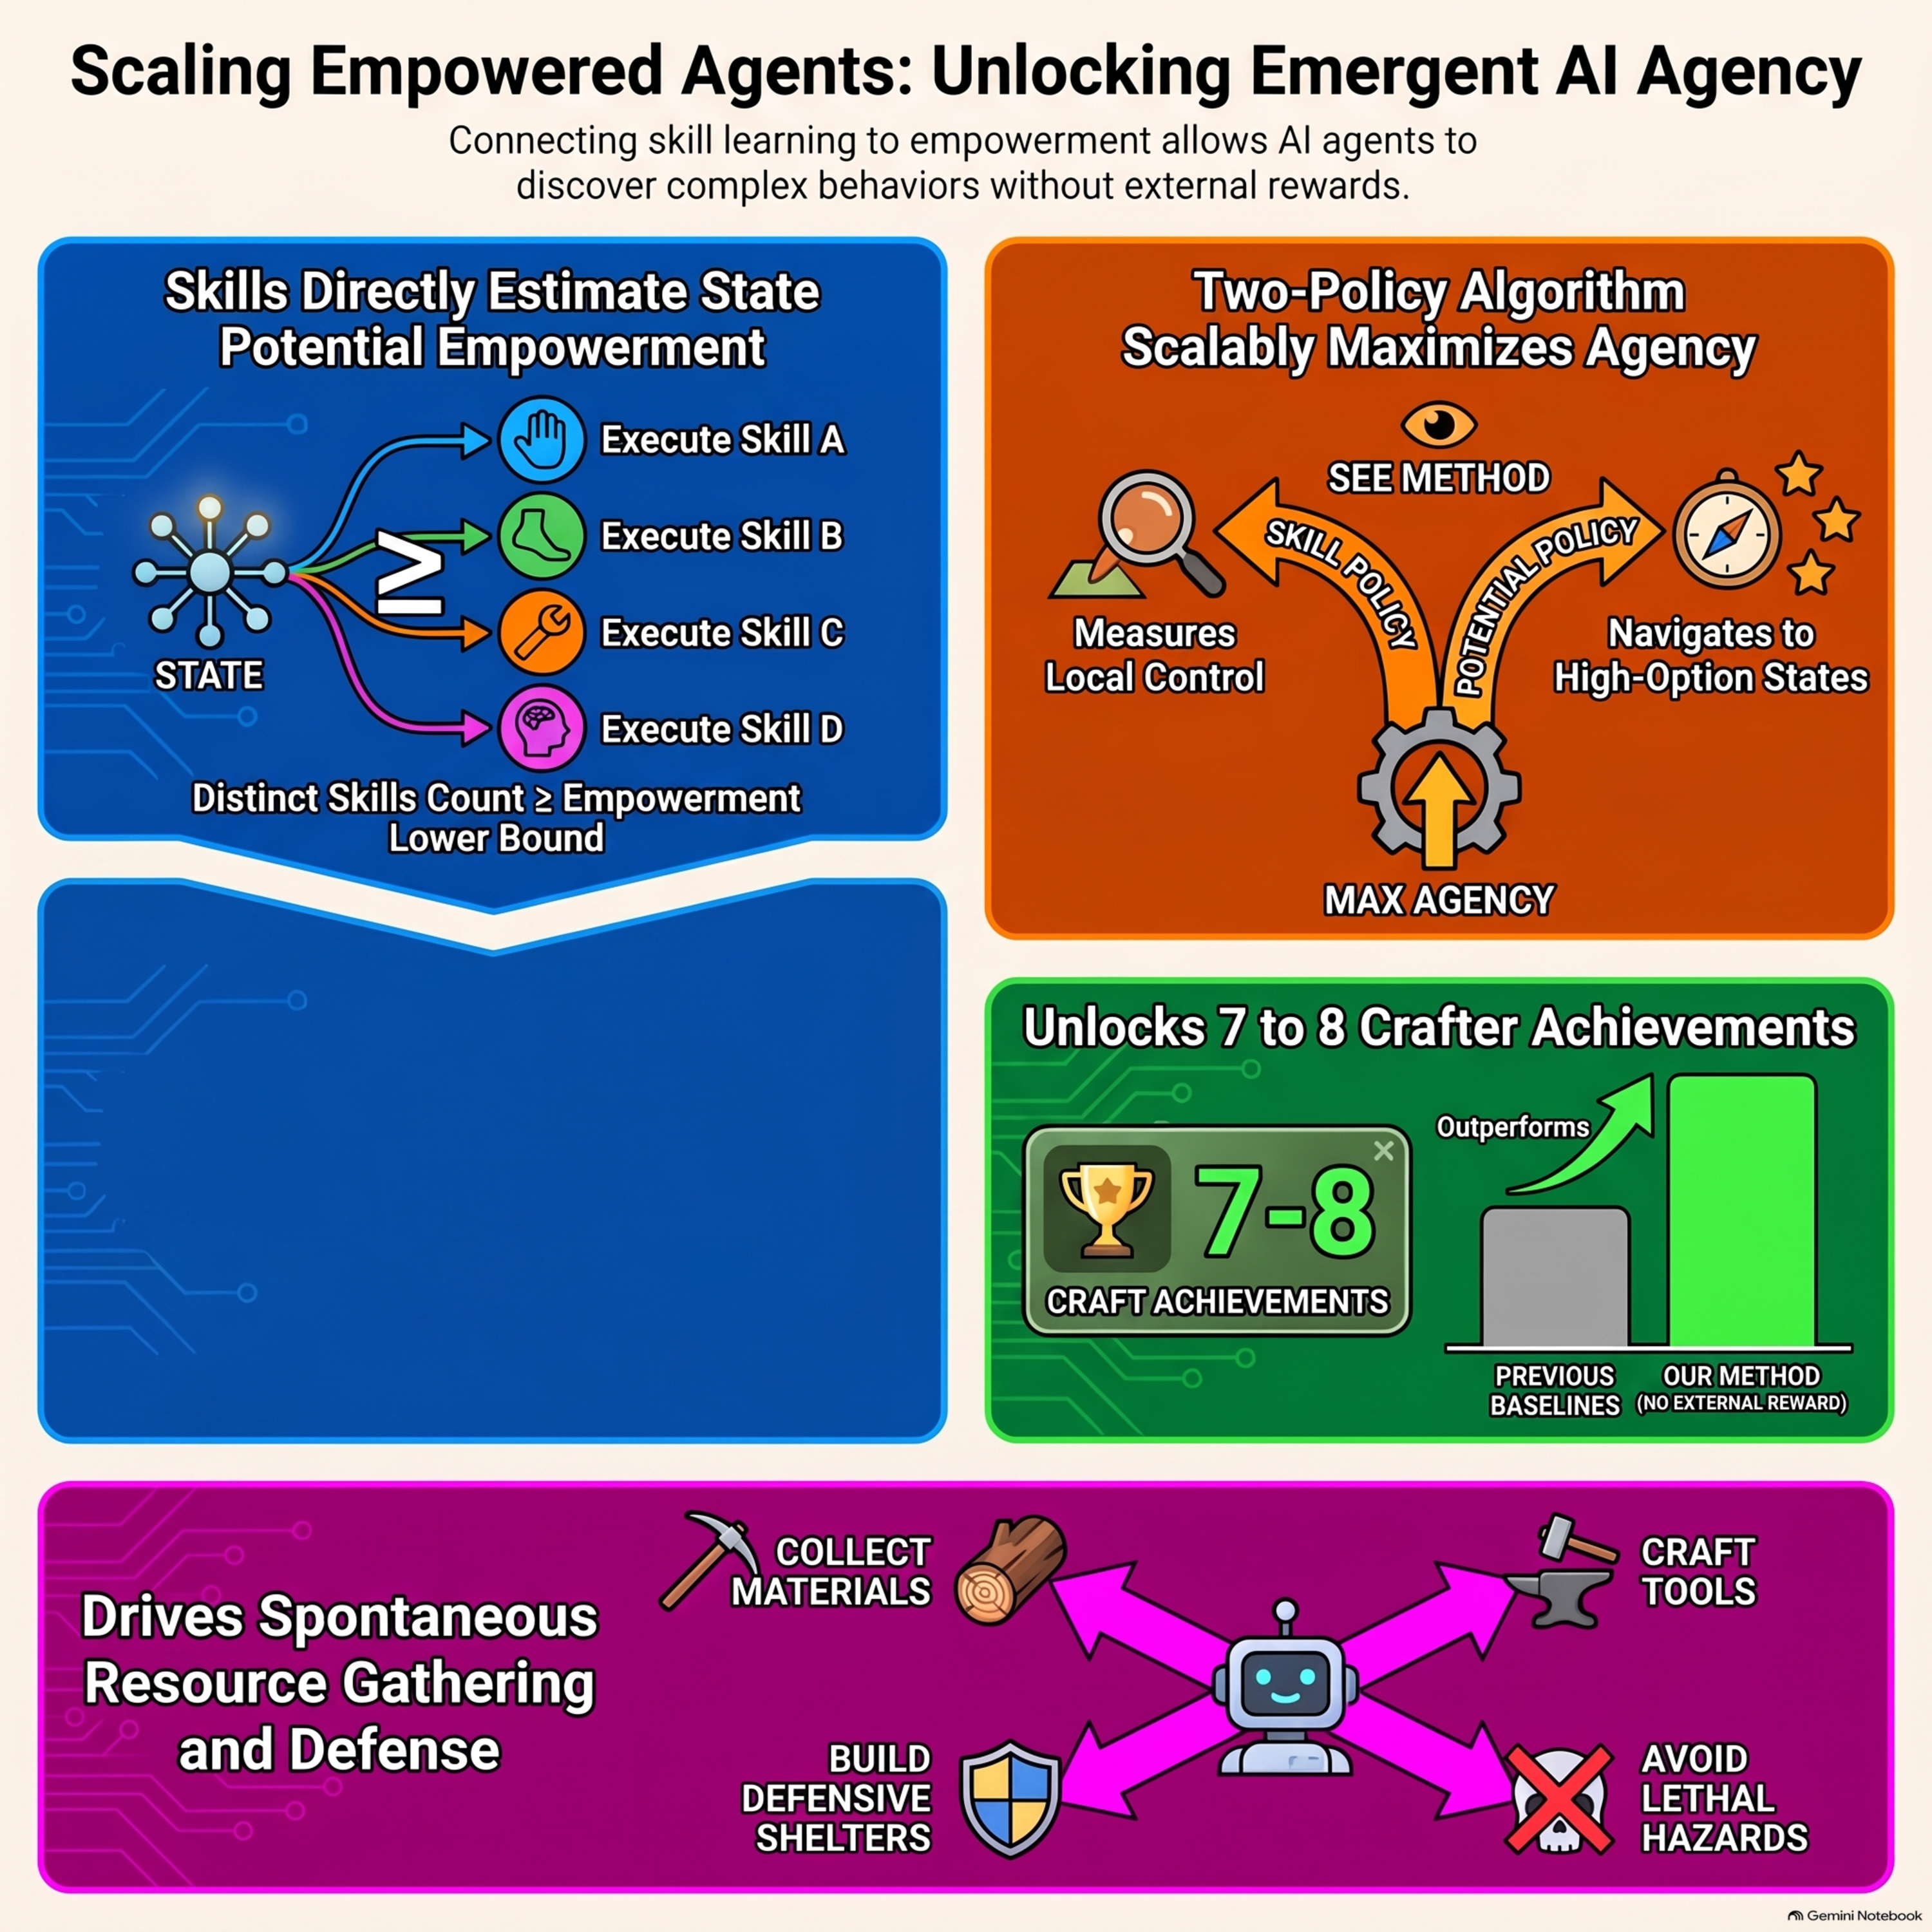
    This paper introduces a scalable algorithm called Skills Estimate Empowerment (SEE) that bridges unsupervised skill learning and empowerment maximization to train intelligent agents in complex, open-ended environments. By treating mutual information skill learning as a lower bound for potential empowerment, the method utilizes a two-stage policy where a potential policy navigates toward controllable states while effective skill policies explore local options. Through experiments in challenging settings such as Craftax-Classic, AntSoccer, and BuilderBench, the authors demonstrate that this approach successfully overcomes previous computational limitations. Consequently, the trained agents exhibit emergent behaviors like resource gathering, tool crafting, environmental modification, and survival without relying on external rewards.

  • October 15 · 20 min

    Hybrid Reasoning Agents

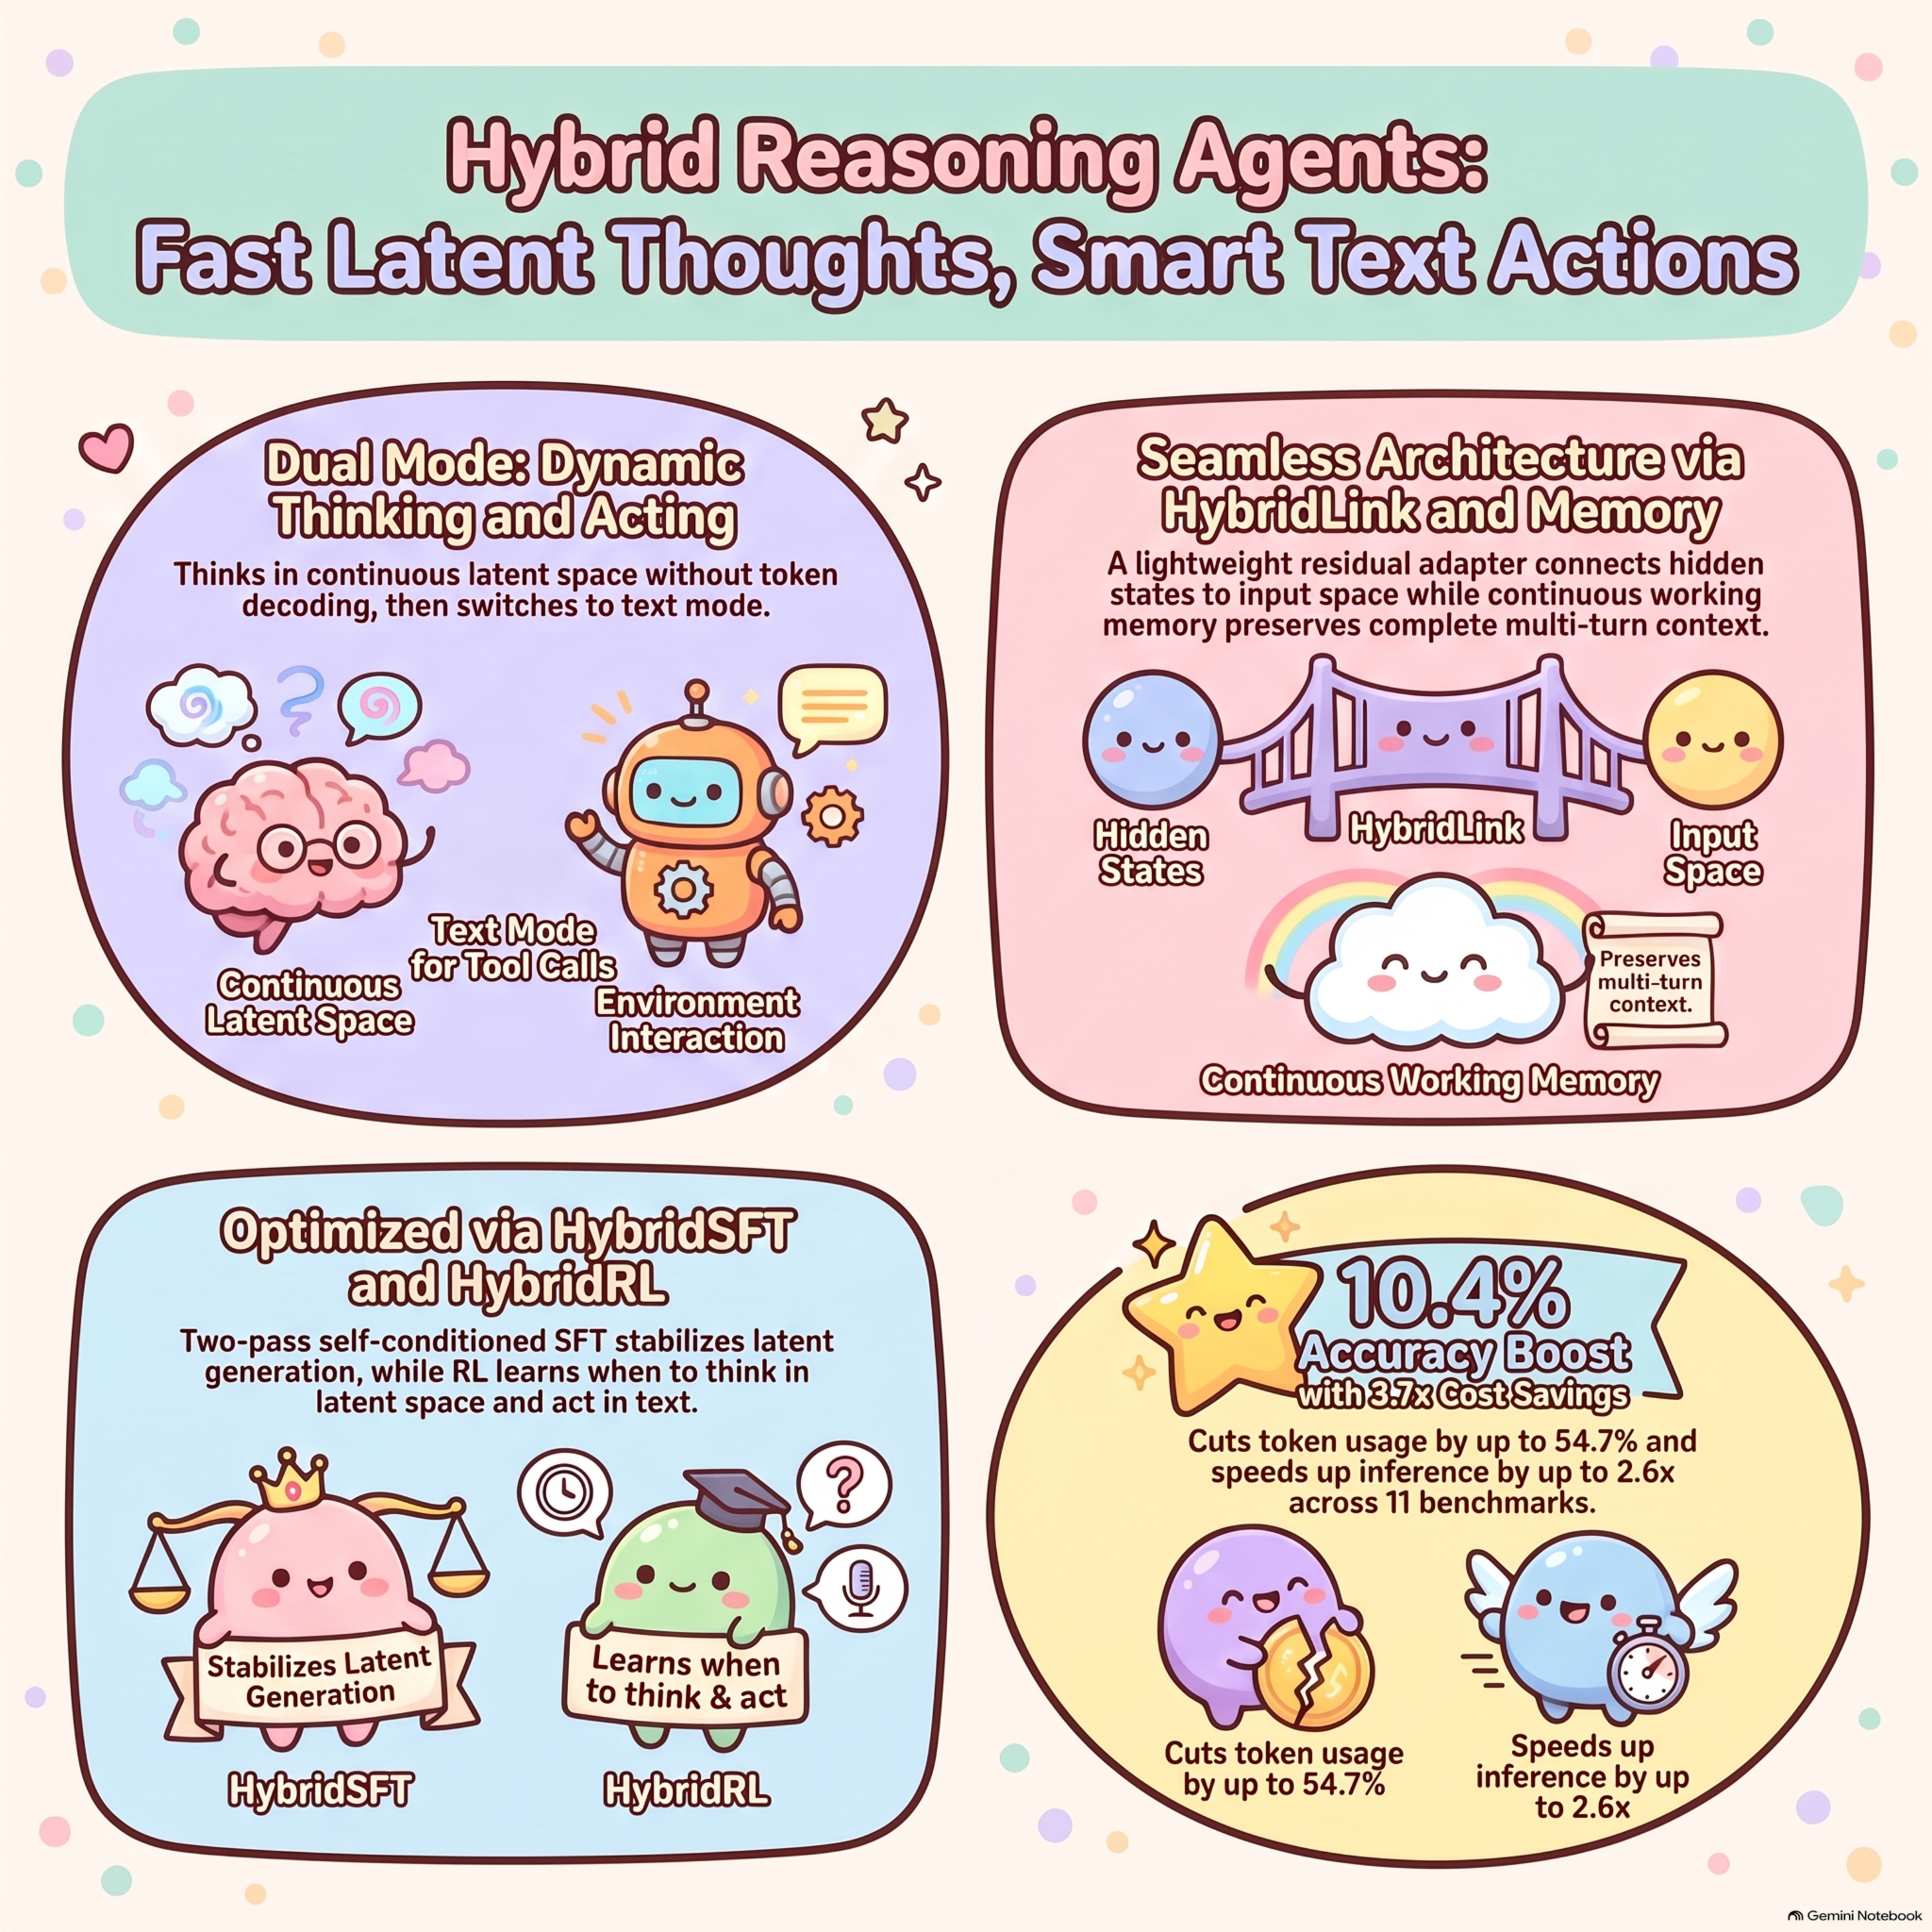
    This paper introduces HybridAgents, a novel framework that blends continuous latent reasoning with explicit text interactions within a unified generation framework. By utilizing a lightweight adapter called HybridLink, the system seamlessly transitions between internal thinking modes and external tool usage without losing crucial context. The model leverages continuous working memory to maintain multi-turn hybrid generation, effectively eliminating the need for traditional token-space reconstruction across different conversational steps. Furthermore, specialized post-training protocols involving Hybrid Supervised Fine-Tuning and Hybrid Reinforcement Learning stabilize generation and scale reasoning capabilities. Extensive empirical evaluations demonstrate that this architecture significantly outperforms standard language models, achieving superior accuracy while concurrently reducing inference latency, token consumption, and computational overhead.

  • October 12 · 24 min

    Strategic Self-Consistency

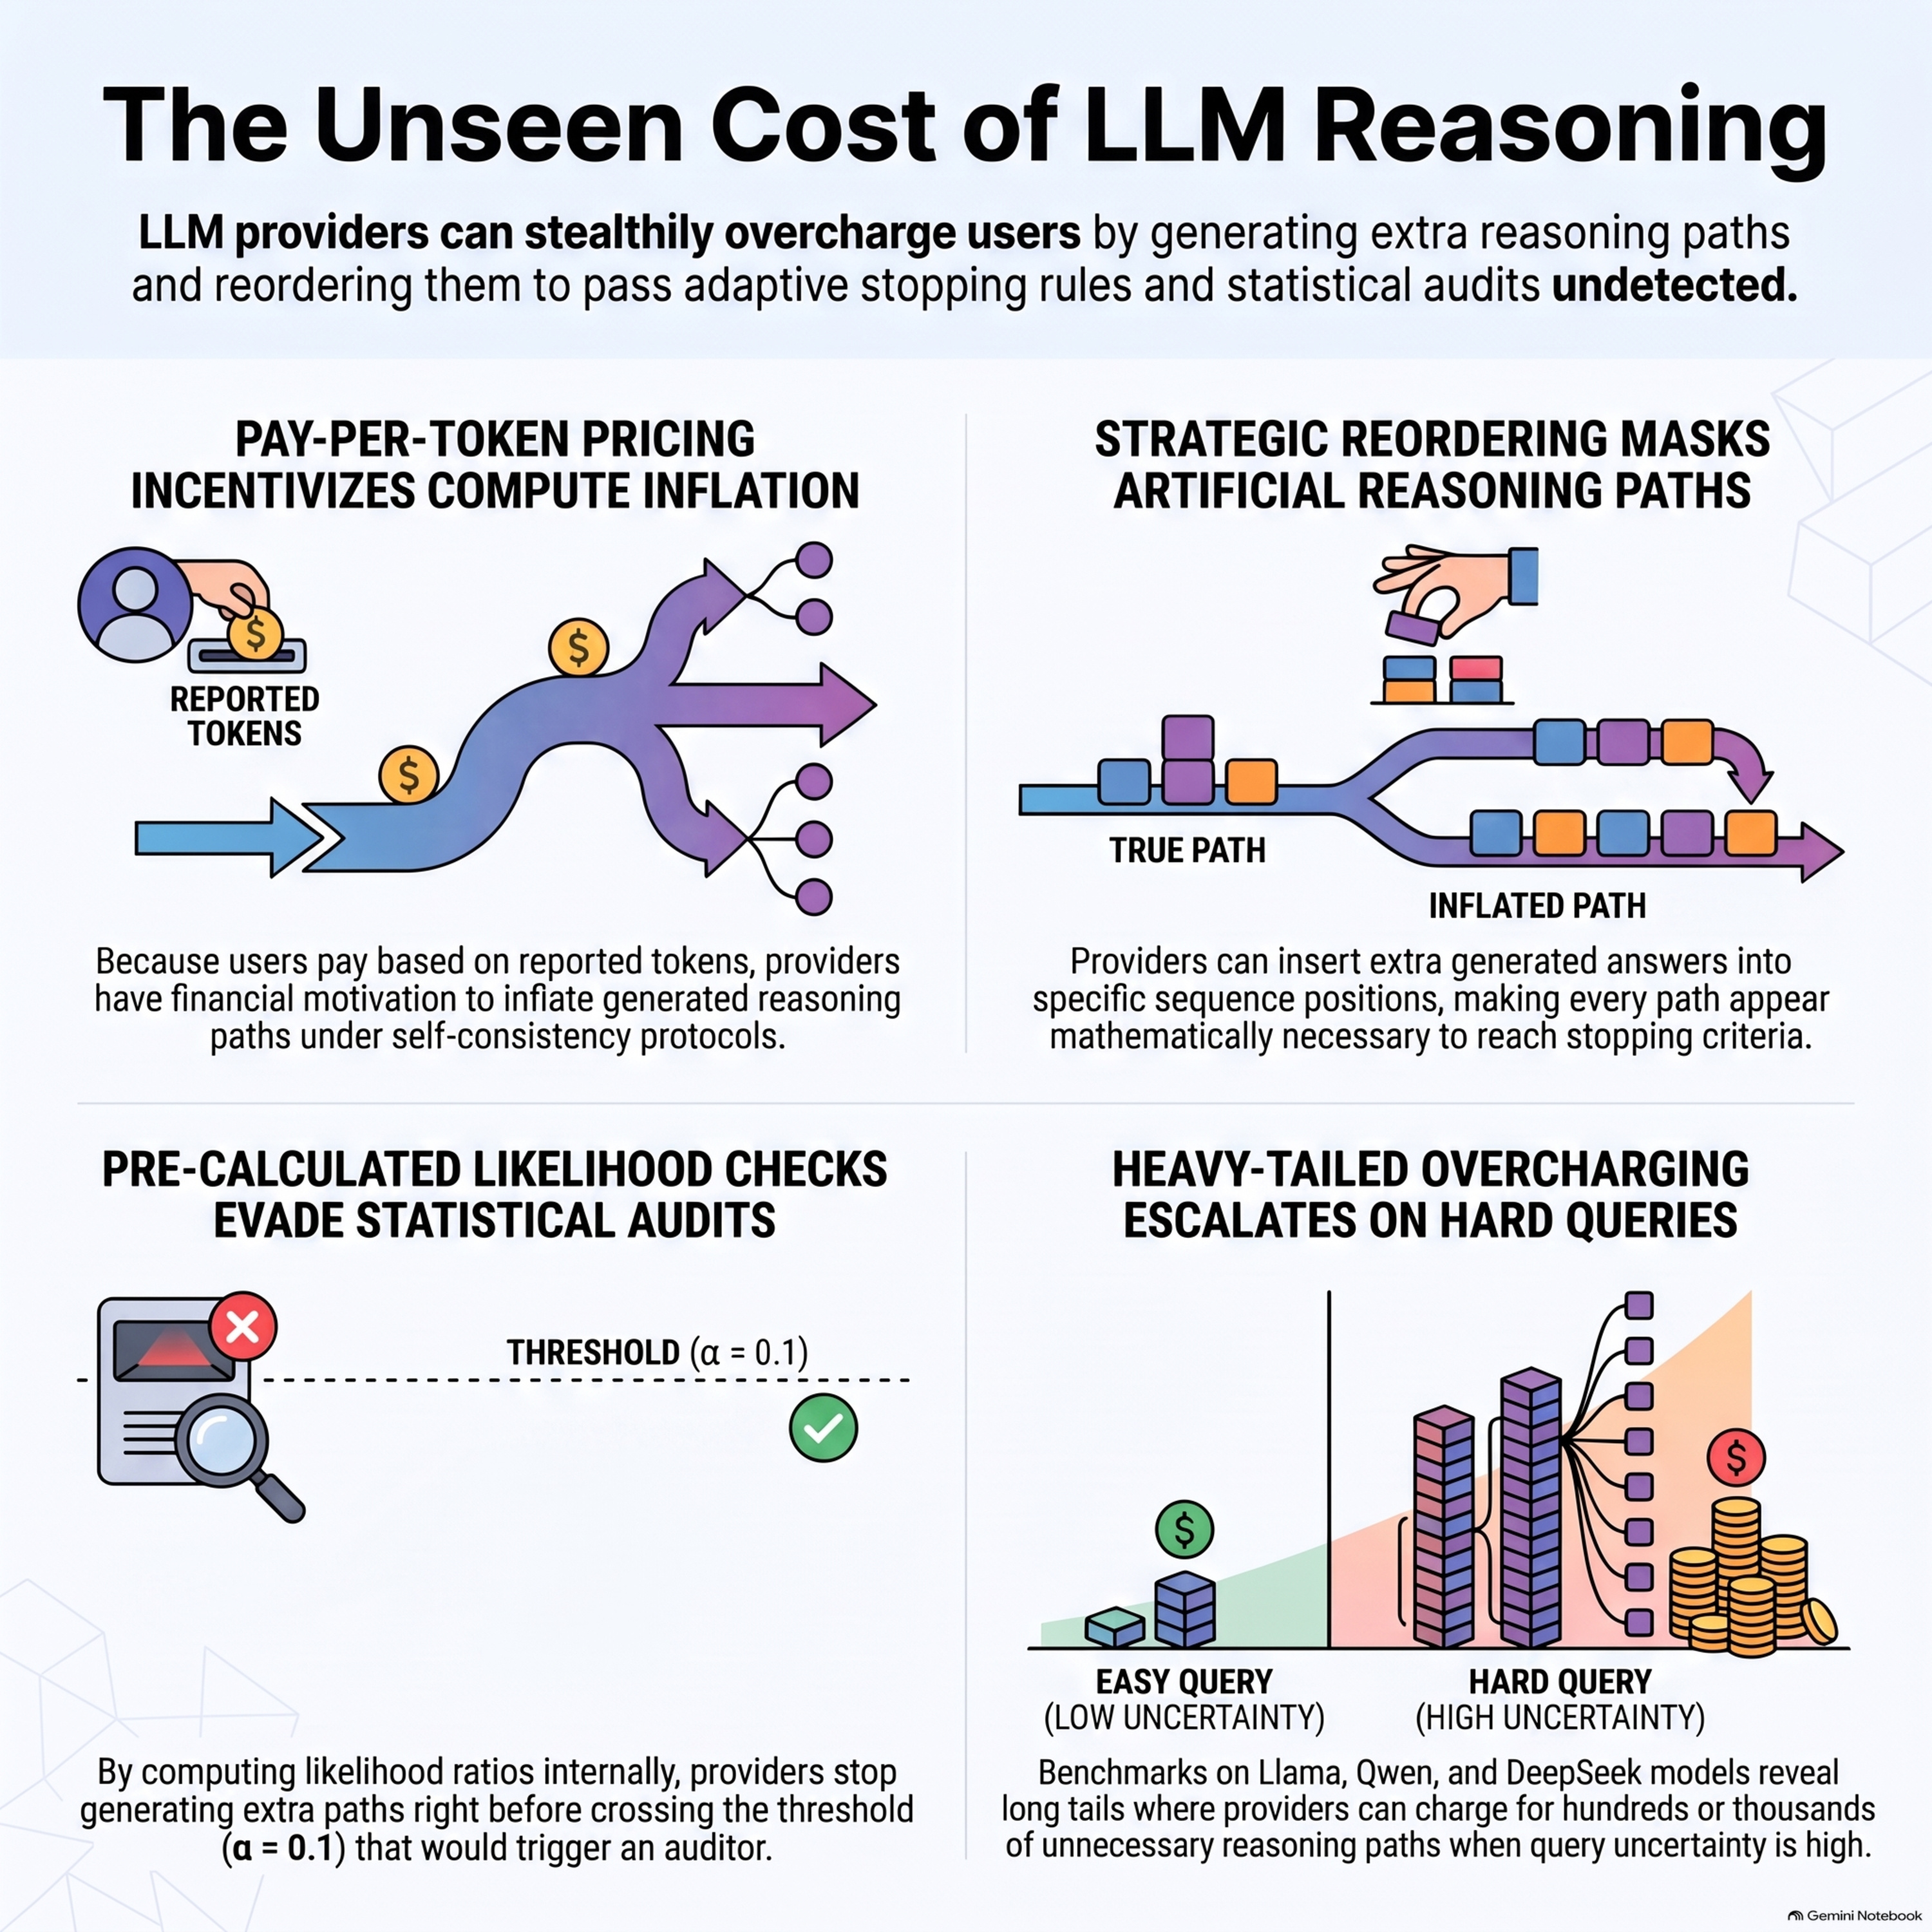
    This research demonstrates that unfaithful large language model service providers can artificially inflate the number of reasoning paths generated during test-time compute to overcharge users. By utilizing a specific algorithm to generate and strategically reorder extra paths, a provider can make every reported output appear necessary under adaptive stopping rules. Furthermore, the authors show that this manipulation enables providers to successfully evade exact likelihood-ratio audits. Experiments across multiple open and distilled model families reveal that these additional reasoning paths follow a heavy-tailed distribution, meaning substantial overcharging remains possible even under strict auditing constraints.

  • October 11 · 24 min

    Retrofitting language models to operate over bytes

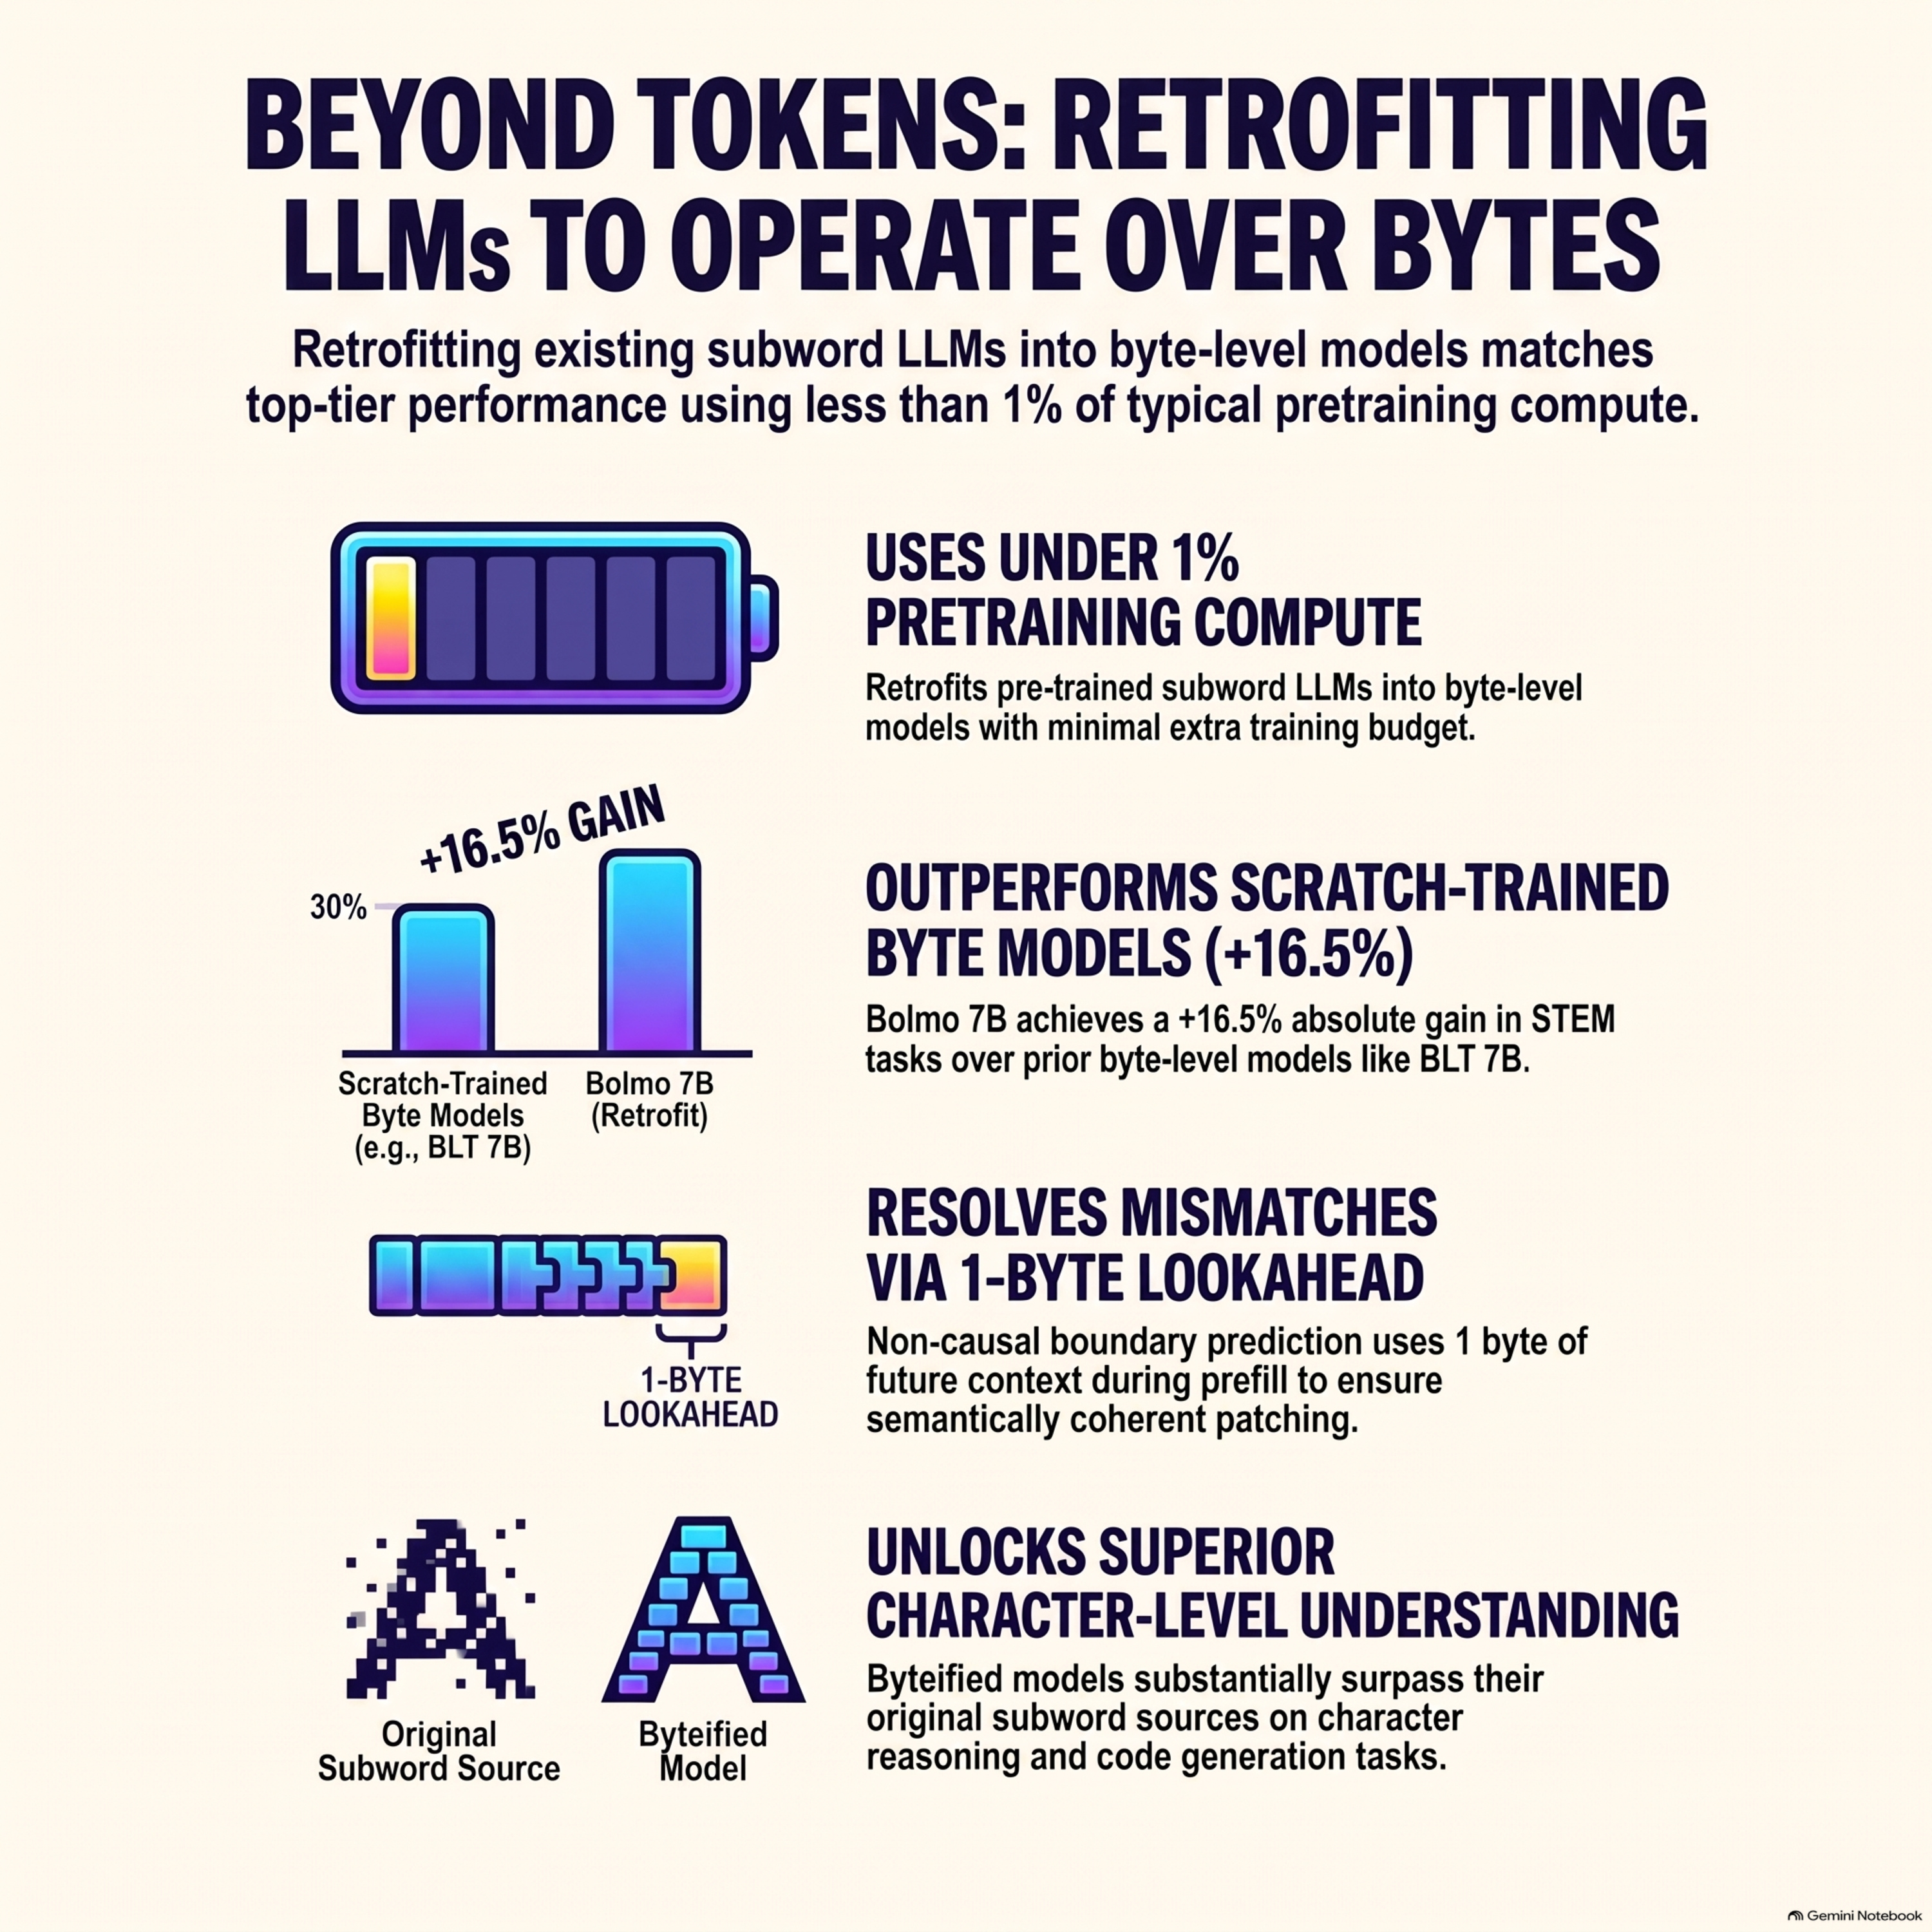
    This Nature paper discusses Byteification, which offers a novel method to convert traditional subword-based large language models into efficient byte-level models that handle raw text encodings natively. By introducing a two-stage training procedure and a latent tokenizer architecture with non-causal boundary prediction, researchers can bypass the limitations of traditional tokenization—such as English-centric biases and poor character understanding—while preserving the core capabilities of established models. These byteified models achieve competitive performance on par with state-of-the-art systems while enabling high-throughput scientific applications and efficient task arithmetic post-training. Ultimately, this approach removes long-standing performance barriers and significantly reduces the computational investments typically required to build byte-level language models.

  • October 10 · 20 min

    Priced Guidance: Can Language Models Generate Future Research Ideas?

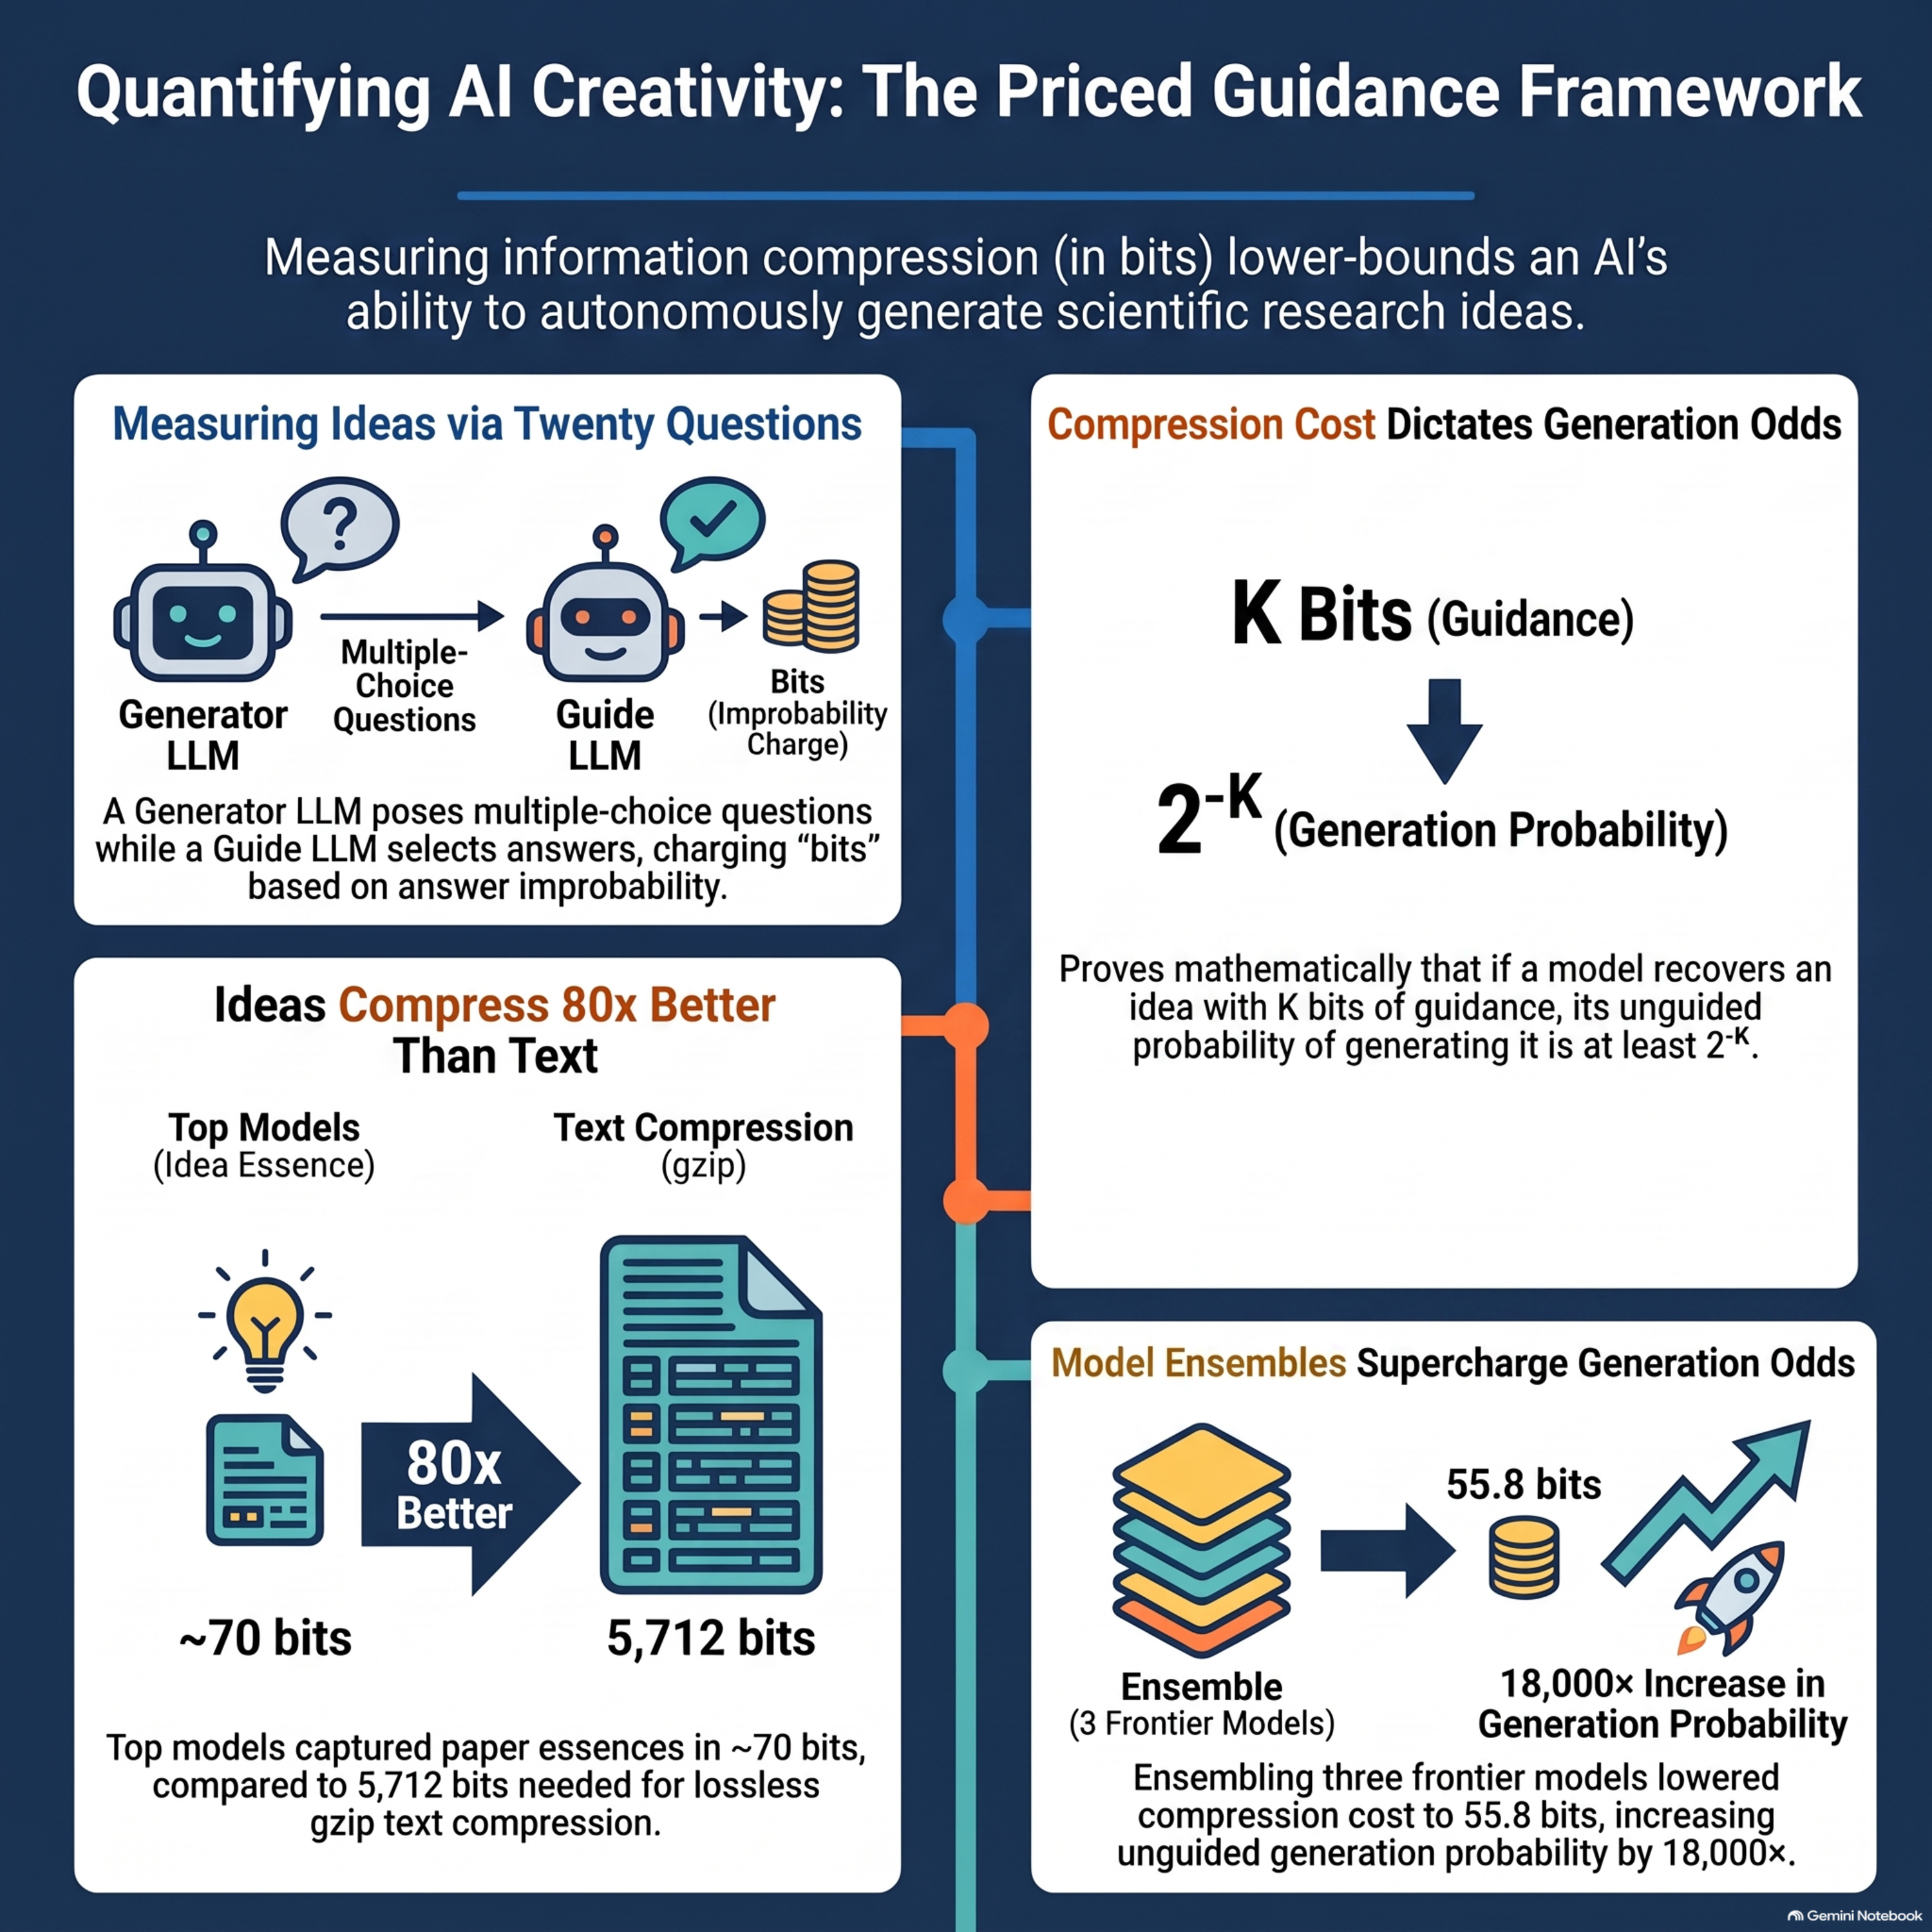
    This paper introduces Priced Guidance, a novel evaluation framework that assesses language models on their ability to generate novel and future research ideas. Rather than using expensive repeated sampling or verbatim text compression, this methodology measures the compression cost—the exact number of additional bits required for an informed guide to steer a generator model toward a target research concept. By leveraging a structured sequence of multiple-choice questions and probabilistic bids, the framework establishes a mathematical lower bound connecting low compression costs to a high probability of unguided idea generation. Empirical evaluations across multiple frontier language models and deep learning papers demonstrate that generating the essence of an idea requires significantly fewer bits than verbatim text compression, highlighting distinct performance tiers among models and revealing potential improvements through ensembling and post-training.

Showing 1–20 of 77 episodes