transcript
show notes
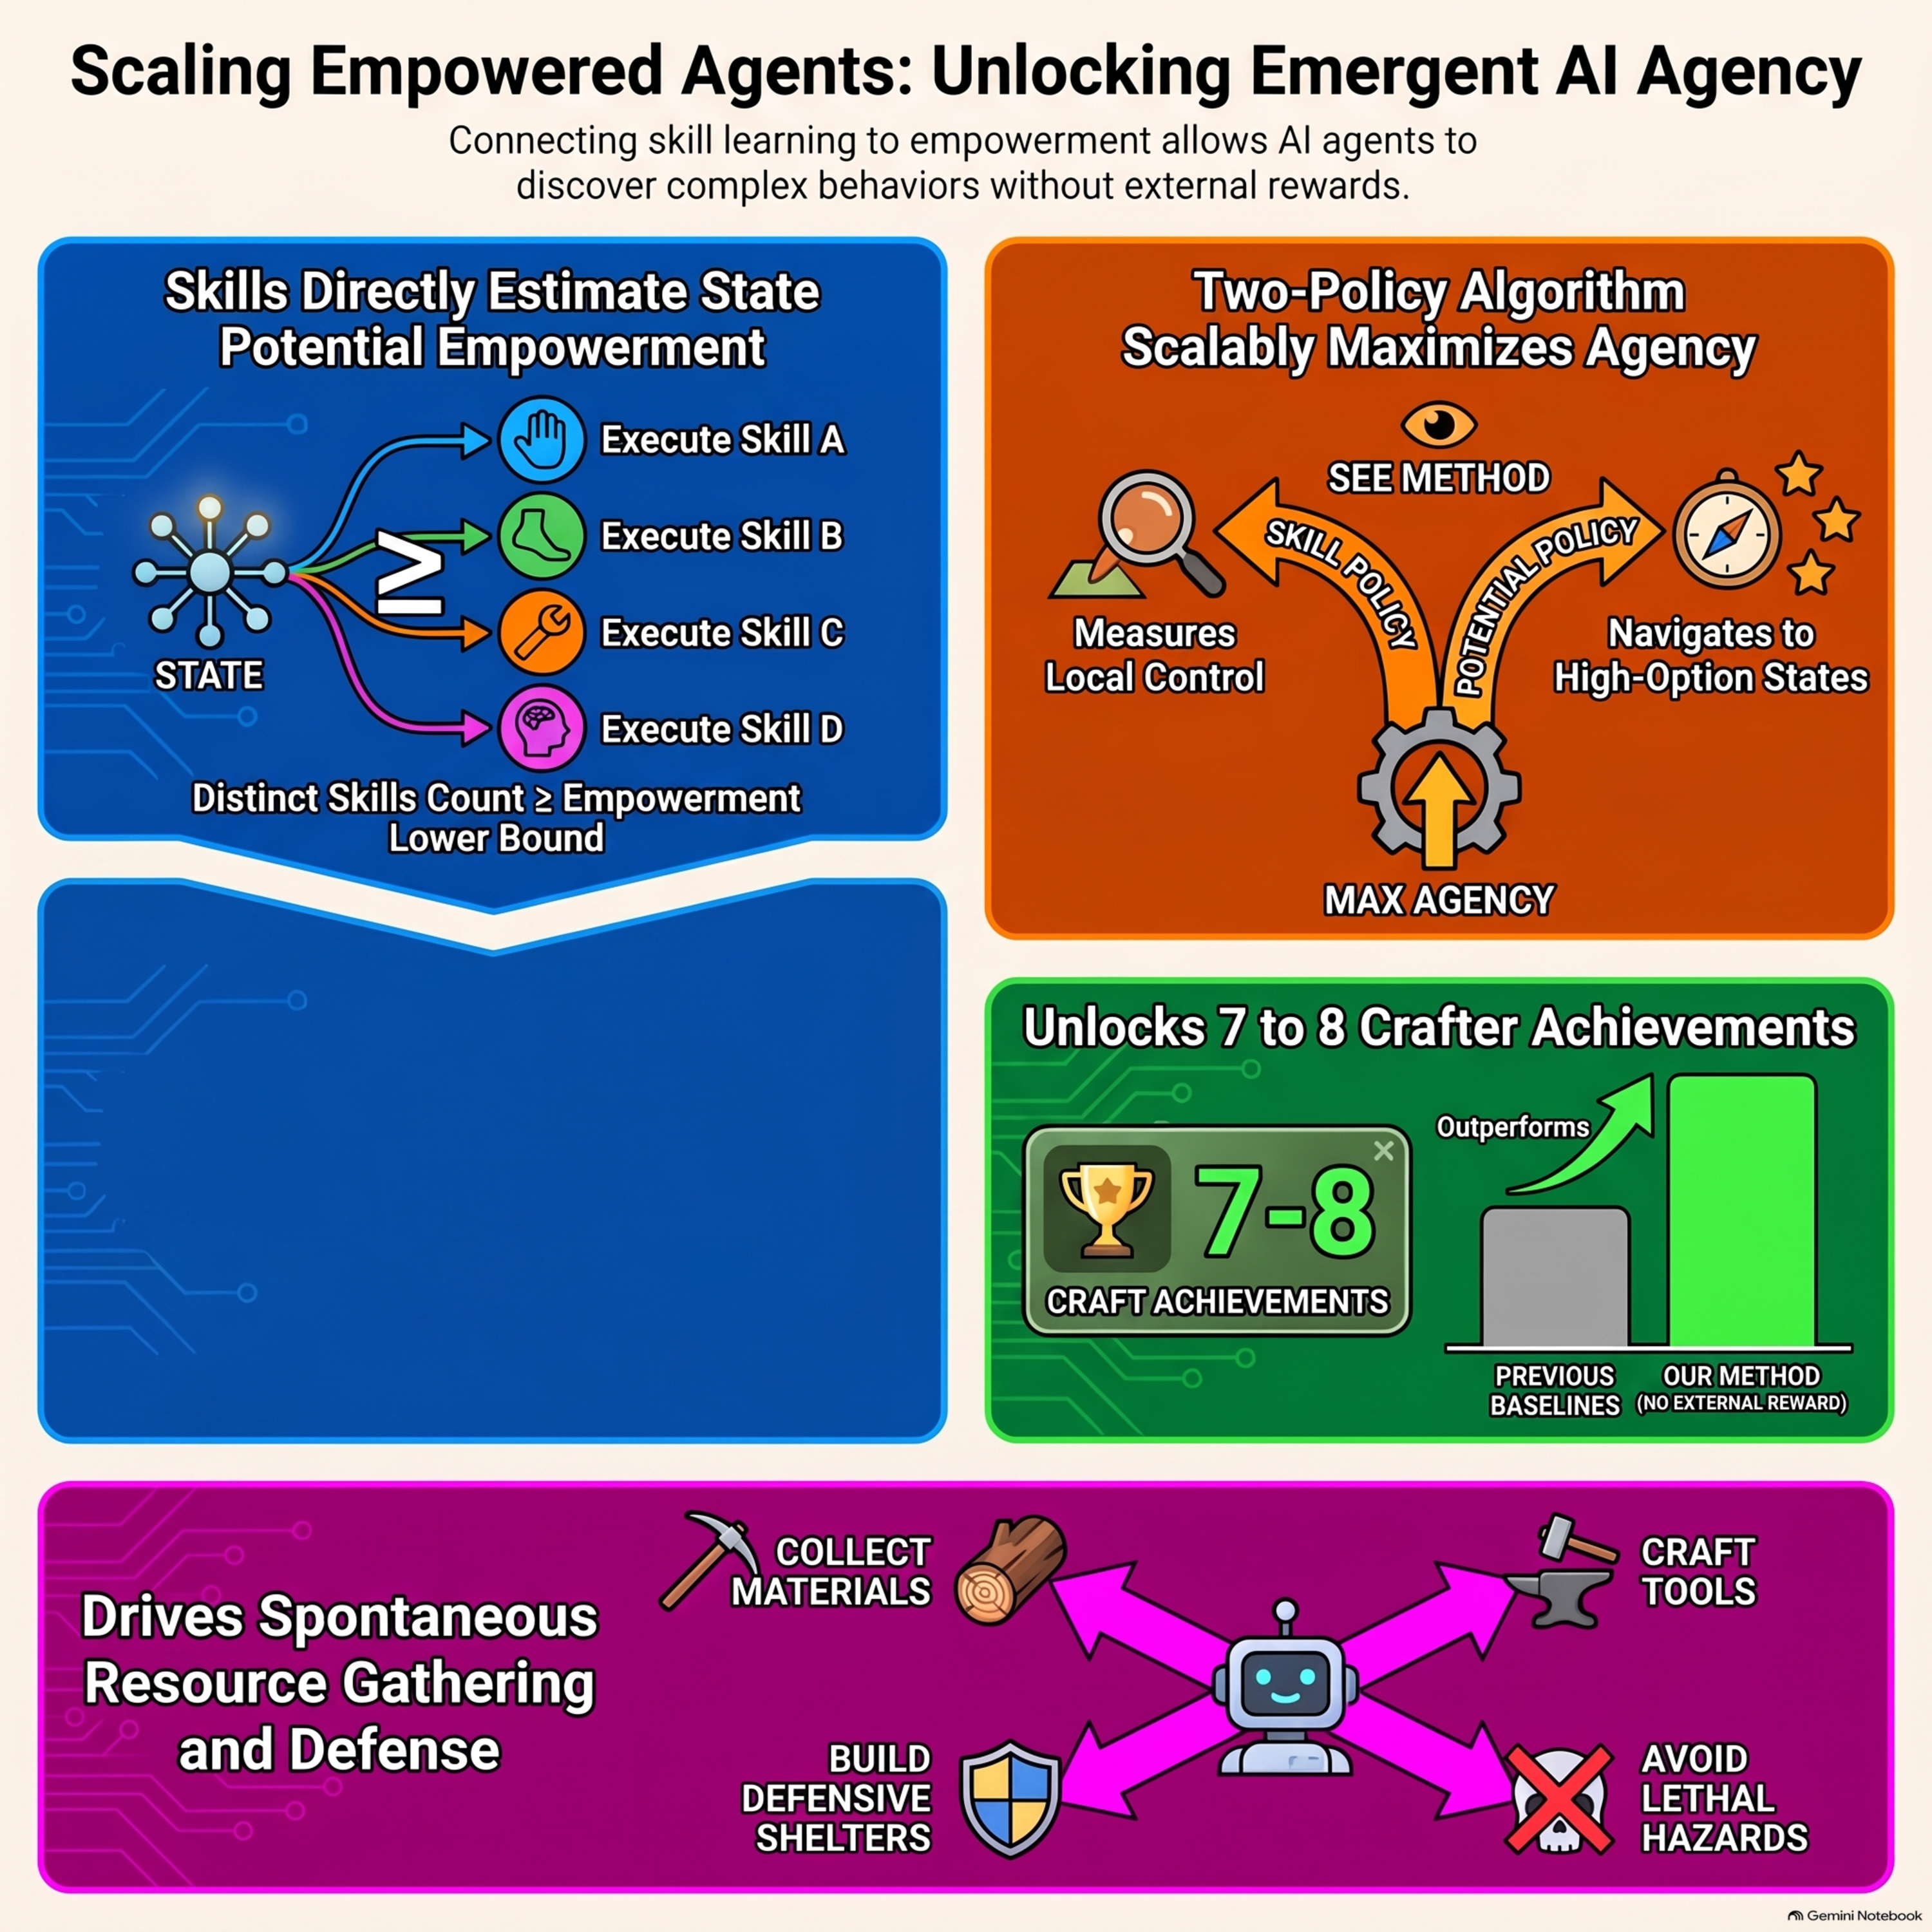
This paper introduces a scalable algorithm called Skills Estimate Empowerment (SEE) that bridges unsupervised skill learning and empowerment maximization to train intelligent agents in complex, open-ended environments. By treating mutual information skill learning as a lower bound for potential empowerment, the method utilizes a two-stage policy where a potential policy navigates toward controllable states while effective skill policies explore local options. Through experiments in challenging settings such as Craftax-Classic, AntSoccer, and BuilderBench, the authors demonstrate that this approach successfully overcomes previous computational limitations. Consequently, the trained agents exhibit emergent behaviors like resource gathering, tool crafting, environmental modification, and survival without relying on external rewards.