Skip to content
Artwork for Best AI papers explained
Best AI papers explained · Yesterday · 21 min

Scaling Discovery Requires Forgetting

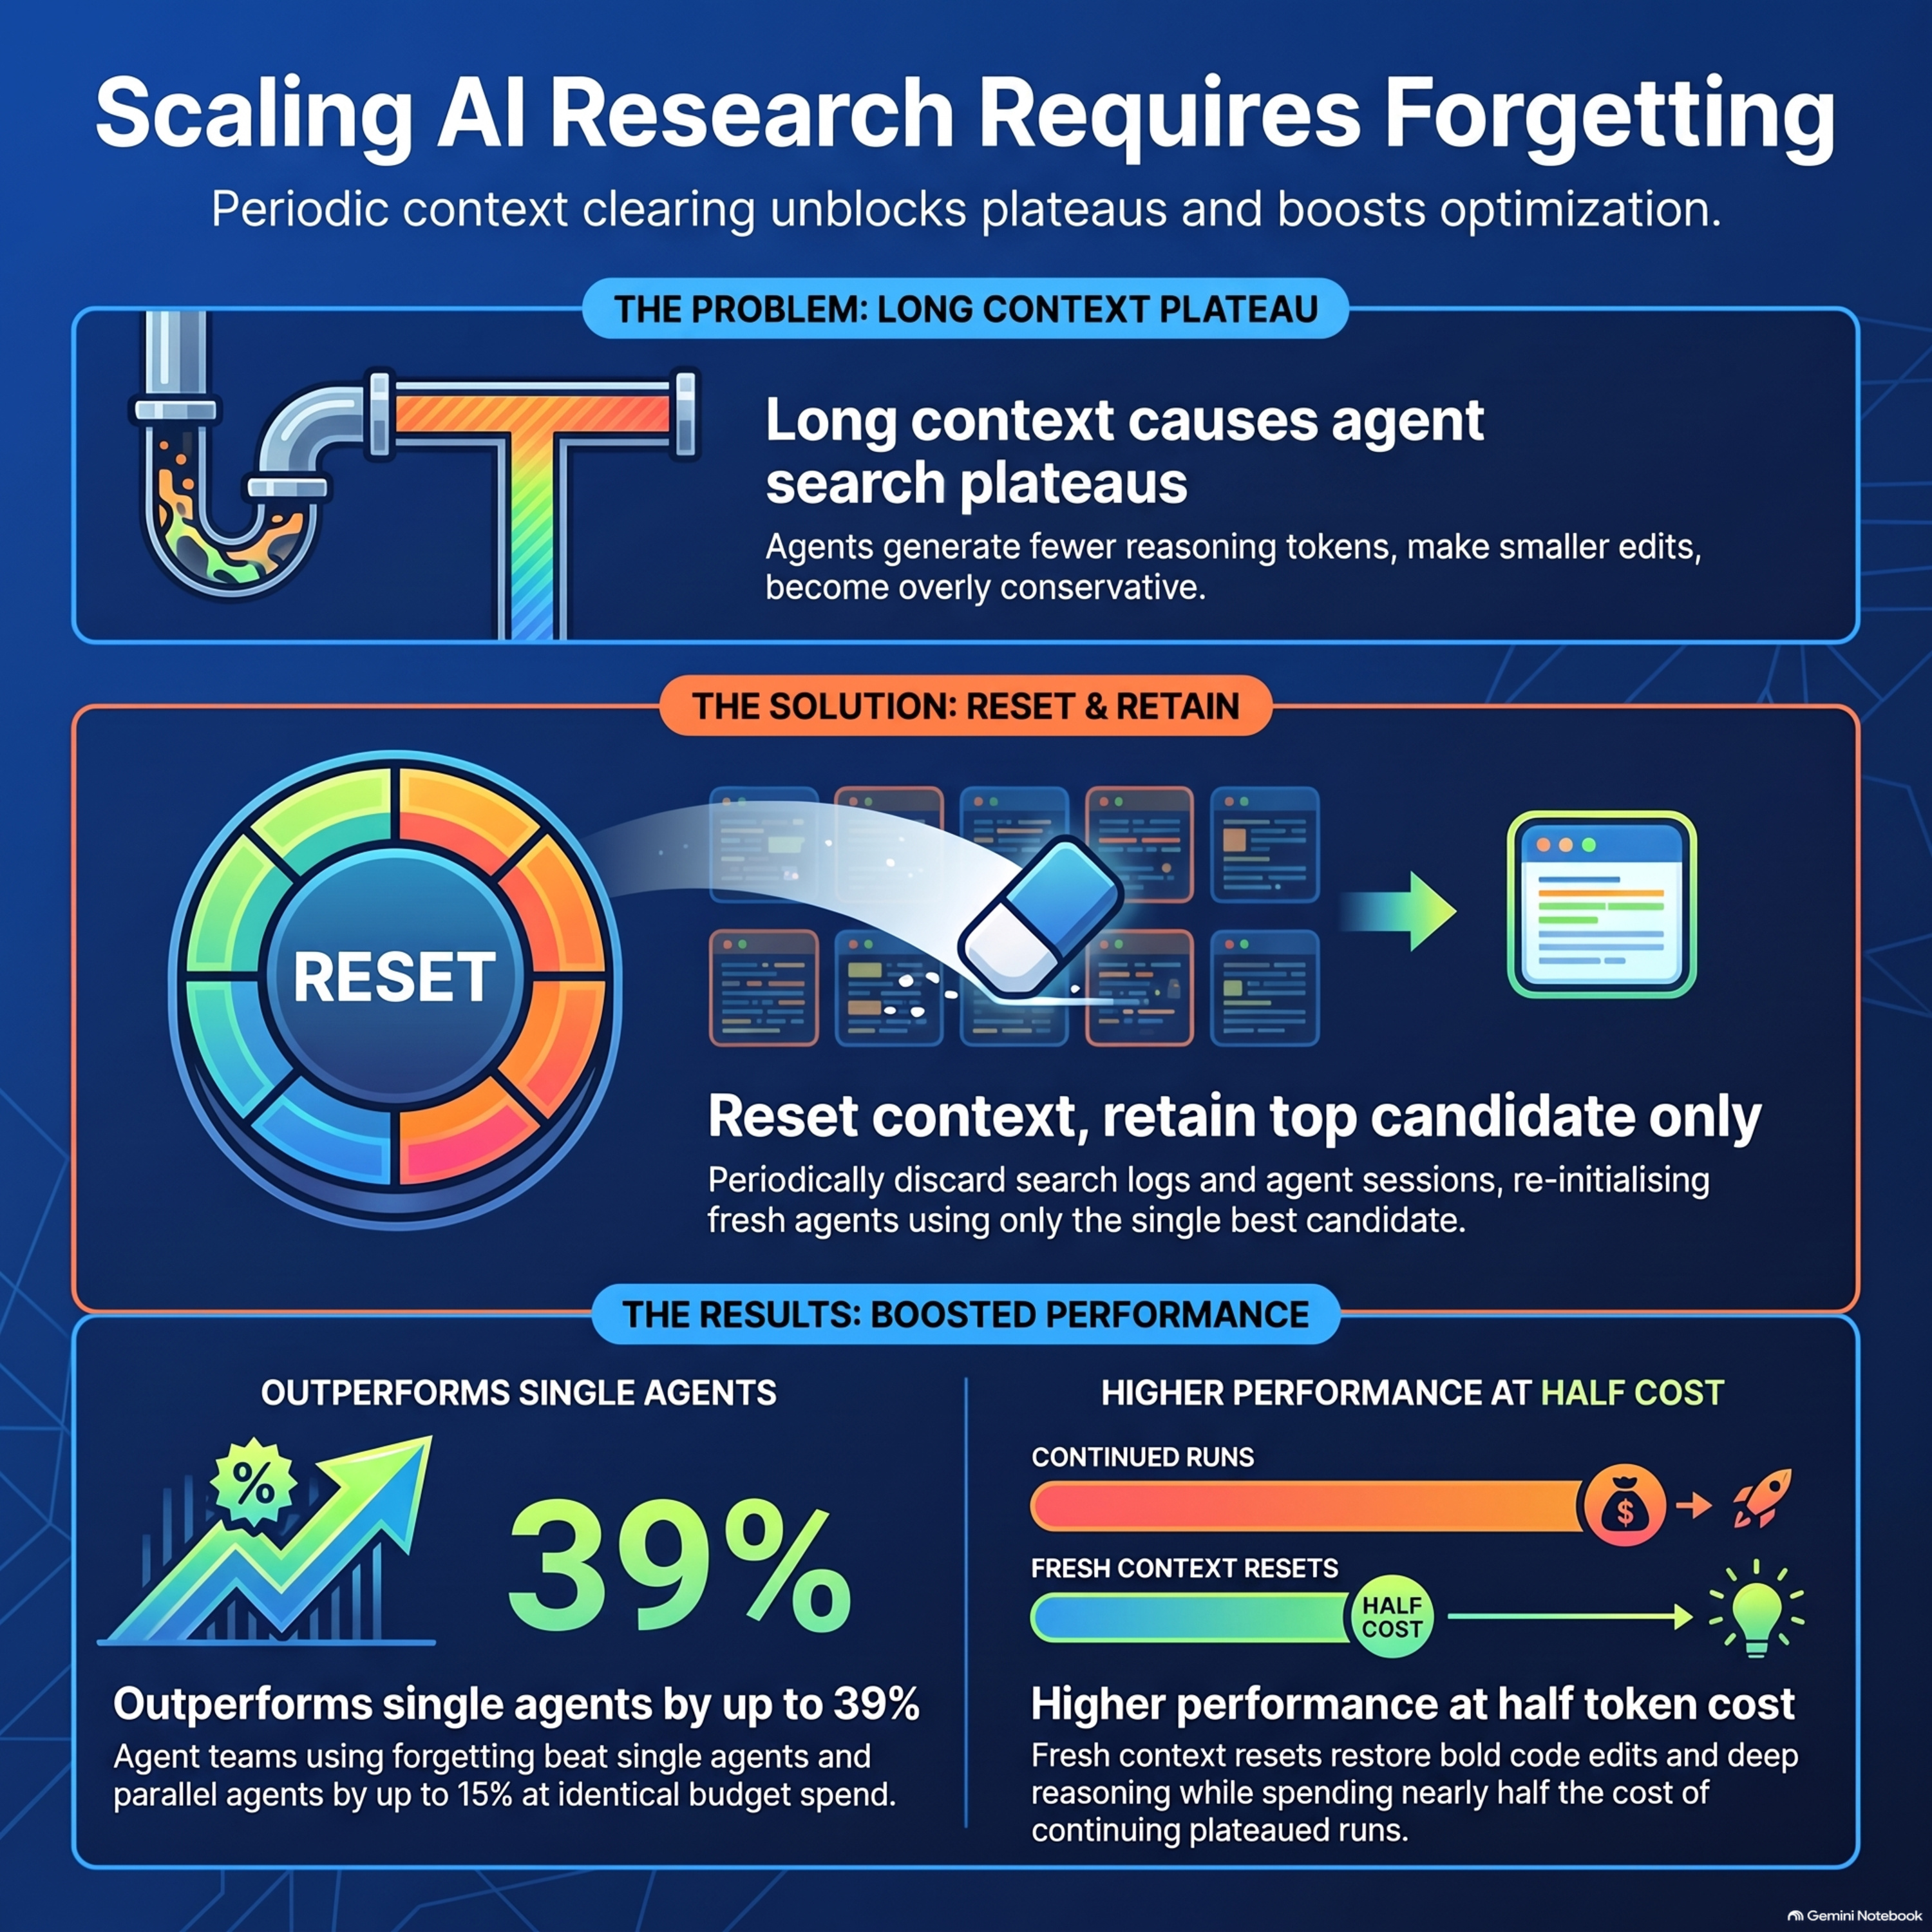
Automated research agents powered by large language models often experience performance plateaus during open-ended discovery tasks as their accumulated history makes their edits overly conservative. To overcome this limitation, researchers introduce a novel strategy called forgetting, which periodically discards previous agent sessions and candidate search histories while retaining only the single best solution found so far. When combined with a collaborative multi-agent team setup that allows asynchronous communication, this reset mechanism clears out unproductive contextual baggage and unblocks fresh exploration. Experimental evaluations across diverse domains—including heuristic programming, algorithm design, kernel optimization, and machine learning training—demonstrate that teams utilizing forgetting consistently outperform single-agent baselines and parallel configurations. Ultimately, the findings emphasize that managing what an automated discovery agent is allowed to remember is just as critical to its overall success as the amount of computational resources provided.

0:00-21:25

transcript

No transcript — this publisher did not publish one.

show notes

Automated research agents powered by large language models often experience performance plateaus during open-ended discovery tasks as their accumulated history makes their edits overly conservative. To overcome this limitation, researchers introduce a novel strategy called forgetting, which periodically discards previous agent sessions and candidate search histories while retaining only the single best solution found so far. When combined with a collaborative multi-agent team setup that allows asynchronous communication, this reset mechanism clears out unproductive contextual baggage and unblocks fresh exploration. Experimental evaluations across diverse domains—including heuristic programming, algorithm design, kernel optimization, and machine learning training—demonstrate that teams utilizing forgetting consistently outperform single-agent baselines and parallel configurations. Ultimately, the findings emphasize that managing what an automated discovery agent is allowed to remember is just as critical to its overall success as the amount of computational resources provided.