Skip to content
Artwork for Machine Learning Tech Brief By HackerNoon
Machine Learning Tech Brief By HackerNoon · Sunday · 7 min

Turning Non-Standard Business Documents Into Structured, Verifiable Data

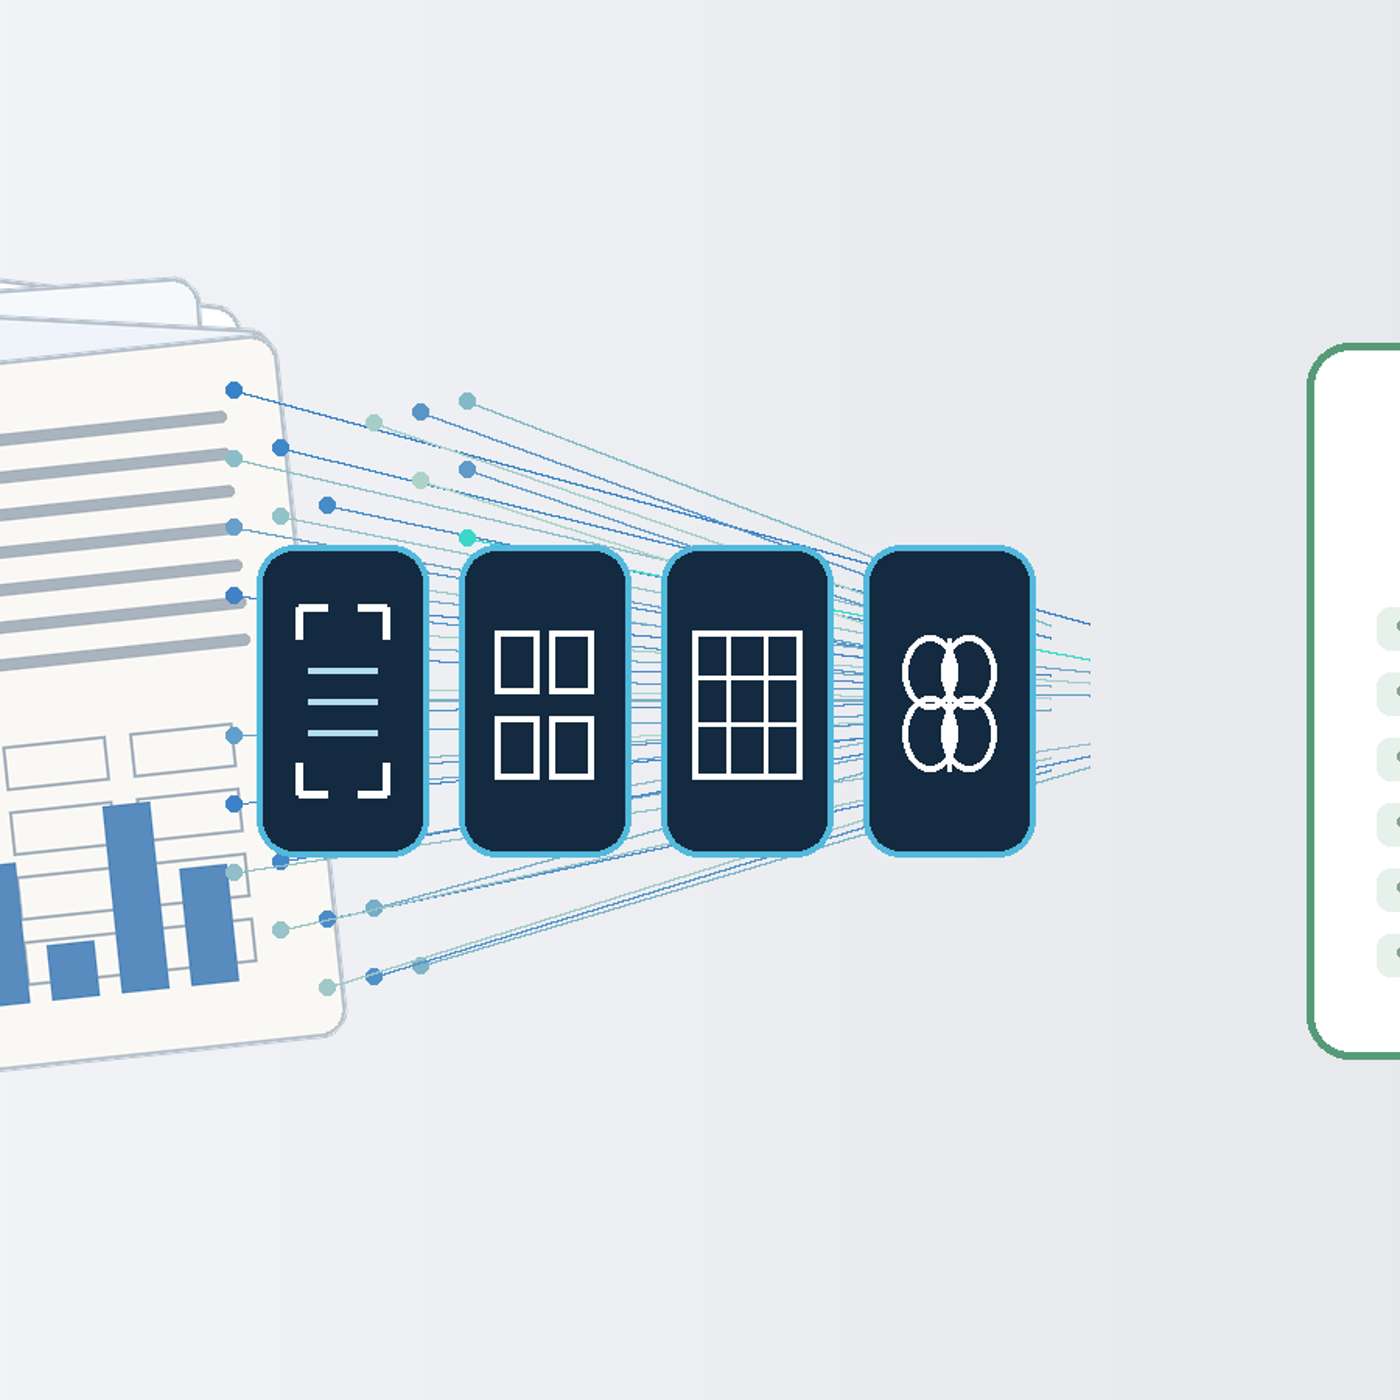
This story was originally published on HackerNoon at: https://hackernoon.com/turning-non-standard-business-documents-into-structured-verifiable-data. OCR reads the words but doesn't guarantee correct data. How layout models, table detection, and verification turn messy business documents into trusted output. Check more stories related to machine-learning at: https://hackernoon.com/c/machine-learning. You can also check exclusive content about #ai, #unstructured-data-processing, #unstructured-data, #llms, #ocr, #optical-character-recognition, #multimodal, #multimodal-pipeline, and more. This story was written by: @navsuresh. Learn more about this writer by checking @navsuresh's about page, and for more stories, please visit hackernoon.com. Business documents don't follow templates, so template-based parsers fail on them. OCR reads the words but can still lose the layout that gives a number its meaning. Break the pipeline into stages so each failure type is testable, and attach a source and confidence score to every extracted value. Then send only the uncertain ones to a human.
0:00-7:30

transcript

No transcript — this publisher did not publish one.

show notes

This story was originally published on HackerNoon at: https://hackernoon.com/turning-non-standard-business-documents-into-structured-verifiable-data.
OCR reads the words but doesn't guarantee correct data. How layout models, table detection, and verification turn messy business documents into trusted output.
Check more stories related to machine-learning at: https://hackernoon.com/c/machine-learning. You can also check exclusive content about #ai, #unstructured-data-processing, #unstructured-data, #llms, #ocr, #optical-character-recognition, #multimodal, #multimodal-pipeline, and more.

This story was written by: @navsuresh. Learn more about this writer by checking @navsuresh's about page, and for more stories, please visit hackernoon.com.

Business documents don't follow templates, so template-based parsers fail on them. OCR reads the words but can still lose the layout that gives a number its meaning. Break the pipeline into stages so each failure type is testable, and attach a source and confidence score to every extracted value. Then send only the uncertain ones to a human.
links13