How Do You Evaluate an Agent That Calls Tools That Call Other Tools?
transcript
show notes
This story was originally published on HackerNoon at: https://hackernoon.com/how-do-you-evaluate-an-agent-that-calls-tools-that-call-other-tools.
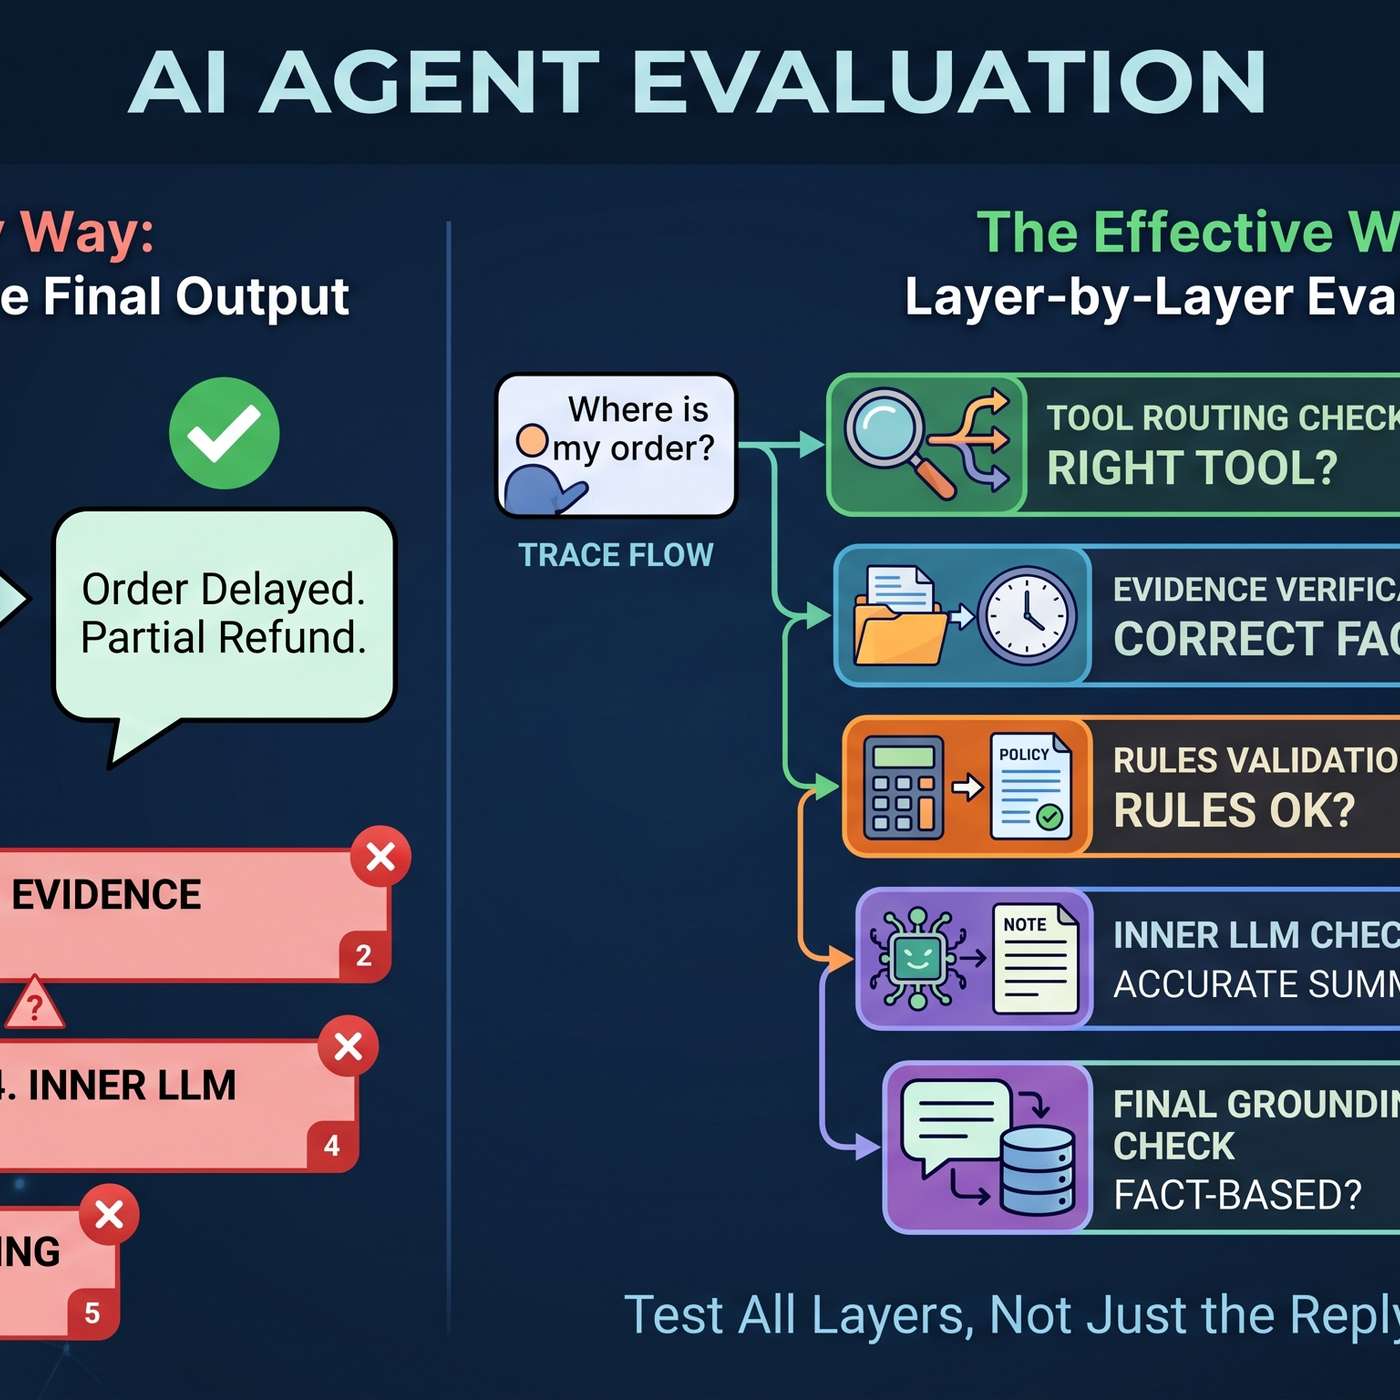
A good final answer can hide failures elsewhere in an AI agent. Test tool routing, evidence retrieval, rules, and model output separately
Check more stories related to machine-learning at: https://hackernoon.com/c/machine-learning.
You can also check exclusive content about #ai-evaluation, #ai-tool-integration, #ai-agent-rule-validation, #ai-agent-evaluation-framework, #ai-agent-testing-and-debugging, #llm-tool-routing-evaluation, #ai-agent-grounding-evaluation, #hackernoon-top-story, and more.
This story was written by: @akeshap. Learn more about this writer by checking @akeshap's about page,
and for more stories, please visit hackernoon.com.
An agent can produce a polished answer after failing three steps upstream. Test the route it chose, the evidence it found, the rules it applied, and the claims it made. Most of that can be checked with code and labeled examples. Use an LLM judge only when the check requires reading language