Skip to content
Artwork for Data Science Tech Brief By HackerNoon
Data Science Tech Brief By HackerNoon · Monday · 9 min

How I Fixed a Data Ingestion Bottleneck With Date Partitioning

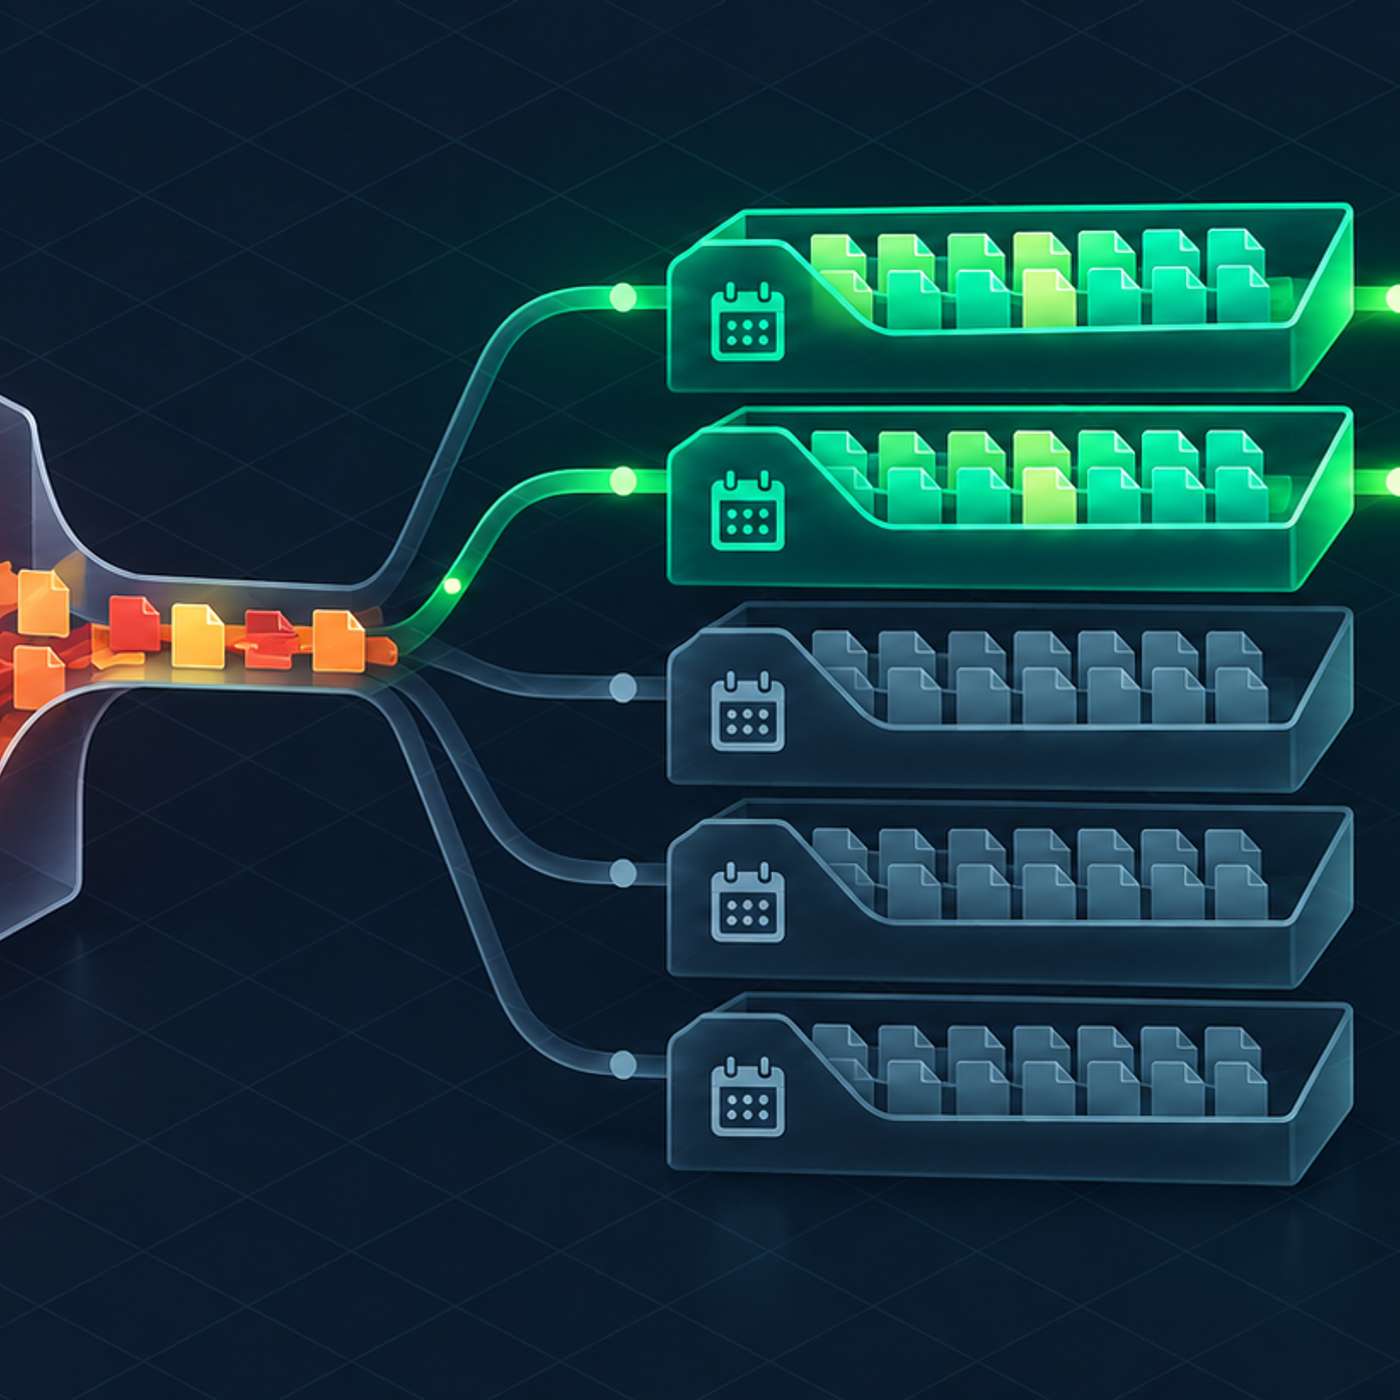
This story was originally published on HackerNoon at: https://hackernoon.com/how-i-fixed-a-data-ingestion-bottleneck-with-date-partitioning. I fixed a recurring data ingestion bottleneck by working with a vendor to introduce date-partitioned exports and reduce unnecessary file discovery. Check more stories related to data-science at: https://hackernoon.com/c/data-science. You can also check exclusive content about #data-engineering, #distributed-systems, #data-ingestion-pipelines, #data-partitioning, #object-storage, #incremental-data-ingestion, #idempotent-data-processing, #data-pipeline-reliability, and more. This story was written by: @rahuln. Learn more about this writer by checking @rahuln's about page, and for more stories, please visit hackernoon.com. Our vendor-data ingestion jobs were repeatedly enumerating a growing history of export files. I worked with the vendor's engineers on date-partitioned delivery and prepared our consumer in parallel. This case study explains how partitioning bounds file discovery, why event-date partitions need late-arrival and replay policies, and how to coordinate the producer-consumer cutover.

0:00-9:12

transcript

No transcript — this publisher did not publish one.

show notes

This story was originally published on HackerNoon at: https://hackernoon.com/how-i-fixed-a-data-ingestion-bottleneck-with-date-partitioning.
I fixed a recurring data ingestion bottleneck by working with a vendor to introduce date-partitioned exports and reduce unnecessary file discovery.
Check more stories related to data-science at: https://hackernoon.com/c/data-science. You can also check exclusive content about #data-engineering, #distributed-systems, #data-ingestion-pipelines, #data-partitioning, #object-storage, #incremental-data-ingestion, #idempotent-data-processing, #data-pipeline-reliability, and more.

This story was written by: @rahuln. Learn more about this writer by checking @rahuln's about page, and for more stories, please visit hackernoon.com.

Our vendor-data ingestion jobs were repeatedly enumerating a growing history of export files. I worked with the vendor's engineers on date-partitioned delivery and prepared our consumer in parallel. This case study explains how partitioning bounds file discovery, why event-date partitions need late-arrival and replay policies, and how to coordinate the producer-consumer cutover.
links13