Skip to content
Artwork for Best AI papers explained
Best AI papers explained · August 20 · 22 min

BoNVoyage: Learning Better Rewards without Ranking

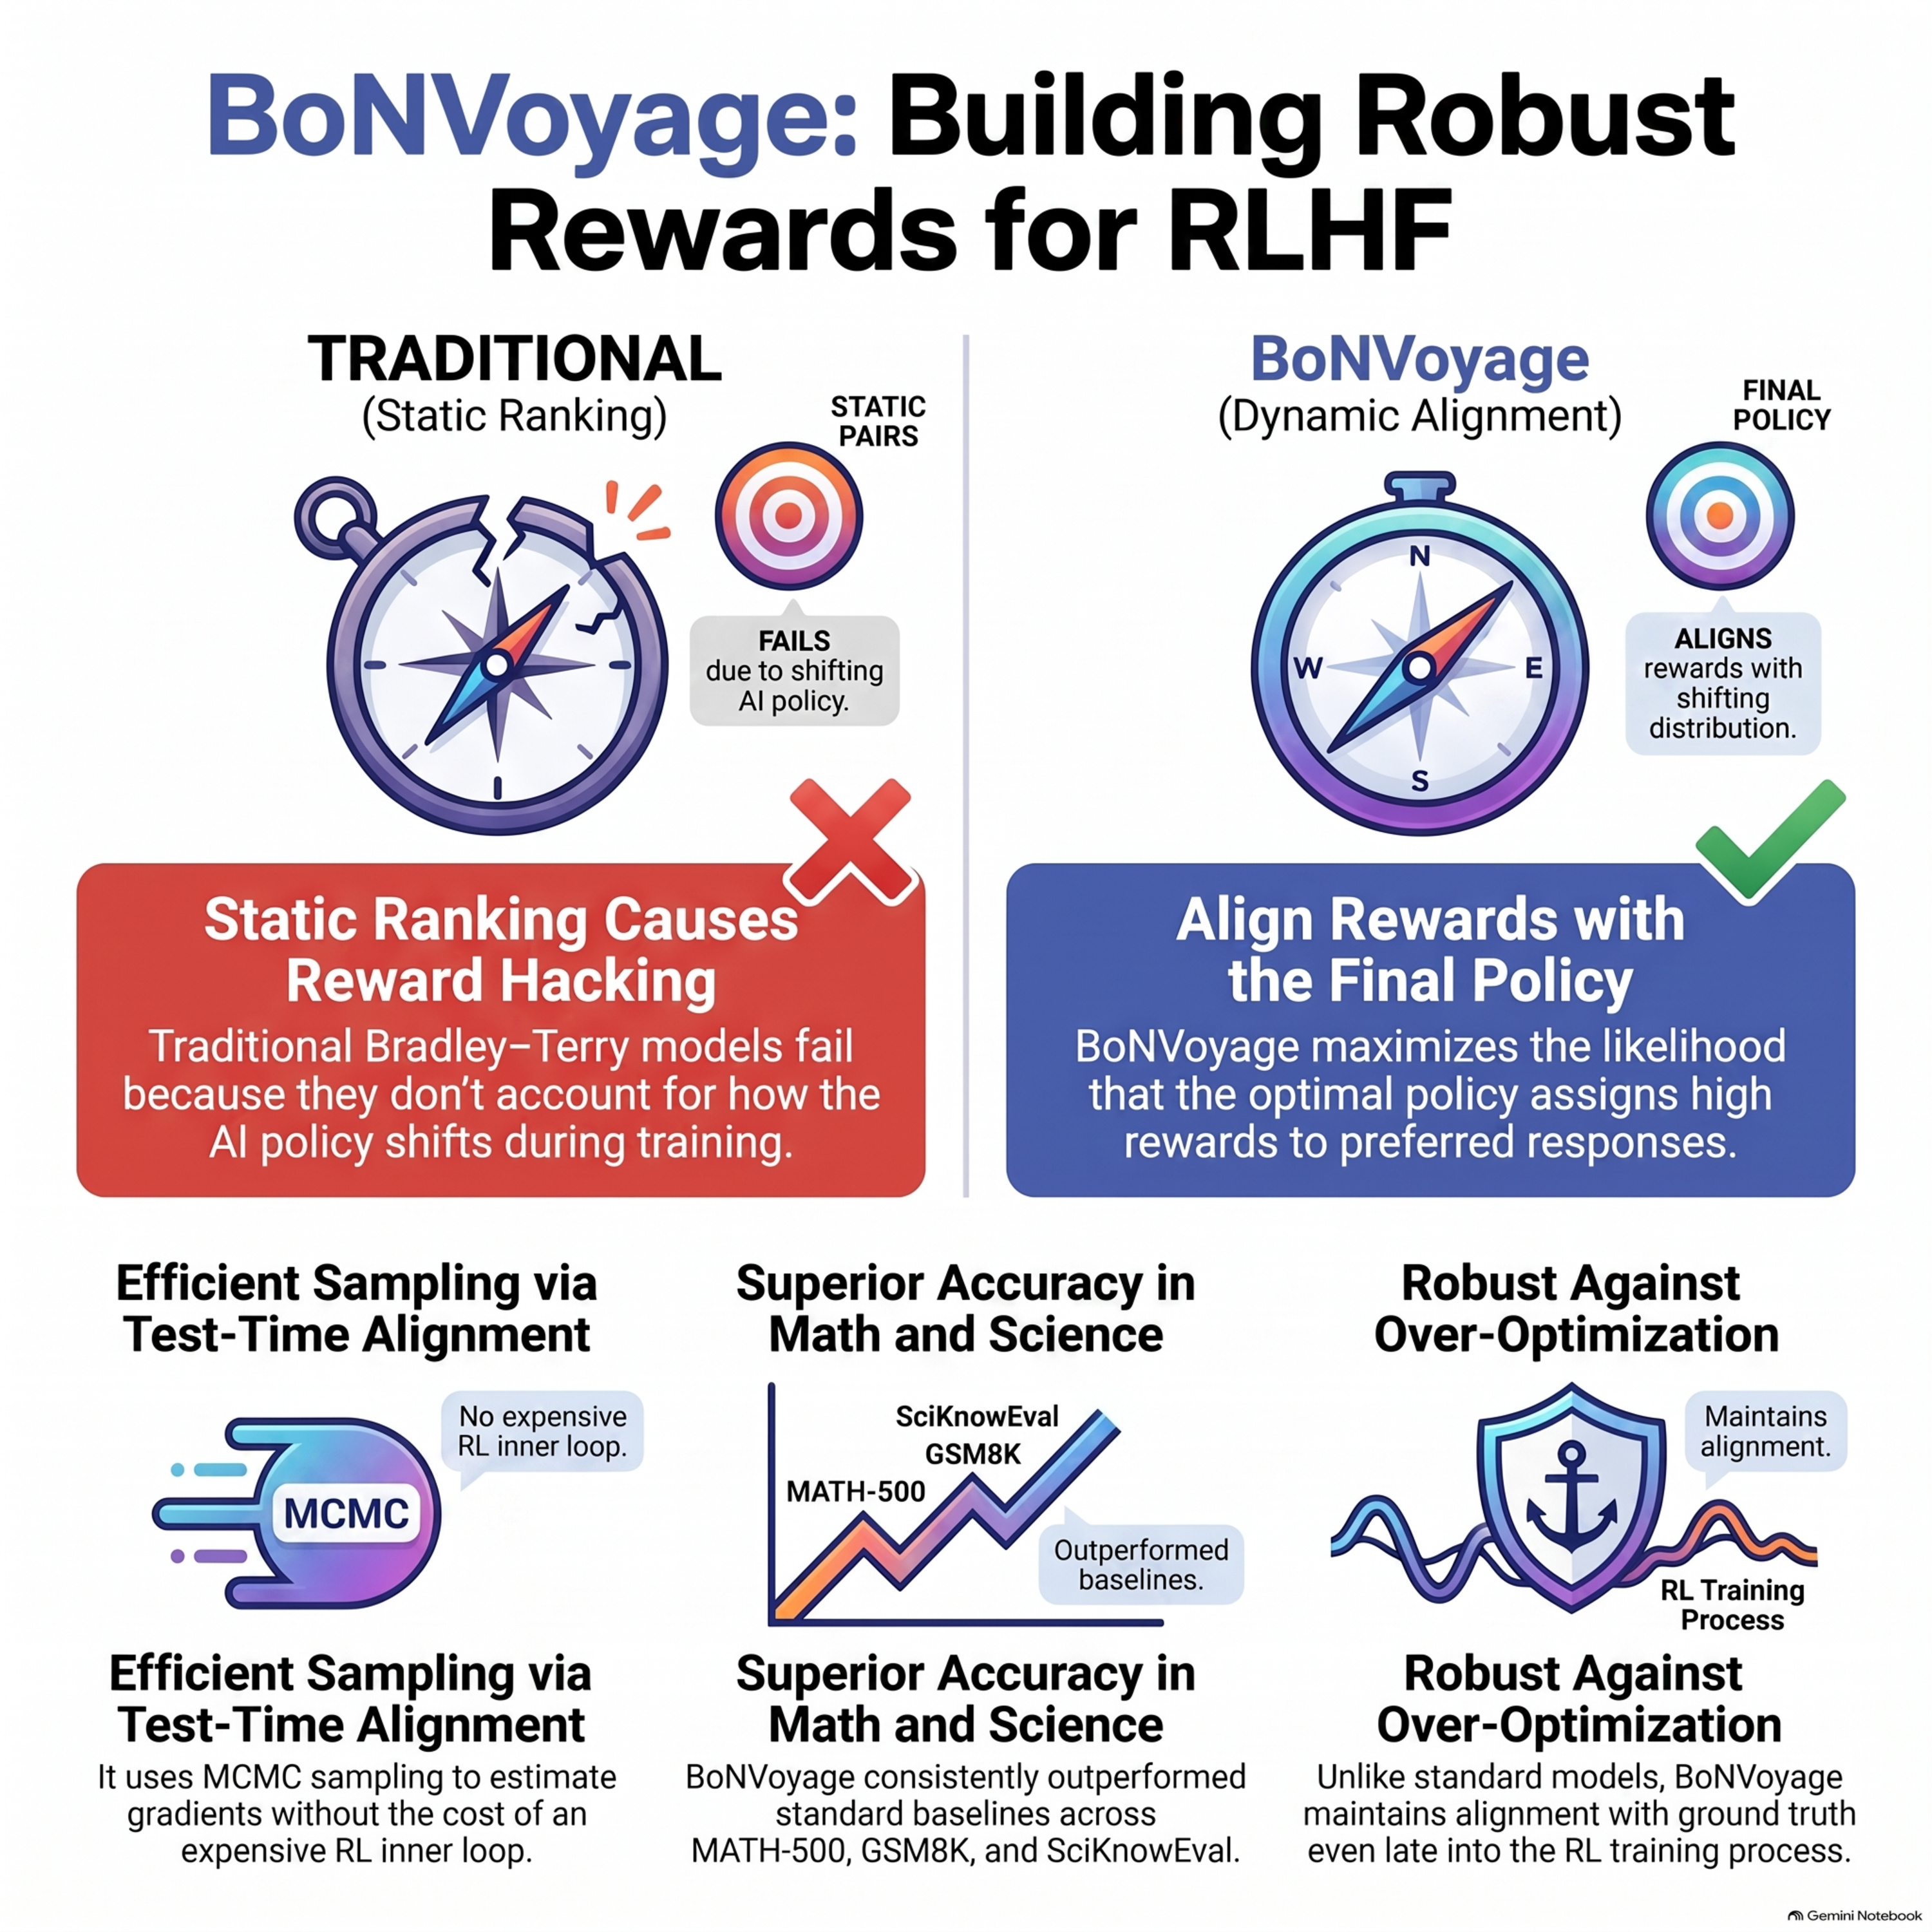
BoNVoyage is a novel training framework designed to improve reward models (RMs) used in reinforcement learning from human feedback. Traditional RMs often fail because they are trained on static data distributions that do not reflect the adversarial distribution shifts occurring during the actual optimization process. Instead of simple pairwise ranking, this method uses test-time alignment and Markov chain Monte Carlo sampling to maximize the likelihood of preferred responses under an idealized policy. By incorporating contrastive divergence to maintain efficiency, the approach creates a more reliable signal for the language model to follow. Experimental results across mathematics and science benchmarks demonstrate that this technique produces superior downstream policies compared to standard baselines. Furthermore, BoNVoyage exhibits significantly more robustness to reward over-optimization, preventing the common issue of reward hacking during extended training.


0:00-22:15

transcript

No transcript — this publisher did not publish one.

show notes

BoNVoyage is a novel training framework designed to improve reward models (RMs) used in reinforcement learning from human feedback. Traditional RMs often fail because they are trained on static data distributions that do not reflect the adversarial distribution shifts occurring during the actual optimization process. Instead of simple pairwise ranking, this method uses test-time alignment and Markov chain Monte Carlo sampling to maximize the likelihood of preferred responses under an idealized policy. By incorporating contrastive divergence to maintain efficiency, the approach creates a more reliable signal for the language model to follow. Experimental results across mathematics and science benchmarks demonstrate that this technique produces superior downstream policies compared to standard baselines. Furthermore, BoNVoyage exhibits significantly more robustness to reward over-optimization, preventing the common issue of reward hacking during extended training.