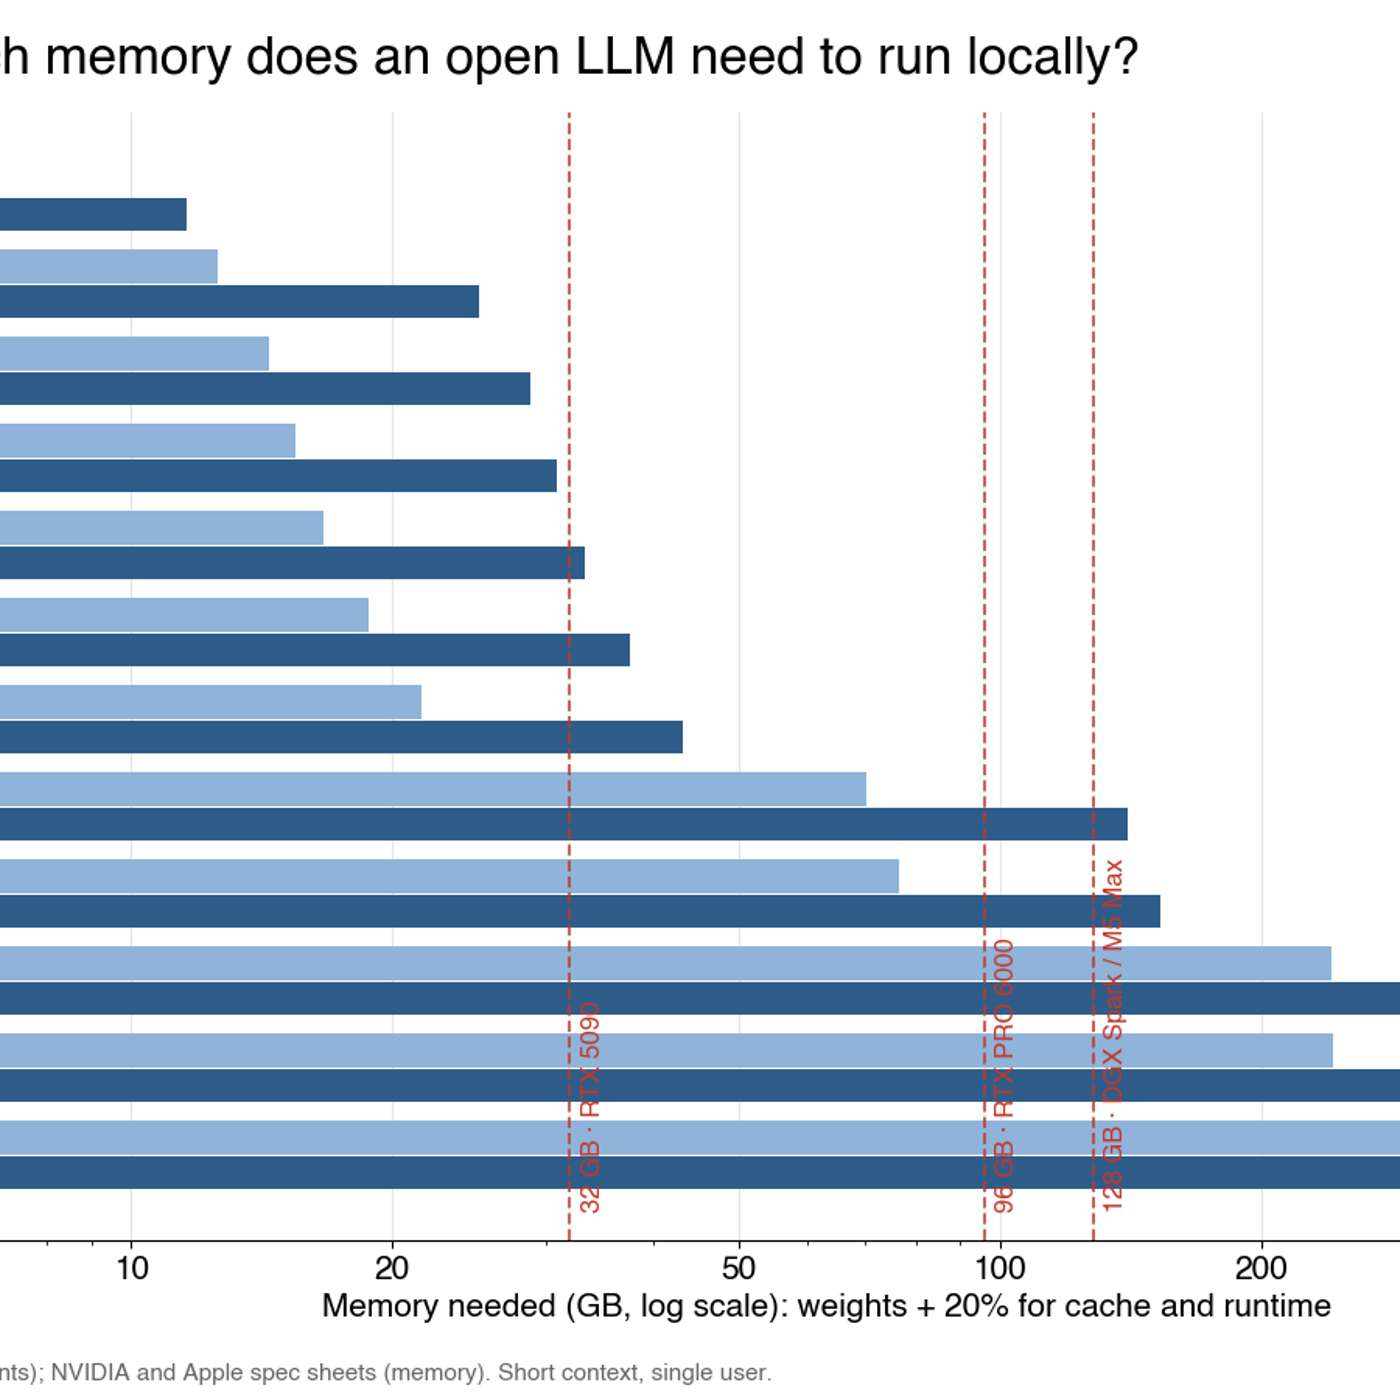
How Much GPU Memory Do You Really Need to Run an Open LLM Locally?
transcript
show notes
This story was originally published on HackerNoon at: https://hackernoon.com/how-much-gpu-memory-do-you-really-need-to-run-an-open-llm-locally.
How to size hardware for a local LLM: weights, KV cache and memory bandwidth, checked against official specs for 12 open models and 9 GPUs and Macs.
Check more stories related to tech-stories at: https://hackernoon.com/c/tech-stories.
You can also check exclusive content about #local-llm, #gpu-memory-requirements, #local-llm-hardware, #llm-quantization, #mixture-of-experts-models, #self-hosted-ai, #vram-estimation, #llm-hardware-sizing, and more.
This story was written by: @contextetech. Learn more about this writer by checking @contextetech's about page,
and for more stories, please visit hackernoon.com.