Skip to content
Artwork for Software Testing Unleashed - QA, DevEx & Quality Engineering
Software Testing Unleashed - QA, DevEx & Quality Engineering · Yesterday · 28 min

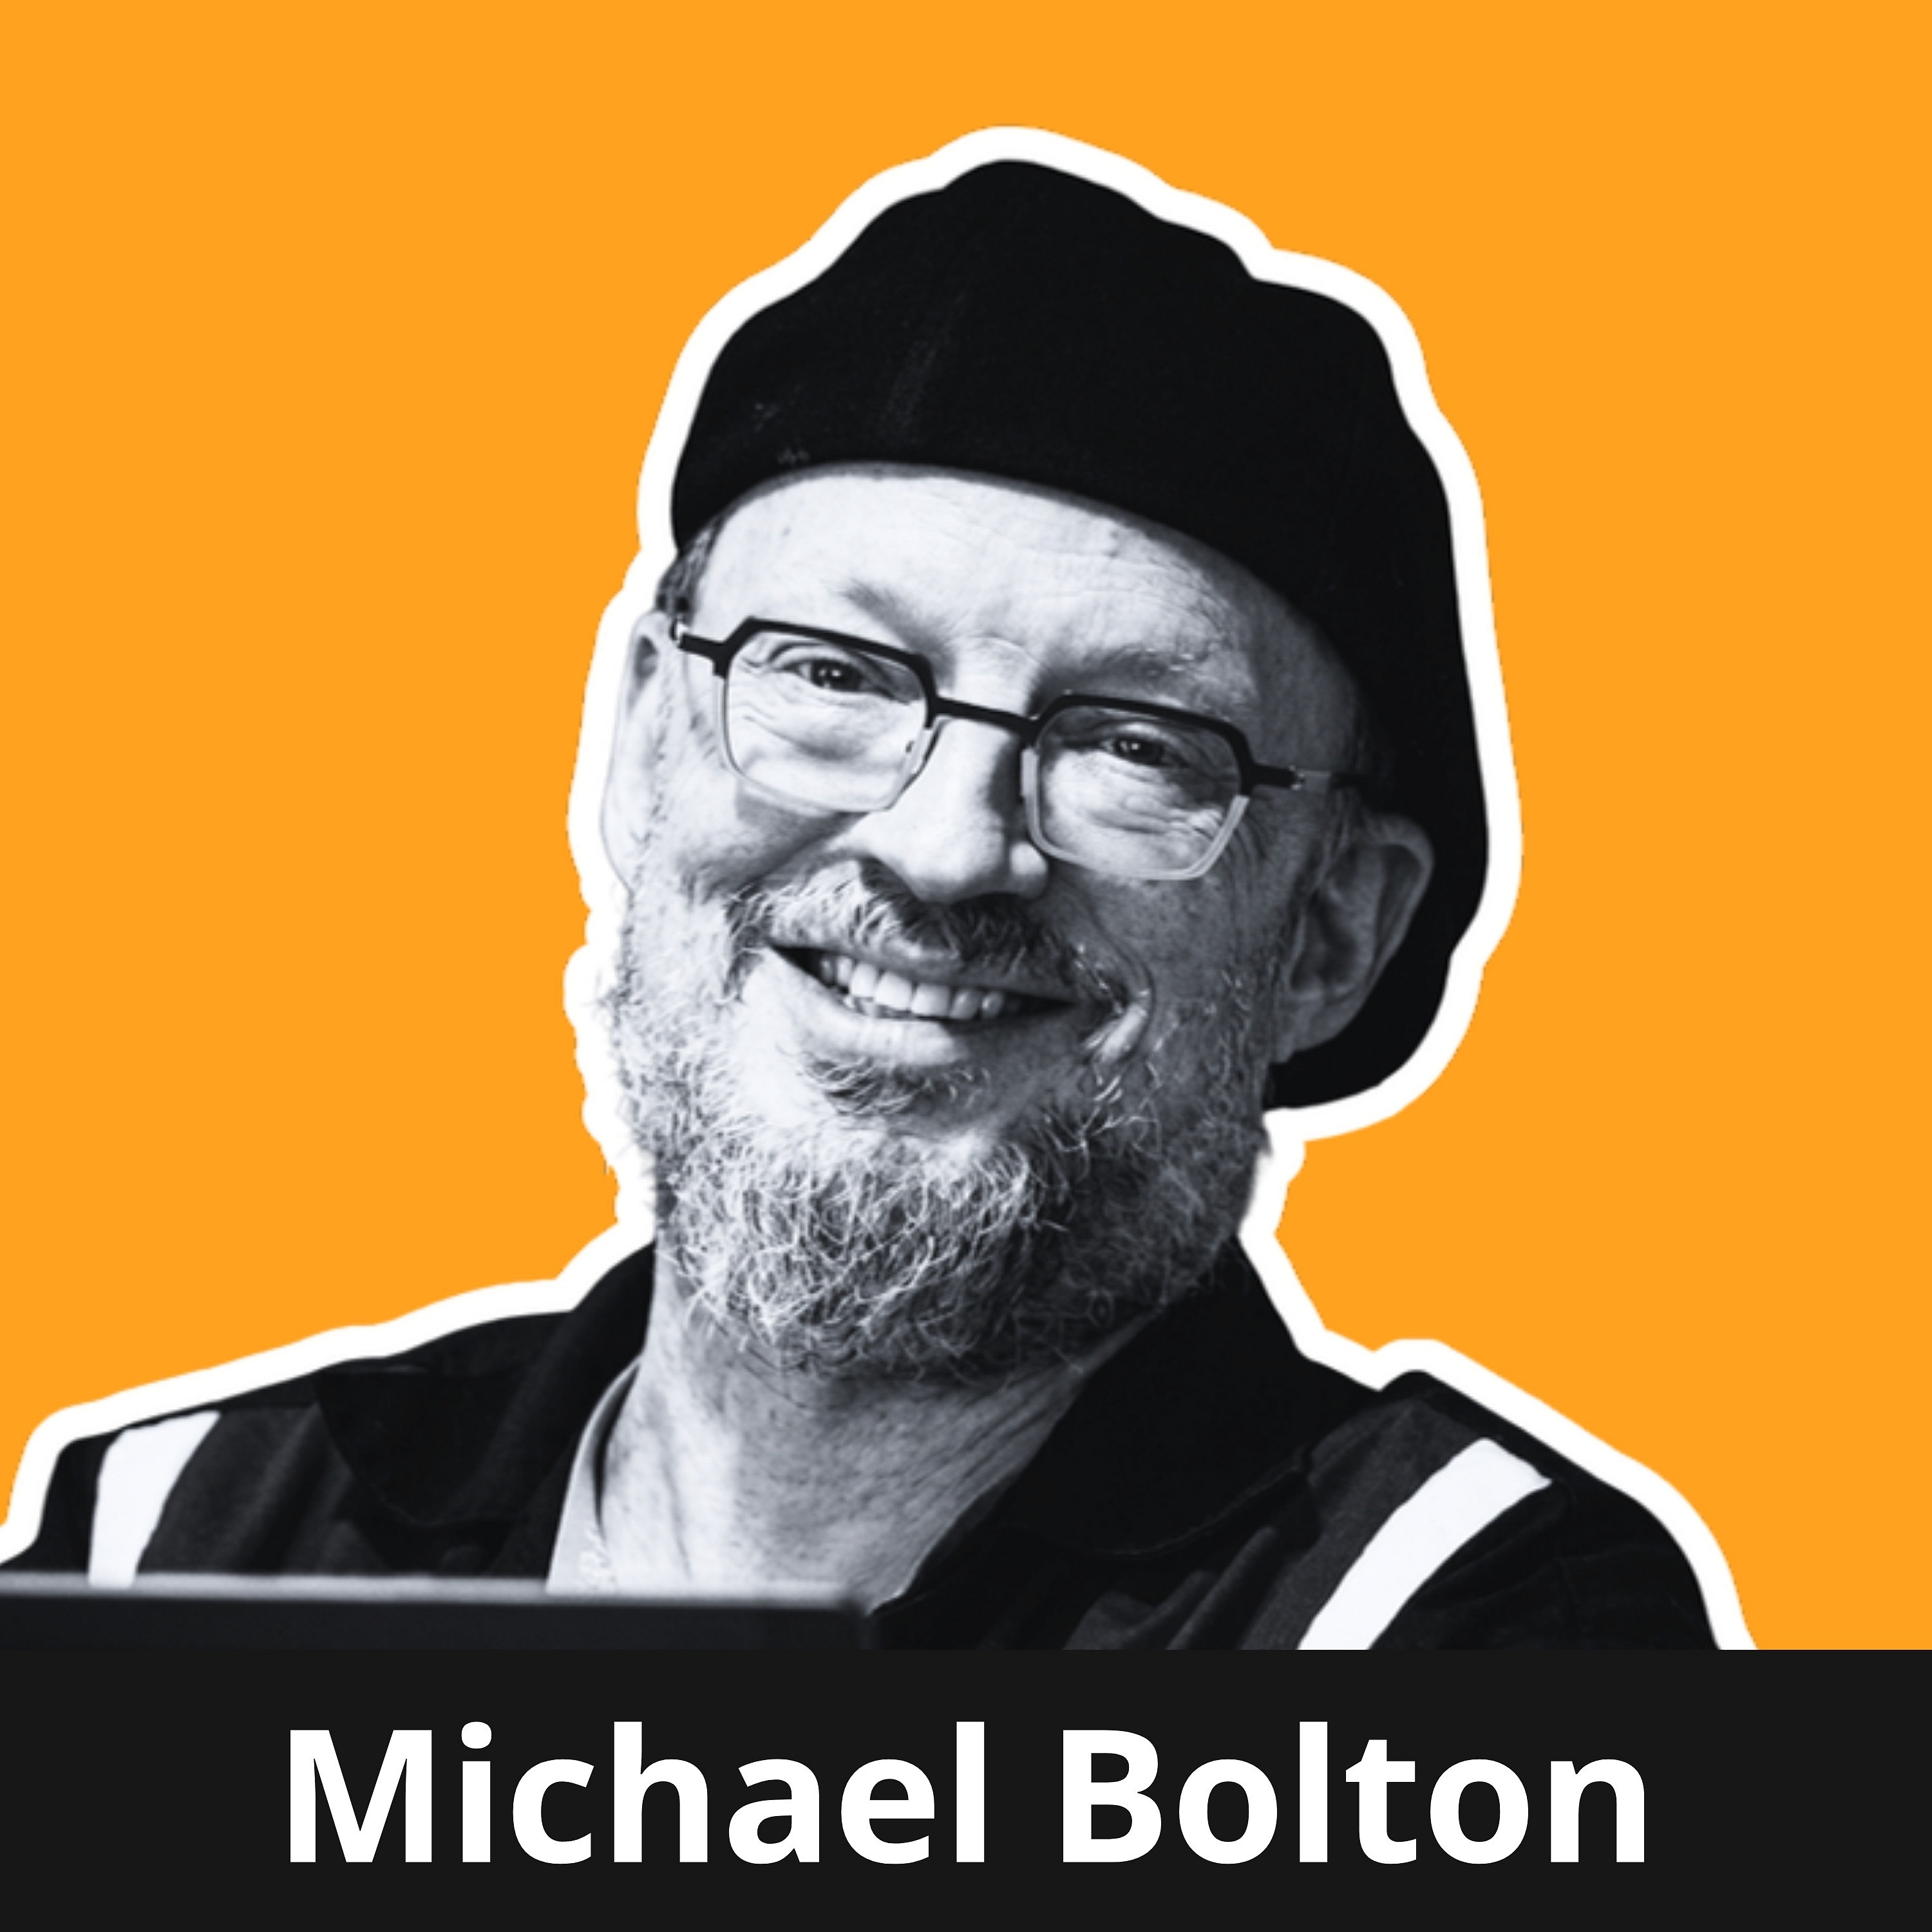
Testing AI Models as Magic Boxes: Why Checks Fail - Michael Bolton

Michael Bolton on how to test LLMs you can neither control nor fully understand Testing AI models means testing a magic box: nobody has the source code, and the behavior is neither controlled nor understood. Michael Bolton calls that strongly magical, and with him I talk about what follows from it. His principles are simple: if something matters very much, don't depend on magic, and if you use it anyway, responsibility demands that you test it and maximize testability. Simple output checks don't stand a chance against a language model, so testing becomes experiencing, exploring and experimenting, like peeling an onion. And Penn and Teller's clear plastic cups show why we fall for these models in the first place: the insight we see in their text comes from us. "If something matters very much, you probably shouldn't depend on magic to get it." - Michael Bolton Michael Bolton is a consulting software tester and testing teacher who helps people to solve testing problems that they didn't realize they could solve. In 2006, he became co-author (with James Bach) of Rapid Software Testing (RST), a methodology and mindset for testing software expertly and credibly in uncertain conditions and under extreme time pressure. Michael has over 30 years of experience testing, developing, managing, and writing about software. For over 20 years, he has led DevelopSense, a Toronto-based testing and development consultancy. Prior to that, he was with Quarterdeck Corporation for eight years, during which he managed the company's flagship products and directed project and testing teams both in-house and around the world. Highlights: Machine learning models are not developed by a conscious, intentional human; Michael Bolton compares them to strains from petri dishes. Nobody knows how they work, nobody has their source code. Testing AI models with output checks is hopeless: that approach works for deterministic software developers understand and can instrument, and a large language model is neither. Nothing that matters very much should depend on magic; a bot writing a funny poem for a party carries no risk, a bot giving medical advice carries a big one. Anyone asking how to test LLMs without source code can still monitor inputs and outputs and know the training data, guardrails, context window and outside calls, which shrinks the magic. Large language models fool us like a mentalist on stage, because patterns of text suggest insight while the insight comes from the reader making sense of the output. More Links with Insights: DevelopSense 📘 Tool migration ahead? Teamscale playbook: migrate only 20% of tests, keep nearly all bug detection. Download for free

0:00-28:07

transcript

No transcript — this publisher did not publish one.

show notes

Michael Bolton on how to test LLMs you can neither control nor fully understand

Testing AI models means testing a magic box: nobody has the source code, and the behavior is neither controlled nor understood. Michael Bolton calls that strongly magical, and with him I talk about what follows from it. His principles are simple: if something matters very much, don't depend on magic, and if you use it anyway, responsibility demands that you test it and maximize testability. Simple output checks don't stand a chance against a language model, so testing becomes experiencing, exploring and experimenting, like peeling an onion. And Penn and Teller's clear plastic cups show why we fall for these models in the first place: the insight we see in their text comes from us.

"If something matters very much, you probably shouldn't depend on magic to get it." - Michael Bolton

Michael Bolton is a consulting software tester and testing teacher who helps people to solve testing problems that they didn't realize they could solve. In 2006, he became co-author (with James Bach) of Rapid Software Testing (RST), a methodology and mindset for testing software expertly and credibly in uncertain conditions and under extreme time pressure.

Michael has over 30 years of experience testing, developing, managing, and writing about software. For over 20 years, he has led DevelopSense, a Toronto-based testing and development consultancy. Prior to that, he was with Quarterdeck Corporation for eight years, during which he managed the company's flagship products and directed project and testing teams both in-house and around the world.

Highlights:

  • Machine learning models are not developed by a conscious, intentional human; Michael Bolton compares them to strains from petri dishes. Nobody knows how they work, nobody has their source code.
  • Testing AI models with output checks is hopeless: that approach works for deterministic software developers understand and can instrument, and a large language model is neither.
  • Nothing that matters very much should depend on magic; a bot writing a funny poem for a party carries no risk, a bot giving medical advice carries a big one.
  • Anyone asking how to test LLMs without source code can still monitor inputs and outputs and know the training data, guardrails, context window and outside calls, which shrinks the magic.
  • Large language models fool us like a mentalist on stage, because patterns of text suggest insight while the insight comes from the reader making sense of the output.

More Links with Insights:

📘 Tool migration ahead? Teamscale playbook: migrate only 20% of tests, keep nearly all bug detection. Download for free
links3