Skip to content
Artwork for LessWrong (30+ Karma)
LessWrong (30+ Karma) · October 26 · 12 min

“Is GPT 2XL already clean?” by Jasper Blank

In which I investigate if Opus is able to interpret neurons better than GPT 4. TLDR: Opus 5.5 is able to identify 3-19% of the neurons of GPT 2-XL based on activations. This is a big improvement over the 0.3% that GPT-4 was able to achieve in 2023. #AI notice: This post is human written but in the research there was heavy use of Opus 5.5. I mainly asked it to rerun this 2023 paper to see how big the improvement is if Opus 5.5 is used instead of GPT4. Since the invention of Large language models they have been stubbornly refusing to be clear. They have been described as black boxes and as inscrutable machines, if this stays true that is bad news for detecting AI scheming and thus Alignment. Recently the Goodfire post told us that neural networks are already clean and that simply looking into the neurons is enough. For the case of this post I mean to say that a neural network is clean if we can understand what the neurons do only by looking at the neurons and not by creating some additional derived object to study. This inspired me [...] --- Outline: (02:11) Methods 1: OpenAI (05:02) Methods 2: Opus 5.5 (07:06) How good is Opus at one shotting these explanations? (09:03) Exploring a single difficult neuron (10:46) Future plans (11:24) Appendix 1: Link to the Claude conversation (11:38) Appendix 2: Comparing explainer to simulator The original text contained 2 footnotes which were omitted from this narration. --- First published: October 25th, 2026 Source: https://www.lesswrong.com/posts/drMv4SM2gaxk3oz3m/is-gpt-2xl-already-clean --- Narrated by TYPE III AUDIO. --- Images from the article: Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
0:00-12:26

transcript

No transcript — this publisher did not publish one.

show notes

In which I investigate if Opus is able to interpret neurons better than GPT 4.

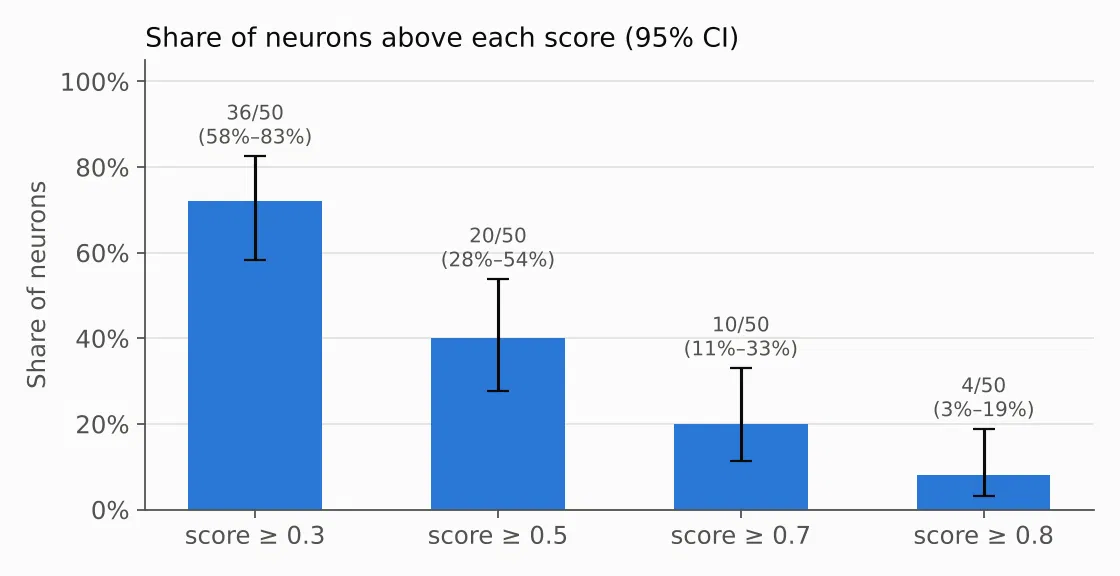
TLDR: Opus 5.5 is able to identify 3-19% of the neurons of GPT 2-XL based on activations. This is a big improvement over the 0.3% that GPT-4 was able to achieve in 2023.

#AI notice: This post is human written but in the research there was heavy use of Opus 5.5. I mainly asked it to rerun this 2023 paper to see how big the improvement is if Opus 5.5 is used instead of GPT4.


Since the invention of Large language models they have been stubbornly refusing to be clear. They have been described as black boxes and as inscrutable machines, if this stays true that is bad news for detecting AI scheming and thus Alignment. Recently the Goodfire post told us that neural networks are already clean and that simply looking into the neurons is enough. For the case of this post I mean to say that a neural network is clean if we can understand what the neurons do only by looking at the neurons and not by creating some additional derived object to study.

This inspired me [...]

---

Outline:

(02:11) Methods 1: OpenAI

(05:02) Methods 2: Opus 5.5

(07:06) How good is Opus at one shotting these explanations?

(09:03) Exploring a single difficult neuron

(10:46) Future plans

(11:24) Appendix 1: Link to the Claude conversation

(11:38) Appendix 2: Comparing explainer to simulator

The original text contained 2 footnotes which were omitted from this narration.

---

First published:
October 25th, 2026

Source:
https://www.lesswrong.com/posts/drMv4SM2gaxk3oz3m/is-gpt-2xl-already-clean

---

Narrated by TYPE III AUDIO.

---

Images from the article:
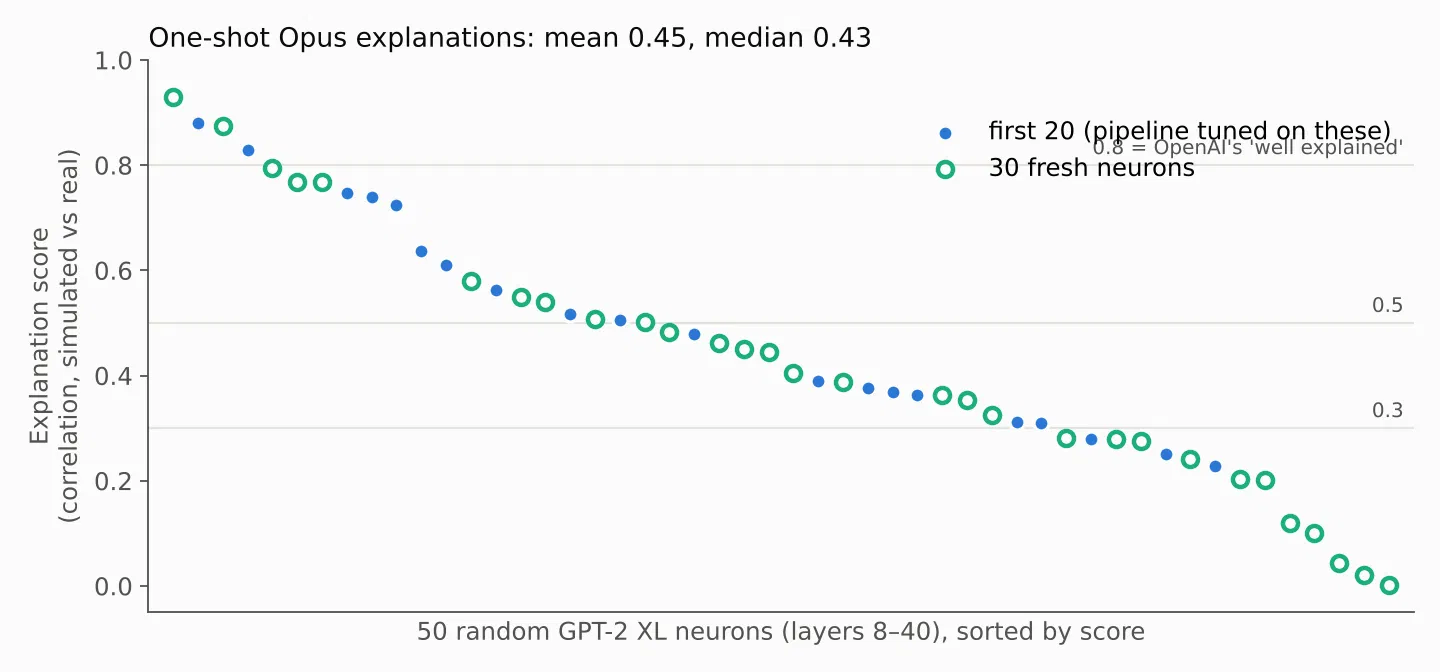
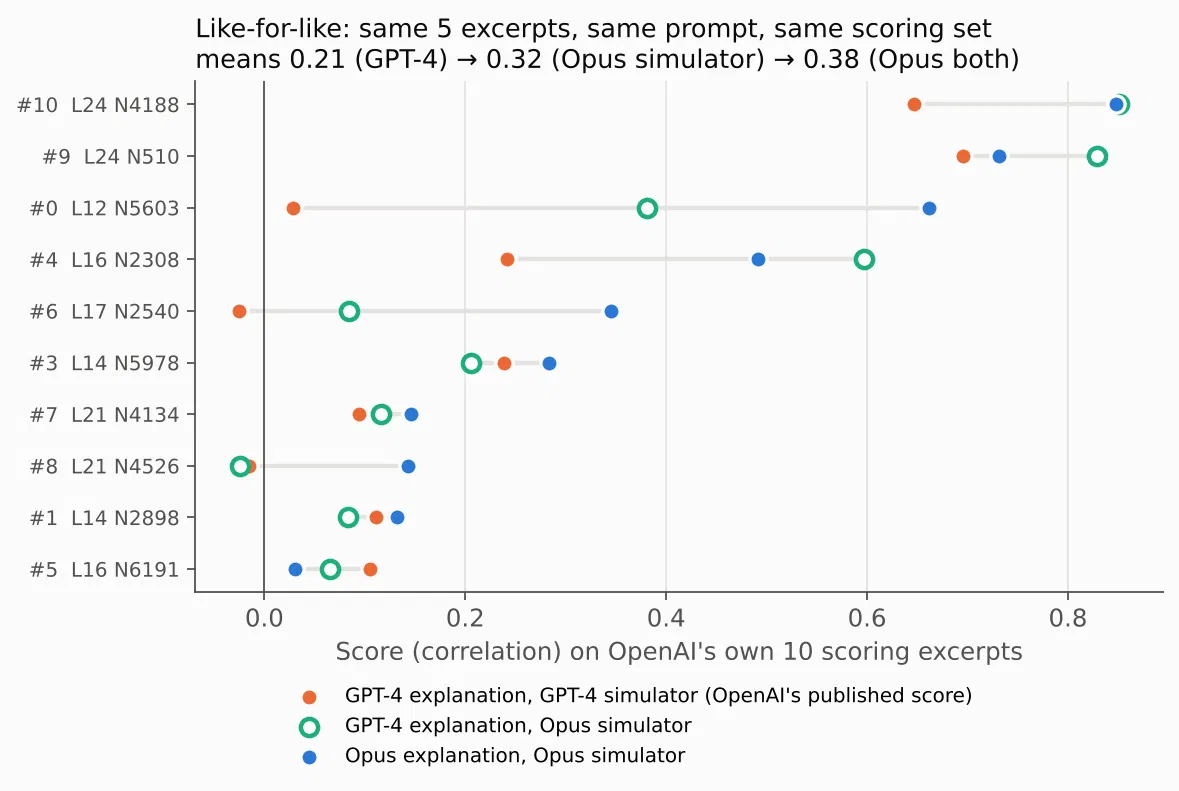
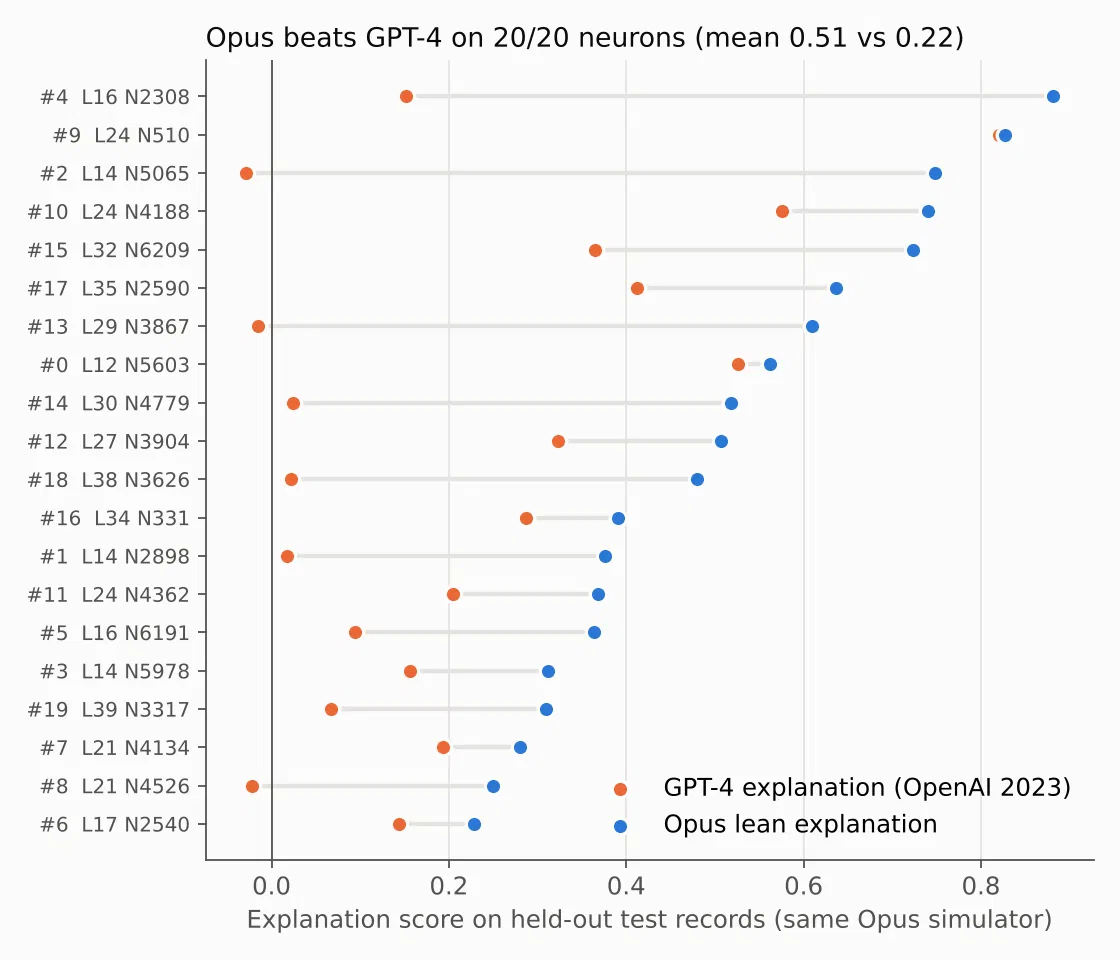
Fig 1: The explanation score of both Opus 5.5 and GPT-4 on the same data
Fig 2: All 50 identified neurons and their Explanation scores
Fig 3:4 bars showing what percentage of neurons was able to score above criteria level. 0.7 corresponds to about half of the variation in the neuron's activity being explained and 0.8 corresponds to around 64%.
Fig 4

Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.

links7