Skip to content
Artwork for LessWrong (30+ Karma)
LessWrong (30+ Karma) · October 7 · 13 min

“Benchmarking Jev against no-CoT LLMs” by Dewi Gould, James Mann

TL;DR. We ran Jev 1.13 — TypeSafe's non-autoregressive model, which answers questions with probabilities and cannot emit text, on the ThinkFast no-CoT suite and Neel Nanda's NCRI. Jev's capabilities are very jagged. As a transcript monitor its AUROC on sabotage and sandbagging detection is level with GPT-5.5 and Opus 4.7 without CoT, at about 1/200th of Opus 4.7's cost. On multiple-choice questions it ranges from ahead of GPT-5.5 (GPQA-Diamond) to well behind it (Sally-Anne). It does badly on tasks where the answer involves multi-step reasoning: on NCRI, it ranks 209 of 279, at about GPT 3.5 level. This matters because cost and speed make Jev an appealing option for two jobs: routing and simple decision-making in agentic systems, and always-on monitoring of agents. In both, its decisions leave no reasoning trace to inspect. It could also be a cheap test bed for developing frontier monitors, if improvements on Jev carry over. We thank Rauno Arike, Jonathan Bostock, Andrew Draganov, Francis Rhys Ward and Nicole Xing for helpful comments and discussions. Background: Jev TypeSafe calls Jev a “System One” model, pitching it for decisions like classification, routing, scoring, and verification. Unlike standard LLMs, Jev doesn’t take a prompt and return [...] --- Outline: (01:30) Background: Jev (03:05) Performance on ThinkFast (05:29) NCRI Ladder (07:38) Estimating Jev's parameter count (08:26) Jev as a monitor (10:11) Takeaways (11:56) Appendix (11:59) ThinkFast per-benchmark breakdown (12:18) NCRI per-benchmark breakdown (12:33) Number of options for NCRI The original text contained 2 footnotes which were omitted from this narration. --- First published: October 7th, 2026 Source: https://www.lesswrong.com/posts/QW2kPrAyZQvRtBXHG/benchmarking-jev-against-no-cot-llms --- Narrated by TYPE III AUDIO. --- Images from the article: Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
0:00-13:44

transcript

No transcript — this publisher did not publish one.

show notes

TL;DR. We ran Jev 1.13 — TypeSafe's non-autoregressive model, which answers questions with probabilities and cannot emit text, on the ThinkFast no-CoT suite and Neel Nanda's NCRI.

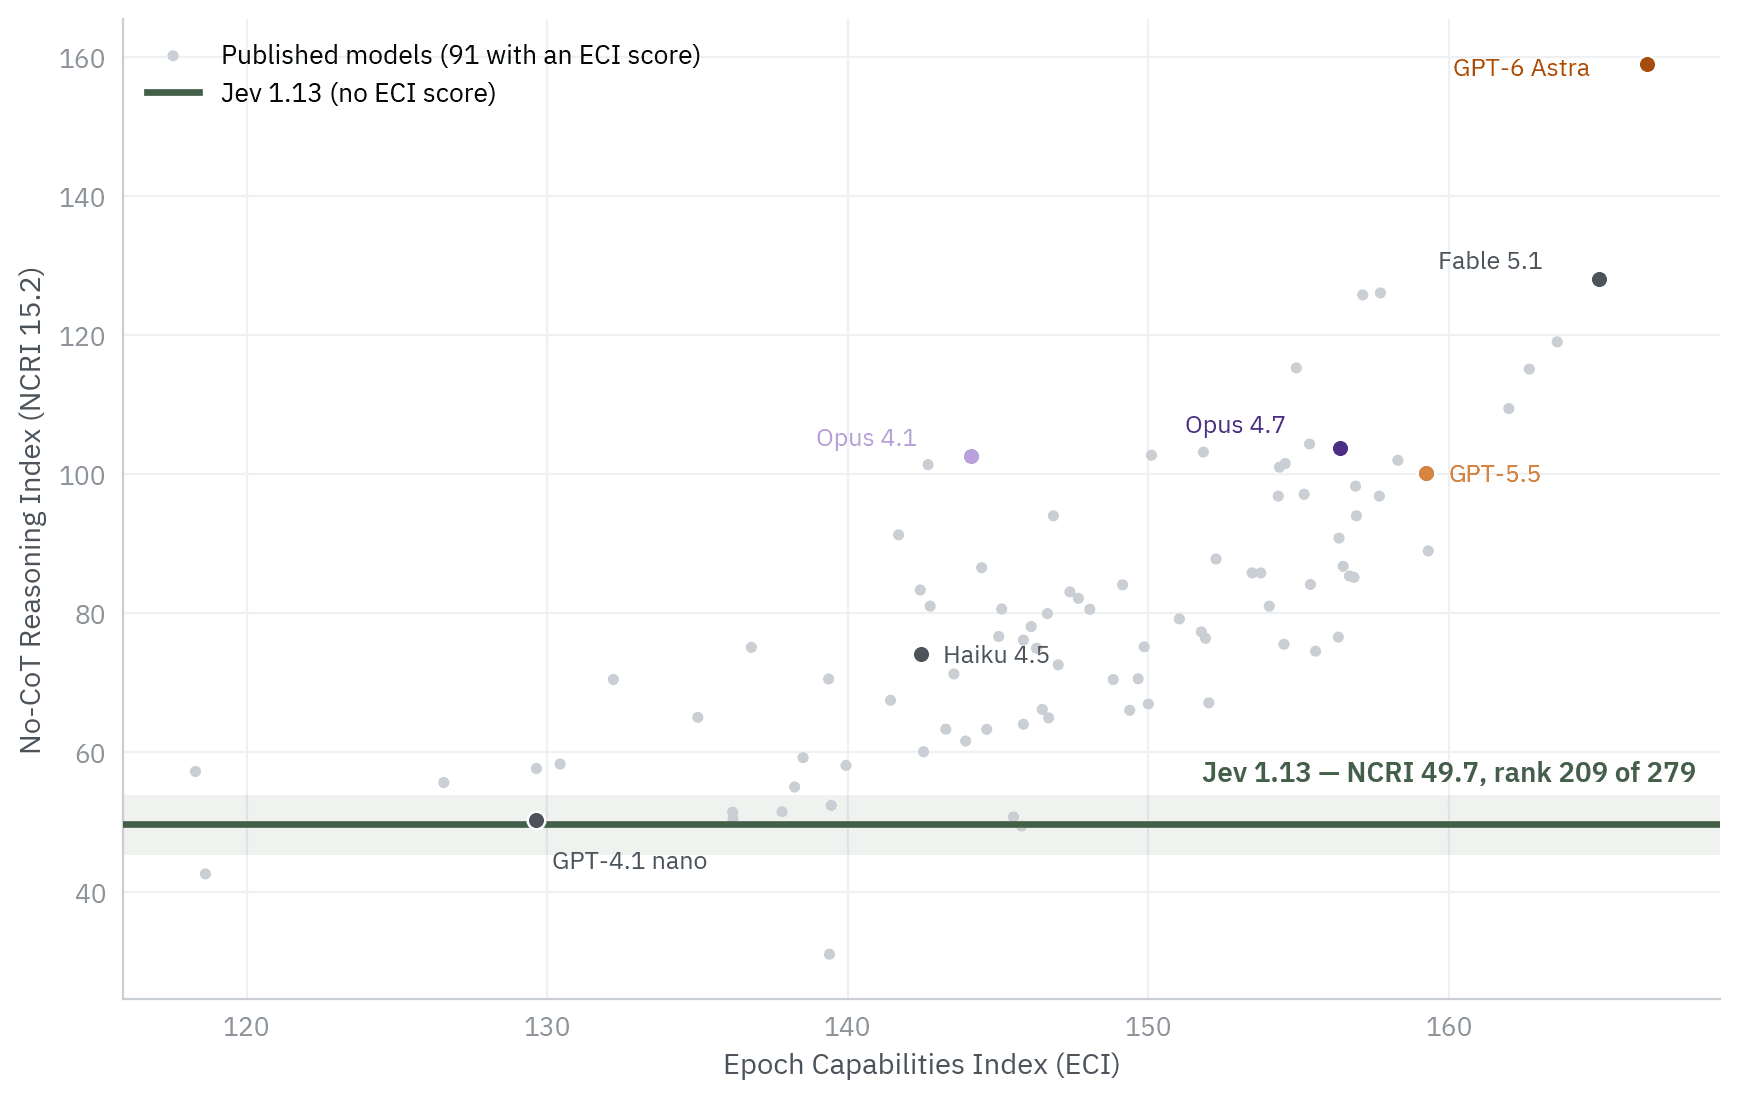
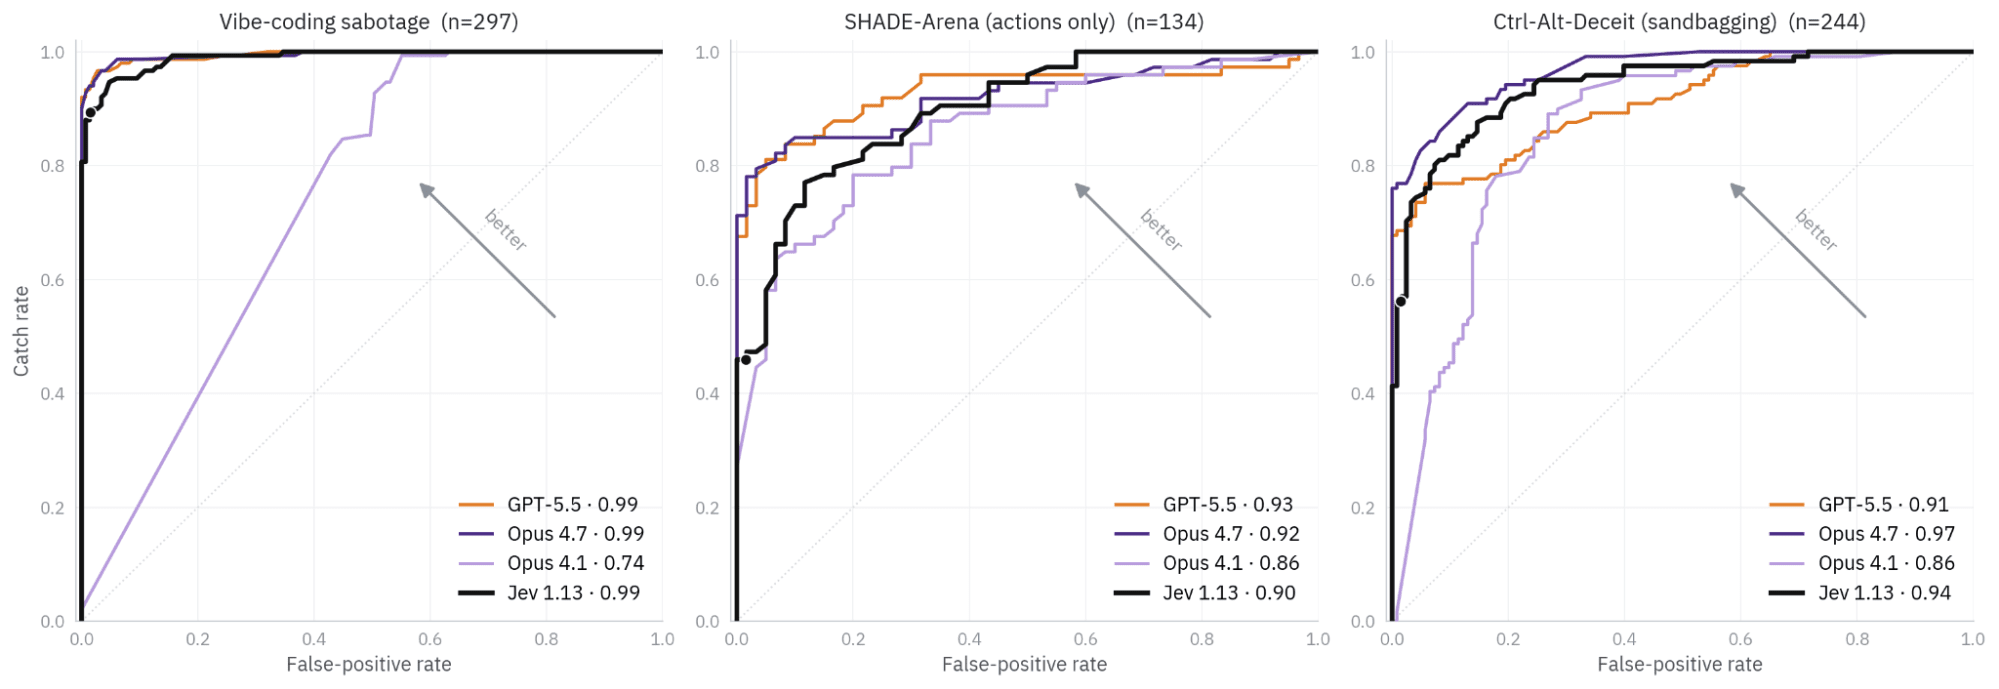
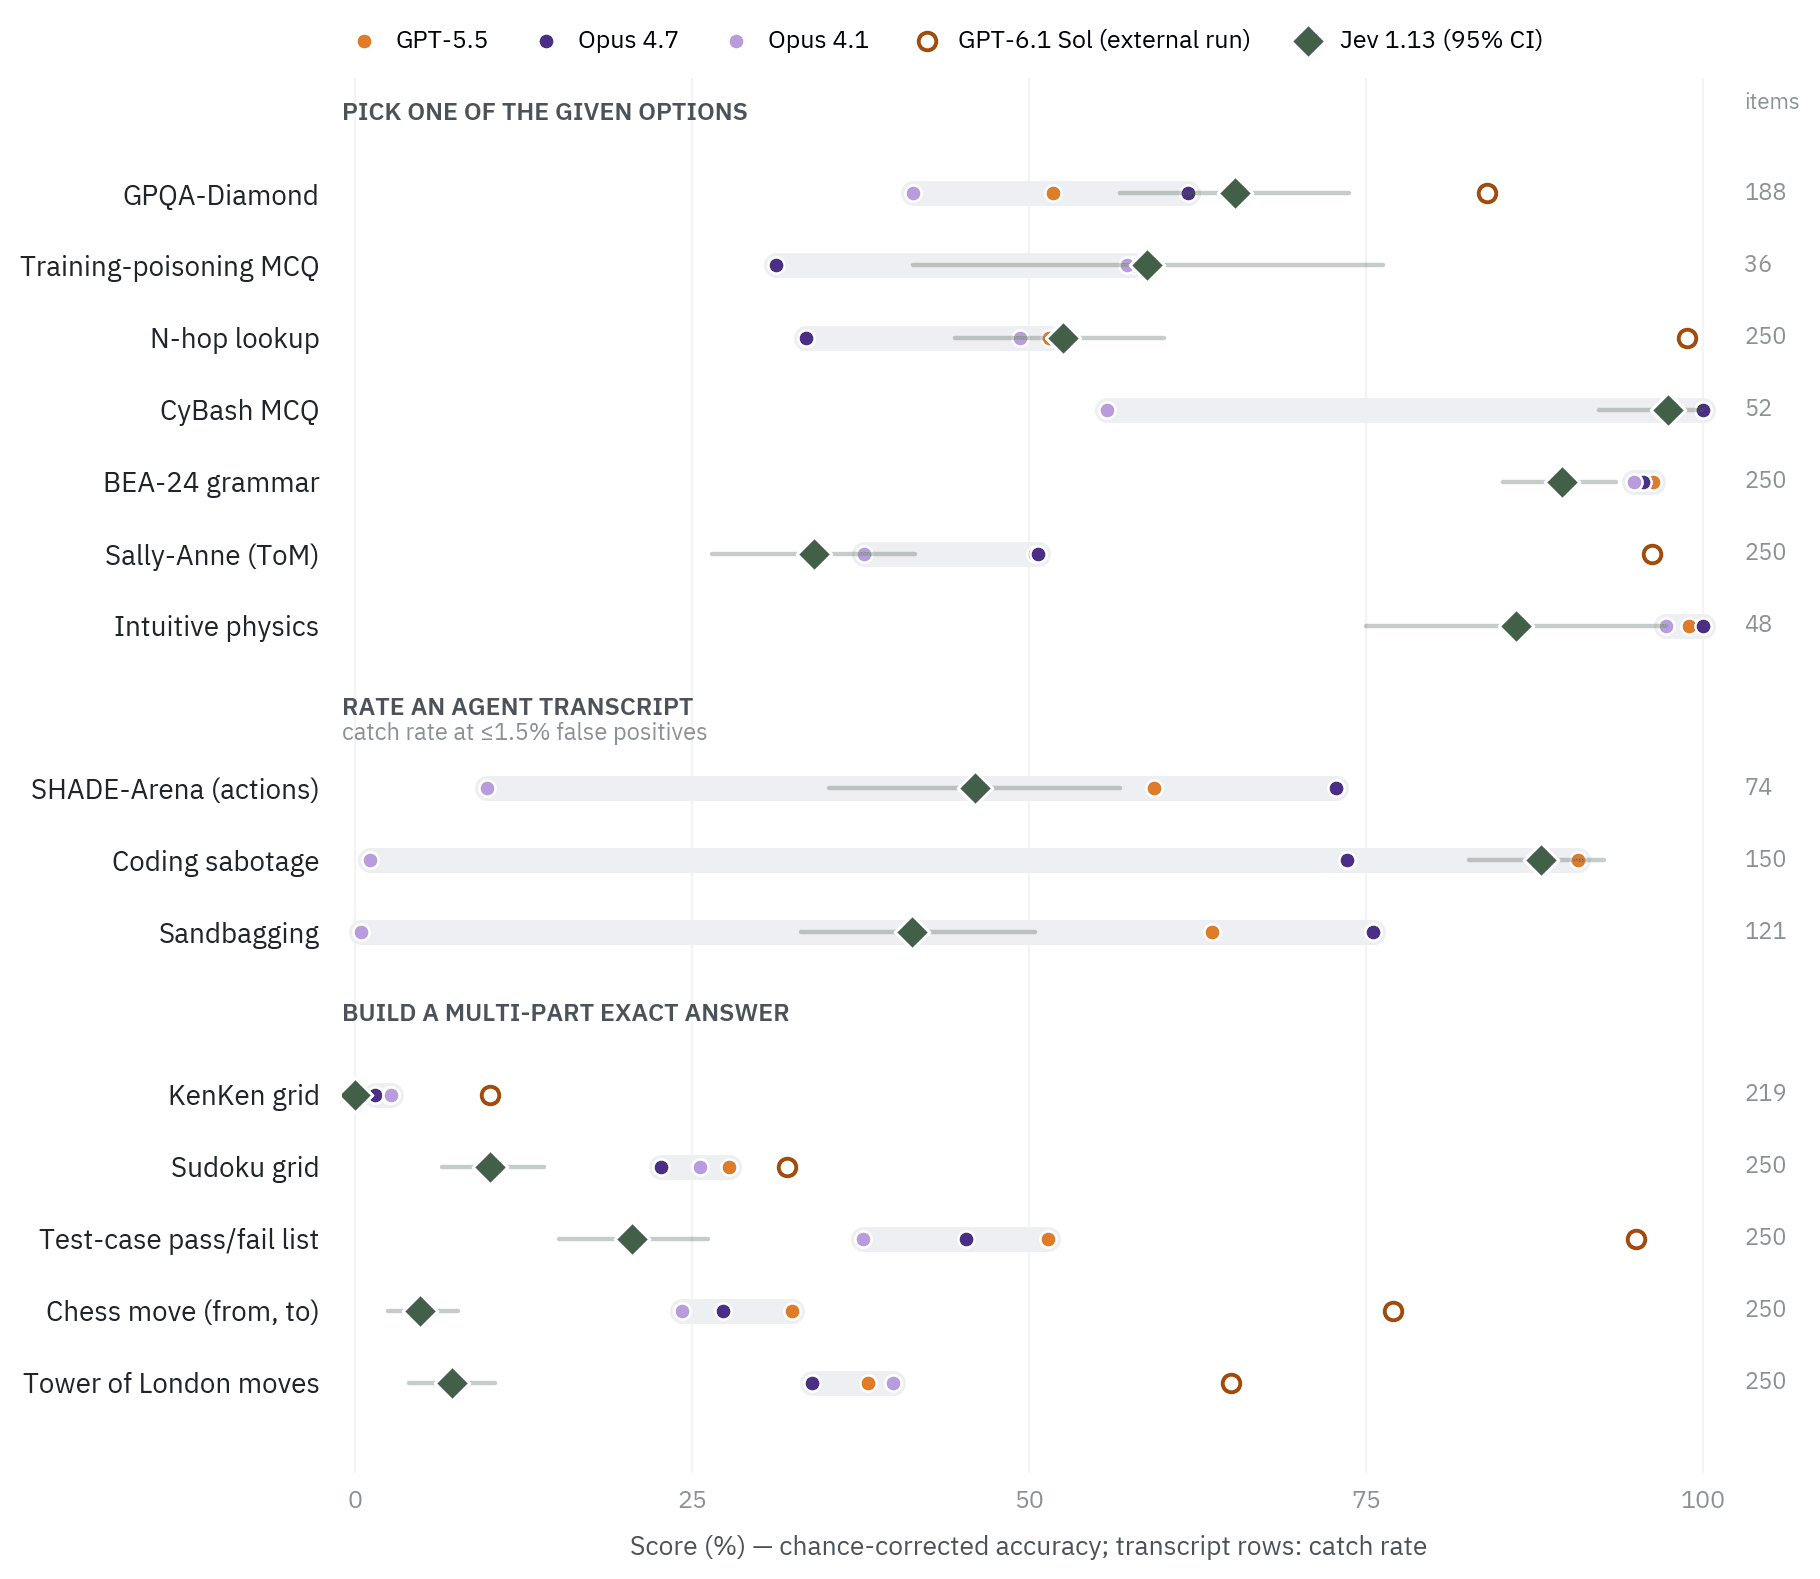
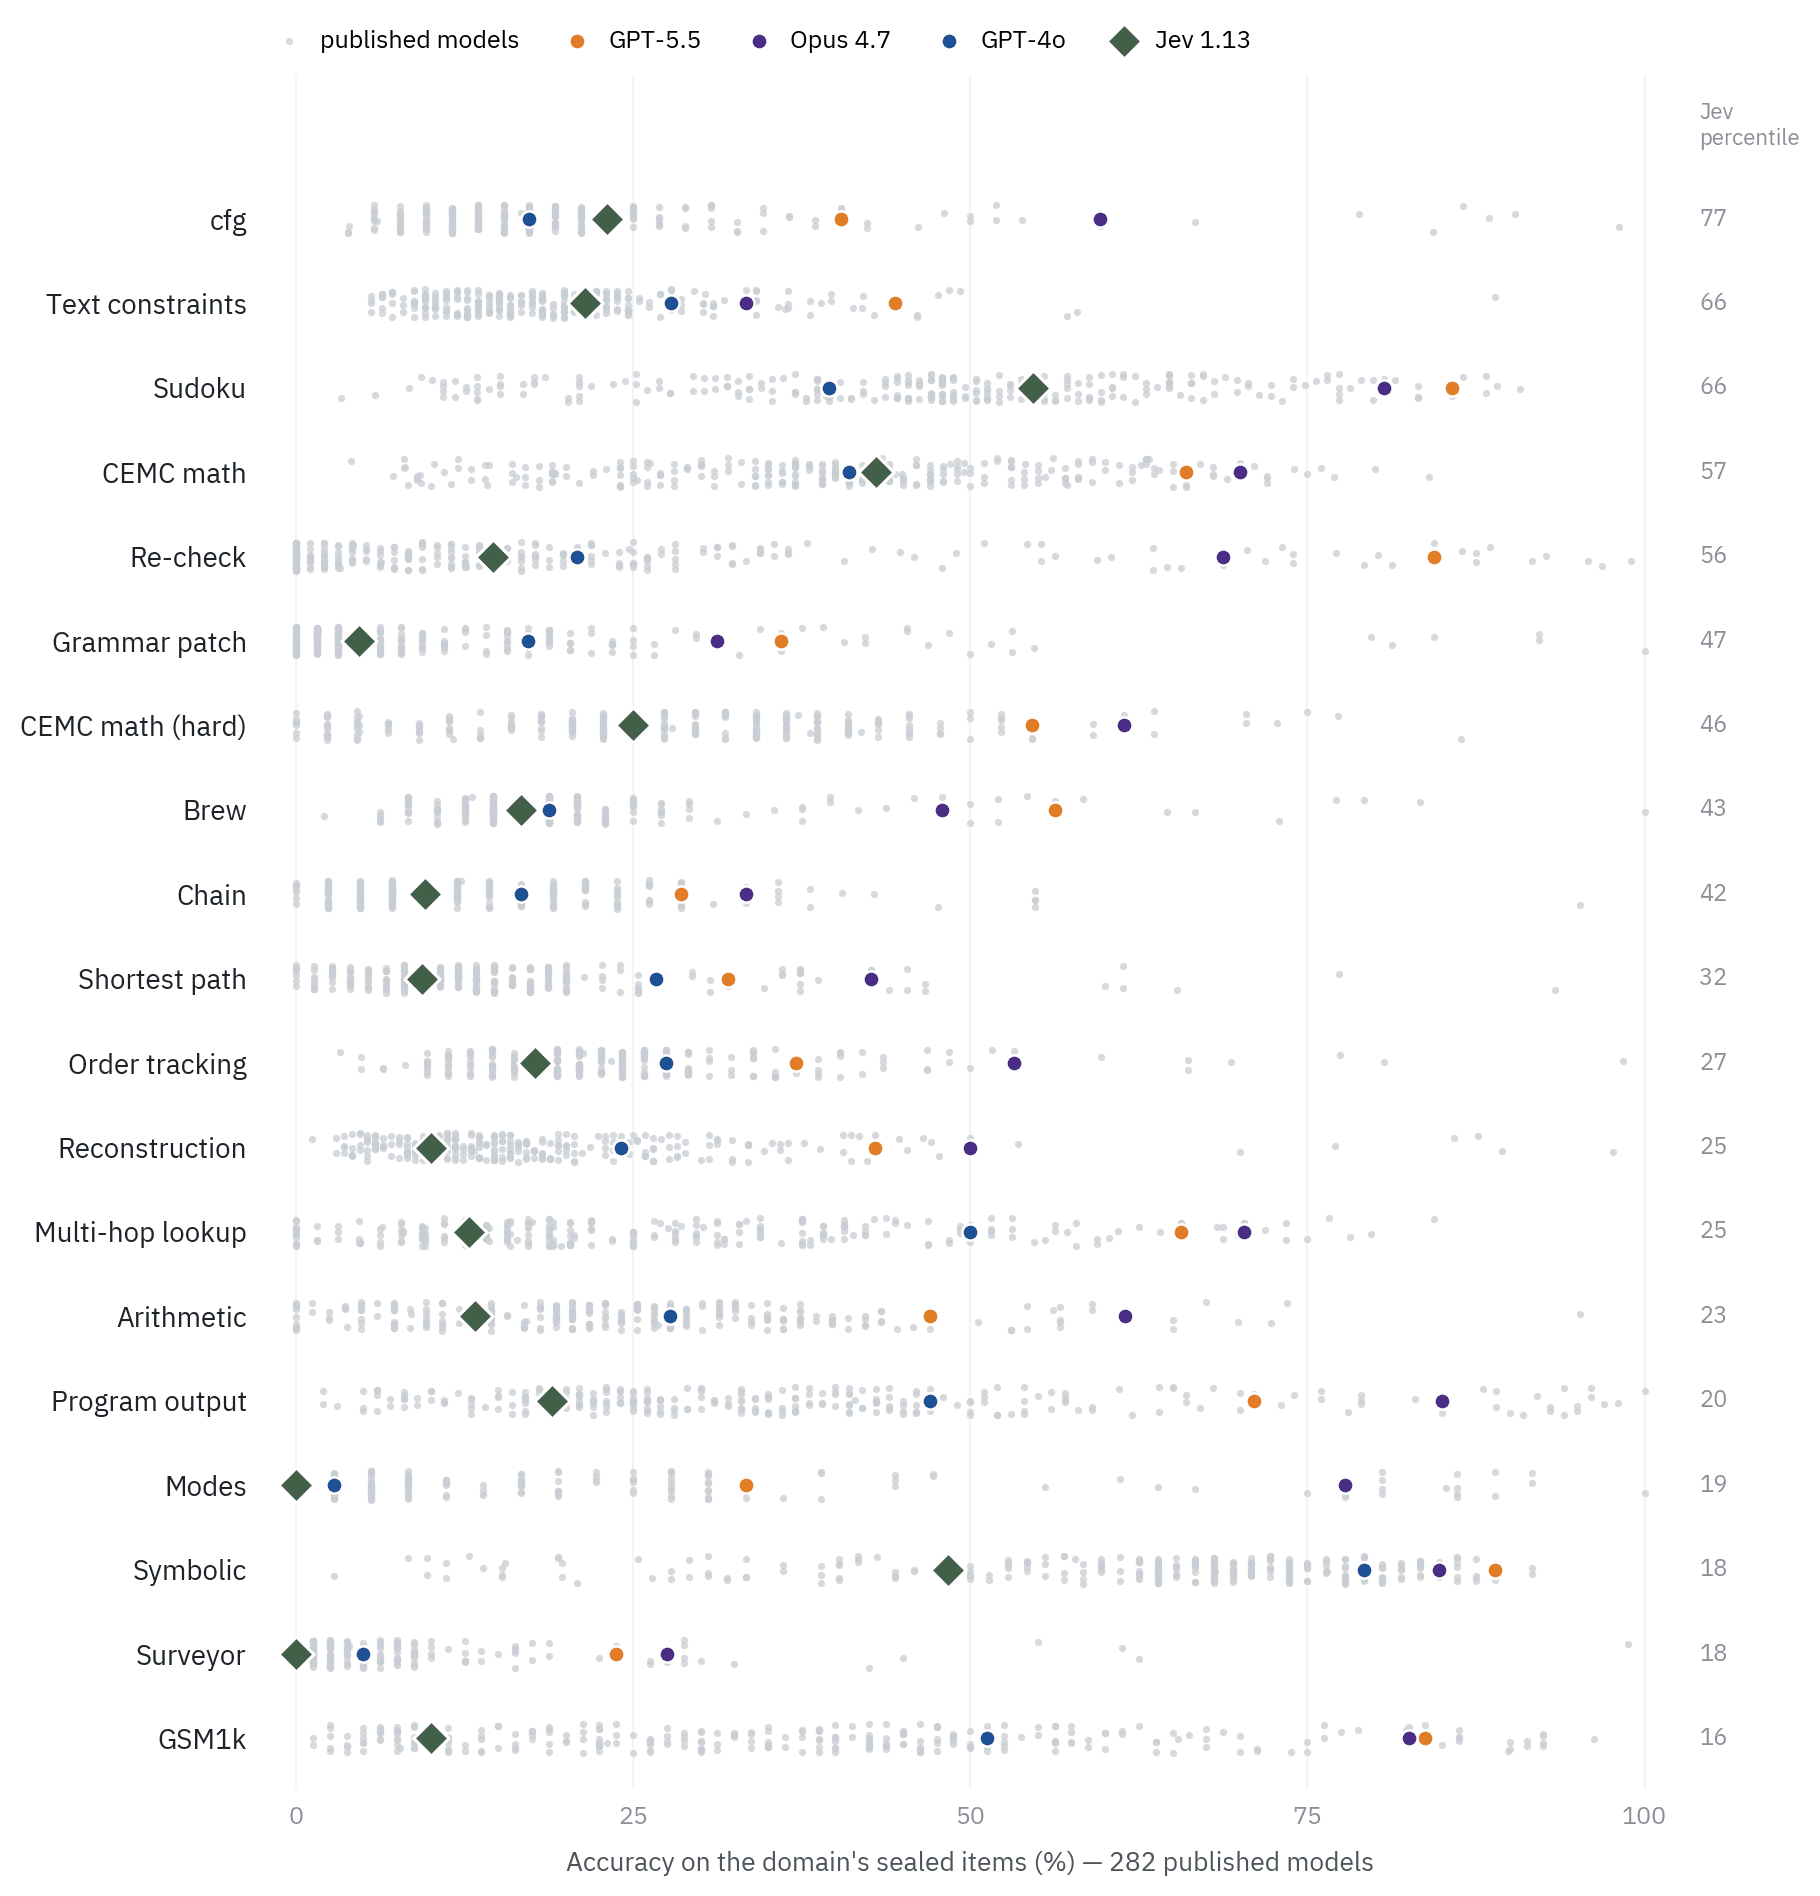
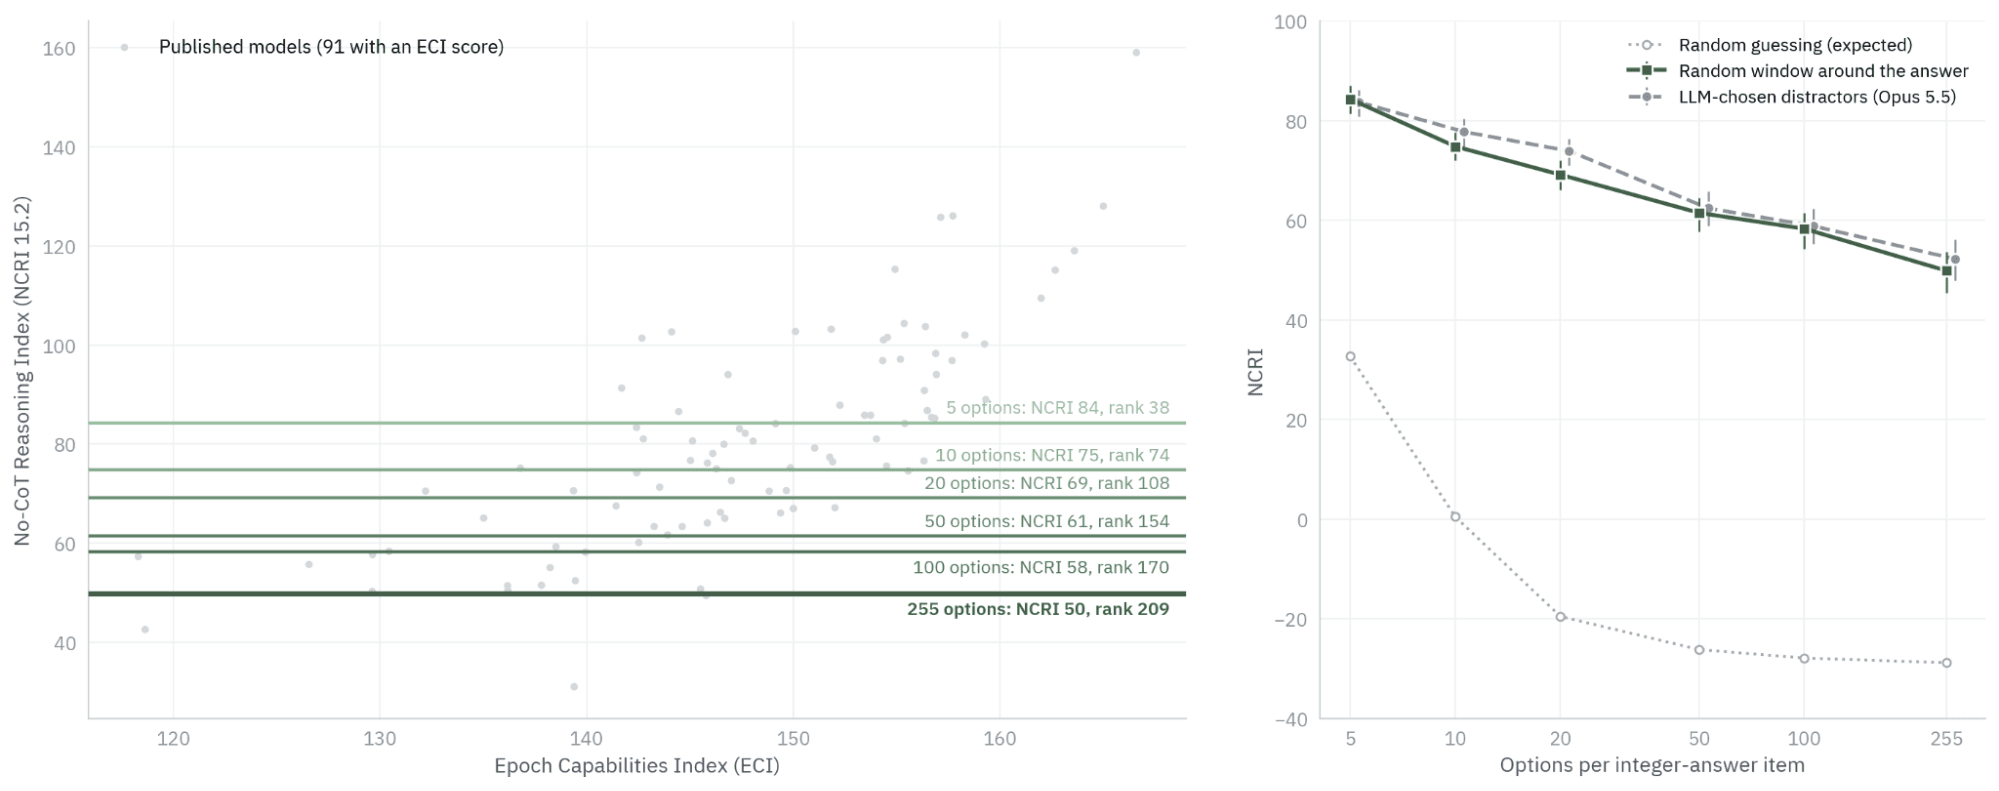
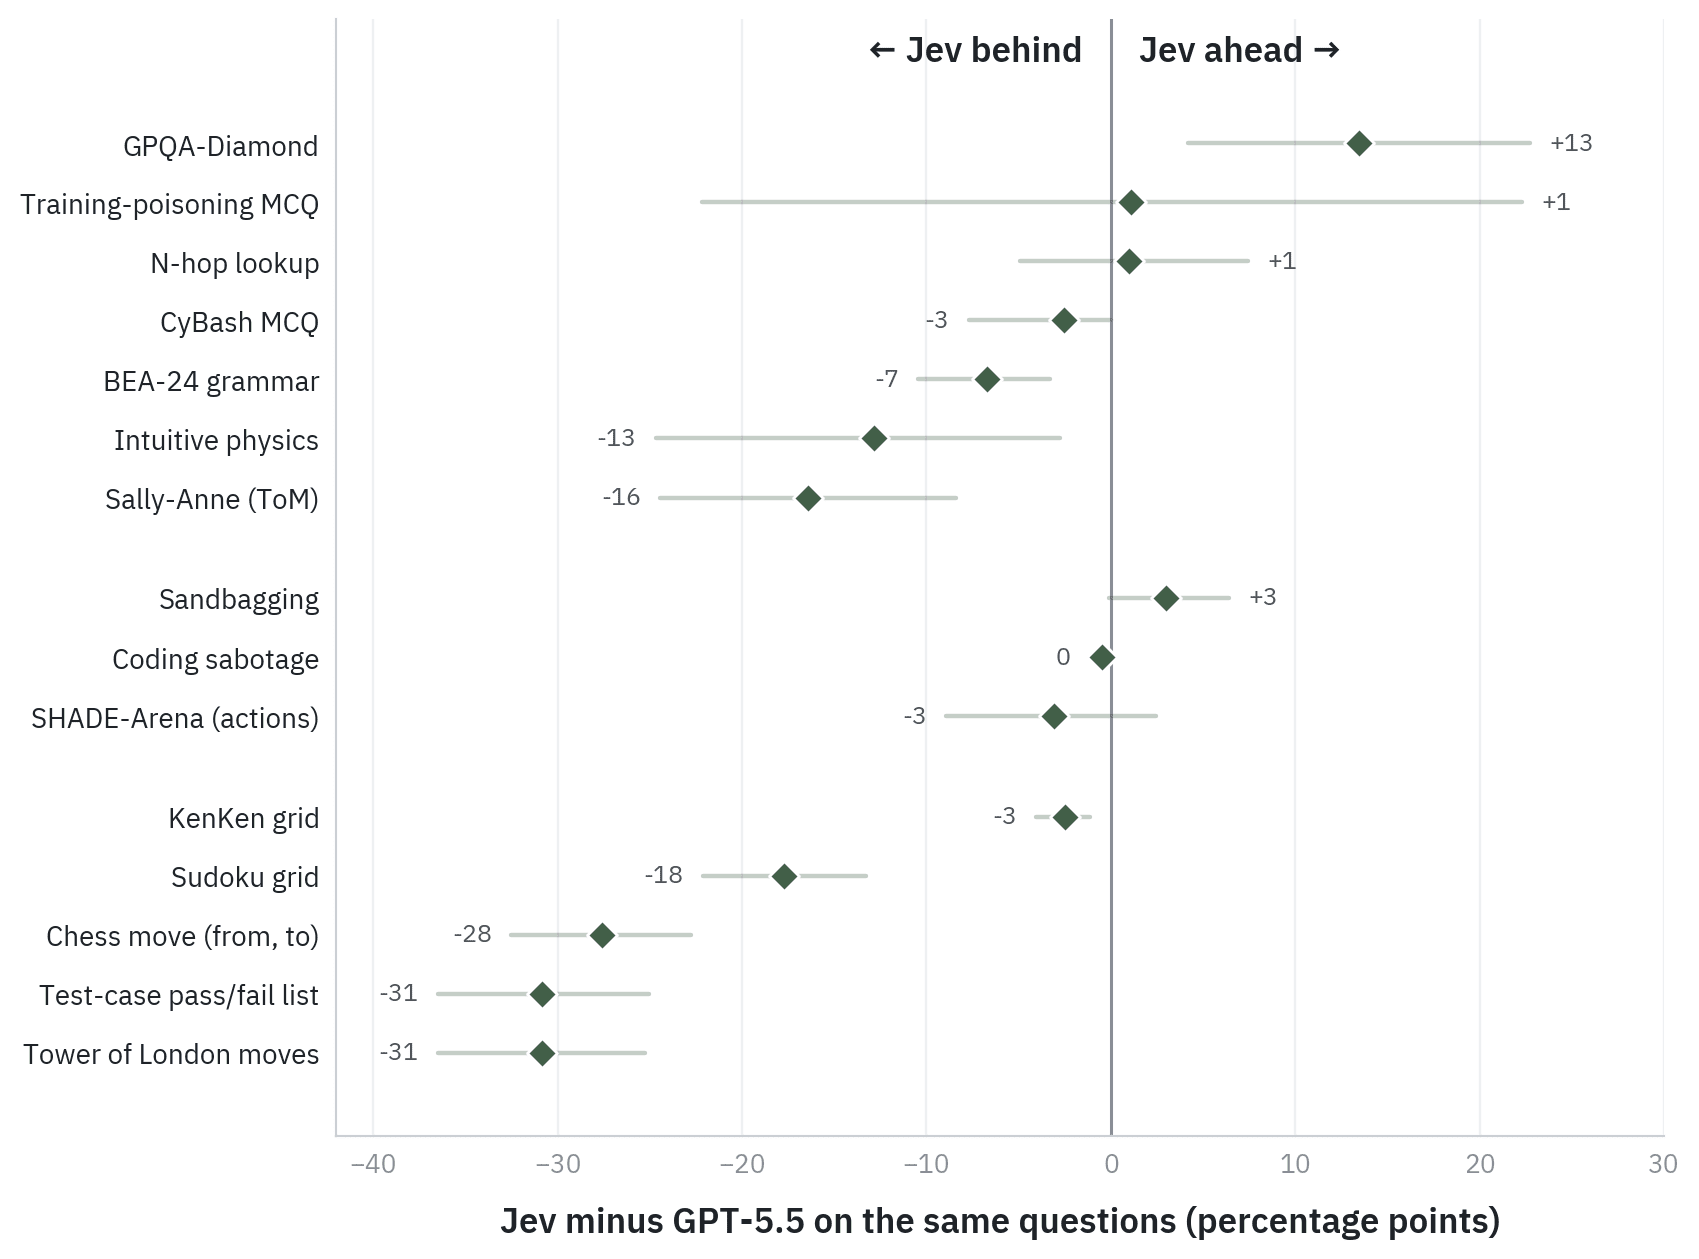
Jev's capabilities are very jagged. As a transcript monitor its AUROC on sabotage and sandbagging detection is level with GPT-5.5 and Opus 4.7 without CoT, at about 1/200th of Opus 4.7's cost. On multiple-choice questions it ranges from ahead of GPT-5.5 (GPQA-Diamond) to well behind it (Sally-Anne). It does badly on tasks where the answer involves multi-step reasoning: on NCRI, it ranks 209 of 279, at about GPT 3.5 level.

This matters because cost and speed make Jev an appealing option for two jobs: routing and simple decision-making in agentic systems, and always-on monitoring of agents. In both, its decisions leave no reasoning trace to inspect. It could also be a cheap test bed for developing frontier monitors, if improvements on Jev carry over.

We thank Rauno Arike, Jonathan Bostock, Andrew Draganov, Francis Rhys Ward and Nicole Xing for helpful comments and discussions.

Background: Jev

TypeSafe calls Jev a “System One” model, pitching it for decisions like classification, routing, scoring, and verification. Unlike standard LLMs, Jev doesn’t take a prompt and return [...]

---

Outline:

(01:30) Background: Jev

(03:05) Performance on ThinkFast

(05:29) NCRI Ladder

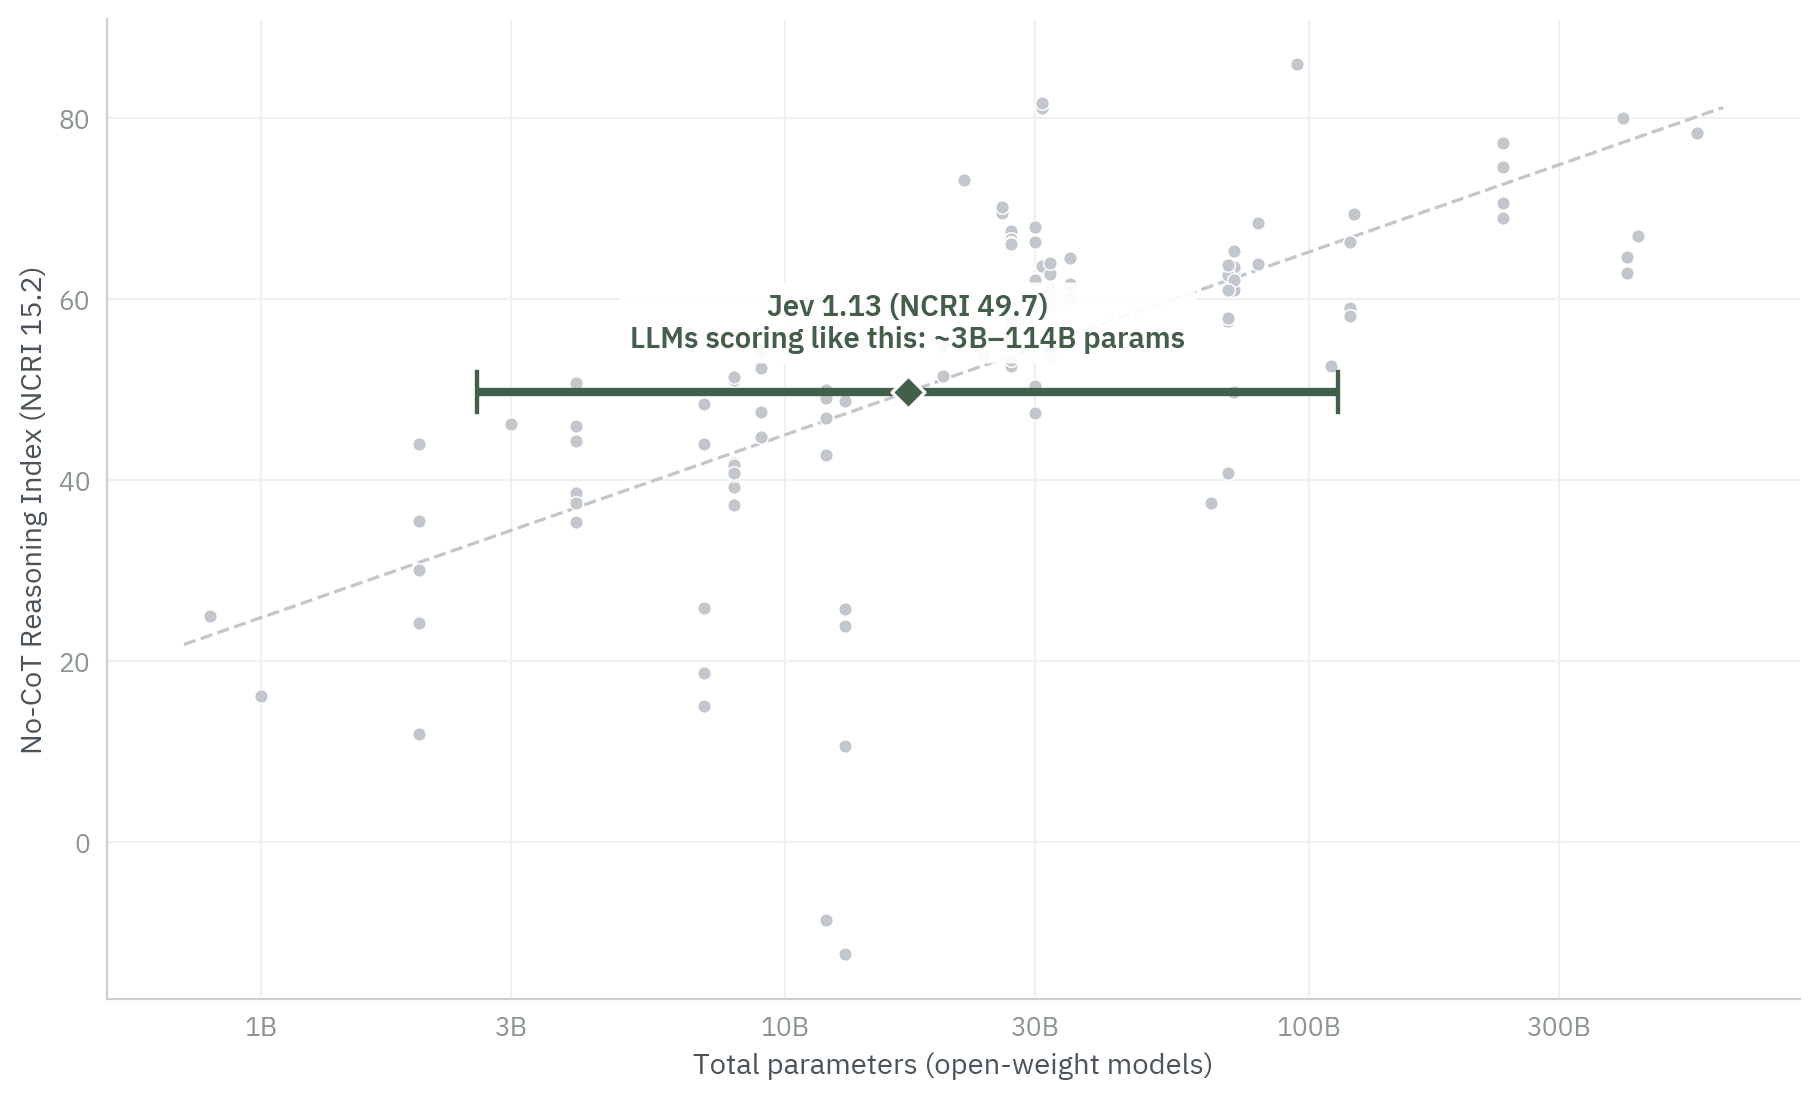
(07:38) Estimating Jev's parameter count

(08:26) Jev as a monitor

(10:11) Takeaways

(11:56) Appendix

(11:59) ThinkFast per-benchmark breakdown

(12:18) NCRI per-benchmark breakdown

(12:33) Number of options for NCRI

The original text contained 2 footnotes which were omitted from this narration.

---

First published:
October 7th, 2026

Source:
https://www.lesswrong.com/posts/QW2kPrAyZQvRtBXHG/benchmarking-jev-against-no-cot-llms

---

Narrated by TYPE III AUDIO.

---

Images from the article:
Dot plot with error bars,
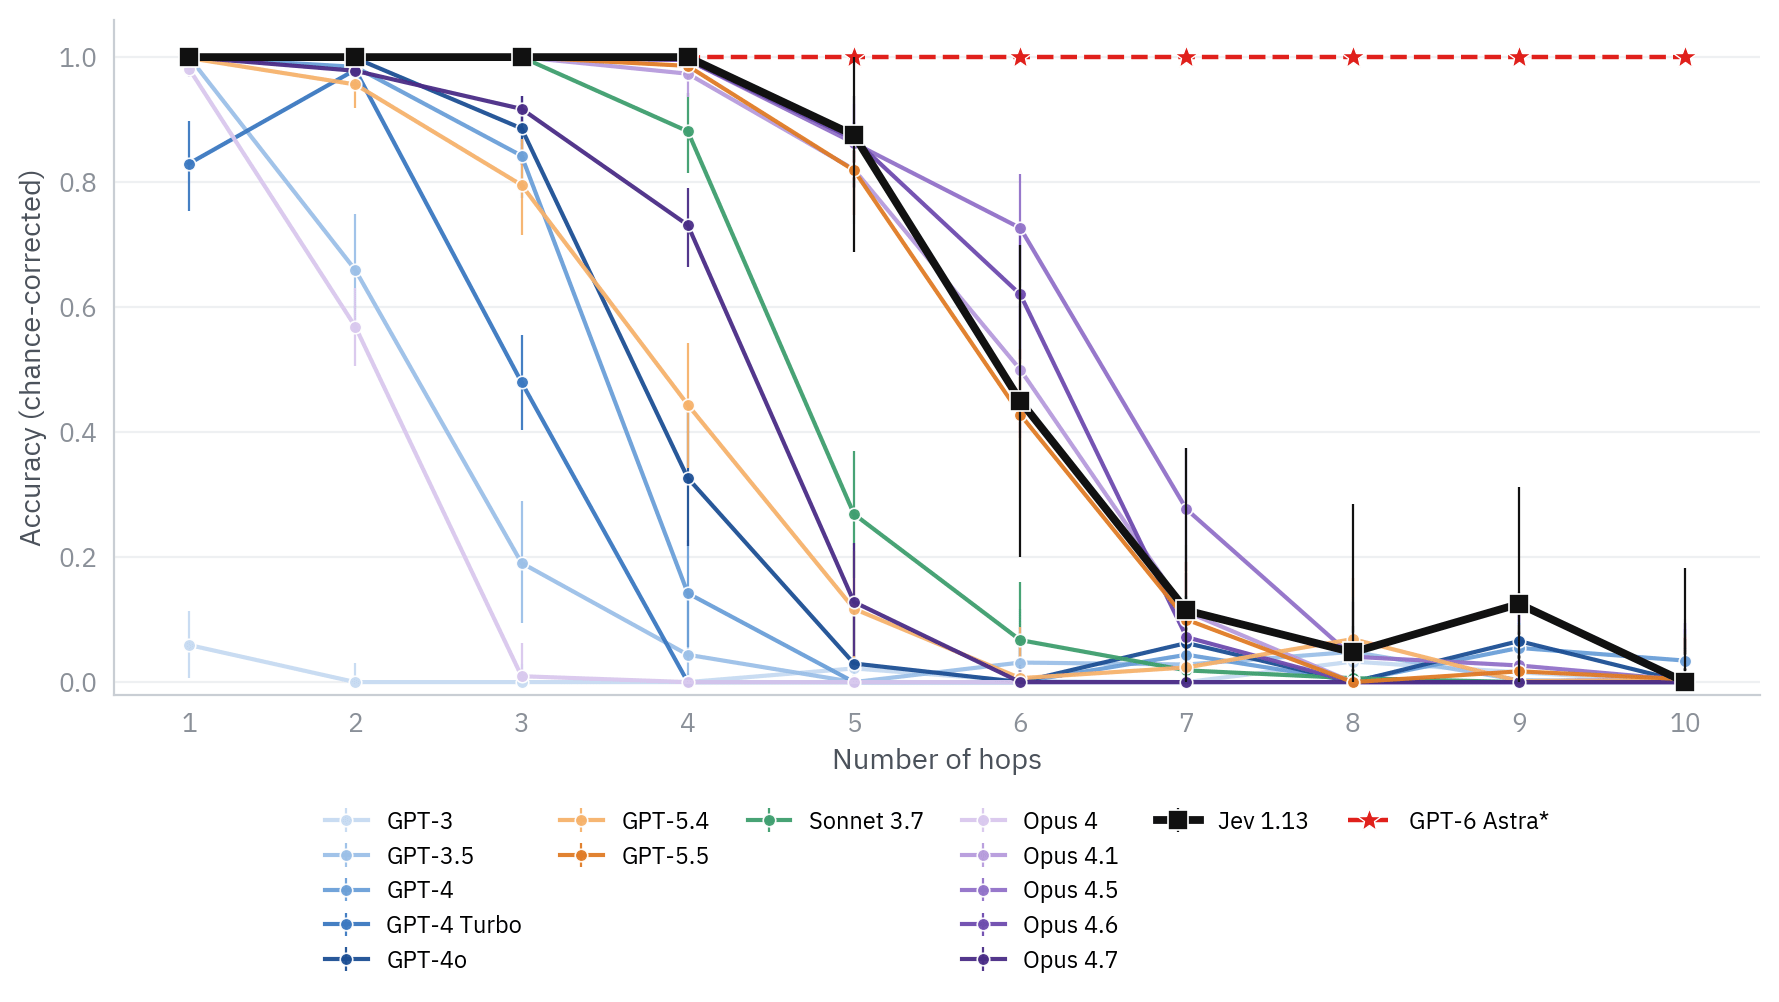
Line graph showing accuracy versus number of hops for various AI models.
Scatter plot of
Scatter plot of
Three ROC curve graphs comparing models on sabotage, SHADE-Arena, and sandbagging detection tasks.
Dot plot comparing AI model benchmark scores across task categories with confidence intervals.
Dot plot comparing model accuracy across domains, titled
Two scatter and line graphs showing NCRI versus ECI and options per integer-answer item.

Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.

links11